EnterpriseRAG-Bench's own source table sums to 499,000, not over 500,000
Dataset and benchmark for RAG on company internal documents.
At a glance
- What is it?
- A synthetic corpus of company internal documents with a 500-question set split across ten categories, built for retrieval evaluation rather than for realism of documents. Thirty of the questions have no ground truth document at all, and the table of volumes adds up to just under the headline figure.
- Who is it for?
- Use it if you are comparing retrieval systems on internal-document questions rather than on public corpora, since that is exactly the gap it fills. Two things to weigh before you read a score.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 72 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
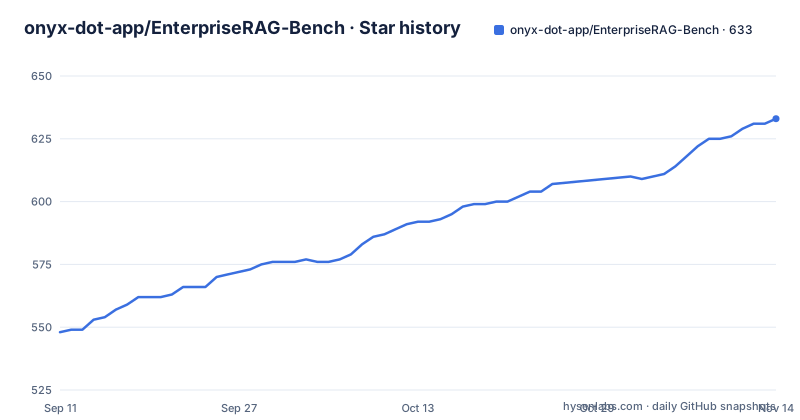
- onyx-dot-app/EnterpriseRAG-Bench633 ★ · +85
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| onyx-dot-app/EnterpriseRAG-Bench | 548 | 633 |
85 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The volume table adds up to just under the headline
The overview says the dataset consists of slightly over 500,000 documents. The table of source volumes adds up to 499,000.
Slack accounts for 275,000, Gmail for 120,000, Linear for 35,000, Google Drive for 25,000, Hubspot for 15,000, Fireflies for 10,000, GitHub for 8,000, Jira for 6,000 and Confluence for 5,000. The column is labelled approximate, which is the honest word for it, but nine approximate figures that land one thousand short of a round half-million is the kind of thing a reader will notice.
The question set, by contrast, adds up exactly. The ten categories total 500: 175 Basic, 125 Semantic, 40 Intra-Document Reasoning, 40 Project Related, 30 Constrained, 20 Conflicting Info, 20 Completeness, 20 Miscellaneous, 10 High Level and 20 Info Not Found.
The distribution format matters for anyone loading this. The release offers `all_documents.zip` as a single archive, or per-source slices named `<source_type>_slice_<slice_number>.zip`, each holding up to 5,000 documents with no nested directory structure. A flat archive means a loader cannot rely on directory paths to identify a source, so the filename is the only signal.
The corpus simulates a company called Redwood Inference that provides AI model inference as a service, which is why the document mix is weighted toward engineering discussion rather than, say, retail operations.
Thirty questions have no ground truth document
Two of the ten categories carry an explicit note that they have no ground truth documents: High Level, with 10 questions where the answer is not located in any single document, and Info Not Found, with 20 questions where the answer is not available at all.
That is 30 of the 500 questions, or six percent of the set, where a retrieval system cannot be scored against a document it is supposed to find. For Info Not Found the intended behaviour is a refusal, and for High Level the answer has to be synthesised across documents. Both need an evaluation method that is not recall against a known document, and the visible page does not say which one is used.
A third block sits outside the main set. A further 100 metadata-dependent questions are available in `extra_questions.jsonl` for teams interested in metadata-aware retrieval, and they are excluded from the leaderboard because their evaluation criteria differ from the core retrieval-focused benchmark.
So the leaderboard runs on 500 questions of which 470 have an answer somewhere in the corpus, and a separate 100 are available only for local evaluation. Any comparison between systems has to state which of those sets it used, since a system tuned on the extra set is not being measured on the same thing.
Sixty percent of the set is single-document lookup
The category counts describe what the benchmark actually rewards. Basic is 175 questions with a single ground truth document. Semantic is 125, described as similar but more roundabout, with less keyword and phrase overlap and no giveaway keywords. Together that is 300 of 500 questions, or three fifths, that are essentially find-the-right-document problems with a phrasing twist.
The aggregation categories are much smaller. Intra-Document Reasoning is 40 questions and needs several distant sections of one longer document combined. Project Related is 40 and aggregates across documents from a single initiative. Constrained is 30, where several documents are relevant but qualifiers disqualify all but one. Each of those is under a tenth of the set.
The remaining 90 questions split into Conflicting Info at 20, where documents contradict each other and the system must give a complete and correct answer; Completeness at 20, which require fetching every relevant document and explicitly cap that set at ten documents; Miscellaneous at 20, aimed at informal, off-topic or loosely organised material; and the 30 with no ground truth.
The upshot for anyone using this: a system with good lexical retrieval and weak aggregation can post a respectable number, because the benchmark's centre of gravity is recall on a mostly single-document task. The completeness category's ten-document cap also means the recall pressure is bounded, which is a deliberate choice and also a limit on what the number says.
The corpus is generated, and the noise is a designed feature
Five principles describe how the documents were made, and the first is about coherence rather than realism of individual files.
Generation starts with human-in-the-loop scaffolding: a company overview, initiatives, an employee directory and a source structure. A core set of high-fidelity documents is then produced with full awareness of that context and of each other, so the corpus contains the kind of meaningful cross-document connections a real company has. High-volume generation follows using topic-based scaffolding, which keeps diversity at scale without the cost of full awareness for every file.
Noise is added deliberately after the initial set exists: documents get misfiled, information becomes outdated, near-duplicates accumulate across systems with updated or conflicting facts, and shuffling is both random and LLM-driven alongside miscellaneous files. Internal terminology is a separate principle, so documents use project codenames, product-specific acronyms and organisational jargon that matter for correct retrieval and mean nothing outside the company.
The fifth principle is generality across enterprise settings, which is the reason the code is published as a generator rather than only as data: the framework is meant to produce comparable datasets for other industries, company sizes and organisational structures rather than encoding one company's assumptions.
That is the correct framing for reading any score. The benchmark measures retrieval against a corpus built to contain misfiled, stale and contradictory near-duplicates, not against documents harvested from a real company.
Slack outnumbers the wiki by fifty-five to one, on purpose
The volume distribution is presented as a design decision rather than an accident, and the reason given is that topic spread within each source follows a real distribution instead of clustering around themes a language model favours.
Read as a ratio, the table says something specific about the simulated company. Slack at 275,000 against Confluence at 5,000 is a factor of 55, and the page states the point directly: Slack channels vastly outnumber wiki pages. Gmail at 120,000 is second, which means chat and email together are almost four fifths of the corpus. Structured systems, the ticket trackers and the CRM, account for roughly 90,000 documents between Linear, Hubspot, Jira and Fireflies, and code and documents in Drive, GitHub and Confluence make up the remaining 38,000.
The coverage claim in the text matches that mix: planning, engineering, documentation, sales, customer success, internal discussions and email. Fireflies is specified as meeting transcripts for both internal and external facing meetings, and Jira as support tickets on both sides too, so the corpus includes material that a company would consider sensitive.
That skew is useful for anyone who cares about chat-heavy retrieval, and it is a reason not to read a good score as evidence about document-heavy estates.
The manifest configures tooling and declares no package
`pyproject.toml` in this repository contains no project metadata. There is no name, no version and no dependency table; what is there is tool configuration.
Black is configured with a target version of py310, a line length of 88, and an include pattern scoped to Python files under `src/`. Mypy is configured for Python 3.10, with `files` set to `src`, `warn_return_any`, `warn_unused_configs`, `disallow_untyped_defs` and `check_untyped_defs` all enabled, and `ignore_missing_imports` left on.
Two things follow. The code is not installable from this manifest, so a consumer clones the repository and runs against the tree rather than installing a package, which suits a dataset-and-generator repository. And both tools are scoped to `src/`, meaning anything outside that directory is outside the formatter and the type checker's view, including the loose scripts that must sit alongside the data.
Dependencies live in `requirements.txt` instead of in the manifest, and the tooling is split across the two files, which is the older convention and explains why the manifest looks empty at first glance.
Two vector stores, two model vendors, one optional tracer
The runtime dependencies describe what the evaluation code expects to talk to. `pydantic[email]` for validated config, `openai` and `anthropic` for the two model vendors, `tiktoken` for token counting, `pyyaml` and `python-dotenv` for configuration, and `pyarrow` for columnar reads of the data files.
Two vector databases are listed as required rather than optional: `qdrant-client` and `opensearch-py`. That is the shape of a benchmark meant to be run against more than one retrieval stack, since a system that wants to be compared fairly should not be forced into one vendor's index.
Tracing is the one part marked optional, with a comment naming two environment variables, a Braintrust API key and project, and the package listed below that line. So experiment logging is a deliberate add-on rather than something a run requires.
Development dependencies are separate and minimal: black, mypy, pre-commit and type stubs for PyYAML. The repository also carries a pre-commit configuration and a `.vscode/` directory, and the tree contains `answer_evaluation/` with its own README for scoring answers rather than retrieving them, plus `methodology.md`, `quickstart.md` and a `generated_data/` directory.
On provenance, the dataset is published by the company that sells a RAG product, and the page says so directly: Onyx excludes itself from the leaderboard to avoid a conflict of interest. The dataset, the leaderboard space and the linked paper all sit under the same organisation.
Editorial conclusion
Use it if you are comparing retrieval systems on internal-document questions rather than on public corpora, since that is exactly the gap it fills. Two things to weigh before you read a score. The question set is heavily weighted to single-document lookup, with 300 of 500 in the Basic and Semantic categories, so a system that retrieves well but cannot aggregate will still look competent. And 30 questions have no ground truth document, plus 100 more metadata-dependent questions excluded from the leaderboard, so check which subset your evaluation actually covers.
Frequently asked questions
What is EnterpriseRAG-Bench?
An MIT dataset and benchmark for retrieval augmented generation over company internal documents, simulating a company called Redwood Inference that provides AI model inference as a service. It contains slightly over 500,000 documents and 500 questions, and the code can generate comparable datasets for other industries.
How many questions does EnterpriseRAG-Bench have?
500, split across ten categories: 175 Basic, 125 Semantic, 40 Intra-Document Reasoning, 40 Project Related, 30 Constrained, 20 Conflicting Info, 20 Completeness, 20 Miscellaneous, 10 High Level and 20 Info Not Found.
Which EnterpriseRAG-Bench questions have no ground truth document?
The 10 High Level questions and the 20 Info Not Found questions, both marked as having no ground truth documents. A further 100 metadata-dependent questions live in extra_questions.jsonl and are excluded from the leaderboard because their evaluation criteria differ.
How do I download the EnterpriseRAG-Bench dataset?
From the latest release or from HuggingFace, either as all_documents.zip or as per-source slices named `<source_type>_slice_<slice_number>.zip` holding up to 5,000 documents each with no nested directory structure. The question set is questions.jsonl, and answer scoring is documented in answer_evaluation.
Is Onyx on the EnterpriseRAG-Bench leaderboard?
No. The page states that Onyx offers a RAG-based product and excludes itself from the leaderboard to avoid a conflict of interest, although the dataset, the leaderboard space and the linked paper are all published under the same organisation.
What does running EnterpriseRAG-Bench require?
Both qdrant-client and opensearch-py are required dependencies, along with the OpenAI and Anthropic SDKs, tiktoken, pydantic, pyyaml, python-dotenv and pyarrow. Braintrust is optional for LLM tracing and needs an API key and project set. The repository declares no installable package, so consumers clone the tree.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/onyx-dot-app-enterpriserag-bench)Star history chart for your README
[](https://hysenlabs.com/projects/onyx-dot-app-enterpriserag-bench)Was this useful?