openai/tiktoken: a Rust extension, a private attribute shortcut, and a benchmark pinned to 0.2.0
tiktoken is a fast BPE tokeniser for use with OpenAI's models.
At a glance
- What is it?
- tiktoken is the byte pair encoding tokenizer behind OpenAI's models, shipped as a compiled Rust extension with a thin Python layer, and most of what trips people up is not the counting. It is the extension story, where the fast path reaches for attributes that are not part of the public API, the clean path requires shipping a second package, and the README does not document an offline mode.
- Who is it for?
- Use tiktoken if you need to know what a string costs before you send it to an OpenAI model, and if you are willing to pin the version, because the project has not published a 1.0 and the gaps between releases run to months.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
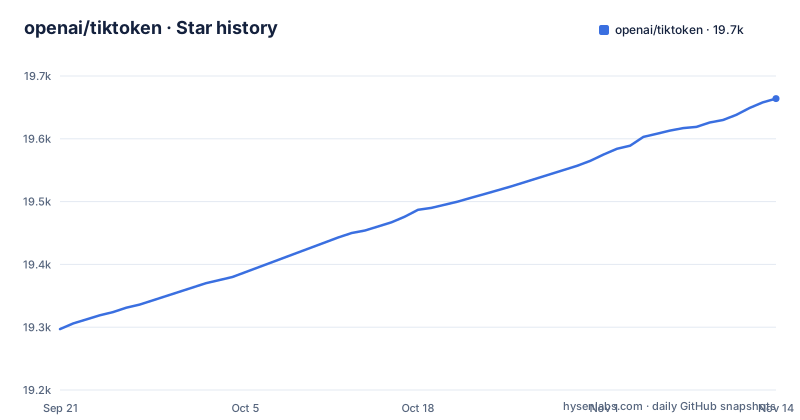
- openai/tiktoken19,664 ★ · +367
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| openai/tiktoken | 19.3k | 19.7k |
367 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The speed claim in the README was measured with tiktoken 0.2.0
The Performance section makes one claim: tiktoken is between 3 to 6 times faster than a comparable open source tokeniser. The measurement conditions follow immediately, and they are the interesting part. It was measured on 1GB of text, using the GPT-2 tokeniser, comparing GPT2TokenizerFast from tokenizers==0.13.2 with transformers==4.24.0 against tiktoken==0.2.0.
So the number describes a build from the 0.2 line, a comparison library at 0.13.2, and a single tokenizer on a single workload. The project version in pyproject.toml and Cargo.toml is 0.14.0, and the last push was 2026-08-17, so both sides of that comparison have moved a long way. The claim is not wrong, it is scoped, and the scope is one encoding rather than o200k_base or cl100k_base.
There is a perf.svg at the repository root. If speed is what brought you here, measure your own workload with the encoding you actually use, because the ratio for a rare-language corpus is a different question from the ratio for 1GB of English GPT-2 text.
pip install tiktoken gives you a compiled extension called tiktoken._tiktoken
The install is one line from PyPI, `pip install tiktoken`, and what arrives is not a pure Python package. setup.py declares a RustExtension named tiktoken._tiktoken with binding PyO3, and pyproject.toml lists setuptools-rust among the build requirements alongside setuptools and wheel.
The debug flag in that extension is set to False, and the comment attached to it explains why: between the project's use of editable installs and its wish to use Rust for performance sensitive code, it makes sense to always use the release build. The Rust side is a real crate rather than a build detail, with crate-type declared as both cdylib and rlib, edition 2024, pyo3 0.29.2 behind an optional python feature, and its own dependencies in fancy-regex, regex, rustc-hash and bstr. The rlib entry is what makes the tokenizer usable from Rust directly, not only from Python.
The consequence is for anyone who cannot use a prebuilt wheel: building from source means having a Rust toolchain, and the wheel configuration shows what that entails. On Linux the CI installs rustup with curl before the build, and on macOS it adds the aarch64-apple-darwin and x86_64-apple-darwin targets and sets a deployment target of 10.12.
32-bit Linux, musllinux i686 and win32 are skipped, so those users build from source
The wheel configuration carries a skip list with three patterns: manylinux_i686, musllinux_i686, and win32. On macOS the architectures built are x86_64 and arm64. Python support starts at 3.9, and the runtime dependencies of the package are declared as just regex and requests.
Read the skip list as a statement about who has a binary and who has to compile. A 32-bit x86 Linux host has no wheel, and a 32-bit Windows host has no wheel, and an Alpine-style musl 32-bit target has none either. In those cases pip falls back to a source install, which by the previous section means installing Rust, building the extension, and only then importing it. That is a far heavier prerequisite than `pip install`, and it is invisible until someone tries it on a locked down or 32-bit image.
The test wiring in the same file installs pytest and hypothesis and runs the tests directory with an import mode of append, so the project's own verification of a build happens through that same compiled path.
There is a requests dependency and an optional blobfile, and no documented offline mode
Two things in the packaging point at where the encoding data comes from without ever saying so. The declared dependencies are regex and requests, and there is one optional dependency group, blobfile, which requires blobfile>=3. Neither is explained in the README.
What is missing is the part that matters operationally. The README documents the quick start, the performance comparison, the BPE background, the educational submodule, and the two extension routes, and it does not document a cache directory, an environment variable for offline use, or a way to vendor the encoding files. So a deployment that must work without outbound network access has no documented answer, and the requests dependency plus the blobfile extra is the strongest hint that fetching is involved.
If that is your situation, the question to answer before anything else is whether the encoding data is already on the machine, and the honest answer from the documentation alone is that it does not say. There is an issue tracker for questions, which is where that belongs.
Two routes to a custom encoding, and only one of them needs a package
There are two documented ways to extend tiktoken, and the README says which to prefer. The first is to create the Encoding object exactly the way you want and pass it around yourself. The second is the tiktoken_ext plugin mechanism, and the qualifier is precise: it is only useful if you need tiktoken.get_encoding to find your encoding, otherwise prefer option 1.
That reverses the usual instinct. The plugin route is nicer at the call site and worse everywhere else, because it means shipping a second distribution with a namespace package under tiktoken_ext, laid out with a setup.py and my_encodings.py, and the README is explicit that the tiktoken_ext/__init__.py file must be omitted so it stays a namespace package.
from setuptools import setup, find_namespace_packages

setup(
    name="my_tiktoken_extension",
    packages=find_namespace_packages(include=['tiktoken_ext*']),
    install_requires=["tiktoken"],
    ...
)
Inside, my_encodings.py must expose a variable named ENCODING_CONSTRUCTORS, a dictionary from an encoding name to a function taking no arguments and returning arguments for tiktoken.Encoding. The reference implementation is tiktoken_ext/openai_public.py and the mechanics are in tiktoken/registry.py. Then `pip install ./my_tiktoken_extension`, with one warning: make sure not to use an editable install.
The fast route reads private attributes, and the name is your only warning
Option 1 looks like this:
cl100k_base = tiktoken.get_encoding("cl100k_base")

# In production, load the arguments directly instead of accessing private attributes
# See openai_public.py for examples of arguments for specific encodings
enc = tiktoken.Encoding(
    # If you're changing the set of special tokens, make sure to use a different name
    # It should be clear from the name what behaviour to expect.
    name="cl100k_im",
    pat_str=cl100k_base._pat_str,
    mergeable_ranks=cl100k_base._mergeable_ranks,
Three of the inputs read attributes with a leading underscore, and the comment on the block says so in as many words: in production, load the arguments directly instead of accessing private attributes, and see openai_public.py for examples. The third is the special_tokens dictionary, which spreads the base encoding's own _special_tokens and then adds an entry such as "<|im_start|>": 100264. The README points out that the tokeniser API is documented in tiktoken/core.py, which is the public surface; the other names are not that surface.
The second comment is the design instruction that matters most. If you are changing the set of special tokens, use a different name, and it should be clear from the name what behaviour to expect. The example follows it, naming the derived encoding cl100k_im rather than reusing cl100k_base. A derived encoding that keeps the base name is indistinguishable from the base at every call site, and since you constructed it in process, the only artifact a reader has is the name.
The educational submodule is a Python tokenizer you read, not one you ship
Under a heading about what byte pair encoding is, the README points at a submodule described as educational and friendlier if you want to learn the details, including code that visualises the procedure.
from tiktoken._educational import *

# Train a BPE tokeniser on a small amount of text
enc = train_simple_encoding()

# Visualise how the GPT-4 encoder encodes text
enc = SimpleBytePairEncoding.from_tiktoken("cl100k_base")
enc.encode("hello world aaaaaaaaaaaa")
Two functions carry it. train_simple_encoding trains a BPE tokeniser on a small amount of text, and SimpleBytePairEncoding.from_tiktoken takes a real encoding name, cl100k_base, so you can watch the actual encoder work. The sample string is chosen to show the difference: a long run of a characters tokenises differently from ordinary words.
The name is the warning. The module is _educational, which the leading underscore places outside the public surface that core.py documents. Use it to understand what your encodings are doing, and read the four properties the README lists for BPE while you are there, including that each token corresponds to about 4 bytes on average in practice.
No 1.0 yet, and the gaps between releases run to months
The version history is 0.12.0 on 2025-10-06, 0.13.0 on 2026-05-15, and 0.14.0 on 2026-08-17. The project has not published a 1.0, and the intervals are not monthly, they are about seven months, then about three.
For a library this small, that cadence means the pin is the real dependency. The 0.x line is where breaking changes are allowed by the numbering convention, and the two documented extension patterns are themselves a demonstration: one of them reads attributes off the base object directly, and the other forbids editable installs. Both are signs of a surface that expects to move, so an application that stores encoded token ids, or that depends on a custom encoding name resolving at runtime, wants an exact version rather than a range.
The other signal in pyproject.toml is the authors list, which names one person, Shantanu Jain, and the help section says the same thing in a different way: post questions in the issue tracker, and if you work at OpenAI, check the internal documentation. Support is a public tracker plus an internal path, and CHANGELOG.md at the root is where a version note would be written down.
Editorial conclusion
Use tiktoken if you need to know what a string costs before you send it to an OpenAI model, and if you are willing to pin the version, because the project has not published a 1.0 and the gaps between releases run to months. Do not quote its speed from the README, since the 3 to 6 times figure was measured with tiktoken 0.2.0 against tokenizers 0.13.2 on one gigabyte of GPT-2 text, and do not plan around an offline install without checking first, because the only trace of where the encoding data comes from is a requests dependency and an optional blobfile extra. Check four things before you rely on it: that your platform has a wheel, since 32-bit Linux, musllinux i686 and win32 are skipped, and a source build then needs a Rust toolchain; whether you are extending an encoding, and if so which of the two routes you want, since constructing an Encoding yourself reaches into private attributes while the plugin route makes you publish a package and forbids editable installs; how you will name a derived encoding, because the README makes the name the only signal that behaviour changed; and that the tokeniser API you rely on is the one in tiktoken/core.py. The license is MIT and the last push was 2026-08-17.
Frequently asked questions
What is a TikToken for?
A token in tiktoken is one unit of the number sequence a language model actually reads, and tiktoken is a fast byte pair encoding tokeniser for use with OpenAI's models. It gives you the encoding for a named vocabulary or for a specific model, and encode and decode round trip losslessly.
How to install TikToken?
The open source version installs from PyPI with `pip install tiktoken`. Building it from source is a different matter, since setup.py compiles a Rust extension named tiktoken._tiktoken through PyO3 and setuptools-rust, and the wheel configuration skips manylinux_i686, musllinux_i686 and win32.
how to use tiktoken to count tokens
Load an encoding and take the length of the encoded result. The quick start uses `enc = tiktoken.get_encoding("o200k_base")` and shows the round trip with enc.decode(enc.encode("hello world")), and for a specific model in the OpenAI API you use `enc = tiktoken.encoding_for_model("gpt-4o")` instead.
Does GPT use TikToken?
tiktoken is described as a fast BPE tokeniser for use with OpenAI's models, and the quick start has a call to tiktoken.encoding_for_model that returns the tokeniser corresponding to a specific model in the OpenAI API, gpt-4o in the example. The vocabulary names themselves, such as o200k_base and cl100k_base, are the identifiers you load with get_encoding.
how to use tiktoken offline
The README does not document an offline mode, a cache location, or a vendoring option for encoding data. The only related pieces in the packaging are the requests dependency and an optional blobfile extra, so if offline use is a requirement, ask in the issue tracker rather than assuming a flag exists.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Build a BPE Tokenizer in 80 Lines of TypeScript and Watch JSON Eat Your Tokensdev.to · Nov 2, 2026 · 3 points · 4 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openai-tiktoken)Star history chart for your README
[](https://hysenlabs.com/projects/openai-tiktoken)Was this useful?