MiniCPM-Robot: a 1.5B manipulation policy with streaming memory and a 0.9B on-device tracker, and the benchmark rows it does not win
A Smarter and Faster On-Device AI Brain for Robots
At a glance
- What is it?
- OpenBMB/MiniCPM-Robot is the repository for MiniCPM's first embodied intelligence models: MiniCPM-RobotManip, a 1.5B vision-language-action policy, and MiniCPM-RobotTrack, a 0.9B tracker for on-device use. The benchmark table backs the efficiency story better than the claim to beat larger models everywhere.
- Who is it for?
- Take MiniCPM-Robot if you want a small open-weight manipulation policy with a documented inference script and reproducible evaluators for LIBERO, CALVIN, RoboTwin2 and RMBench. Be cautious if you need the top score on every benchmark, since several larger models beat it on individual columns.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 82 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
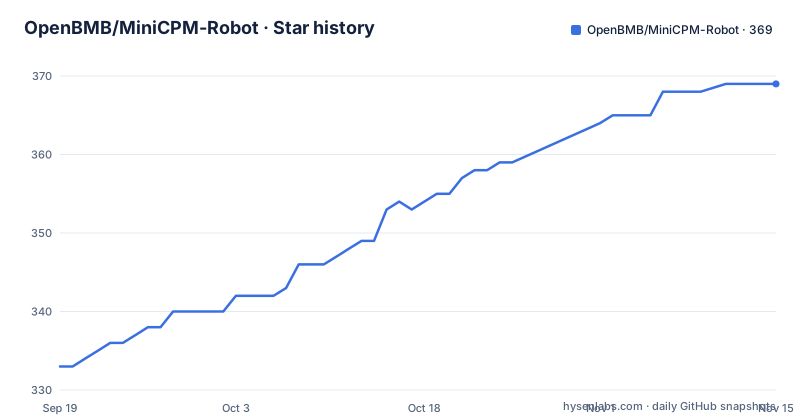
- OpenBMB/MiniCPM-Robot369 ★ · +36
| Repository | 2026-09-19 | 2026-11-15 |
|---|---|---|
| OpenBMB/MiniCPM-Robot | 333 | 369 |
36 Stars in the last 57 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two models share one repository, and the README's strongest claims belong to the authors
MiniCPM-Robot is described as MiniCPM's embodied intelligence model family for real-world perception, decision-making and action. The first two members are MiniCPM-RobotManip, a 1.5B generalist vision-language-action model for robot manipulation in simulation and on real robots, and MiniCPM-RobotTrack, a 0.9B embodied target tracker described as the first fully on-device one.
The repository splits cleanly: MiniCPM-RobotManip and MiniCPM-RobotTrack are separate directories, with weights hosted in collections on Hugging Face and ModelScope. The launch news is dated 2026.07.19.
Statements such as open-source SOTA on EVT-Bench and beating larger models come from the authors' own evaluations. The repository gives evaluation code for the manipulation model, which lets you check those claims yourself, but for the tracker the visible text offers only the headline figures.
Streaming inference keeps a minute of memory at a fraction of the recompute cost
The streaming context is the design feature that sets RobotManip apart. Historical observations are incorporated into the model context through streaming inference. With 60 frames of history, traditional recomputation needs 125 TFLOPs per decision step, while streaming inference needs only 3.3 TFLOPs. The model supports up to 1 minute of visual context memory, with online cost kept comparable to traditional single-frame reactive inference.
The consequence is that tasks which depend on remembering what happened earlier become practical without paying for full recompute. RMBench is the memory oriented benchmark in the table, and RobotManip scores 53.3 there against 10.4 for the only other model with a number.
The limit is the horizon. Memory is stated up to 1 minute, so a task that needs to recall something from longer ago falls outside the stated capability.
The 120 ms latency figure has conditions attached
RobotManip inherits MiniCPM-V 4.6's visual token compression, reducing each frame from 256 to 64 visual tokens, a 4x compression. With an H100, BF16 and single-frame input, model-forward latency per decision step is 120 ms, compared with 234 ms for pi0.5. The measurement excludes task autoregressive decoding.
Each condition narrows what the number means. A different GPU, a precision other than BF16 or multi-frame input will change the time, and the decoding exclusion means the end to end loop may be slower than the figure suggests.
A separate project, PhyAI, added Day-0 support and reports raising inference throughput on NVIDIA H20 from 10 Hz to 37 Hz through CUDA Graph and custom Triton fused kernels. That is a third party optimisation, on a different GPU, so it shows headroom rather than what the stock repository delivers.
The benchmark table shows efficiency wins but not a sweep
The comparison covers LIBERO, Calvin (ABC to D), RoboTwin2 clean and random in easy and hard splits, and RMBench. RobotManip posts 97.5 on LIBERO, 4.1 on Calvin, 91.3 and 91.6 on RoboTwin2, and 53.3 on RMBench.
Read against the rows, the picture is mixed. On LIBERO, Abot-M0 at 98.6, LingBot-VA at 98.5, Qwen-VLA at 97.9 and StarVLA-alpha at 97.8 all score higher. On RoboTwin2 easy, LingBot-VA reaches 92.9 against 91.3, and the hard split ties at 91.6. On Calvin it ties pi0.5 at 4.1. It does beat pi0.5 on RoboTwin2 and clearly on RMBench.
Many cells for the competitors are blank. The claim to beat larger models therefore holds on selected columns, and the real argument is parity at 1.5B against models of 3B to 5B and above. It is also the only row marked Generalist with open weights at that size.
vla_infer.py takes images, text and a checkpoint, and returns a (30, 80) action chunk
Single-sample inference runs through vla_infer.py. You provide at least one image and a language instruction. Robot state defaults to zeros if you omit it, which means a state-conditioned task run without a state file runs on a blank state. The model returns an action chunk of shape (30, 80):
cd MiniCPM-RobotManip
python vla_infer.py \
    --image frame.jpg \
    --text "Pick up the red block." \
    --checkpoint ./checkpoint \
    --state-file state.npy \
    --embodiment-id 0 \
    --output action.npy
For multi-view input, repeat the --image flag, for example a front camera and a wrist camera. Without --output, the predicted action is printed as JSON.
The --embodiment-id flag selects which robot the output is for, so the id must match your hardware. The script predicts actions only; wiring those chunks into a real controller is your job.
Because the output is a 30 by 80 array, the shape alone tells you the policy plans a block of future steps per call, not one command at a time. Your control loop has to decide how many of those steps to execute before asking the model again, and the repository's inference script does not make that choice for you. Saving to action.npy with --output keeps the raw array for inspection before you trust it on hardware.
Setup is a conda environment pinned to Python 3.10 and PyTorch 2.6.0 with CUDA 12.4
Installation starts by installing and initialising Conda. The specification follows the tested Python 3.10 and PyTorch 2.6.0 (CUDA 12.4) setup, and the commands are:
cd MiniCPM-RobotManip
conda env create -f environment.yml
conda activate MiniCPM-RobotManip
Evaluation adds more moving parts. Integrations for LIBERO, CALVIN, RoboTwin2 and RMBench live under evaluation/. The evaluators connect to a WebSocket plus MessagePack model server, and the model server and each benchmark simulator run in separate Python environments. Simulators, datasets and assets are external dependencies installed according to each benchmark's own guide.
The consequence is real setup effort. Reproducing the table means building several environments, one per benchmark, on top of the model server, and the repository does not bundle any of the simulators.
RobotTrack's published numbers are for one robot, and the repository has no tagged release
RobotTrack covers static, dynamic and adversarial targets and is called open-source SOTA on EVT-Bench. Its speed claim is specific: 5+ FPS, about 180 ms, on a Unitree Go2 EDU with fully local, vision-only natural-language tracking.
That figure is tied to one platform. A different robot or onboard computer will not necessarily match it, and vision-only means no other sensor is part of the stated setup. The model is 0.9B, small enough to be the reason on-device operation is plausible, but the repository's own text gives only the Go2 EDU figure.
There are no GitHub releases, so there is no version to pin, and the last push was on 2026-08-25. The repository is not archived and is licensed Apache-2.0. Note the commit you test against, since the weights live in separate collections that can change independently.
Editorial conclusion
Take MiniCPM-Robot if you want a small open-weight manipulation policy with a documented inference script and reproducible evaluators for LIBERO, CALVIN, RoboTwin2 and RMBench. Be cautious if you need the top score on every benchmark, since several larger models beat it on individual columns. Before committing, replicate the latency figure on your own GPU, because the published one is for H100 with BF16 and single-frame input.
Frequently asked questions
What is the MiniCPM model in MiniCPM-Robot?
MiniCPM-Robot is MiniCPM's embodied intelligence model family. Its first members are MiniCPM-RobotManip, a 1.5B manipulation policy, and MiniCPM-RobotTrack, a 0.9B tracker.
How do I run MiniCPM-RobotManip inference?
Create the conda environment from environment.yml, then run vla_infer.py with --image, --text and --checkpoint. It returns an action chunk of shape (30, 80).
Does MiniCPM-RobotManip beat larger models on every benchmark?
No. It beats pi0.5 on several columns, but Abot-M0, LingBot-VA, Qwen-VLA and StarVLA-alpha score higher on LIBERO, and LingBot-VA is higher on RoboTwin2 easy.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openbmb-minicpm-robot)Star history chart for your README
[](https://hysenlabs.com/projects/openbmb-minicpm-robot)Was this useful?