NornicDB wants to be Neo4j and Qdrant in one process, and its compose file ships with auth off
Nornicdb is a distributed low-latency, Graph+Vector, Temporal MVCC with all sub-ms HNSW search, graph traversal, and writes. Using Neo4j Bolt/Cypher and qdrant's gRPC means you can switch with no changes while adding intelligent features like schemas, managed embeddings, reranking+llm, GPU accel, Auto-TLP, Policy-based Memory Decay, and MCP server.
At a glance
- What is it?
- NornicDB is a Go database that speaks Neo4j's Bolt and Cypher, offers a Qdrant compatible gRPC endpoint, and adds MVCC historical reads on top. It is MIT licensed and moving quickly, with a preview tag in flight. The parts to read before anything else are the default compose settings and the line in the transaction section that puts search outside the historical view.
- Who is it for?
- Read the default compose settings first, because they are the part that decides whether this is safe to expose. The shipped file binds the address to 0.0.0.0, publishes HTTP, HTTPS, Bolt, and a Qdrant compatible gRPC port, and defaults `NORNICDB_NO_AUTH` to true while the JWT and OAuth variables sit there empty.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
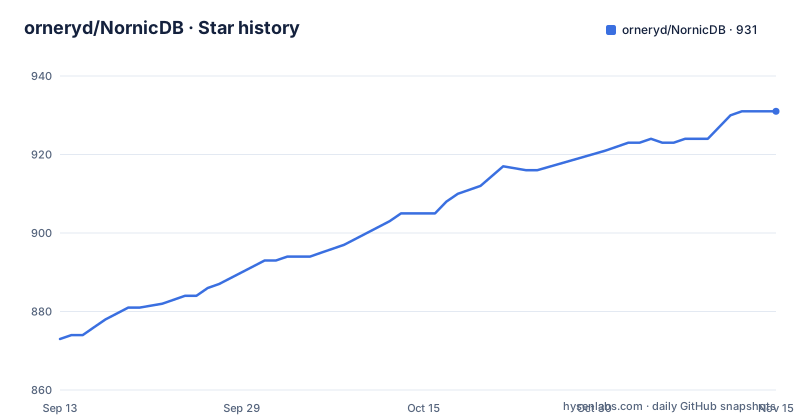
Star history
- orneryd/NornicDB931 ★ · +58
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| orneryd/NornicDB | 873 | 931 |
58 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Both upstream clients are dependencies, which is how the compatibility is built
The compatibility claim is not a shim written against a protocol description. The Go module requires the official Neo4j driver at v5 and the official Qdrant client, alongside a GraphQL stack built on gqlgen and a parser generator, a websocket library, a message pack codec, and three cloud key management wrappers for Google, AWS, and Azure.
That dependency choice is the design in one line. A graph database that wants to be a drop-in for Neo4j speaks Bolt and Cypher; one that wants to absorb a Qdrant deployment offers a gRPC compatibility endpoint, and the compose file publishes port 6334 for exactly that purpose. Both are labelled compatibility, and both are also the same storage engine underneath, which is the difference between migrating a client and migrating a system.
The interface list goes further than that: REST, GraphQL, Bolt and Cypher, Qdrant compatible gRPC, and an additive Nornic gRPC of its own, all described as living on one platform. The page's own slogan line is a Psygnosis reference, and the subheading is the one that describes the product: graph, vector, and historical truth in one database.
Search is deliberately kept out of the historical view
The transaction section is the most precise writing on the page. Snapshot isolation is implemented at the storage layer, and every transaction is anchored to a specific MVCC version, so point reads, label scans, and snapshot visible traversals all resolve against the same committed view.
The consequences are spelled out rather than implied. A transaction sees its own buffered writes but not commits that land after its read snapshot, which is what makes reads repeatable. Concurrent graph mutations against the same logical state fail at commit with a normalised `ErrConflict` rather than silently overwriting newer data. Pruning preserves the current head and a retained floor per logical key, and a request below that floor fails safely with `ErrNotFound` instead of returning a guess.
Then the line that changes how you should use the thing: search remains current state focused, and the current search paths are intentionally separate from historical MVCC state. So an as-of read and a semantic search are not looking at the same world. Any design that combines historical truth with retrieval has to decide which of the two it is asking, and this database will not reconcile them for you.
The compose file publishes four ports and defaults authentication off
The shipped compose file is where to look before the benchmarks. It builds from `docker/Dockerfile.arm64-metal-heimdall` with an argument that includes the bge-m3 embedding model in the image, and it publishes four ports: the HTTP API and browser UI, a native HTTPS API, the Bolt protocol port, and a hardcoded 6334 for the qDrant gRPC compatibility endpoint. All four are bound through variables that default to the standard values, so a plain `docker compose up` exposes all of them.
The environment block is where the risk is. `NORNICDB_ADDRESS` defaults to `0.0.0.0`. `NORNICDB_NO_AUTH` defaults to `true`. Alongside them sit `NORNICDB_AUTH`, `NORNICDB_AUTH_JWT_SECRET`, `NORNICDB_AUTH_PROVIDER`, `NORNICDB_AUTH_TOKEN_EXPIRY`, and a minimum password length, plus four OAuth variables for issuer, client id, client secret, and callback URL. Every one of those is present and every one defaults to empty.
So the default posture is an unauthenticated Bolt endpoint on all interfaces, which is a reasonable developer default and a poor production one. The variables to set are all there; nothing sets them for you.
Docker on macOS gives you the Metal image without the Metal
The quick start offers three ways in, starting with a Homebrew tap, a service start, and a Docker run per architecture. The images are named by architecture and accelerator, all under a Docker Hub organisation that is not the repository owner, and all with an embedded model in the tag:
# arm64 / Apple Silicon
docker run -d --name nornicdb -p 7474:7474 -p 7687:7687 -v nornicdb-data:/data timothyswt/nornicdb-arm64-metal-bge:latest

# amd64 / CPU only
docker run -d --name nornicdb -p 7474:7474 -p 7687:7687 -v nornicdb-data:/data timothyswt/nornicdb-amd64-cpu-bge:latest
Then the note that changes the meaning of the first command. Docker on macOS does not expose Metal acceleration. The Apple Silicon image still runs, but on that host it runs without a GPU, and acceleration requires either a native install from the releases page or a local build.
That makes the image name a description of what the binary supports rather than what your machine will get. The two ports in the run line are also fewer than the four the compose file publishes, so a quick start user gets no HTTPS and no Qdrant endpoint by default.
Two image naming schemes, and a build matrix smaller than the shipped images
The tags in the quick start and the tag in the compose file do not match. The quick start uses `timothyswt/nornicdb-arm64-metal-bge:latest`, and the compose file builds and tags `timothyswt/nornicdb-arm64-metal-bge-heimdall:latest`, with a commented out CUDA alternative sitting underneath it. So there are at least two naming conventions in circulation for what looks like the same artefact, and a reader who follows one and then greps for the other will not find it.
The Makefile documents the intended matrix, and it is smaller than the page's claim. It names two architectures, arm64 with Metal and amd64 with CUDA, and two variants of each: a base variant described as bring your own model, where models are mounted at runtime, and a BGE variant with the bge-m3 model pre-packaged. The targets follow that grid, with build and deploy for each cell and an all-in-one for the current architecture. Version and registry are variables defaulting to `latest` and to that same Docker Hub organisation, and the build stamps the commit and timestamp into the binary through linker flags.
The page claims four, though: CPU, CUDA, Metal, and Vulkan, and it names a Vulkan image in the quick start prose. So one accelerator is advertised and shipped without a documented build target.
A fourteen second benchmark, and one ratio that does not divide out
The performance section is a Northwind benchmark on an M3 Max with 64 GB, 48,000 products and 48,000 orders, ten measured iterations after two warmups. Four rows, each with a difference column.
Mean query latency is 0.23 ms against Neo4j's 98.64 ms, with a 432.38x ratio. Throughput is 17.70 against 7.76 ops per second. Wall clock is 14.00 s against 31.63 s. Energy during the benchmark is 118.00 J against 264.87 J. The page also states that all seed counts and per-query result fingerprints matched between the two systems, which is the detail that makes the rest worth reading.
Three of the four figures reconcile exactly from the rounded numbers: 7.76 to 17.70 is 2.28x and 128 percent, 31.63 to 14.00 is 2.26x, and 264.87 to 118.00 is 2.24x. The latency ratio does not: 98.64 divided by 0.23 is 429, not 432. That is a rounding artefact rather than a discrepancy, since 0.23 is given to two decimals, but it is the one number in the table you cannot reproduce from the table.
The scale is the other thing to hold in mind. A full run is fourteen seconds, and the dataset is under a hundred thousand entities on one machine.
The Go directive is patch pinned, and the test spec is written in Gherkin
The module declares `go 1.26.6`, which is a patch version rather than the language version the directive normally takes, so it pins a toolchain more tightly than most projects do.
Two dependencies in the main require block say more about how the project is built than how it is used. The Cucumber Gherkin and Godog packages sit alongside the drivers, which means the test suite is written as behaviour specifications rather than as Go tests alone. And `ebitengine/purego` is present, a foreign function interface library that calls native code without cgo, which is the piece that lets a project ship CUDA, Metal, and Vulkan images without a C toolchain in the build.
The rest of the module is a large but conventional surface: three cloud KMS wrappers, four OpenTelemetry packages plus a Prometheus exporter, the Neo4j and Qdrant clients, a GraphQL server and parser, cobra for the command line, testify, and a message pack codec. Nothing in that list is a red flag on its own; the Gherkin dependency and the patch pinned directive are the two that say something about process.
env.local sits at the root, and there are three Windows build scripts
The top level is long enough to be worth scanning for what should not be there. `env.local` is present as a tracked file, which is the name people give to machine specific settings that usually belong in an ignore list. `generated/` is tracked at the root as well, next to `models/`, `neural/`, `apoc/`, `resolvers/`, `plugins/`, `ui/`, and `lib/`.
Build tooling is split three ways by platform: `build.sh` alongside `build.bat`, `build.ps1`, and a separate `build-cuda.bat`. Documentation is built with mkdocs and a Python requirements file, in a Go project, and there is a `neo4j_import.py` at the root, so a handful of Python entry points are part of the distribution rather than an accident.
The governance files fill out the rest: `SECURITY.md`, `CONTRIBUTING.md`, `CONTRIBUTORS.md`, `CITATION.cff`, `PATENTS.md`, and `NOTICES.md`, alongside a custom hooks directory, a changelog, an agent instructions file, and an openspec directory.
Editorial conclusion
Read the default compose settings first, because they are the part that decides whether this is safe to expose. The shipped file binds the address to 0.0.0.0, publishes HTTP, HTTPS, Bolt, and a Qdrant compatible gRPC port, and defaults `NORNICDB_NO_AUTH` to true while the JWT and OAuth variables sit there empty. Set the auth provider and a secret, or bind to loopback, before that container is reachable by anything but your own machine. After that, this fits a team consolidating a Neo4j plus Qdrant plus embeddings stack into one deployment and willing to read the query cookbook. Three things to check next. Whether you need as-of reads together with semantic search, since the transaction section states search paths are kept separate from historical MVCC state. Whether the benchmark means anything at your size, since the published run is 48,000 products and 48,000 orders on a single machine and finishes in fourteen seconds. And whether you are on Metal, because the Docker path on macOS gives you the Apple Silicon image with no acceleration at all.
Frequently asked questions
How do I run NornicDB locally?
Three ways: brew tap orneryd/nornicdb && brew install nornicdb && brew services start nornicdb, or a docker run of one of the published images, for example timothyswt/nornicdb-arm64-metal-bge:latest on Apple Silicon and timothyswt/nornicdb-amd64-cpu-bge:latest on CPU only. The admin UI is at http://localhost:7474.
Does the NornicDB Docker image get GPU acceleration on macOS?
No. The page states Docker on macOS does not expose Metal acceleration, so the Apple Silicon image still runs without it. Acceleration on that host needs a native install from the releases page or a local build.
Does NornicDB enable authentication by default?
Not in the shipped compose file, where NORNICDB_NO_AUTH defaults to true and NORNICDB_ADDRESS defaults to 0.0.0.0, with the JWT secret, auth provider, token expiry, and OAuth variables present but empty. Four ports are published, including Bolt on 7687 and 6334 for the qDrant gRPC compatibility endpoint.
Can NornicDB read historical versions of the graph?
Yes, through MVCC. Transactions anchor to a specific version, concurrent mutations fail at commit with a normalised ErrConflict, and requests below the retained floor fail with ErrNotFound. Search is separate, since the current search paths are intentionally kept apart from historical MVCC state.
How does NornicDB compare to Neo4j on the Northwind benchmark?
On an M3 Max with 64 GB, 48,000 products and 48,000 orders, ten measured iterations after two warmups: 0.23 ms mean query latency against 98.64 ms, 17.70 ops/s against 7.76, 14.00 s wall clock against 31.63 s, and 118.00 J against 264.87 J, with seed counts and result fingerprints matching between the two.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/orneryd-nornicdb)Star history chart for your README
[](https://hysenlabs.com/projects/orneryd-nornicdb)Was this useful?