the oxylabs web-scraper-api repository is a map of a paid service, not code
All-in-one web scraping API for real-time, large-scale data extraction – proxies, CAPTCHA management, JS rendering, and parsing in a single request returning HTML or structured JSON.
At a glance
- What is it?
- The repository holds a README and two banner images: no source, no client library, no releases and no licence file. What the README does contain is a developer-facing description of a commercial scraping API that folds proxy rotation, access management, CAPTCHA handling, JavaScript rendering and parsing into one request, with dedicated sources for named targets.
- Who is it for?
- Read this repository as documentation for a commercial service rather than as a project you adopt. It contains no code, no client library and no licence, so there is nothing to vendor, fork or self host, and the only decision it supports is whether to buy the service.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 45 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
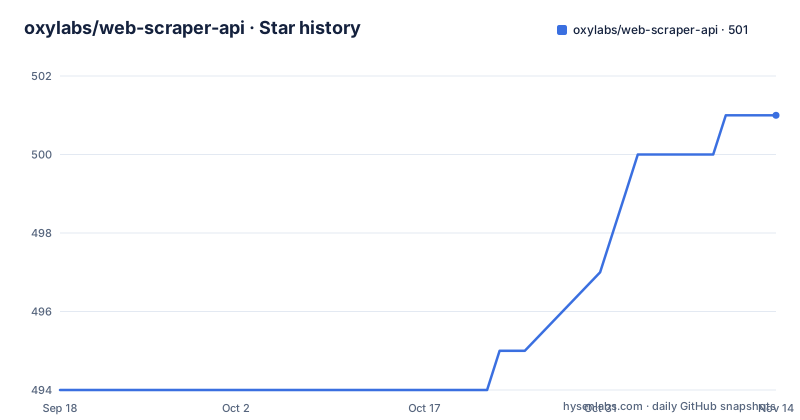
- oxylabs/web-scraper-api501 ★ · +7
| Repository | 2026-09-18 | 2026-11-14 |
|---|---|---|
| oxylabs/web-scraper-api | 494 | 501 |
7 Stars in the last 57 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A README and two banner images, with the product living elsewhere
The repository holds three files: a README, a PNG named Github repositories banner [email protected], and a JPG banner sized 1532 by 354. There is no source directory, no package manifest, no licence file and no release history, and GitHub does not report a primary language for it at all. One fork, no open issues, and a last push on 1 October 2026. What the opening line of the README says it is, in its own words, is the official repository overview for the product: a developer-focused technical reference that doubles as the central hub linking to all the related repositories, code examples and integrations. That framing decides how to read everything else on the page. There is nothing to install from this repository and nothing to import, so an engineer evaluating it is reading a map of a hosted service rather than reading code. The banner images give the game away. The purpose of the page is to send you somewhere else, to a dashboard, to developer documentation, or to a sibling repository that holds the examples. Judged as a repository it is thin, and judged as a landing page it is doing a specific and useful job, which is telling a developer what the product is composed of before they ever see a pricing page.
Proxy rotation, CAPTCHA handling and parsing folded into one request
The central claim is consolidation. Proxy rotation, automated access management, CAPTCHA handling, JavaScript rendering, parsing and delivery sit behind a single endpoint, and the stated alternative to that is assembling a proxy provider, an unblocking layer, a browser automation setup and a parser yourself. The request lifecycle is described as handling IP interruptions and CAPTCHA challenges automatically, and the proxies come from what the vendor calls an ethically sourced network, which is a sourcing claim rather than a technical one and worth reading as such. The compliance framing is specific: SOC 2 Type II, on infrastructure maintained by the vendor's own engineering team. For a buyer that combination answers the two questions a self-built stack raises first, namely who operates the proxies and who answers when a target changes its markup. It also moves the failure modes somewhere else. Blocked requests, degraded results and rendering timeouts stop being your code's problem and become the vendor's, which saves maintenance hours and costs you control at the same time. Nothing on the page prices that trade, and the sentence that would let you evaluate it, a comparison with assembling the same stack yourself, is a ToC entry rather than a paragraph.
Dedicated sources replace the parsing code you would otherwise write
There are two ways to ask for data. A universal source works against any public website and returns what that site returns, while dedicated sources are tuned for named targets and hand back structured JSON without you writing or maintaining parsing logic. The named list is long and specific. Search: Google Search, Google Ads, Google Trends, Google Lens, Google Scholar and Bing. AI platforms: ChatGPT, Perplexity and Google AI Mode. Marketplaces, among others: Amazon, Walmart, eBay, Etsy, Best Buy, Target, Costco, AliExpress, Alibaba, Lazada, Flipkart and MercadoLibre, with the full catalogue linked off the page. For those targets a request does not have to carry a URL at all. You can send a search query, a product ID or a video ID instead and let the source resolve it, or keep the raw response and ask for structure by setting "parse": true. That flag is the whole parsing story for anyone whose target is on the list, and the trade is straightforward. You give up the ability to change extraction the moment the target changes, and in exchange you get field names the vendor already settled on, which is the difference between a scraper that survives a redesign and one that needs a rewrite.
render html or png, and browser_instructions for the clicks in between
Pages that assemble their content in the browser need rendering, and the Custom Browser feature covers it through a render parameter with two values. Set it to html and the response is the rendered page; set it to png and you get a Base64-encoded screenshot, which is the option for something you need to look at rather than parse. The second half is browser_instructions, a list of typed actions passed along with the request, and the example given is a real search flow rather than a placeholder:
{
  "source": "universal",
  "url": "https://www.ebay.com/",
  "render": "html",
  "browser_instructions": [
    { "type": "input", "value": "pizza boxes", "selector": { "type": "xpath", "value": "//input[@class='gh-tb ui-autocomplete-input']" } },
    { "type": "click", "selector": { "type": "xpath", "value": "//input[@type='submit']" } },
    { "type": "wait", "wait_time_s": 5 }
  ]
}
Three instruction types show up in that example: input with a value and a selector, click with a selector, and wait with a duration in seconds. Selectors are expressed as xpath, which is the less convenient choice for anyone who keeps their selectors in CSS elsewhere, and worth knowing before you build a library of instructions. The waits are timed rather than condition based, so an instruction set that pauses five seconds for results is making an assumption about a third-party page, and that assumption is the piece that needs editing first when the page is redesigned. The Playground in the vendor dashboard is where instruction sets get generated and tested without hand-editing JSON, which is the practical answer to that fragility.
geo_location means different things depending on the source category
Localization here is a parameter whose behaviour depends on what you are asking for, and that is the detail worth reading twice. geo_location selects the proxy server location so the response looks like it came from a particular country, state or city. For SERP sources it adjusts the results page to reflect what users in that location would see. For e-commerce sources, certain marketplaces require specific values, and the per-target documentation is where you find out which ones. Three further parameters narrow a request independently: domain sets the top-level domain, locale sets the interface language, and results_language sets the language of the results. That separation matters because a search interface does not localize the way the request's apparent location does, and one knob cannot express both. For an engineer the practical consequence is that geo_location is not a proxy setting you tune once. It is a per-target contract, and the marketplace exceptions mean a pipeline that assumes a single value works everywhere will be quietly wrong somewhere, which is the kind of bug that shows up as empty results rather than as an error.
Custom Parser is free, and Parser Presets are the part that scales
Custom Parser is described as a free feature, and it is the layer that sits on top of a raw response: you define the parsing logic, and what comes back is a structured object containing only the fields you care about. It is configurable through the API or through the dashboard. The adjacent feature, Parser Presets, is where reuse lives, since it saves and manages parsing configurations so one extraction can be applied across jobs instead of being redefined per request. This is the part of the product that most resembles code you would otherwise write yourself, with one difference that matters operationally: the parser runs on the vendor side, so changing it is changing a remote configuration rather than making a commit. That is convenient right up to the point where a field you depend on quietly stops coming back. Whether presets are versioned, pinned or rolled back is not something this repository explains, so treat a preset as something you would pin yourself, and keep the field list you depend on written down somewhere you control.
Web Unblocker, Agent Browser, Scheduler and OxyCopilot appear as names
The table of contents promises the parts of an evaluation you would otherwise have to chase: how the service works, integration methods, a request example, supported targets, common use cases, output formats and delivery, and rate limits together with batch requests. It also sets up a three-way comparison between Web Scraper API, Web Unblocker and Agent Browser, with a subsection on when to choose each, which is the standard way to present a product line that spans a full extraction API and a lighter unblocking product aimed at a different buyer. Two more names appear as feature headings with nothing attached: Scheduler and OxyCopilot. The repository does not document what either one does beyond its heading, so both need looking up in the dashboard before they enter a decision. Pricing is the other absence: no price appears anywhere in the repository text, and the page routes readers instead to the product site, a Discord server and a YouTube channel, which is also why the free-trial and pay-as-you-go questions that dominate search traffic for this category are answered somewhere other than here.
Editorial conclusion
Read this repository as documentation for a commercial service rather than as a project you adopt. It contains no code, no client library and no licence, so there is nothing to vendor, fork or self host, and the only decision it supports is whether to buy the service. Adopt it when you need structured data from named targets at volume and would rather not maintain proxies, rendering and parsing yourself, since the SOC 2 Type II claim and the vendor-operated infrastructure are the parts of the pitch that answer procurement. Look elsewhere when the requirement is a single site, a one-off crawl, or anything that has to run inside your own network, because none of those are what this product is shaped for. Three things to check before signing anything. What the rate limits and batch request behaviour actually are, since the table of contents names that section but the repository does not carry the numbers. What Custom Parser presets do when a target changes its markup. And what Scheduler and OxyCopilot turn out to be, since both appear here as headings and nothing more.
Frequently asked questions
What is the oxylabs web-scraper-api repository for?
It is the official overview and documentation hub for Oxylabs' Web Scraper API, linking to the related repositories, code examples and integrations. The repository itself contains a README and two banner images, with no source code, no releases and no client library, so nothing there can be installed or imported.
Does Web Scraper API replace my proxy and CAPTCHA handling setup?
That is the stated design: proxy rotation, automated access management and CAPTCHA handling happen inside the request lifecycle, along with JavaScript rendering and parsing, behind one endpoint. The vendor describes the proxies as coming from its own ethically sourced network and claims SOC 2 Type II compliance.
Can Web Scraper API render JavaScript-heavy pages and interact with them?
Yes. The render parameter takes html for rendered markup or png for a Base64-encoded screenshot, and the browser_instructions parameter takes a list of typed actions such as input, click and wait with xpath selectors and a wait time in seconds. Instruction sets can be generated and tested in the Playground in the Oxylabs dashboard.
Which sites does Web Scraper API have dedicated sources for?
Named dedicated sources cover Google Search, Google Ads, Google Trends, Google Lens, Google Scholar and Bing, the AI platforms ChatGPT, Perplexity and Google AI Mode, and marketplaces including Amazon, Walmart, eBay, Etsy, Best Buy, Target, Costco, AliExpress, Alibaba, Lazada, Flipkart and MercadoLibre. A universal source handles any other public website, and setting "parse": true returns structured JSON instead of HTML.
Is the Custom Parser feature free?
Custom Parser is described as a free feature that lets you define parsing logic on top of a raw scraping result and return only the fields you need in a structured format. It is configurable through the API or the dashboard, and Parser Presets let you save, manage and reuse those parsing configurations across jobs.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oxylabs-web-scraper-api)Star history chart for your README
[](https://hysenlabs.com/projects/oxylabs-web-scraper-api)Was this useful?