PaddleNLP 3.0: the Makefile installs a nightly CPU build, the lint target watches directories that are gone, and the beta tags stopped in 2025
Easy-to-use and powerful LLM and SLM library with awesome model zoo.
At a glance
- What is it?
- A look at how PaddleNLP is actually wired for developers: a Makefile install that reaches for a nightly PaddlePaddle index, a lint target that only inspects a stale list of directories, a test suite with taskflow commented out, and a set of published tags that stopped at rl-v1.0.0 in May 2025.
- Who is it for?
- PaddleNLP fits teams already committed to the PaddlePaddle framework who need training, checkpointing, compression and serving to move as one pipeline, and who can accept that the LLM suite ships under beta tags. It does not fit a team that wants a stable pin today: the newest tags are rl-v1.0.0 from 2025-05-21 and v3.0.0-beta4 from 2025-03-12, while the develop branch received commits on 2026-05-23.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 175 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
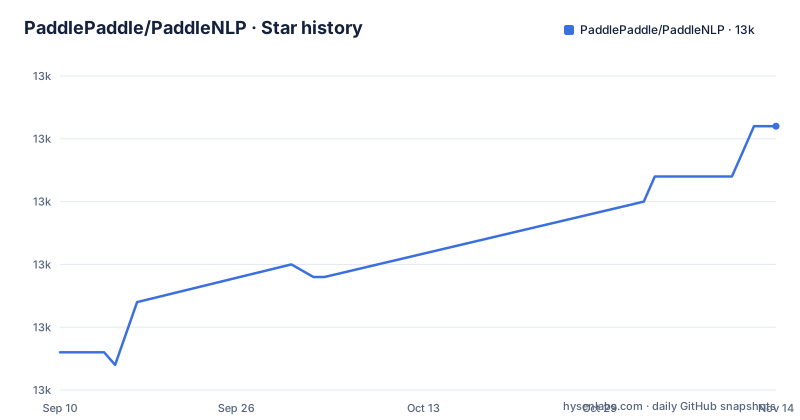
- PaddlePaddle/PaddleNLP12,991 ★ · +18
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| PaddlePaddle/PaddleNLP | 13k | 13k |
18 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
make install pulls a nightly CPU build of PaddlePaddle
The documented developer setup is a Makefile target, and its first line installs a pre-release.
install:
	pip install --pre paddlepaddle -i https://www.paddlepaddle.org.cn/packages/nightly/cpu/
	pip install -r requirements-dev.txt
	pip install -r requirements.txt
	pip install -r paddlenlp/experimental/autonlp/requirements.txt
	pre-commit install
The --pre flag combined with the nightly CPU index means you get the newest CPU build of PaddlePaddle, not a stable release. Nothing in that target installs a GPU build, so anyone targeting an accelerator has to source that package separately and reconcile it with the framework version the nightly picked. The target also installs three separate requirements files, one of them from a subdirectory, and registers pre-commit hooks at the end, so a fresh checkout changes your local git behaviour as part of setup.
make lint scans a directory list that no longer matches the repository root
The lint target decides what to check by listing directories itself.
check_dirs := applications examples model_zoo paddlenlp pipelines ppdiffusers scripts tests

lint:
	$(eval modified_py_files := $(shell python scripts/get_modified_files.py $(check_dirs)))
	@if test -n "$(modified_py_files)"; then \
		echo ${modified_py_files}; \
		pre-commit run --files ${modified_py_files}; \
	else \
		echo "No library .py files were modified"; \
	fi
applications, examples, model_zoo, pipelines and ppdiffusers do not appear among the tracked top-level entries, while llm/, slm/, csrc/, ops/, tools/ and docs/ do and are absent from check_dirs. The consequence for your patch is quiet: edit files under llm/ or slm/ and the target prints No library .py files were modified and exits successfully. A green lint run is not evidence your changes were formatted.
tests/taskflow is commented out of the pytest paths with a paddle 2.5.1 note
The pytest configuration in pyproject.toml enumerates the suites that run, and one line is disabled in place.
testpaths = [
    "tests/data",
    "tests/dataaug",
    ...
    # "tests/taskflow",  TODO (paddle 2.5.1 breaks this test suite, debug later)
    "tests/utils",
    "tests/longlora",
]
The exclusion is recorded with a reason tied to a specific PaddlePaddle release, so taskflow coverage is knowingly absent rather than forgotten. Two more settings change what a green run means. python_files accepts both test.py and test_*.py, so a test file named either way counts, and filterwarnings ignores UserWarning and DeprecationWarning wholesale, which means a deprecation introduced by your dependency upgrade will not reach your console. addopts is only -ra -q, so verbosity comes from the Makefile rather than the config.
Requirements hold numpy, datasets and pyarrow below current ceilings
requirements.txt is a mix of loose names and hard upper bounds, and the bounds are old.
dill<0.3.5
multiprocess<=0.70.12.2
datasets==3.6.0
pyarrow==20.0.0
numpy<=1.26.4
tokenizers<=0.20.3; python_version<="3.8"
tokenizers>=0.21,<0.22; python_version>"3.8"
fast_dataindex>=0.1.1 ; platform_system == "Linux"
Two of these lines change behaviour by interpreter: on Python 3.8 or older you resolve tokenizers 0.20.3 or older, and above it you resolve 0.21 or newer but below 0.22, so the tokenizer in your environment is not the same artifact across the versions you might run. fast_dataindex is Linux-only, so a macOS install simply lacks it.
For numpy, datasets and pyarrow the practical effect is that pip resolves downward to satisfy this file. Any project in the same virtual environment needing a newer datasets or a numpy above 1.26.4 will conflict, and the resolution belongs to you rather than to the toolkit.
The tags stopped in May 2025 while the develop branch kept moving
Look at the published versions against the branch activity. The three most recent tags are rl-v1.0.0 dated 2025-05-21, v3.0.0-beta4 dated 2025-03-12 and v3.0.0-beta3 dated 2024-12-16, and the default branch is develop rather than main. The last push to the repository is 2026-05-23.
Two things follow. First, the LLM suite has shipped under v3.0 beta tags since June 2024, so a pin on v3.0.0-beta4 is a pin on a preview line rather than a stable one. Second, the stable-looking v1.0.0 belongs to the reinforcement learning component, which is versioned on its own track from the LLM package, so version numbers alone will not tell you whether a given feature is in the release you installed.
The gap between the March 2025 beta tag and the May 2026 commit date also means what you get from pip and what sits in develop can differ, and nothing in the repository marks the boundary.
Unified Checkpoint is the piece that survives a change in machine count
Resume behaviour is handled by a storage tool rather than by a trainer flag, and the reported numbers are specific.
Asynchronous saving is credited with making model storage 95% faster, and checkpoint compression with saving 78.5% of storage space. The same release notes describe a unified train, compress and inference storage protocol that needs no manual conversion. The v3.0 beta3 entry adds optimizer state offloading and reloading plus fine-grained recomputation, credited with a 7% training performance improvement, and beta3 also added a checkpoint compression feature.
The dynamic scaling claim covers resuming a training run after machines are added or removed, and the Unified Checkpoint write-up also claims adaptive conversion when the distributed strategy is adjusted. And the percentages are release-specific figures attached to one beta, so treat them as the state of that release rather than as a property of the current develop branch.
The throughput numbers are single-machine and tied to specific models
The inference claims attach to named models and one box. Full quantization support is stated for the full DeepSeek V3 and R1 models across FP8, INT8 and 4-bit, with MTP speculative decoding, and single-machine output reported above 1000 tokens/s for FP8 and above 2100 tokens/s for 4-bit. Beta3 separately records an upgraded Append Attention with FP8 quantization and speculative decoding.
Read those figures with their scope attached. Single-machine output is not multi-node throughput, so a capacity plan built on them will be wrong the moment you span more than one host. The figures also belong to the DeepSeek family and to a released inference image, not to every model in the zoo, and the Qwen3 support announced on 2025-04-29 comes with no throughput number attached at all. Model support and inference performance are two separate claims here, and only one of them is measured in the notes.
Five accelerator families are listed, but the same interface is the only thing shared
The hardware line names NVIDIA GPU, Kunlun XPU, Ascend NPU, Enflame GCU and Hygon DCU for both training and inference of large models and natural language understanding models, and the claim is that the suite interface supports fast switching to lower the cost of moving between them. Training parallelism is described as 4D: pure data parallel, grouped parameter sliced data parallel, tensor model parallel and pipeline model parallel, with the Trainer taking distributed strategy configuration.
The mechanism behind the memory claims is narrower. FlashMask is a column sparse attention mask representation described as unique to the Paddle framework, and fine-tuning throughput is attributed to combining zero-padded data flow with that operator. The repository carries csrc/ and ops/ directories at the root. Interface-level portability does not mean every operator exists on every listed accelerator, and the notes do not map operators to devices.
Editorial conclusion
PaddleNLP fits teams already committed to the PaddlePaddle framework who need training, checkpointing, compression and serving to move as one pipeline, and who can accept that the LLM suite ships under beta tags. It does not fit a team that wants a stable pin today: the newest tags are rl-v1.0.0 from 2025-05-21 and v3.0.0-beta4 from 2025-03-12, while the develop branch received commits on 2026-05-23. Before you build on it, read requirements.txt and check its upper bounds against your own environment, confirm which accelerator you need is covered by the ops and csrc kernels, and run the test suite knowing that taskflow is excluded.
Frequently asked questions
What is PaddlePaddle GPU?
PaddleNLP names NVIDIA GPU among the hardware it trains and serves large models on, alongside Kunlun XPU, Ascend NPU, Enflame GCU and Hygon DCU. Its Makefile install target only installs a nightly CPU build of PaddlePaddle, so a GPU build is a separate step the project does not script for you.
Does PaddleNLP need a nightly build of PaddlePaddle?
The repository's own install target runs pip install --pre paddlepaddle against the nightly CPU index at paddlepaddle.org.cn, so a nightly pre-release is what the scripted developer setup gives you. A released PaddlePaddle version is not what that target installs.
Why does the PaddleNLP test run skip taskflow?
In pyproject.toml the tests/taskflow entry is commented out with the note TODO (paddle 2.5.1 breaks this test suite, debug later). The exclusion is deliberate and version specific, so a full green run of the configured testpaths does not include taskflow coverage.
Which models and compression paths does PaddleNLP 3.0 cover?
Model parameter support is listed for the LLaMA, Baichuan, Bloom, ChatGLM, Gemma, Mistral, OPT and Qwen series, and Qwen3 support was announced on 2025-04-29 with six dense sizes and two mixture of experts weight sets. The v3.0 beta4 notes record FP8, INT8 and 4-bit quantized inference for the full DeepSeek V3 and R1 models with MTP speculative decoding.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paddlepaddle-paddlenlp)Star history chart for your README
[](https://hysenlabs.com/projects/paddlepaddle-paddlenlp)Was this useful?