PaddleFormers trains 100+ models, but make install insists on CUDA
PaddleFormers is an easy-to-use library of pre-trained large language model zoo based on PaddlePaddle.
At a glance
- What is it?
- PaddleFormers is a Transformers-shaped training library built on PaddlePaddle, covering 100+ LLM and VLM families with tensor, pipeline, expert and context parallelism, gated behind an install target that refuses to run without nvcc.
- Who is it for?
- PaddleFormers fits teams that have already chosen PaddlePaddle, hold Kunlunxin P800 or TianShu TianGai 150 hardware, and want a Transformers-shaped interface plus deepseek3, glm4_moe or ernie chat templates for pretraining and SFT. It does not fit a CPU-only box, because make install stops at the nvcc check, and it does not fit a stack already pinned to transformers 4.x, because requirements.txt demands 5.0.0 or newer.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
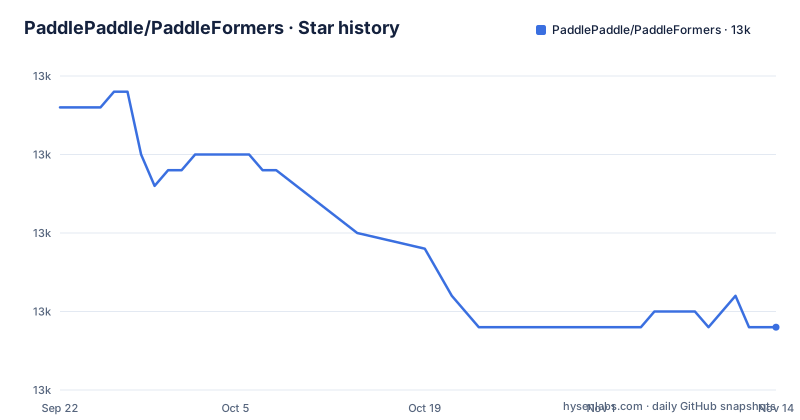
- PaddlePaddle/PaddleFormers12,969 ★ · -14
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| PaddlePaddle/PaddleFormers | 13k | 13k |
-14 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The install target stops before pip is ever reached
The first thing the Makefile install target does is refuse to continue without a CUDA compiler. This is that guard, copied from the file:
	@echo "Checking CUDA version and selecting pip source..."
	@if ! command -v nvcc >/dev/null 2>&1; then \
	    echo "ERROR: nvcc (CUDA) not found. Please install CUDA before proceeding."; \
	    exit 1; \
	fi; \
	cuda_version=$$(nvcc --version | grep release | awk '{print $$5}' | sed 's/,//'); \
	echo "Detected CUDA version: $$cuda_version"; \
	if [ "$$cuda_version" = "12.6" ]; then \
	    PADDLE_SOURCE="https://www.paddlepaddle.org.cn/packages/nightly/cu126/"; \
The check runs before any wheel index is chosen, so a workstation with no CUDA toolkit cannot install through this target at all, whatever you intend to do afterwards. The library's own test recipe is plain pytest, so the block is specific to installation rather than to using the code. What is left for you on a machine without nvcc on PATH is editing the Makefile by hand or finding another route, and the README is written in Chinese, its navigation bar linking sections labelled 安装 and 快速体验, so plan for reading the longer docs under docs/ as well.
A nightly wheel index picked by string match on the nvcc version
After the guard, the target derives cuda_version by grepping the release line out of nvcc --version and stripping the comma, then compares that string against a list. The first branch maps 12.6 to a nightly cu126 index and a second branch begins for 12.9. Selection is a string comparison, not a capability probe. The URL the target picks is a nightly build directory, so the PaddlePaddle underneath your training run is whatever that directory held on the day you ran it. requirements.txt never names PaddlePaddle at all, which means the framework version is decided by the calendar and by your local CUDA, not by anything you wrote down.
transformers is capped below 5.4.0 and two extras are Linux only
requirements.txt is the install's dependency source, setup.py reads it through read_requirements_file, and it is a flat list with no extras to select from. Three entries shape what you can install alongside. transformers>=5.0.0, <5.4.0 carries an upper bound, so an environment already on 4.x cannot be extended into this one, and a clean install stops resolving the moment the newest 5.x moves past the ceiling. paddlecodec>=0.2, <0.3; sys_platform == 'linux' and fast_dataindex>=0.1.1 ; platform_system == "Linux" are gated to Linux, spelled with two different marker styles, so macOS skips the codecs and the data indexing they carry. Everything else is unconditional, including visualdl, librosa, tiktoken and GPUtil, so even a minimal pull brings visualization and audio libraries with it. Because the file is read at install time, a change to it reaches your environment on the next build.
develop is the default branch and one release tag lost its v prefix
The repository is not archived and its last push was on 2026-10-21, under Apache-2.0 with the terms in the LICENSE file. Two details matter before you pin a version. The default branch is develop, so a plain clone lands on the integration branch, and setup.py derives the package revision from git HEAD through git_revision and is_dirty, which means a local build records a develop commit rather than a tagged release. The tag prefixes are also uneven: the recent list gives v1.2.0 from 2026-06-19, then 1.1.1 from 2026-04-02, then v1.0.0 from 2026-01-21. Anything that parses tags expecting a leading v silently misses 1.1.1. The changelog dates drift from the release dates as well, with the v1.1 entry dated 2026.03.31 while the 1.1.1 release is stamped 2026-04-02. setup.py also defines PADDLEFORMERS_STABLE_VERSION, an environment-shaped name for a stable version override.
The chat template column gives ERNIE two names and Qwen2 a duplicate
Each row of the README model table binds a family to a chat template name, and that pairing is the part you have to copy correctly into a training config. Most rows name one: deepseek3 for DeepSeek-V3, DeepSeek-V3.2, DeepSeek-V4-Pro and DeepSeek-V4-Flash, glm4_moe for the four GLM-4.5 checkpoints, seed_oss for the ByteDance-Seed 36B pair, jinja for OLMo2, granite for granite-3.2, gpt for openai/gpt-oss. The ERNIE-4.5 row is the exception. It carries seven checkpoints, one of them baidu/ERNIE-4.5-21B-A3B-Thinking, and offers two template names, ernie and ernie_nothink, without saying which checkpoint takes which. The Qwen2 row also repeats Qwen/Qwen2-0.5B-Instruct after having named it once already. Neither slip changes what trains, but both mean the table is a document, not something you can import: it is where this mapping is written down.
Parallelism strategies are named without a single flag to set
The README names the distributed surface in prose only. The introduction lists tensor, pipeline and expert parallelism, and the release notes and feature list add CP context parallelism, Document Mask, Packing data flow, FP8 low precision training, FlashMLA attention operators, a fused FP8 MoE module, DeepEP and HybridEP expert parallelism communication libraries, TileLang fused operators, and MoE Auto-Subbatch dynamic memory load balancing. DeepSeek-V4's CSA+HCA hybrid attention, mHC residual connections and the Muon optimizer appear the same way, with performance described as clearly beating Megatron-LM on DeepSeek-V3 and GLM-4.5-Air. Not one of these terms comes with a config key, module path or class name. What you get as a handle is a single linked path, ./examples/best_practices/DeepSeek-V4/, and four directories: examples/best_practices/, examples/config/, examples/experiments/ and examples/tools/. Whether a strategy is on by default is not stated.
Training stops at the checkpoint and hands off to vLLM or SGLang
The scope is training, and the handoff at the end is deliberate. Pretraining through post-training is claimed, and the post-training line names CPT, SFT, SFT-LoRA, DPO and DPO-LoRA, closing with 等 rather than a closed enumeration, so an algorithm outside that set is unconfirmed rather than absent. Function Call and Thinking training are called out as model capabilities, with Data Packing and Padding Free named as the data path techniques. v1.1 adds MTP single step and multi step training for GLM-4.5 plus a trunk freeze switch for the MTP modules. Weights come out in Safetensors, the same format hosted on Hugging Face, so they load in FastDeploy, vLLM or SGLang. If your requirement includes serving, this repository ends at the checkpoint and a second framework takes over, which means serving defects surface in code you do not own.
The test suite runs with UserWarning and DeprecationWarning muted
pyproject.toml points pytest at nine functional testpaths plus a coverage_test tree, and the collection rules are narrow:
addopts = "-ra -q "
pythonpath = ["."]
python_files = [
    "test.py",
    "test_*.py"
]
filterwarnings = [
    "ignore::UserWarning",
    'ignore::DeprecationWarning',
]
Both ignore rules are global for the run, so a green result cannot tell you whether a PaddlePaddle API you depend on is already emitting a deprecation warning. The layout does, however, map capability to directories: tests/trainer, tests/peft, tests/mergekit, tests/generation, tests/nn, tests/dataset and tests/data, with coverage_test repeating those areas under cli, quantization, transformers and utils. The Makefile unit-test recipe sets DOWNLOAD_SOURCE=aistudio, then runs pytest with --retries 1 --retry-delay 1, --durations 20 and --cov=./paddleformers. A feature with no matching directory has no test asserting it works.
Editorial conclusion
PaddleFormers fits teams that have already chosen PaddlePaddle, hold Kunlunxin P800 or TianShu TianGai 150 hardware, and want a Transformers-shaped interface plus deepseek3, glm4_moe or ernie chat templates for pretraining and SFT. It does not fit a CPU-only box, because make install stops at the nvcc check, and it does not fit a stack already pinned to transformers 4.x, because requirements.txt demands 5.0.0 or newer. Check two things before committing: that your CUDA version string appears in the install target's branch list, and that the chat template name for your checkpoint exists in the README table, which is where that mapping is written down.
Frequently asked questions
How do I install PaddleFormers, and do I need a GPU?
The make install target requires nvcc on PATH and exits with "ERROR: nvcc (CUDA) not found. Please install CUDA before proceeding." when it is missing, then reads the CUDA release string to pick a PaddlePaddle wheel index such as https://www.paddlepaddle.org.cn/packages/nightly/cu126/.
Which model families can PaddleFormers train?
It claims training support for 100+ mainstream LLM and VLM families, including DeepSeek-V3, DeepSeek-V3.2, DeepSeek-V4-Pro and DeepSeek-V4-Flash, GLM-4.5, Qwen2, Qwen3, Qwen3-VL, ERNIE-4.5, ERNIE-4.5-VL and PaddleOCR-VL, with table rows for gemma3, gpt-oss, Seed-OSS, Granite, Llama-3, MiniMax-Text-01, OLMo2, phi-4 and Cohere aya.
Can PaddleFormers serve models, or only train them?
Training only. Completed models are saved in Safetensors, the same weight format hosted on Hugging Face, and are intended to be used in any framework or tool that supports that format, such as FastDeploy, vLLM or SGLang.
How does PaddleFormers compare to Hugging Face Transformers and Megatron-LM?
It is built as a Transformers library on PaddlePaddle, aiming to give the PaddlePaddle ecosystem model interfaces and a feature experience equivalent to Hugging Face Transformers. On performance it states training clearly exceeds Megatron-LM on DeepSeek-V3 and GLM-4.5-Air, and that Qwen3-VL 30B-A3B is 48 percent better than the previous version and 6 percent ahead of Megatron-LM, without stating the hardware or configuration behind those figures.
Does PaddleFormers run on domestic Chinese compute chips?
It states support for Kunlunxin P800, TianShu TianGai 150 and MetaX C550, and that DeepSeek V3 SFT on 128 Kunlunxin P800 cards is the smallest domestic compute post-training solution. PaddleOCR-VL was adapted on Kunlunxin P800 and TianShu TianGai 150 in the v1.0 release.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paddlepaddle-paddleformers)Star history chart for your README
[](https://hysenlabs.com/projects/paddlepaddle-paddleformers)Was this useful?