ParadeDB: one Postgres extension, a curl install with no version pin, and a source build that starts at pg_config
One Postgres for your application data, full-text search, vector retrieval, and aggregations. Home of the pgsearch extension.
At a glance
- What is it?
- ParadeDB adds BM25 full-text search, vector retrieval, hybrid search and aggregations to Postgres through the pg_search extension. The easy install is a single piped script, and the work of pinning, building and versioning it is all in the build system rather than in the docs.
- Who is it for?
- Try the curl install to see whether the query surface fits your application, then plan the real deployment deliberately: pin a final tag rather than the branch, budget for the aggregates reference pages, and confirm with the vendor which capabilities are community and which need a commercial licence before you self-host anything.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
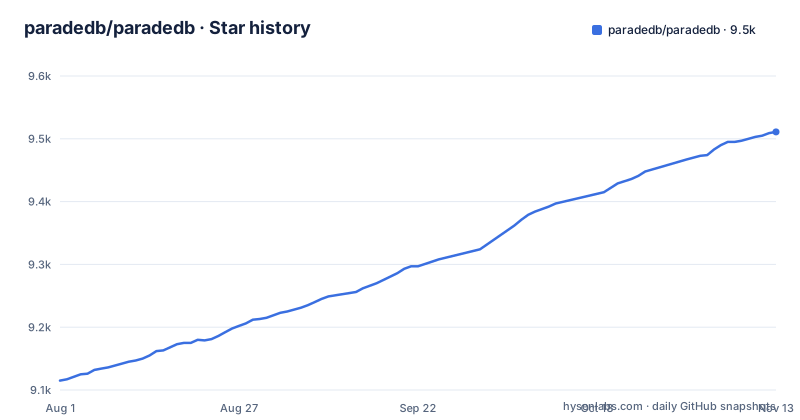
Star history
- paradedb/paradedb9,511 ★ · +396
| Repository | 2026-08-01 | 2026-11-13 |
|---|---|---|
| paradedb/paradedb | 9.1k | 9.5k |
396 Stars in the last 104 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The local install is one curl pipe with no version argument to pin
Getting ParadeDB onto a machine is a single line, and that line is the entire installation section:
curl -fsSL https://paradedb.com/install.sh | shAfter it, you open a psql session against the local instance and query through the pg_search extension. Two details matter before you reuse that line anywhere else. The script is fetched and piped straight into sh, so whatever the endpoint serves at that moment is what executes, and the command carries no version flag, no digest and no checksum, which means there is no documented way to hold that line at v0.26.4 or at any other release. Second, the same page then points you elsewhere for anything lasting: ParadeDB Cloud for a fully managed experience, or the self-hosted deployment options. So the curl line is an evaluation shortcut, not an artifact you can pin in a release process. Teams who need a fixed build can compile the extension themselves, and that path has its own prerequisites, covered next.
The source build starts at pg_config and PGXS, not at cargo
ParadeDB is a Postgres extension built through pgrx, and the Makefile shows where a build actually begins. Its variables are scraped rather than declared: PG_CONFIG defaults to whatever which pg_config returns, the distribution name is read from the name field of pg_search/Cargo.toml, the version comes from the workspace Cargo.toml, the pgrx version is pulled out of Cargo.toml with a single perl expression, and the Postgres major version comes from pg_config --version. Then the file includes PGXS:
PGXS := $(shell $(PG_CONFIG) --pgxs)
include $(PGXS)
That include is the hard prerequisite. Without a Postgres installation that provides both pg_config and its PGXS makefile fragment there is no build at all, however complete your Rust toolchain is. The init step then binds the result to one server major version:
pgrx-init: pg_search/Cargo.toml
	@cargo pgrx init "--pg$(PGV)"="$(PG_CONFIG)"
Since PGV comes from the locally installed pg_config, what you compile is for that major version, and the same binding appears in both the package and install targets, which each pass --pg-config "$(PG_CONFIG)" to their tool. An extension binary built against one major version is not interchangeable with another, so your build machine's Postgres version is a decision, not a detail.
A bare cargo build covers pg_search and tokenizers, nothing else
The workspace has eight members and a deliberately short default set, and the manifest explains the choice:
members = [
  "benchmarks",
  "dst",
  "macros",
  "pg_search",
  "schemabot",
  "stressgres",
  "tests",
  "tokenizers",
]
# A bare `cargo build`/`check`/`clippy`/`test` at the root covers only the
# extension stack. Other members pull in dependencies the extension does not
# need (`benchmarks`, for example, builds the bundled DuckDB from C++ source).
# Build them with `-p <crate>` or `--workspace`.
default-members = ["pg_search", "tokenizers"]
Read that as a warning about what your local checks mean. A green cargo test at the root says nothing about benchmarks, dst, schemabot, stressgres or tests, because those crates are never compiled by the default invocation. The reason given is dependency weight, and the profile table backs it up: [profile.dev.package.libduckdb-sys] sets debug = false, with a comment explaining that DuckDB is a benchmark comparison engine rather than something being debugged, and that compiling its objects with -g costs gigabytes per target directory. The repository therefore ships its own comparison engine and charges build time for it, and anyone reproducing a benchmark number has to opt into that cost with -p or --workspace deliberately.
The DST profile exists so query generation does not distort the numbers
Several profile entries are shaped for measurement rather than for serving traffic. The workspace defines a release-with-debug profile that inherits release, turns debug on and disables debug assertions, described as an optimized build with debug symbols for profiling. A separate DST profile uses moderate optimization for a stated reason: so unoptimized ParadeDB execution does not dominate query generation time. It also retains DWARF, debug assertions and overflow checks for debugging. The shipping release profile is the conservative one: lto is set to thin rather than fat, with a comment about avoiding the memory usage of fat LTO without affecting benchmarks, opt-level is 3, codegen-units is 1, and panic is unwind, so a panic inside the extension unwinds rather than aborting. Two consequences for you. The numbers in the benchmarks crate describe a deliberately configured build, so quoting them without saying so is misleading. And panic = unwind in a component loaded inside a database process means error handling is up to the calling code, not to an abort.
Aggregates is the widest branch of the feature tree, with three separate reference pages
The shape of the feature list tells you where the design work is. Full-text search is expanded into BM25 scoring, Top K, highlighting, and tokenizers and token filters, each with its own reference page. Vector search, hybrid search and filtering are single entries with one page each. Aggregates is the only branch that carries three children of its own: columnar storage, bucket and metrics, and facets. JOINs has a page as well. The practical consequence is that search is the well trodden path, with scoring, ranking limits and presentation already documented as first class pieces, whereas aggregation is where you will be making choices across several separate mechanisms rather than following one documented default. Highlighting and Top K having their own pages also means the query result is meant to be presentation ready rather than a ranked id list you have to render yourself. When you scope a project, spend your reading time on the aggregates section, not on the scoring section.
Each ORM integration is its own repository, and Prisma is still listed as coming
The integration list points outward rather than inward. Drizzle, Django, SQLAlchemy, Rails and EF Core each live in a separate repository under the paradedb organisation, and the list closes with More coming (Prisma, and others). The AI agent side is separate again, with an Agent Skills repository, an MCP integration guide and a Cursor plugin published in that marketplace. Deployment is documented per provider too, with Railway, Render, Fly.io, Dokku and DigitalOcean each on its own page. The consequence is version independence: the extension and each adapter move on their own schedules, and this repository holds no compatibility matrix telling you which adapter release matches v0.26.0 of the extension. When pg_search changes an interface, the adapter repositories are where you find out whether your ORM call site has caught up, and if your ORM is Prisma today you are writing the queries yourself against the extension with no adapter to lean on. Budget for that before choosing the project.
Community is AGPL-3.0, and self-hosted Enterprise starts with an email to sales
There are two editions and the boundary is stated plainly rather than hidden. ParadeDB Community is licensed under the GNU Affero General Public License v3.0, which is also the license field in the workspace Cargo.toml. ParadeDB Enterprise is commercially licensed and included with ParadeDB Cloud, and the project routes self-hosted Enterprise through a contact sales address rather than a download. The same address is listed for enterprise support and commercial licensing. What this means during evaluation: nothing in this repository states which capabilities belong to Enterprise and which are community only, so any feature you read about in the documentation may sit on the commercial side of the line, and the licensing question has to be settled with the vendor before you commit to the self-hosted path. If your requirement is to run everything you use on infrastructure you control with no commercial relationship, treat the AGPL community tree as the only thing you can evaluate directly, and verify the feature you need is in it.
Two release candidates minutes apart sit beside the v0.26.0 tag
Version discipline is the quiet risk for anyone deploying this. The workspace version is 0.26.0 on edition 2024, and the release history is dense: v0.26.2 on 2026-10-16, v0.26.3 on 2026-10-22 and v0.26.4 on 2026-10-29, with the most recent push to the default branch on 2026-11-02. On a 0.x line a minor bump is allowed to carry interface level change, and the install script gives you no way to select a candidate or hold a version, so an unpinned curl line can move under you between two otherwise identical runs. Two habits follow. Pin the final tag in anything you deploy rather than tracking the branch, and read the changelog and the long-term roadmap as separate documents, since the project publishes both and they answer different questions: one says what just changed, the other says where the surface is heading. For contributors the process is documented in the tree, with RELEASE.md, a .changelog_headers.json and a CHANGELOG.md at the root.
Editorial conclusion
Try the curl install to see whether the query surface fits your application, then plan the real deployment deliberately: pin a final tag rather than the branch, budget for the aggregates reference pages, and confirm with the vendor which capabilities are community and which need a commercial licence before you self-host anything.
Frequently asked questions
Which is better, ParadeDB or Elasticsearch?
This repository makes no such comparison. What it states is the architectural difference: ParadeDB upgrades Postgres with a custom index for full-text and vector search, BM25 scoring, filters, facets, aggregations and joins, built as a Postgres extension so application data and search stay in one database with standard SQL and ACID transactions. Deployment paths listed are ParadeDB Cloud, self-hosted, and the PaaS providers Railway, Render, Fly.io, Dokku and DigitalOcean.
What is parade db?
A Postgres extension named pg_search that adds a custom index for fast full-text and vector search, with BM25 scoring, Top K, highlighting, tokenizers and token filters, hybrid search, filtering, aggregates including columnar storage, bucket and metrics, and facets, and joins. Local setup is a single curl script and the hosted option is ParadeDB Cloud.
Is ParadeDB open source?
The community edition is, under the GNU Affero General Public License v3.0, which is also the license declared in the workspace Cargo.toml. ParadeDB Enterprise is commercially licensed and included with ParadeDB Cloud, and self-hosting it means contacting sales.
What is the difference between paradedb and pgvector?
The repository publishes no comparison with pgvector. It names its own dependencies instead: pgrx bridges Postgres and Rust, Tantivy powers full-text and vector search, and Apache DataFusion handles OLAP processing, with upstream contributions where possible. Vector Search and Hybrid Search each have their own reference page.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paradedb-paradedb)Star history chart for your README
[](https://hysenlabs.com/projects/paradedb-paradedb)Was this useful?