pscale: five ways to install it, and a guide compiled into the binary
Project brief: The CLI for PlanetScale Database. PlanetScale CLI PlanetScale is more than a database and our CLI is more than a jumble of commands.
At a glance
- What is it?
- pscale is PlanetScale's command line client for branches and deploy requests, published as a Homebrew tap, deb and rpm packages, a scoop bucket, a raw binary, a third-party installer and a container image, with an interactive terminal UI and a non-interactive path for CI. Two details are worth more than the feature list: the API client is vendored rather than taken from the vendor's own SDK, and the agent guide ships inside the executable so it cannot drift from the version you are running.
- Who is it for?
- pscale fits you if you treat database changes as something that should go through review and a deploy request rather than as a console you paste into, because the branch and deploy-request vocabulary is the whole point of the tool and the non-interactive path with service tokens is what makes it usable in a pipeline.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
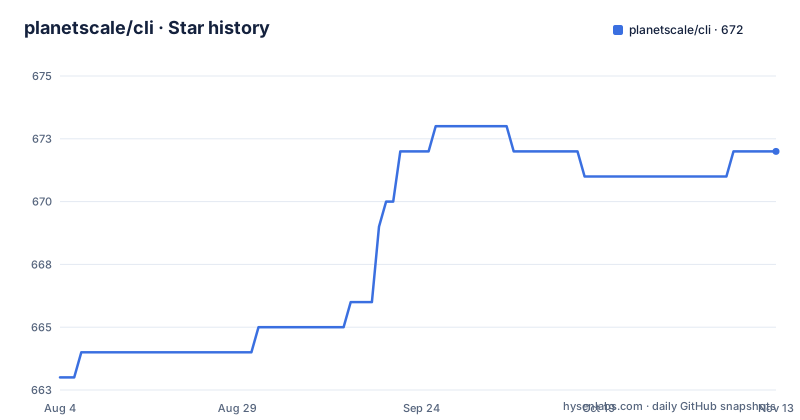
- planetscale/cli672 ★ · +9
| Repository | 2026-08-04 | 2026-11-13 |
|---|---|---|
| planetscale/cli | 663 | 672 |
9 Stars in the last 101 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Five install routes, and the example image tag is a long way behind
The installation section is longer than the feature documentation, which tells you something about where the effort goes.
brew install planetscale/tap/pscaleOn macOS there is a Homebrew tap, an upgrade command, and an optional MySQL client package that some commands need in the path. On Linux the answer is a deb or an rpm from the releases page, installed with the corresponding package tool, plus an Arch package in the user repository. On Windows there is a scoop bucket that you add before installing, and the install line pulls the database client in the same command. Two more routes sit underneath all of that: copy a pre-compiled binary anywhere yourself, or point a third-party installer at the repository URL, which handles macOS, Windows and Linux with one command and has its own upgrade verb. Container images are published as well, with a floating tag and a pinned tag. Two observations. The pinned example in the readme refers to a version in the sixties while the current releases are in the hundreds, so that example is stale by a wide margin and should not be copied as a template. And the shell alias the readme offers, which makes the word run the latest container image with your configuration directory mounted and your host user id, deliberately tracks the newest release. Convenience and reproducibility pull in opposite directions here, and the alias is on the convenience side.
The container carries a database client and an ssh client, not just the tool
The image is worth reading closely, because it is not a thin wrapper around one binary. It is built in one stage from a pinned Go toolchain with the C compiler disabled and symbol tables and file paths stripped, which is what produces a static executable that will run on any Linux distribution. The final stage is a plain Ubuntu image with exactly three packages installed: certificate authorities, a MySQL client, and an ssh client. Those three are the interesting part. The MySQL client is there because the readme says certain commands need a MySQL 8 client on the path, so the image satisfies a requirement that a naive packaging of this tool would miss. The ssh client is there for the connection-tunnel commands, which cannot work without it. And the image declares the database port as exposed, which matches the port mapping in the readme's alias: the container is expected to hold a live connection to the database the CLI opened a tunnel for. The readme also points at a third-party shell function for the cases the alias does not cover, specifically service tokens and telling apart commands that need a pseudo-terminal from ones that can run without one, which is the classic difficulty of running an interactive tool inside a container.
The API client was pulled in-house and the SDK dependency was dropped
One line in the development section is a bigger statement than it looks: the API client is vendored inside the repository, and the project no longer depends on the vendor's own Go client for it. There is a document to read before touching anything that talks to the API, which is the note you only find in a repository where someone has already broken something by skipping it. Taking ownership of the client has real benefits. It decouples the CLI's release cadence from the client's, it lets the CLI use API features the client has not exposed, and it means a breaking change in the client library cannot hold the tool back. The costs are equally real: someone maintains that code now, including its pagination, its error shapes and its authentication, and it will drift from the service unless someone is watching. For a tool whose entire job is calling one service's API, that trade is usually worth making, and the readme's instruction to read the document first is the discipline that keeps it from rotting. The client lives under the internal directory, which is Go's way of saying nothing outside this module should import it, so the boundary is enforced by the build rather than by convention.
Two database wire protocols, two Postgres drivers and a SQL parser
The dependency list is longer than a command line client usually needs, and reading it tells you what the tool actually does. There is a MySQL driver and a separate MySQL protocol stack, so it can speak to a database as well as to the API. There is a Postgres driver, a second and older Postgres driver sitting beside it, and two more database packages from the vendor's own organisation, which together cover the connection paths different commands need; having two Postgres drivers side by side is unusual and suggests one is there for a specific feature rather than as a default. Then there is a MySQL-compatible SQL parser, which is the dependency that explains the schema-oriented commands: parsing locally is what makes it possible to inspect or compare MySQL syntax without asking a server to parse it for you. Around that sit the tools a serious CLI accumulates: a keyring library so credentials go to the operating system credential store rather than a file, a configuration library that reads YAML and an XDG library that decides where that configuration lives, the usual command and flag libraries, an OAuth library and a browser launcher for the interactive login, a version library for comparing releases, a CSV writer and a table printer for the two output shapes, and a full terminal interface stack with prompts, a spinner and colour. This is a scriptable tool and an interactive tool in one binary, which is why the container section has to think about pseudo-terminals.
The agent guide is a Go source file inside the executable
There are two commands aimed at machines rather than people, and they are the newest thing in the tool. One prints a guide for AI agents and automation; the other emits that same guide as an installable skill file. Where the text lives is the interesting part: a Go source file at the top of the repository, which means the guide is compiled into the binary rather than fetched from a website. For a tool meant to be driven by an agent, that is the correct architecture. An agent that has to fetch documentation from a web page is reading a version of the documentation that may not match the binary it is holding, and a vendor's hosted documentation is a network dependency in the middle of an automated task. Compiling it in means the instructions and the tool cannot drift apart, and it means the guide works with no network at all. For the deeper material, the readme points somewhere else: a separate skills repository covering operational workflows such as inventory, safety review and schema recommendations. The split is sensible. The in-binary guide tells an agent how to use the tool correctly; the external skills tell it what to do with a database once it can drive the tool.
Two releases in one evening, and a linter installed from the tip
The release record shows three tags inside about two days, two of them on the same evening, at versions in the three hundreds. At that cadence the version number is a build identifier rather than a milestone, and there is no visible long-term-support branch, so pinning is entirely your problem. That matters most for the container alias, which tracks the newest tag by default. One build decision is worth flagging because it is unusual in the other direction.
lint:
	@go install honnef.co/go/tools/cmd/staticcheck@HEAD
	@staticcheck ./...
	@go vet ./...
The lint target installs its static analysis tool from the tip of that tool's repository on every run, rather than at a pinned version, and then runs it and the standard vet pass. The consequence is that your lint result depends on the day you run it: you always get current checks, and you can get a new failure with no change to this repository. For a project that tags releases automatically and ships a container, that is a deliberate trade and a slightly surprising one, and it is the kind of thing that surprises a fork trying to reproduce a green build. Two guards in the same file are more conventional and equally useful: the image build refuses to run unless the git tree is clean, and the publish step refuses unless the version matches a strict semantic-version pattern.
Version, commit and date are injected at link time
There is no version constant in the source.
ARG VERSION
ARG COMMIT
ARG DATE

RUN CGO_ENABLED=0 GOOS=linux GOARCH=amd64 go build -trimpath -ldflags="-s -w -X main.commit=$COMMIT -X main.version=$VERSION -X main.date=$DATE" github.com/planetscale/cli/cmd/pscale
The build file derives three values from git before anything is compiled: a short commit hash, a version taken from the most recent tag, and a UTC timestamp generated at build time. Those are passed into the container build as build arguments and end up as linker flags that write into three variables in the main package, alongside flags that strip the symbol table and file paths. The result is that the binary always knows what it is without anyone remembering to bump a number, and the same mechanism serves the release binaries and the published image. Two details in there are worth more than they appear. Disabling the C compiler is what makes the output static, which is the difference between one binary that runs everywhere and a build matrix per distribution. Stripping paths is why the released binary does not leak the build machine's directory layout. There is also a release target that builds a separate container from a second Dockerfile, with the release tool's version and the image-scanning tool's version pinned as variables, and runs it in a throwaway container. Pinning those two while leaving the linter unpinned is a telling inconsistency: the release path is reproducible and the lint path is not.
Credentials in the keyring, configuration in an XDG directory, and a browser login
Putting those three facts together explains the shape of the container setup. Credentials go into the operating system's credential store rather than a file, so on a laptop they are protected by the login keychain and nothing readable is left in your configuration directory. Configuration, by contrast, is plain YAML read through a library that knows where each platform wants it, which is the XDG library in the dependency list. That is exactly why the readme's alias sets the home directory to a temporary path inside the container and mounts your real configuration directory there.
mkdir -p $HOME/.config/planetscale
alias pscale="docker run -e HOME=/tmp -v $HOME/.config/planetscale:/tmp/.config/planetscale --user $(id -u):$(id -g) --rm -it -p 3306:3306/tcp planetscale/pscale:latest"
The container then looks in the same place the host does and finds the same files. The alias also passes your host user and group identifiers, so anything the tool writes is owned by you instead of by root. Login is browser-based, using an OAuth library and a browser launcher, which is fine interactively and useless in a pipeline. The automation path therefore uses a service token instead, and the GitHub Actions example shows the whole shape.
- name: Setup pscale
  uses: planetscale/setup-pscale-action@v1
- name: Use pscale
  env:
    PLANETSCALE_SERVICE_TOKEN_ID: ${{ secrets.PLANETSCALE_SERVICE_TOKEN_ID }}
    PLANETSCALE_SERVICE_TOKEN: ${{ secrets.PLANETSCALE_SERVICE_TOKEN }}
  run: |
    pscale deploy-request list my-db --org my-org
A third-party helper script exists for the container case, specifically because service tokens and pseudo-terminal handling do not compose well with the naive alias.
Editorial conclusion
pscale fits you if you treat database changes as something that should go through review and a deploy request rather than as a console you paste into, because the branch and deploy-request vocabulary is the whole point of the tool and the non-interactive path with service tokens is what makes it usable in a pipeline. Before you commit to it, decide how you will pin the version, since the release numbers move several times a week and the convenient shell alias runs the latest image by default, so a script that worked on Tuesday can behave differently on Friday without anything changing in your repository. Second, read what your credentials end up in: they go to the operating system keyring, which is right on a laptop and awkward in a container, which is why the CI path uses a service token from a secret store instead. Third, note that the tool ships its own copy of the API client and talks to databases over several drivers at once, so it is a bigger surface than the command list suggests, and the vendored client means API changes land in this repository rather than in a dependency bump.
Frequently asked questions
How do I install the pscale CLI?
Five documented routes: a Homebrew tap on macOS, deb or rpm packages on Linux with an Arch package as well, a scoop bucket on Windows, a pre-compiled binary you copy anywhere yourself, and a third-party installer that works on all three platforms. Container images are published too, with a floating tag and a pinned one.
Does pscale need a MySQL client installed?
For certain commands, yes. The readme says a MySQL 8 client has to be on your path, and it is why the scoop install line pulls a database client alongside the tool and why the published container image installs one as well.
How do I use pscale in a CI pipeline?
Install it with the project's setup action, then set the service token identifier and the service token as environment variables from your secret store and run commands non-interactively. A service-token aware helper shell function exists for running the container image, where the naive shell alias does not cover tokens or commands that need a pseudo-terminal.
What does the pscale agent-guide command do?
It prints a guide aimed at AI agents and automation, and a related flag writes the same guide out as an installable skill file. The text lives in a Go source file, so it is compiled into the binary and cannot drift from the version you are running.
Does the pscale CLI use the PlanetScale Go SDK?
No. The API client is vendored inside the repository under the internal directory and the readme states the project no longer depends on the vendor's Go client. It also asks you to read the API client document before changing anything that talks to the API.
How does pscale get its version number?
From git, at build time. The build derives a short commit hash, a version from the most recent tag and a UTC timestamp, then passes them as linker flags into three variables in the main program. The image build refuses to run on a dirty tree, and the publish step refuses a version that is not strict semantic versioning.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/planetscale-cli)Star history chart for your README
[](https://hysenlabs.com/projects/planetscale-cli)Was this useful?