Rocky ships three version trains, and the engine install comes from a release
A SQL transformation engine that type-checks your whole pipeline and catches breaking changes before they run, branches, replay, column-level lineage, compile-time contracts, per-model cost. Adapters: Databricks, Snowflake, BigQuery, DuckDB. Single static Rust binary. Apache 2.0.
At a glance
- What is it?
- Rocky is a static Rust binary that compiles SQL transformation models, checks types, references and contracts before anything runs, and targets Databricks, Snowflake, BigQuery, Trino and DuckDB. The interesting engineering is in what it refuses to promise: a clean compile reports the problems the available SQL, schemas and configuration make visible, and nothing more. The build is a monorepo with four subprojects in a fixed dependency order, and the extension ends in an Electron integration suite weighing about 344 MB.
- Who is it for?
- Rocky fits a data team on Databricks or Snowflake where a renamed column is discovered in production, and who want the check to run locally against a DuckDB playground before it reaches the warehouse.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
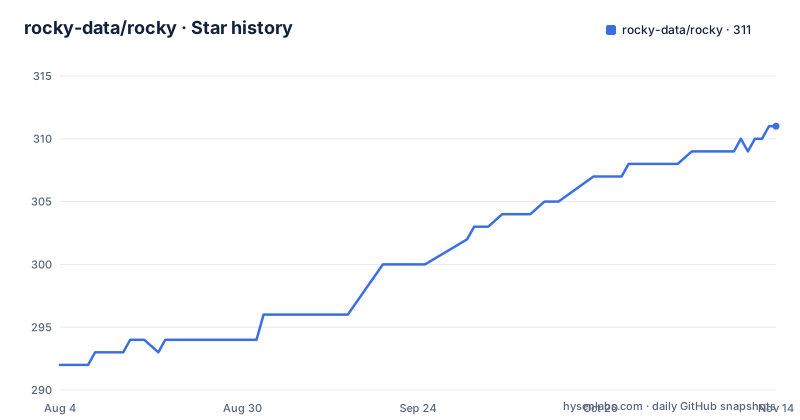
Star history
- rocky-data/rocky311 ★ · +19
| Repository | 2026-08-04 | 2026-11-14 |
|---|---|---|
| rocky-data/rocky | 292 | 311 |
19 Stars in the last 102 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three version trains released in the same minute
Look at the release tags rather than the headline feature list, because they tell you what Rocky actually is. The three most recent releases carry three different product prefixes and three unrelated version numbers: engine-v1.75.0, sdk-v0.16.0 and vscode-v1.42.0, all published on 2026-10-01 within about forty minutes of each other. That is not one product with one version; it is three trains moving independently, which means an engine at 1.75.0 can coexist with an SDK still at 0.16.0. The gap between 0.x and 1.x matters here, because the SDK is the piece a Python or Dagster user touches and it has not reached a stable declaration. The tree confirms the split: engine, sdk, integrations, editors and deploy are separate directories, and each has its own CI badge in the README for engine, sdk, dagster and vscode. Anyone pinning dependencies has to decide per train, not per project.
A clean compile does not prove the query will run
The README opens with an unusually firm limit on what the tool claims, and it is worth quoting rather than paraphrasing. Rocky compiles SQL models and reports supported static problems, and it does so when the available SQL, schemas and configuration make them visible. The next sentence is the one to hold on to: a clean compile does not prove every query will run in a warehouse or produce correct values. That qualifier is load-bearing, and the diagram beside it is drawn to match. Compile checks selected types, references and contracts, and the arrow back to your model files is labelled that an error makes this compile, which is the whole loop. In practice the check is therefore bounded by your inputs. A type change in a source column is caught when that schema is present. An unresolved reference is not caught unless source schemas are available or a runtime check covers it. Rocky is a static analyser with a runtime escape hatch, not an oracle.
plan and apply exist because run is one step too many for production
There are two execution paths and the README is explicit about which to use when. For production deploys you run rocky plan, which saves what will change, then rocky apply with the plan identifier, which runs it. For local work and automation, rocky run does it all in one step. That split is the difference between reviewing a change and discovering it. Getting started takes three commands and no credentials, because the playground runs on local DuckDB.
rocky playground my-first-project
cd my-first-project
rocky compile && rocky test && rocky run
Installation is a single script per platform, piped straight into a shell.
# macOS / Linux
curl -fsSL https://raw.githubusercontent.com/rocky-data/rocky/main/engine/install.sh | bash

# Windows (PowerShell)
irm https://raw.githubusercontent.com/rocky-data/rocky/main/engine/install.ps1 | iex
One caveat sits right next to those commands and is easy to skip: the installer downloads a published engine release, changes on main can arrive before the next release, and you are told to check rocky --version against the release notes when following examples. So the documented output can describe a build you do not have.
lineage-diff writes Markdown for a pull request comment
This is the feature that changes a review, so it is worth reading the actual output rather than the description. The command compares two versions of your project and lists the downstream tables and columns each change affects, writing Markdown that is ready to paste into a GitHub pull request comment.
$ rocky lineage-diff main

### Rocky Lineage Diff

**2 row(s) changed** (2 modified, 0 added, 0 removed, 0 unchanged)

stg_orders — modified (3 column changes)

| Column      | Change  | Downstream consumers      |
|-------------|---------|---------------------------|
| amount_usd  | added   | fct_revenue.total_revenue |
| amount      | removed | (removed; not traceable)  |
The summary line is the least interesting part. The right-hand column is the payload: renaming amount to amount_usd names the model and the column that reads it, before anyone merges. Note also the second row, where a removed column is marked not traceable. That is the honest failure mode of column-level lineage, and a tool that prints it instead of guessing is more useful than one that reports a confident downstream count it cannot support.
Contract failures carry numbers: E010, E011 and E013
Contracts are where the compile step stops being advisory. In the strict data contracts example, a known missing or dropped output column can refuse the affected model outright, and it does so with error codes E010, E011 and E013. A refused model is the intended behaviour, not a crash, and it is the mechanism that turns a schema change into a build failure. The adjacent examples show the same philosophy applied elsewhere. Schema drift recovery covers a source column changing type, where Rocky spots it and rebuilds safely. Incremental loads are opt-in per model through a strategy field set to incremental, after which Rocky reads only new rows. Data masking tags the personal columns and the check fails if one goes out unmasked. Cost attribution is the outlier: rocky cost derives an allocation only when a run records scanned bytes, and the README tells you to compare it with your own bill and notes that it needs credentials.
The editor checker is a language server, not a CI report
Most type errors in a SQL project surface hours later than they are created. Rocky moves that earlier by running the checker as a language server in VS Code, so type mismatches and broken references appear while you type rather than in a pipeline. Column types show on hover, and go-to-definition works across models, which matters when a model inherits columns from a staging layer several hops upstream. The Rocky Inspector panel sits alongside it and shows a model's columns with their origins, its lineage, its tests, available run metrics and classified columns; the sketch in the README shows order_id as a BIGINT from stg_orders.id and total_revenue as a DECIMAL from stg_orders.amount, with two passing tests and a cost line that reads as an allocation when data exists. That last phrasing is deliberate. The panel reports what the run recorded, not what the warehouse billed. The editor directory and the vscode CI badge confirm the extension ships as a first-class artefact rather than a sample.
The monorepo builds four subprojects in a fixed order
The justfile is short enough to read in full and it is the clearest statement of how this project is put together. Running just with no recipe lists the available ones, and the build recipe chains four subprojects in a specific order.
build: build-engine build-sdk build-dagster build-vscode

build-engine:
    cd engine && cargo build --release

build-sdk:
    cd sdk/python && uv build --wheel
The ordering is not arbitrary and the file says why in a comment: rocky-sdk is built before dagster-rocky, which depends on it. Four toolchains coexist in one repository, Rust for the engine, uv and pytest for the Python pieces, npm for the editor extension and a separate npm project for the browser UI that rocky serve --ui embeds. That last part is the subtle bit. A plain cargo build needs none of the UI, so the browser interface is opt-in at compile time through a feature flag, and the release shape is the SPA built first and then the binary with it embedded.
The Electron suite is 344 MB and does not run by default
One line of the justfile will tell you how the project balances coverage against iteration speed. The default VS Code test recipe runs the unit tests, and a comment directly above it explains the reason: the plain npm test entry runs the integration tests, which download a full Electron build under a .vscode-test directory, about 344 MB. The instruction is to use the vitest unit tests by default and reserve the electron suite for CI. That is a pragmatic choice and a revealing one, because it says the extension's real test surface is large enough to be inconvenient locally. The agent conformance evals follow the same pattern with a different dependency. They need a rocky build, an Anthropic API key and the claude and duckdb command-line tools, skip cleanly when those are absent, and are label-gated in CI, with a separate credential-free self test for the harness plumbing itself.
Editorial conclusion
Rocky fits a data team on Databricks or Snowflake where a renamed column is discovered in production, and who want the check to run locally against a DuckDB playground before it reaches the warehouse. It does not fit anyone treating a green compile as a correctness guarantee, since the project itself says a clean compile does not prove a query will run or return correct values, and it does not fit a team unwilling to maintain a Rust engine plus an SDK, a Dagster integration and a VS Code extension at three separate version numbers. Before you adopt it, run rocky --version against the release notes, because the installer pulls a published build while main moves faster, and read the lineage-diff output rather than the summary line, since the downstream consumer column is the part that matters.
Frequently asked questions
What does Rocky do to SQL models?
Rocky compiles SQL models and reports the static problems the available SQL, schemas and configuration make visible, covering types, references and contracts before anything executes. It states plainly that a clean compile does not prove every query will run in a warehouse or produce correct values.
How do I try Rocky without warehouse credentials?
Create a playground project, change into it, then compile, test and run. No credentials are needed because the playground runs on local DuckDB, and the install itself is a single curl script on macOS and Linux or an irm command in PowerShell on Windows.
What does rocky lineage-diff report?
It compares two versions of a project and lists the downstream tables and columns each change affects, writing Markdown ready to paste into a pull request comment. The output names the specific consuming column, for example fct_revenue.total_revenue, and marks removed columns as not traceable.
Does Rocky replace rocky run in production?
No. For production deploys the documented path is rocky plan, which saves what will change, then rocky apply with the plan identifier, which runs it. The single-step rocky run is for local work and automation.
Which warehouses does Rocky support?
It is built first for data engineers on Databricks, and also runs on Snowflake, BigQuery, Trino and DuckDB. The README states you keep your existing warehouse and your existing SQL.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rocky-data-rocky)Star history chart for your README
[](https://hysenlabs.com/projects/rocky-data-rocky)Was this useful?