Turso runs SQL as VDBE bytecode, which is how one Rust core hosts both SQLite and an experimental Postgres frontend
A SQL database in Rust: SQLite-compatible, now also speaking Postgres (experimental). The LLVM of databases.
At a glance
- What is it?
- Turso is an in-process SQL database written in Rust that compiles SQL into VDBE bytecode and executes the bytecode, so a single core can carry the SQLite dialect and, experimentally, a Postgres dialect and wire protocol. This looks at the binding set, the features carrying an experimental label, the compatibility boundaries, and where the engine will not do what a reader might assume.
- Who is it for?
- Turso suits teams that want an in-process SQL engine with real SQLite compatibility and that will keep Postgres, encryption at rest, full-text search, and multi-process coordination behind their own abstractions while those carry an experimental label. It does not suit a team needing approximate vector search today, or one treating the Postgres wire protocol as a finished migration target.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
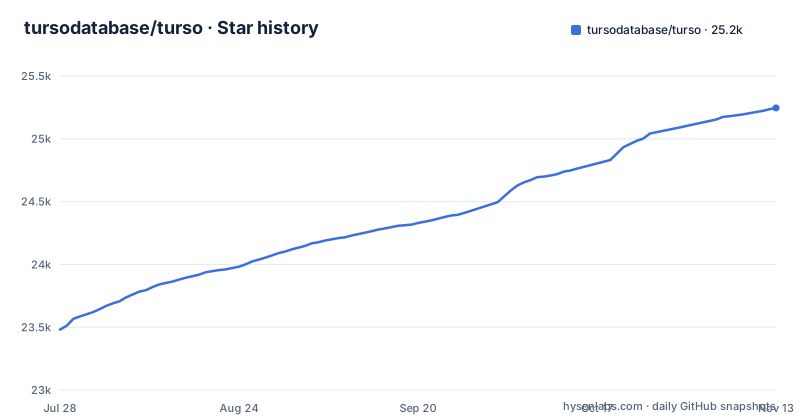
- tursodatabase/turso25,246 ★ · +1,765
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| tursodatabase/turso | 23.5k | 25.2k |
1,765 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
SQL compiles to VDBE bytecode, which is why one core can host two dialects
Turso's stated architecture is a virtual machine rather than a query planner. SQL is compiled into bytecode for the VDBE, the same execution target SQLite uses, and the engine then runs that bytecode. That single decision is what lets one core sit underneath more than one frontend. SQLite is the first and primary frontend that compiles onto it. Postgres is now a frontend of its own, with its own dialect and its own wire protocol, and the project lists that frontend as experimental. The stated goal is to be for databases what LLVM is to compilers: one modern and reliable core with many frontends compiled down onto it. The project's own measure of how general that core is, is that it is general enough to run Doom, in a separate turso-vdbe-doom-example repository. The versioning tells you how much weight to put on that framing. The recent tags are v0.9.0-pre.2 dated 2026-10-28, v0.9.0-pre.1 dated 2026-10-15, and v0.8.3 dated 2026-10-12, so the project sits pre-1.0 while shipping quickly. For an adopter the practical payoff is narrower than the LLVM framing suggests: you are not choosing a frontend at the SQL level, because the SQLite path is the primary one and the Postgres path keeps its own compatibility file.
Postgres compatibility is experimental and tracked in a file apart from COMPAT.md
Compatibility is split across two documents, and the split is the thing to notice. SQLite compatibility covers the SQL dialect, the file formats, and the C API, with the project stating that it tracks SQLite version 3.50.4 and that COMPAT.md holds the details. Postgres compatibility covers the SQL dialect and the wire protocol, and its detail lives in a separate reference at postgres/COMPAT.md. The feature list then places Postgres compatibility alongside encryption at rest, incremental computation, full-text search, and multi-process WAL coordination in a block labelled experimental. Five headline capabilities sit outside the stable list, which is a materially different posture from the SQLite path. What that means for a reader is that a Postgres wire protocol you can connect to is not the same as a Postgres replacement you can migrate onto. Dialect differences are collected in a file the README links rather than summarized anywhere prominent, so nothing in the front page tells you which statements diverge. Check postgres/COMPAT.md against the specific statements, types, and functions your application actually issues before pointing anything at it, and keep treating the SQLite path as the only one you can assume behaves as documented.
Exact vector search is listed as a feature, approximate vector indexing is only on the roadmap
The vector entry in the feature list is worded narrowly on purpose: vector support including exact search and vector manipulation. A separate roadmap section lists vector indexing for fast approximate vector search, similar to libSQL vector search. Those are two different operations with two very different costs. Exact search compares a query vector against stored vectors one at a time. Approximate search first uses an index structure to narrow the candidate set. Turso ships the first and, by its own roadmap, has not shipped the second. The consequence lands hardest on the workloads that made vectors interesting in the first place. If you are holding embeddings for documents, messages, or products at a volume where linear comparison becomes the bottleneck, nothing in the current engine rescues you, because the structure that would make the volume tolerable is the piece still to be built. Exact search remains perfectly reasonable for small collections, small test corpora, and for checking correctness against an approximate result once one exists. Capacity plan around a linear scan now, and treat any approximate-search performance number you encounter as describing something the roadmap has not yet delivered.
Encryption at rest and full-text search carry the experimental label as well
Encryption at rest, for protecting data locally, sits in the experimental block rather than the stable feature list. So does full-text search, which is powered by the tantivy library, and incremental computation using DBSP for incremental view maintenance and query subscriptions. Read that placement as a statement about support expectations: these three are documented and reachable, but the project is not claiming the same stability for them as for SQLite dialect and file-format compatibility. For encryption at rest the consequence is shaped by compliance. If a requirement says data must be encrypted where it is stored, an experimental flag is not something to sign off on without understanding what keys the implementation expects and where they live. For full-text search, the consequence is that an application depending on it inherits a tantivy-backed surface the project reserves the right to change. Neither of these is a reason to avoid Turso. Both are reasons to put the feature behind an interface you own instead of calling it directly from product code, so that the day the label changes you are changing one adapter rather than every call site.
Cross-process access needs the .tshm sidecar, so a bare file path is not the whole story
Running inside your own process is the design centre, and the CLI makes that visible. Launching the interactive shell with tursodb prints that it is connected to a transient in-memory database and instructs you to use .open FILENAME to reopen on a persistent one. Reaching across process boundaries is the part still marked experimental. The feature is multi-process WAL coordination via the .tshm sidecar, described as serving cross-process WAL readers and writers. The consequence is that several processes touching one database file is a configuration problem before it is a concurrency problem. Coordination depends on a sidecar file existing alongside the database, so a deployment where each process simply opens the same path on a separate host, or on a filesystem that will not carry the sidecar alongside it, does not receive the stated guarantee. Write throughput past a single writer is the other edge. BEGIN CONCURRENT is the documented path to improving write throughput through multi-version concurrency control, so a write-heavy workload deserves to be measured with that statement genuinely in use rather than assumed to benefit from it. The .tshm coordination is on the experimental list, so measurements that rely on it are of an experimental configuration.
Six bindings, six install lines, and no shared API surface between them
Every language gets its own package name and its own API shape, so moving code between them is not mechanical work. Rust is installed with cargo add turso and exposes an async builder over a local file plus a query call. JavaScript installs @tursodatabase/database from npm, and the same package reaches browsers through WebAssembly. Python installs pyturso through uv and exposes connect, cursor, and execute. Go fetches turso.tech/database/tursogo and registers itself with database/sql under the driver name turso. .NET ships Turso.Data.Sqlite.Provider on NuGet and exposes a TursoConnection whose data source string looks like an ordinary SQLite connection string.
let db = Builder::new_local("sqlite.db").build().await?;
let conn = db.connect()?;

let res = conn.query("SELECT * FROM users", ()).await?;import turso
con = turso.connect("sqlite.db")
cur = con.cursor()
res = cur.execute("SELECT * FROM users")
print(res.fetchone())What this arrangement costs a reader is rewrite cost. A data access layer built against one binding's async model, its transaction calls, and its error types will not survive the trip to another binding without being rewritten rather than adjusted. Pick the binding your host language forces on you, then keep your SQL and query shapes portable underneath it so that the database choice stays reversible later.
Source builds want Rust 1.73.0 and TCL 8.6, and the test target fans out into four suites
Building from source is a first-class path rather than a fallback. The CLI installer is one shell pipeline that fetches the release installer script and pipes it into sh, and the shell it installs is invoked as tursodb. Developers can skip the installer completely with cargo run in the repository root, or use the two-step Docker route.
curl --proto '=https' --tlsv1.2 -LsSf \
https://github.com/tursodatabase/turso/releases/latest/download/turso_cli-installer.sh | shmake docker-cli-build && \
make docker-cli-runThe declared floors are specific enough to plan around. The Makefile sets a minimum Rust version of 1.73.0 and runs rustup update stable for you when rustup is present, or prints a message and exits 1 when it is not. A separate check requires TCL 8.6 or newer, and the compatibility tests run against an executable named scripts/limbo-sqlite3. The Python packaging metadata requires Python 3.13 or newer and still carries the project name limbo at version 0.1.0. The test target fans out into test-without-sqltest, test-sqltest, test-sqltest-js, and test-sqltest-cli, and the workspace lists dedicated crates for differential oracles, fuzzers, a simulator, stress testing, and per-area perf harnesses. Contributors should expect those two legacy names to keep surfacing in issues and patches.
The engine pins itself to SQLite 3.50.4, so newer SQLite features arrive on the project's schedule
Compatibility here is a stated target rather than an open-ended promise of parity with whatever SQLite shipped most recently. The feature list says the project tracks SQLite version 3.50.4 for SQL dialect, file formats, and the C API, with COMPAT.md holding the detail. A pinned target is the genuinely useful part, because it tells you which behaviours you can reason about and which ones you must check. It also draws a line in the other direction: anything introduced in SQLite after 3.50.4 is not something a reader can assume, and every binding that wraps the dialect, the file formats, or the C API inherits whatever sits behind that boundary. The claim itself is also narrower than drop-in replacement. Three surfaces are named as compatible, and staying inside those three is what keeps a database file portable between Turso and stock SQLite tooling. Move a file across that line and you are relying on behaviour the project has not claimed. The repository does ship perf crates for throughput, latency, full-text search, join benchmarks, encryption, memory, and query batches, alongside a PERF.md, which is where a reader who cares about the comparison should start measuring rather than reading.
Editorial conclusion
Turso suits teams that want an in-process SQL engine with real SQLite compatibility and that will keep Postgres, encryption at rest, full-text search, and multi-process coordination behind their own abstractions while those carry an experimental label. It does not suit a team needing approximate vector search today, or one treating the Postgres wire protocol as a finished migration target. Before adopting, read COMPAT.md for the SQLite boundary and postgres/COMPAT.md for the dialect gaps, and confirm your Rust, Python, and TCL versions clear the documented floors.
Frequently asked questions
What is Turso used for?
It is an in-process SQL database written in Rust that runs SQL as bytecode on the VDBE, is compatible with SQLite for dialect, file formats, and the C API, and now ships a Postgres frontend alongside bindings for Go, JavaScript, Java, .NET, Python, Rust, and WebAssembly.
Is Turso free to use?
The repository is published under the MIT license, and the source, the release installer, and each language package are available from it.
is turso faster than sqlite
The README's feature list makes no speed claim against SQLite. The repository ships perf crates for throughput, latency, joins, memory, and query batches plus a PERF.md, so measure it on your own data instead of trusting a headline.
how to install turso cli on windows
Windows is one of the listed platforms, and the documented install runs a release installer script from the releases page piped into sh. The README gives no separate native Windows installer command.
what is turso db
It is the same in-process Rust SQL database. The CLI is invoked as tursodb and opens on a transient in-memory database unless you use .open FILENAME, and the engine tracks SQLite version 3.50.4.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tursodatabase-turso)Star history chart for your README
[](https://hysenlabs.com/projects/tursodatabase-turso)Was this useful?