YDB: a distributed SQL database where storage and compute scale apart
YDB is an open source Distributed SQL Database that combines high availability and scalability with strong consistency and ACID transactions.
At a glance
- What is it?
- YDB is an open source distributed SQL database written in C++, and the architecture decisions worth knowing are structural: disaggregated storage and compute layers, a cluster that keeps serving reads and writes through the loss of an entire availability zone, and two compatibility modes, PostgreSQL for tables and Kafka for topics, wrapped around its own YQL dialect.
- Who is it for?
- Adopt YDB if you are building an OLTP-like web service that has to grow across machines and survive a datacenter loss, and you want a SQL dialect rather than an API to learn. Do not adopt it for a single machine that needs a relational database, because production and preproduction workloads need a full multi-node cluster deployed with Ansible or Kubernetes.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
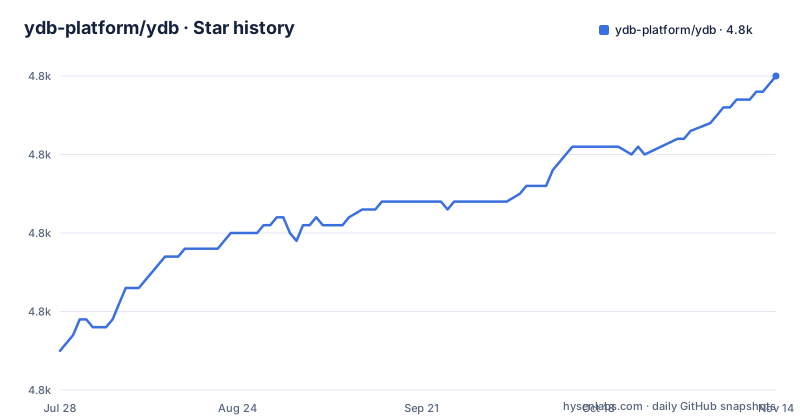
- ydb-platform/ydb4,790 ★ · +35
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| ydb-platform/ydb | 4.8k | 4.8k |
35 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
YQL sits between a PostgreSQL mode and a Kafka mode
Three interfaces meet in one database. The native dialect is YQL, described as rich for both data manipulation and schema definition. On top of it sit two compatibility modes: a PostgreSQL-compatible mode for table operations and a Kafka-compatible mode for topics. That pair is the practical decision a team makes on day one. If your application already speaks the PostgreSQL wire protocol, you connect through that mode and write against tables; if your data flows through a topic consumer, the Kafka mode covers it.
Three availability zones, and a zone can disappear completely
The fault tolerance claim is specific rather than general. YDB can be deployed in three availability zones, which the documentation describes as datacenters, and a cluster remains available for both reads and writes during a complete outage of a single zone. Reads and writes is the part that matters: plenty of systems keep serving reads from replicas and lose write capacity in the same event. The README separately lists independent horizontal scalability of storage and compute layers and automatic disaster recovery with minimum latency disruptions for applications. After an unpredictable disk, node, rack or datacenter failure, the cluster stays available and restores the required data redundancy itself, which is why the fault list ranges from a single disk up to a whole building.
Ten thousand nodes is a statement about the largest installs
The README quotes current production installations with over 10000 nodes, petabytes of data, and millions of distributed transactions per second. Read that as a description of the top of the range rather than a sizing target, because the same document describes the smallest thing you can run. The Quick Start guide yields a single-node cluster, and it is described as suitable for functional testing, application development and similar tasks. Fault tolerance testing, performance benchmarks and production or preproduction workloads are explicitly the cases that need a full multi-node cluster. So the same database runs as a single-node cluster and as a zone-spanning installation, and the gap between those two is deployment work rather than a different product. The project also states why it exists in those terms: it was designed from scratch for the growing demand for scalable interactive web services, where scalability, strict consistency and effective cross-row transactions were required for an OLTP-like workload, and it was built by people with database and distributed systems backgrounds who had developed a NoSQL database and a MapReduce system for one of the largest search engines in the world.
Multitenant and serverless share resources in opposite directions
Two sharing models are documented and they are not the same idea. In the multitenant model a user runs a YDB cluster and creates several databases that share one pool of storage while having different compute nodes. Storage is shared, compute is separated, which is the shape you want when tenants have very different data volumes but similar load. In the serverless model a user runs several serverless databases that share one pool of compute resources. Compute is shared so it can be utilized effectively. Both exist because the storage and compute layers were built to be separable in the first place, and the practical consequence is that a workload which is quiet on storage and heavy on compute behaves very differently in the two. Persistent queues are the third shape the data can take, and they exist for moving data around rather than for querying it.
Ubuntu on x86 for production, Mac and Windows for development
The platform section is short and worth reading twice. The minimal system requirement is x86 64-bit with at least 8 GB of RAM. In most production environments YDB runs on 64-bit x86 machines under Ubuntu Linux. For development purposes it is regularly tested that YDB can be compiled and run under the latest versions of MacOS and Microsoft Windows. That is a narrower promise than it first appears: the platform you develop on is not the platform the README describes as typical for production, and a distributed database that depends on specific hardware and kernel behaviour is exactly the kind of program where that gap shows up first. There is no ARM statement here, which also means an ARM host is outside what the documentation currently claims. The minimum of 8 GB of RAM is stated against x86 64-bit rather than against a node role.
Deployment follows the workload: Ansible, Kubernetes, or manual
Three deployment paths are named, and the choice tracks what you are testing. Ansible is for bare metal or virtual machines, Kubernetes is for containers, and manual deployment is listed as a third option. The Quick Start guide is the entry point for experimenting and gives you a single-node cluster. Anything beyond that, meaning testing fault tolerance, running benchmarks, or carrying production and preproduction workloads, needs the full multi-node cluster deployed through one of the two automation paths. Regions and availability zones have their own documentation section, which is where the placement of those three zones is decided before the first node exists. Practically, the deployment method is a decision you make during design, not after the application is written.
Building from source means Ya Make, and ydbd is the server
The source build has its own documentation, `BUILD.md`, covering the two binaries you care about: `ydbd`, the server, and `ydb`, the client. The build system is Ya Make, documented separately, and it is checked into the tree as `ya`, `ya.bat` and `ya.conf` rather than being something you install separately. The repository layout reflects its history and its scale: `ydb/` and `yql/` are the engine and the language, `library/`, `tools/` and `util/` hold shared code, `vendor/` and `.arcadia.root` are also at the root, and `build/`, `contrib/`, `devtools/` and `certs/` are the supporting directories a project of this size accumulates. Around them sit the governance files, `AUTHORS`, `CONTRIBUTING.md`, `CODE_OF_CONDUCT.md`, `SECURITY.md`, `ROADMAP.md`, plus agent instruction files in `AGENTS.md`, `CLAUDE.md` and `.agents/`. Releases use four-part version numbers: 26.1.1.22, then 26.2.1.14, then 26.3.1.16, with the last recorded push on 2026-11-01. License is Apache-2.0.
Editorial conclusion
Adopt YDB if you are building an OLTP-like web service that has to grow across machines and survive a datacenter loss, and you want a SQL dialect rather than an API to learn. Do not adopt it for a single machine that needs a relational database, because production and preproduction workloads need a full multi-node cluster deployed with Ansible or Kubernetes. Verify first which client you will use, since the PostgreSQL-compatible mode covers table operations and the Kafka-compatible mode covers topics, and confirm your hardware against the minimum of x86 64-bit with 8 GB of RAM before planning an Ansible or Kubernetes rollout.
Frequently asked questions
What is YDB?
An open source distributed SQL database written in C++, combining high availability and scalability with strict consistency and ACID transactions. It offers row-oriented and column-oriented tables for transactional and analytical workloads, persistent queues as topics, and its own SQL dialect called YQL.
How do I try YDB?
The Quick Start guide yields a single-node cluster suitable for functional testing and application development. Testing fault tolerance, running performance benchmarks or carrying production workloads needs a full multi-node cluster, deployed with Ansible on bare metal or virtual machines, or with Kubernetes for containers.
Which platforms does YDB run on?
In most production environments YDB runs on 64-bit x86 machines under Ubuntu Linux, and the minimal system requirement is x86 64-bit with at least 8 GB of RAM. Compiling and running under the latest MacOS and Microsoft Windows is regularly tested for development purposes.
Does YDB speak the PostgreSQL and Kafka protocols?
It has a PostgreSQL-compatible mode for table operations and a Kafka-compatible mode for topics, alongside its own YQL dialect.
How do I build YDB from source?
BUILD.md in the repository covers building the server binary ydbd and the client ydb, and the Ya Make build system is documented separately. The build tool is checked into the tree as ya, ya.bat and ya.conf, so no separate install step is described.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ydb-platform-ydb)Star history chart for your README
[](https://hysenlabs.com/projects/ydb-platform-ydb)Was this useful?