PeerDB: every warehouse, queue and storage destination except ClickHouse is deprecated
Fast, Simple and a cost effective tool to replicate data from Postgres to Data Warehouses, Queues and Storage
At a glance
- What is it?
- PeerDB is a Postgres-first ETL and change data capture tool that streams into warehouses, queues and object storage, and its own README now deprecates most of those destinations in favour of ClickHouse. What is left actively maintained is a short list, and the file is careful about the difference between deprecated and removed.
- Who is it for?
- Choose PeerDB if Postgres is your system of record and you want change data capture with a Postgres-compatible SQL interface rather than another integration framework, because the log based path is the one the project still maintains and the SQL front end lets your existing tooling drive it.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
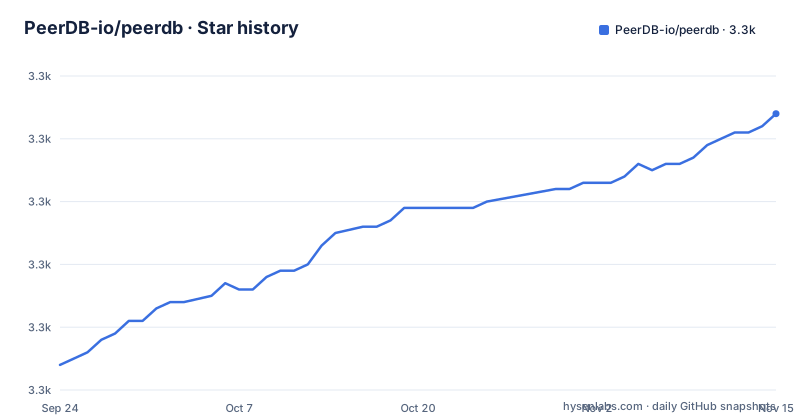
Star history
- PeerDB-io/peerdb3,324 ★ · +40
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| PeerDB-io/peerdb | 3.3k | 3.3k |
40 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The destination list has collapsed to ClickHouse, Postgres and ClickHouse Cloud
The tool was built to stream Postgres into data warehouses, queues and storage engines, and that sentence is now a historical description. A deprecation notice at the top of the file names the destination connectors that are deprecated and no longer actively maintained: Snowflake, BigQuery, ElasticSearch, Kafka including its Confluent and Redpanda variants, Azure Event Hubs, Google Pub/Sub and S3.
What remains actively maintained is a list of three paths: Postgres to ClickHouse, Postgres to ClickHouse Cloud, and Postgres to Postgres. Two details keep that from being a simple amputation. The notice applies to the destination role only, so BigQuery remains a supported source even though its destination connector is deprecated. And the deprecated connectors remain fully functional in the current release and in all prior ones, with no code currently being removed.
For planning purposes the file points at a connector status matrix and at a migration guide for deprecated connectors, whose stated subject is how to pin to a release or fork the relevant code. Pinning and forking are the two options on offer, which is an honest admission that the migration path is yours to carry.
Two of the three mirror types are deprecated while CDC is recommended
The same treatment applies one level down, to the way data is read out of Postgres. Three streaming modes exist: log based change data capture, cursor based replication by timestamp or by integer, and XMIN based replication. The notice says CDC is the recommended and actively maintained mirror type, and that Query Replication, which is QRep, and XMIN are deprecated and no longer actively maintained.
The wording again distinguishes dormant from deleted. Both stay functional, and no code is currently being removed, so an existing pipeline on QRep keeps running today. What you lose is new work on those paths and any fix that would have arrived.
That leaves one supported way to read the change stream, and it is the one with real constraints. Logical replication is what CDC is built on, so it depends on the source database's replication slot and on how Postgres is configured, which is why the file lists tuning Postgres configs and parallel reading of the slot among its optimizations rather than presenting CDC as a self-contained engine.
Files are staged in MinIO, so a ClickHouse outside Docker needs a route back in
Loads are not streamed straight into the destination. PeerDB stages Postgres data in MinIO inside the Docker stack and loads from there, which creates a network dependency that only bites in one common topology: a ClickHouse database running outside Docker, on virtual machines or on ClickHouse Cloud.
The failure is a hostname that does not resolve. The fix is a setting, and the file shows its shape:
AWS_ENDPOINT_URL_S3: http://172.31.26.57:9001 # Change this to IP/host which is accessible by both PeerDB and ClickHouseTwo conditions are attached to that value. It must be reachable from PeerDB and from ClickHouse, which is why an IP is suggested rather than a container name, and on AWS, GCP or Azure the security group has to allow inbound access to MinIO as well. The compose file's own default points the endpoint at `host.docker.internal:9001`, which works only while both sides can reach the host.
So the staging layer is not an implementation detail you can ignore. On a shared network it becomes a listening service with a bucket name and credentials attached.
The quickstart's last command stops in the middle of a hostname
The getting started block clones the repository and offers two routes. One starts a container stack:
git clone [email protected]:PeerDB-io/peerdb.git
cd peerdb
bash ./run-peerdb.sh
The other builds images locally and needs the buf compiler for protobuf generation in addition to docker and docker-compose, running `generate-protos.sh` before `dev-peerdb.sh`. The container route is described as bringing up Postgres as the catalog, Temporal, the PeerDB server, the flow API with workers, and the UI.
The block then tells you to connect with psql version 14.0 or newer, and the command itself stops partway through:
`psql "port=9900 host=localh`
The port is there and the hostname is not, so the copy-paste line cannot be used as printed. It is a small blemish on the one section most people will run first, and worth knowing before you assume you mistyped something.
For reference, the compose file publishes the catalog on a different port, 9901 mapped to 5432, so the catalog and the SQL interface are not the same endpoint.
The compose file ships MinIO and catalog passwords in plain text
The quickstart stack is a local developer stack, and its credentials are written into the compose file where anyone can read them. MinIO appears four times in one anchor block, and all four values are the same string:
x-minio-config: &minio-config
  PEERDB_CLICKHOUSE_AWS_CREDENTIALS_AWS_ACCESS_KEY_ID: _peerdb_minioadmin
  MINIO_ROOT_USER: _peerdb_minioadmin
  PEERDB_CLICKHOUSE_AWS_CREDENTIALS_AWS_SECRET_ACCESS_KEY: _peerdb_minioadmin
  MINIO_ROOT_PASSWORD: _peerdb_minioadmin
The catalog is no better, with user, password and database all set to postgres, and its service pins a Postgres 18 Alpine image by digest, restarts unless stopped, initialises with a C.UTF-8 locale, and maps 9901 to 5432. Containers get `host.docker.internal` mapped to the host gateway through an extra_hosts entry.
None of that is a secret being leaked, because the stack is meant for a laptop. It matters because the same compose file is the obvious starting point for a shared or demo environment, and combined with the MinIO endpoint instruction above, the default configuration has an object store with known credentials and an endpoint that other machines are told to reach. Change both before that stack is visible to anyone.
The test environment file is a map of everything the connectors are run against
The `.env.example` file at the root is the most informative document in the repository for judging coverage, because it enumerates the systems the test suite talks to. There are two Postgres instances on separate ports, both with the default postgres credentials. MySQL appears twice, once in a GTID configuration and once in a position-based one, alongside MariaDB on version 11. There is a CockroachDB instance, a MongoDB instance with an admin account and a separate application user, and ClickHouse on HTTP and native ports with a second instance on a third pair of ports.
Then the security tests. A ClickHouse port for a native protocol over TLS test exists alongside, with client certificates using cert-manager naming and a path that the comment insists is relative to the connector directory rather than to the repository root, which is the kind of detail that only matters after a test fails. Postgres mutual TLS is configured with paths under volumes/pg-tls, and there is a regeneration script under volumes/ch-tls.
The same file carries the AWS variables passed through to workers, with empty defaults and a note that Google Cloud Storage users should set the access key pair to the HMAC keys for the bucket.
ClickHouse now ships this connector natively, and the README links to it
The most awkward line in the file is the announcement that PeerDB is available natively in ClickHouse Cloud as generally available, linking to the ClickPipes Postgres CDC connector. The maintained destination list and that announcement say the same thing from two directions: the Postgres to ClickHouse path is the one being invested in, and the vendor has a customer who now offers it themselves.
For a reader choosing tooling that is not useful, but for a reader choosing support it matters. The upstream integration in ClickHouse Cloud has its own release cadence and its own documentation, and it is the path with a first-party owner behind it.
The performance figures in the same section are claims rather than measurements you can check here. The file says PeerDB is 10x faster than existing tools, that syncing hundreds of gigabytes drops from days to minutes through parallel initial loads that still preserve consistency, and that change data capture holds freshness to a few tens of seconds at throughputs above ten thousand transactions per second. Those are the numbers to test against your own table sizes before believing them.
The SQL interface is what makes it Postgres-shaped rather than another connector list
The argument for the design is that ETL should run in the environment you already have. Instead of a separate job definition language, PeerDB accepts Postgres-compatible SQL, so the same tooling you use for the database drives the pipeline.
The file names the pieces: client tools such as pgAdmin and psql for running commands, BI tools such as Grafana and Tableau for watching syncs and transforms visually, database migration and versioning tools such as Flyway for managing the ETL itself, and any language or scheduler such as Airflow for development. That list is the differentiator in a market where the stated complaint is that other tools optimise for a wide range of connectors instead of Postgres.
Reliability claims sit alongside it: state management, automatic retries, idempotency and consistency handling, with a linked write-up about using Temporal to scale data synchronisation, plus configurable batching and parallelism to avoid out of memory failures. Temporal is also visible in the local stack as a service the flow workers connect to, so it is part of the architecture rather than only an essay topic.
Editorial conclusion
Choose PeerDB if Postgres is your system of record and you want change data capture with a Postgres-compatible SQL interface rather than another integration framework, because the log based path is the one the project still maintains and the SQL front end lets your existing tooling drive it. Then read the deprecation notices before you design anything, because the destination list you have probably read about, Snowflake, BigQuery, Kafka, S3, Pub/Sub, Event Hubs and ElasticSearch, is now maintenance-only, and two of the three mirror types are as well. If your target is ClickHouse, you are on the supported path and can also skip the tool entirely by using the Postgres CDC connector that ClickHouse Cloud now offers natively. If your target is anything else, pin to a release or plan on maintaining a fork, and check what MinIO exposure that topology requires before you put it on a shared network.
Frequently asked questions
Which PeerDB destinations are still actively maintained?
Postgres to ClickHouse, Postgres to ClickHouse Cloud, and Postgres to Postgres. The Snowflake, BigQuery, ElasticSearch, Kafka, Azure Event Hubs, Google Pub/Sub and S3 destination connectors are deprecated and no longer actively maintained, though they remain fully functional.
Is peerdb open source
The repository is licensed under AGPL-3.0, with the LICENSE file at the root of the project.
clickpipes vs peerdb
The README announces that PeerDB is available natively in ClickHouse Cloud as generally available, linking to the ClickPipes Postgres CDC connector. So the maintained Postgres to ClickHouse path now also exists as a first-party ClickHouse feature.
Which PeerDB mirror types are deprecated?
Query Replication, or QRep, and XMIN based replication are deprecated and no longer actively maintained, while log based change data capture is the recommended type. Both deprecated types remain fully functional and no code is currently being removed.
What does the PeerDB quickstart stack include?
Postgres as the catalog, Temporal, the PeerDB server, the PeerDB flow API with workers, and the PeerDB UI, started with run-peerdb.sh. Local development instead builds images locally and needs the buf compiler for protobuf generation.
What is a peerdb alternative?
This repository names no competing tool. Its own guidance for the deprecated paths is to pin to a release or fork the relevant code, and its migration guide for deprecated connectors is the document that covers moving off them.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/peerdb-io-peerdb)Star history chart for your README
[](https://hysenlabs.com/projects/peerdb-io-peerdb)Was this useful?