picollm, an inference engine that runs locally and phones home to start
On-device LLM Inference Powered by X-Bit Quantization
At a glance
- What is it?
- picoLLM is Picovoice's cross-platform inference SDK for compressed open-weight models, shipping bindings for seven platforms and its own quantization scheme. What is worth reading carefully is the tension at the centre: inference is described as running entirely on your machine, while the AccessKey still has to be validated against Picovoice's licence servers over the internet.
- Who is it for?
- picoLLM makes sense when the model has to run on a Raspberry Pi, in a mobile app, or in a browser tab, which are the cases its own videos pick. It is less obviously right when you already have a server with a GPU.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
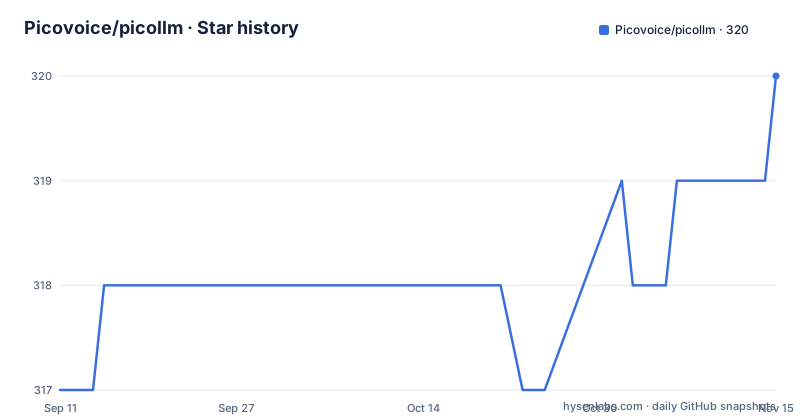
- Picovoice/picollm320 ★ · +3
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Picovoice/picollm | 317 | 320 |
3 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Runs 100% locally and still needs the internet to start
Three statements about offline behaviour sit in one repository, and they are not quite the same claim.
The feature list says private, with LLM inference running 100% locally. The cross-browser video entry is labelled a live demo that works offline. And the AccessKey section says you would need internet connectivity to validate your AccessKey with Picovoice license servers, even though the LLM inference is running 100% offline.
So the boundary is drawn at process startup rather than at the data path. No prompt, no completion, and no weight ever leaves the machine. A licence check does, once per validation, and the key is described as something you must keep secret.
The distinction matters for two very different deployments. For a Raspberry Pi or a phone that goes offline periodically, a validation call that fails closed means the engine will not run at all on a plane or behind a firewall, however private the data path is. For a browser demo advertised as working offline, the claim can only hold if a previously validated key is cached.
The README does not say which of those two behaviours you get, and that is the first thing to check with the vendor.
Models arrive from a console as files, not from a registry
The engine does not fetch weights. You download a model file and pass its path.
Every demo takes the same three arguments, and the Python one is the shortest statement of the whole interface:
pip3 install picollmdemopicollm_demo_completion --access_key ${ACCESS_KEY} --model_path ${MODEL_PATH} --prompt ${PROMPT}The model path points at a file obtained from the Picovoice Console, and the list of available models is described as being on that console. So the supported set is curated by the vendor rather than discovered from Hugging Face, and each model is a local artifact you supply.
That has a clear upside. Quantization is the part Picovoice built, and pairing it with a specific prepared weight file is how you get the accuracy numbers they publish rather than an approximation of them. It also means the runtime has no network dependency once started, which is what makes the browser and Pi cases work.
The cost is a hard boundary on model choice. Anything not on that list is not supported, and there is no documented path for supplying your own weights.
Free for open-weight models is bounded by account limits
The pricing claim is one line, and the AccessKey section is where the terms live.
The feature list says free for open-weight models. The AccessKey section adds that the key verifies your usage is within the limits of your account, that you can see limits and real-time usage on your Console profile, and that to continue after your trial or to adjust your limits you need to reach the Enterprise Sales Team or your existing contact.
So the model weights being open does not make the engine free to run indefinitely. It is free within a quota attached to an account, and the quota is the thing being metered.
That is an ordinary arrangement for a commercial SDK, and stating it this plainly is better than the alternative. It is worth being precise about what the quota counts, though, because the README does not say. Whether it counts tokens, requests, or running time changes the answer completely for a local model you are looping over a long document. An SDK that is nominally self-hosted but metered per call is a different economic proposition from one metered per token, and only one of those stays predictable as you scale.
The AccessKey section is where to ask.
The accuracy claim rests on one model and one benchmark
The quantization story is specific enough to be checkable, which is a compliment, and narrow enough to be worth bounding.
The claim is that picoLLM Compression learns the optimal bit allocation across and within the model's weights given a task-specific cost function, whereas existing techniques require a fixed bit allocation scheme that is described as subpar. The published measurement is that it recovers the MMLU score degradation of GPTQ by 91%, 99%, and 100% at 2, 3, and 4-bit, on Llama-3-8b.
The mechanism is the interesting part. A fixed scheme spends the same bits everywhere; a learned one moves capacity between layers and within them according to a cost function you supply. The phrase task-specific is doing real work in that sentence, since it implies the allocation is fitted rather than universal.
The limitation is the sample size. One benchmark, one model, one comparison baseline. MMLU is a multiple-choice knowledge test, which measures how much capability survives quantization rather than how well the compressed model follows an instruction. The video entries suggest the second matters more to this project, since several of them are voice assistants.
Nothing in the repository reports either measure for a chat or agent workload.
Seven bindings, one set of three flags
The platform list is long and the interface is not.
Supported targets are Linux on x86_64, macOS on arm64 and x86_64, Windows on x86_64 and arm64, Raspberry Pi 3, 4, and 5, Android, iOS, and four browsers: Chrome, Safari, Edge, and Firefox. Inference runs on CPU and GPU. SDKs are published to PyPI as picollm, NuGet as PicoLLM, npm as @picovoice/picollm-web, Maven as picollm-android, and CocoaPods as picoLLM-iOS.
Against that, each demo takes the same three arguments: an access key, a model path, and a prompt. The differences are packaging rather than interface. Python installs a demo package with pip3, Node.js installs globally with yarn, .NET builds a named Release configuration and runs it with dotnet run, and Android opens a project in Android Studio.
The macOS pair is worth noting. Both arm64 and x86_64 are listed, so Intel Macs are covered rather than being an arm-only situation, and Windows arm64 sits alongside x86_64 for the same reason.
Where the demos will differ is in streaming, in batching, and in how generation parameters are exposed, and none of that appears in the top-level documentation.
The tree has include and lib but no engine source
The repository layout tells you what you can and cannot change.
At the top level there are binding/, demo/, include/, lib/, resources/, Package.swift, a LICENSE, and a .gitmodules file. There is no src directory. A bindings directory and per-platform demos are the shape of a wrapper project, and include plus lib is the shape of prebuilt native artefacts shipped alongside it.
The .gitmodules file is the confirming detail. The native binaries are pulled in as submodules rather than built from this tree, which means the quantization engine itself is not something you can read, patch, or compile.
Package.swift sits at the root for Swift Package Manager, which is how the iOS binding is consumed, and resources/ presumably carries model or metadata files, though nothing in the visible text says what is in it.
The licence on all of this is Apache-2.0, which covers the bindings, the demos, and the build glue. It does not extend to a closed binary that the bindings call into. That distinction is normal in this space and rarely written down, but it is the difference between a dependency you can audit and one you can only measure.
If auditing the arithmetic matters to you, that is the question to ask before you build on it.
Eight platforms and about two dozen model names
The catalogue is curated, small, and not entirely a list of chat models.
Counting the identifiers gives roughly twenty-five entries across DeepSeek-OCR-2, EmbeddingGemma, Gemma, Gemma3, Llama-2, Llama-3, Llama-3.2, Mistral, Mixtral, Phi-2, Phi-3, Phi-3.5, and Qwen3-VL. The Gemma 2 and 7B variants are there with and without instruction tuning, Llama-2 goes to 70B, and Llama-3.2 offers only the 1B and 3B instruct builds.
Three entries are not plain text completion models and nothing marks them as such. DeepSeek-OCR-2 and Qwen3-VL are vision-oriented, and EmbeddingGemma produces vectors rather than text. They appear in the same list as gemma-2b and mixtral-8x7b, with no note about whether they run through the same completion path or a separate one.
Gemma3 is also represented by a single 270M size, both the base and instruction-tuned variants. That is a deliberate-looking omission of the larger members of that family, and it is the kind of gap that makes a catalogue feel like a curated set of tested configurations rather than a mirror of upstream releases.
Release history supports that reading. v1.3 was tagged in March 2025, v2.0 in December 2025, and v2.1 in April 2026, with the last push to main on 11 September 2026.
Editorial conclusion
picoLLM makes sense when the model has to run on a Raspberry Pi, in a mobile app, or in a browser tab, which are the cases its own videos pick. It is less obviously right when you already have a server with a GPU. Check four things before you commit. Whether your connectivity policy allows the AccessKey validation call, since a fully offline machine will not start. Whether the model you want is in the console list, because the catalogue is curated rather than open. What your account limit is, since free applies to open-weight models within a quota. And whether the X-Bit accuracy advantage on the documented benchmark transfers to your task, since the published numbers come from MMLU on one Llama model.
Frequently asked questions
How do I run a picollm completion from the command line?
Install the demo package with pip3 install picollmdemo, then run picollm_demo_completion with --access_key, --model_path, and --prompt. The model path is the path to a model file downloaded from the Picovoice Console.
Does picollm send my prompts to Picovoice?
Inference is described as running 100% locally and the cross-browser demo is labelled as working offline. The AccessKey section also states you need internet connectivity to validate your key against Picovoice licence servers even though inference itself runs offline.
Which models does picollm support?
The listed open-weight models include DeepSeek-OCR-2, EmbeddingGemma, Gemma, Gemma3, Llama-2, Llama-3, Llama-3.2, Mistral, Mixtral, Phi-2, Phi-3, Phi-3.5, and Qwen3-VL. The model files themselves are on the Picovoice Console rather than fetched by the runtime.
Which platforms can picollm run on?
Linux on x86_64, macOS on arm64 and x86_64, Windows on x86_64 and arm64, Raspberry Pi 3, 4, and 5, Android and iOS, plus Chrome, Safari, Edge, and Firefox. Inference runs on both CPU and GPU.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/picovoice-picollm)Star history chart for your README
[](https://hysenlabs.com/projects/picovoice-picollm)Was this useful?