Open-Sora Plan: an open text-to-video reproduction effort whose v1.5.0 only runs on Huawei Ascend
This project aim to reproduce Sora (Open AI T2V model), we wish the open source community contribute to this project.
At a glance
- What is it?
- PKU-YuanGroup/Open-Sora-Plan tries to reproduce OpenAI's Sora as an open codebase, with versions from v1.0.0 to v1.5.0. The newest release is trained and inferred on Ascend 910-series accelerators, and the repository's last push was in March 2026.
- Who is it for?
- Open-Sora Plan suits researchers who want the reports, the WFVAE and the sparse attention designs, or who own Ascend hardware. It is a poor pick for anyone who needs a maintained GPU video generator today: the GPU build of v1.5.0 was still marked as coming soon, the last push was on 8 March 2026, and the pinned dependencies need checking against your CUDA stack before anything else.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
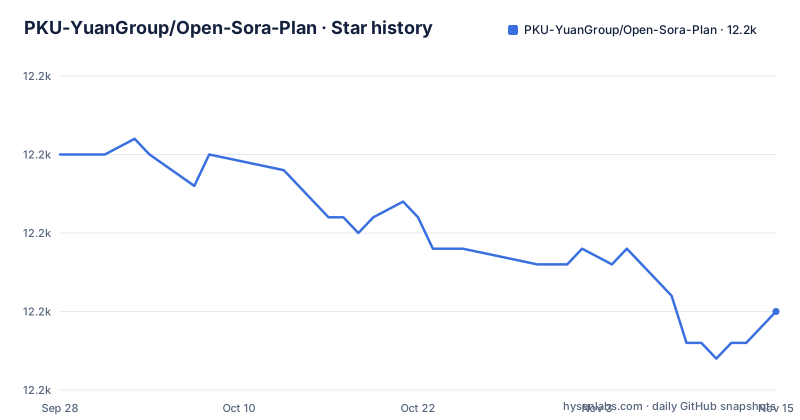
Star history
- PKU-YuanGroup/Open-Sora-Plan12,200 ★ · -10
| Repository | 2026-09-28 | 2026-11-15 |
|---|---|---|
| PKU-YuanGroup/Open-Sora-Plan | 12.2k | 12.2k |
-10 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Version 1.5.0 is built for Ascend 910 hardware, and the GPU build was still promised
The release note for 1.5.0, dated 5 June 2025, says the model is fully trained and inferred on Ascend 910-series accelerators. The new code sits on the mindspeed_mmdit branch, not on main, and the report is docs/Report-v1.5.0.md. The same note ends with the sentence that the GPU version is coming soon. The README header repeats the point in Chinese: V1.5 is trained entirely on Huawei Ascend. For a reader with NVIDIA cards the consequence is direct. The newest and strongest checkpoints in the repository are not a drop-in download for your hardware, and the older versions are where a GPU workflow has to start. Check the branch you clone before you assume main holds the v1.5.0 code. The project describes itself as launched by the PKU-Rabbitpre AIGC joint lab, with contributions from Rabbitpre, Huawei, Pengcheng Laboratory and open-source partners, which explains the Ascend focus: the v1.0.0 announcement already thanked Huawei NPU for its support.
The pyproject.toml pins an older stack than the latest release
The packaging file declares the project as opensora, version 1.3.0, with requires-python set to >=3.8, while the newest GitHub release is v1.5.0. It pins dependencies exactly: torch==2.1.0, torchvision==0.16.0, xformers==0.0.22.post7, transformers==4.44.2, diffusers==0.30.2, deepspeed==0.12.6, accelerate==0.34.0, gradio==4.0.0 and numpy==1.24.4. Exact pins keep the older code reproducible, but they will collide with any environment that already carries a newer PyTorch or a newer transformers. Plan a dedicated virtual environment for it. The setuptools config also excludes assets, docker, docs and scripts from the package, so the training scripts are not something you get from the installed distribution.
The licence field says MIT in one place and Apache in another
GitHub lists the repository licence as MIT, and the README badge links to the LICENSE file in the repository. The pyproject.toml classifiers, however, declare License :: OSI Approved :: Apache Software License. Both permit commercial use in broad terms, but they are different texts, and a company wiring this code into a product should read the LICENSE file itself and not rely on the packaging metadata. The README also points readers to model checkpoints hosted on Hugging Face under LanguageBind, and those repositories may carry their own terms, so confirm the licence for the weights separately from the licence for the code.
Each version changed the architecture, so checkpoints are not interchangeable
The resource table lists a different architecture per version. v1.2.0 is Dense 3D, with weights such as 93x720p and 93x480p. v1.3.0 and later use Skiparse 3D, with Anysize checkpoints at 93x640x640 and an image-to-video variant at 93x640x640_i2v. v1.5.0 uses SUV, described as Skiparse 3D, with a 121x576x1024 diffusion model file named model_ema.pt under a MindSpeed folder and a WFVAE file named wfvae_888_dim32.ckpt. Every version also has its own VAE. The consequence is that you cannot pair a VAE from one row with a diffusion model from another, and code written against v1.2.0 does not carry over to v1.5.0 without work.
WFVAE and SUV carry the technical claims, and they are the project's own measurements
Two highlights anchor the v1.5.0 story. WFVAE uses an 8x8x8 downsampling rate and the README says it reaches higher PSNR than the VAE used in Wan2.1, which lowers the training cost of the DiT built on it. SUV, the sparse attention architecture, is described as achieving performance close to a dense DiT with over a 35% speedup. The release note adds that an 8B-scale model trained on 40 million video samples reaches performance comparable to HunyuanVideo. These are the authors' own statements, linked to reports and papers on arXiv, and nothing in the repository shows an independent reproduction. Read the report before quoting any of those numbers. The earlier releases follow the same pattern of changes: v1.2.0 replaced a 2+1D design with 3D full attention and a true 3D video diffusion model trained on 4s 720p, and the v1.2.0 image-to-video model added transition generation, where both the starting and ending frames condition the output. Each step is a design change documented in its own report under docs, so the reports are the place to learn what actually differs between versions.
Memory use was only documented for the older v1.3.0 model
The one concrete hardware figure in the README comes from v1.3.0, released on 16 October 2024: it supports 93x480p within 24G VRAM. That release also introduced WFVAE, a prompt refiner, a data filtering strategy, sparse attention and a bucket training strategy. For v1.5.0 the text gives no VRAM figure, because the model is described only on Ascend accelerators. Anyone sizing a GPU for this project should therefore plan around v1.3.0 numbers and treat v1.5.0 requirements as unknown. The repository also includes example inputs such as examples/cond_prompt.txt, examples/cond_pix_path.txt and examples/sora.txt, plus examples/rec_image.py and examples/rec_video.py for VAE reconstruction.
The last push was on 8 March 2026, and it pointed to a different project
The repository is not archived, but its last push on 8 March 2026 is about eight months before this article was written, so it should not be read as under active development. The newest GitHub releases are v1.5.0 (5 June 2025), v1.3.1 (22 October 2024) and v1.3.0 (15 October 2024). The most recent news item, from 8 March 2026, introduces Helios, a separate repository from the same group that claims minute-scale video synthesis at 19.5 FPS on a single H100. So the group's current video work is moving to a new codebase, and Open-Sora Plan is better seen as a documented record of versions 1.0.0 through 1.5.0 than as a place waiting for new features.
Editorial conclusion
Open-Sora Plan suits researchers who want the reports, the WFVAE and the sparse attention designs, or who own Ascend hardware. It is a poor pick for anyone who needs a maintained GPU video generator today: the GPU build of v1.5.0 was still marked as coming soon, the last push was on 8 March 2026, and the pinned dependencies need checking against your CUDA stack before anything else.
Frequently asked questions
Is there an open-source version of Sora in Open-Sora Plan?
Open-Sora Plan is an open-source attempt to reproduce Sora, OpenAI's text-to-video model, and is not OpenAI's own release. Its GitHub licence is MIT and its versions run from v1.0.0 to v1.5.0.
Is Open-Sora Plan free?
The repository is listed under the MIT licence, and the model checkpoints are hosted on Hugging Face under LanguageBind. The pyproject.toml classifier names the Apache Software License instead, so check the LICENSE file and the weight pages before commercial use.
What is the Sora OpenAI app in relation to Open-Sora Plan?
The repository describes Sora as OpenAI's text-to-video model, and Open-Sora Plan aims to reproduce it with community contributions. Open-Sora Plan is an independent research codebase, not an app from OpenAI.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pku-yuangroup-open-sora-plan)Star history chart for your README
[](https://hysenlabs.com/projects/pku-yuangroup-open-sora-plan)Was this useful?