Prefect: two UI builds, two pyproject files, one SQLite tag
Prefect is a workflow orchestration framework for building resilient data pipelines in Python.
At a glance
- What is it?
- Prefect is an Apache-2.0 Python framework for turning scripts into scheduled, retried, observed workflows, installable with pip or uv. Underneath that simple pitch sit three maintenance mechanics worth knowing: a SQLite image tag that must be published before a build can pull it, two Node build stages for two web front ends, and a dependency list that has to be edited in two files at once.
- Who is it for?
- Prefect suits a Python team that wants scheduling, caching, retries, and a UI over existing scripts, and that is willing to run a server process to see anything at all. It does not suit a project that wants a dependency free client, since the main package installs server libraries too and prefect-client exists precisely to avoid that, nor a team that wants generated API docs for the agent and analytics modules, which are excluded from the reference build.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
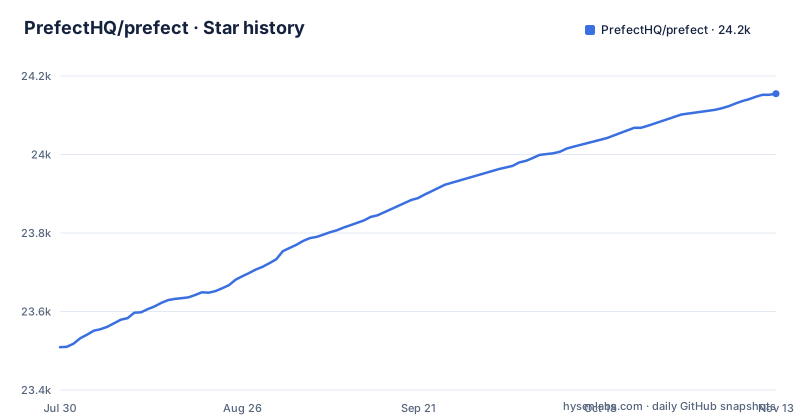
- PrefectHQ/prefect24,155 ★ · +646
| Repository | 2026-07-30 | 2026-11-13 |
|---|---|---|
| PrefectHQ/prefect | 23.5k | 24.2k |
646 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The SQLite image has to be published before the Dockerfile can pull it
The container build does not compile SQLite. It pulls a prebuilt one, and the version is pinned by an argument whose comment spells out the publishing contract. The argument is SQLITE_VERSION, set to 3.50.4, and the comment says it must match the tag published to prefecthq/prefect-sqlite on DockerHub, pointing at Dockerfile.sqlite-builder and a workflow file for the builder. A second comment gives the procedure: to publish a new version, bump SQLITE_VERSION and run the sqlite-builder workflow. The stated reason is that this avoids compiling SQLite from source on every build. The cost is a release step that lives outside this repository, so changing the SQLite version is a publish operation followed by a build rather than a one line edit, and the number has to match on both sides.
Two front ends, two Node versions, two build stages
The image builds two separate web interfaces and pins a Node release for each through separate arguments. One argument, NODE_VERSION at 22.23.4, builds what the comment calls the V1 UI distributable. Another, NODE_V2_VERSION also at 22.23.4, builds the V2 UI distributable and carries the note that it requires Node 22 or newer. The source matches that split, with a ui/ directory and a ui-v2/ directory at the repository root, plus an .nvmrc. For a contributor this decides which toolchain you need before you can build anything that touches the interface, and it means a container image carries both front ends even if your deployment uses one. The UI build stage also installs chromium, with a comment marking it as required for arm64 builds.
The dependency list is written twice and the comment says so
The project metadata splits its dependencies into two labelled groups, one for the server and one for the client, and right between them sits a comment that is the most useful line in the file: if you modify this list, make the same modification in client/pyproject.toml. That instruction refers to a client/ directory at the repository root holding its own project file. In other words the same dependency set is maintained in two places by hand, with nothing in the build described here that checks the two agree. Read the grouping as a design statement too. The server half brings database and infrastructure libraries including aiosqlite, asyncpg, alembic, sqlalchemy with the asyncio extra, docker, and cryptography. The client half brings things like anyio, asgi-lifespan, cachetools, cloudpickle, and coolname. A change to the client list that does not also land in client/pyproject.toml is a silent drift until something fails at install time.
Installing prefect installs the server half too, which is why prefect-client exists
One command gives you both halves. The install instructions offer two routes, and they are equivalent for this purpose.
pip install -U prefectuv add prefectEither one resolves the full dependency list described above, so a script that only wants to submit work to an existing Prefect gets database drivers, migration tooling, and the ASGI stack along with it. The project acknowledges this and names the alternative: prefect-client, described as a lighter weight option for accessing client side functionality in the Prefect SDK, and stated to be ideal for use in ephemeral execution environments. The dividing line the project draws is between talking to Prefect Cloud or a remote Prefect server from a short lived process, and running a server yourself. Read that as the deciding question when choosing which package to put in a container image.
Nightly development tags ship beside the patch line
The recent releases are all from the development stream: 3.9.2.dev1 on 2026-11-01, 3.9.2.dev2 on 2026-11-02 and 3.9.2.dev3 on 2026-11-03 are each labelled as a Nightly Development Release, one per day. The version number itself is not written into the project file: it is declared dynamic and produced by versioningit at build time, with hatchling as the build backend. The practical reading is that the dev tags are for testing what is about to become the next patch, so a production pin belongs on the numbered line and the nightlies belong in a test environment.
Serving locally means two processes, one looking for work
Running a flow on a schedule is a different shape from running a script, and the difference is a process that stays alive. Instead of calling the flow directly, the last lines of the script change to this.
if __name__ == "__main__":
    github_stars.serve(
        name="first-deployment",
        cron="* * * * *",
        parameters={"repos": ["PrefectHQ/prefect"]}
    )
The cron value shown runs every minute, which is a demonstration setting rather than a sensible schedule. The project then states what you have: a process running locally that is looking for scheduled deployments. Alongside it, a separate command starts the server whose UI you open at http://localhost:4200.
prefect server startSo the local setup is two things running at once, one waiting for work and one recording it, and a workflow with no schedule and no server simply executes.
Agent setup is served as plain text through plugins or MCP
The project now addresses coding agents directly, which is unusual to find in a data orchestration framework. It points to agent setup guides for connecting an agent to Prefect through plugins or MCP, and offers an agent readable setup index that provides the same guides as plain text. The examples directory shows where that leads in practice. Among the files are an AI data analyst built with pydantic ai, a database cleanup that involves approval, a dashboard built with Prefect assets, a flow run resumed on a pull request merge, a per worker task concurrency example, a dbt run, an API sourced ETL, a web scraper, and a hello world. The tilt is noticeable: of nine examples, two are AI examples, and one of those includes an approval step.
Contributor commands assume uv, and the docs build pins its own Python
Development runs through a justfile rather than a Makefile, and its first job is checking the tool. The check-uv recipe looks for uv on the path and, when it is missing, prints the install command for the platform it detects: brew install uv on macOS, a curl installer on Linux, and a link for anything else. Installing development dependencies then means uv sync with a perf group selected. Generating the API reference is a separate recipe that runs uvx against an editable install of the project, isolated, using Python 3.12 regardless of the wider support range, pulling mdxify at 0.2.45 or newer. That same call excludes two modules, prefect.agent and prefect.analytics, from the generated reference.
Editorial conclusion
Prefect suits a Python team that wants scheduling, caching, retries, and a UI over existing scripts, and that is willing to run a server process to see anything at all. It does not suit a project that wants a dependency free client, since the main package installs server libraries too and prefect-client exists precisely to avoid that, nor a team that wants generated API docs for the agent and analytics modules, which are excluded from the reference build. Before committing, decide between the full package and prefect-client, read which of ui or ui-v2 you are actually changing, and if you build the container image, confirm the SQLite tag you need has already been published.
Frequently asked questions
How do I install prefect?
Prefect requires Python 3.11 or newer, and two install commands are offered: pip install -U prefect, or uv add prefect. Both resolve the same package, which is published on PyPI.
What is prefect in software terms?
Prefect is a workflow orchestration framework for building data pipelines in Python. The project describes it as a way to elevate a script into a production workflow, with scheduling, caching, retries, and event based automations.
Is prefect open source?
Yes, under the Apache-2.0 licence, with the licence text in the LICENSE file at the repository root and the licence declared in the project metadata. Workflow activity can be tracked on a self hosted Prefect server, and Prefect Cloud is offered separately as a managed dashboard.
Is prefect free?
The framework is published under Apache-2.0 and installs from PyPI without a licence key. Prefect Cloud is a separate managed product that the project says automates over 200 million data tasks monthly, and the site offers a cloud versus open source comparison page.
How do I use prefect for a scheduled workflow?
Decorate functions with the task and flow decorators, then replace the direct call with serve, passing a name, a cron schedule, and parameters. Start a server with prefect server start and open the UI at http://localhost:4200 to see what ran.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/prefecthq-prefect)Star history chart for your README
[](https://hysenlabs.com/projects/prefecthq-prefect)Was this useful?