pypdf: pure-Python PDF pages, with AES behind an extra
A pure-python PDF library capable of splitting, merging, cropping, and transforming the pages of PDF files
At a glance
- What is it?
- pypdf is a pure-Python library that splits, merges, crops and transforms PDF pages, and reads text and metadata off them, for Python developers who do not want a native dependency in the image. The base install is small on purpose and stops short of two things people usually reach it for: there is no OCR, and AES encryption only appears once you ask for the crypto extra.
- Who is it for?
- pypdf fits code that needs page level operations on PDFs that already carry a text layer, with no compiler step in the build image. It does not fit scanned documents, because nothing in the declared extras runs optical character recognition, and it does not fit AES protected files until you install the crypto extra.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
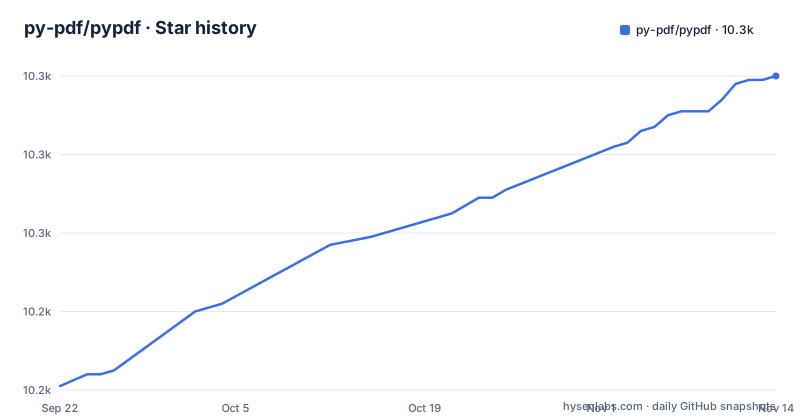
- py-pdf/pypdf10,300 ★ · +79
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| py-pdf/pypdf | 10.2k | 10.3k |
79 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Install with pip, then open a file with PdfReader and call extract_text()
pypdf installs as an ordinary wheel from PyPI:
pip install pypdfThe whole read path is five short statements:
from pypdf import PdfReader

reader = PdfReader("example.pdf")
number_of_pages = len(reader.pages)
page = reader.pages[0]
text = page.extract_text()
`reader.pages` behaves as a sequence, so `len()` gives you the page count and indexing gives a single page object. `extract_text()` returns whatever characters sit in that page's content stream. Note what the example does not do: it never opens a file for writing. Splitting, merging, annotation creation and encryption are all named in the README as things pypdf does, but the only code shown there is read only, so the write half of the API is something you assemble from the documentation rather than from the README.
A base install runs no OCR, so a scanned page has nothing to return
pypdf reads the text layer of a PDF. It does not read pixels, and nothing in the package metadata suggests otherwise. The declared extras are brotli, crypto, cryptodome, fonts, image, rtl_text and a full bundle, and none of them is an OCR engine. That gap matters more than a feature list makes it sound, because a document that arrived as a scan has no text layer. Treat it as the case to test first: a pipeline that quietly indexes zero characters from a scanned archive and reports success is the failure mode worth designing against. The README also points you to pdfly, a separate CLI application built on pypdf, which means command line work is a second package to install rather than a flag on this one.
pip install pypdf[crypto] for AES, and two backends to choose between
AES encryption and decryption sit behind an extra:
pip install pypdf[crypto]That extra resolves to `cryptography>=43`. The project metadata also declares a second extra, `cryptodome`, resolving to PyCryptodome, so there are two ways to reach the same feature and nothing in the README explains which one to choose or what differs between them. The practical consequence is that a plain `pip install pypdf` does not include what AES encryption or decryption needs, according to the README.
rtl_text, image and fonts extras, and what a base install leaves out
The rest of the optional surface is more extras (brotli, fonts, image and rtl_text) plus a bundle. `fonts` pulls in fonttools. `image` pulls `Pillow>=8.0.0`. `rtl_text` pulls both arabic-reshaper and python-bidi, which is the usual pairing for reshaping right to left text, and it exists as a separate extra because the base install does not contain either package. What you get for an Arabic or Hebrew document when you skip that extra is not written down, so run a real file through `extract_text()` before you assume the result is usable text. A `full` extra is declared alongside the others for taking the group in one go. None of this is needed to split or merge pages, which is why the install line in the README stops at `pip install pypdf` and leaves the rest to you.
Python 3.9 is the floor, and 3.11 removes the last dependency
`requires-python` is `>=3.10`, and the classifiers list 3.10 through 3.15, along with an Operating System marker of OS Independent and a Typing marker of Typed. The runtime dependency list holds exactly one entry, `typing_extensions >= 4.0; python_version < '3.11'`, so on 3.11 and above a plain install pulls in no third party package at all. On 3.10 it adds one, which is a small thing and still a real thing for a service that pins an interpreter to keep its dependency tree at zero. Being pure Python also means there is no build step and no compiler needed in the image. Packaging runs through flit, declared as `requires = ["flit_core >=3.11,<5"]` with `build-backend = "flit_core.buildapi"`, and the version is listed under `dynamic`, so it comes from the package rather than from pyproject.toml.
The upgrade note points at a guide named migration-1-to-2 for 3.1.0 changes
One line deserves a close read: `pypdf` 3.1.0 and above include significant improvements compared to previous versions, and the link goes to a document whose path ends in `user/migration-1-to-2.html`. The note describes a break at 3.1.0 while the page it points at is named for the move from 1 to 2. Anyone upgrading from a 2.x line therefore finds no bridge to 3 in that link. The repository root does carry CHANGELOG.md, and the project metadata links a changelog under the readthedocs domain, but the note itself routes you to neither. The practical reading is that this is a library with a real history of breaking changes and a documentation trail that does not line up, so pin an exact version in anything long lived rather than tracking whatever pip resolves.
A useful pypdf bug ticket ships the PDF that breaks
The project asks for an MCVE, a minimal complete verifiable example, and for pypdf that specifically means uploading the PDF that triggers the bug together with the code and all of its output, written as code plus example PDF. It also asks for `print(pypdf.__version__)` so the report says which release is in play. That request has a consequence for anyone running pypdf over documents under NDA or a customer contract: a ticket that can actually be fixed is a ticket that carries the file. Plan on reducing a sample until it still reproduces the failure instead of attaching the original. Questions get answered on Stack Overflow under the pypdf tag and in the repository discussions, and the project states that smaller contributions have a better chance of being included in a timely manner.
make testtype turns runtime type errors inside the library into failures
The Makefile shows what this project treats as a gate before a merge. `make test` runs pytest with coverage, a 60 second per test timeout and the three slowest durations reported. `make testtype` reruns the suite with `--typeguard-packages=pypdf` and a tighter 30 second timeout, so a type error raised at runtime inside the library fails the run rather than passing quietly. `make mypy` and `make ruff` cover the static side, with ruff pointed at `pypdf tests make_release.py`. Releases are cut by script rather than by hand, via the `release` target, which runs make_release.py and then commits a prepared message file. That accounts for the CHANGELOG.md and make_release.py files sitting at the repository root next to requirements/, docs/, sample-files and tests/. One thing to ignore while you are there: the pytest output quoted in the README shows Python 3.6.15, pytest-7.0.1 and 233 collected items, which predates the 3.10 floor the package now declares.
Editorial conclusion
pypdf fits code that needs page level operations on PDFs that already carry a text layer, with no compiler step in the build image. It does not fit scanned documents, because nothing in the declared extras runs optical character recognition, and it does not fit AES protected files until you install the crypto extra. Before committing, run pip install pypdf[crypto] on the same interpreter your service uses, print the version it resolved to, and pin it explicitly: three releases landed within seven days, from 6.21.2 on 2026-10-21 to 6.21.4 on 2026-10-28.
Frequently asked questions
What is pypdf in Python?
pypdf is a pure-Python library for splitting, merging, cropping and transforming the pages of PDF files, and for adding custom data, viewing options and passwords to them. It retrieves text and metadata as well, and its packaging metadata declares BSD-3-Clause with requires-python of >=3.10.
Is pypdf an OCR tool?
No. pypdf reads the text layer of a PDF and does not run optical character recognition. The optional extras it declares are brotli, crypto, cryptodome, fonts, image and rtl_text, and none of them is an OCR engine.
How do I use pypdf to extract text from a PDF?
Open the file with PdfReader, index into reader.pages, and call extract_text() on the page you want. The README example reads the first page and assigns the result to a variable named text.
How do I install pypdf in Python?
Run pip install pypdf. For AES encryption or decryption install the extra instead, with pip install pypdf[crypto], which resolves to cryptography>=43.
Can I install pypdf on Windows?
The package metadata marks pypdf OS Independent and requires only Python 3.10 or newer, so nothing in the install is platform specific. The project assumes pip and a working Python environment, and its documentation is hosted at pypdf.readthedocs.io.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/py-pdf-pypdf)Star history chart for your README
[](https://hysenlabs.com/projects/py-pdf-pypdf)Was this useful?