DoWhy puts refutation next to estimation, and its version number comes from git
DoWhy is a Python library for causal inference that supports explicit modeling and testing of causal assumptions. DoWhy is based on a unified language for causal inference, combining causal graphical models and potential outcomes frameworks.
At a glance
- What is it?
- DoWhy is PyWhy's MIT-licensed causal inference library: identification through graphical causal models and do-calculus, estimation through potential outcomes, and a refutation API that tests assumptions for any estimation method. The costs live in the dependency tree, where numba and econml hold part of it below Python 3.11, and in a version string generated from git tags.
- Who is it for?
- Use DoWhy when your team can defend a causal graph and wants the assumption checks to survive an estimator swap, and use a plain estimator library when nobody will own the graph. Verify two things before building on it: whether the estimator you need routes through econml and therefore through numba, which pyproject.toml marks as needing Python below 3.11, and what version your install reports, since it is generated from git tags rather than a number committed to the tree.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
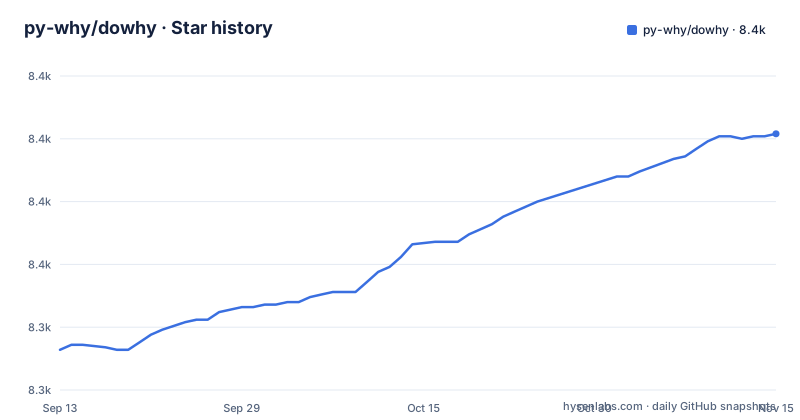
- py-why/dowhy8,402 ★ · +86
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| py-why/dowhy | 8.3k | 8.4k |
86 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Refutation is the part that runs against any estimator
Plenty of libraries estimate an effect. The feature DoWhy puts at the centre of its README is that its refutation and falsification API can test causal assumptions for any estimation method, which means the check on your assumptions is not welded to the estimator that produced the number.
That has a concrete consequence. If you try an estimator, refute it, swap in a different one, and refute again, the second check runs the same way. A refuter that only works with one estimator leaves you comparing results without re-examining the assumptions, which is the failure mode where a plausible number survives a broken graph. The repository root carries example_parallel_refutation.py and test_parallel_refuters.py, files named for running refutation in parallel.
What refutation cannot do is repair the graph you drew. It tells you whether the estimate survives a test of your assumptions. It does not tell you which node you got wrong.
Graphs identify, potential outcomes estimate, and you switch between them
DoWhy is built on two frameworks at once, and the README is explicit about which does which. For effect estimation it uses graph-based criteria and do-calculus for modelling assumptions and for identifying a non-parametric causal effect. For estimation it then switches to methods based primarily on potential outcomes.
The split has an effect on where failures appear. Identification is a property of the graph, so a graph with no valid adjustment set fails before any estimator runs, and the thing you have to defend is a set of arrows rather than a model object. Once identification succeeds, the estimator borrows from potential outcomes and the graph steps back. Below effect estimation the emphasis moves: DoWhy models the data generation process through explicit causal mechanisms at each node, which is what makes it possible to attribute an observed effect to particular variables or to estimate point-wise counterfactuals for one row rather than for the population.
So the graph is not a picture of your model. It is the thing that decides which questions you are allowed to ask.
Three installers, and conda has its own documented rescue
The README offers pip, poetry and conda, one line each.
pip install dowhypoetry add dowhyconda install -c conda-forge dowhyThe conda path comes with a troubleshooting note: if you hit Solving environment problems, run conda update --all and install again, and if that fails there is a conda config change suggested next. That advice is doing real work, since a conda solver that cannot find a compatible set for your platform will refuse the whole install rather than degrade.
Underneath the install is a dependency set that is not plain Python. pyproject.toml requires cython at >=3.0 in the runtime dependencies as well as in the build system, and its Poetry configuration declares an explicit torch-cpu package source at download.pytorch.org.
The README says Python 3.8+, the metadata says 3.9 to 3.13
Two version statements sit side by side and they disagree. The installation section says DoWhy supports Python 3.8+. The packaging metadata constrains python to >=3.9,<3.14 and its classifiers stop at 3.13, listing 3.9 through 3.13 and marking the project as Development Status :: 4 - Beta.
For a reader the metadata is the one your installer obeys, so 3.8 is out in practice, and 3.14 is out by declaration rather than by test. The rest of the tree shifts with the interpreter. cython is required at >=3.0, the setuptools floor changes at the 3.13 boundary, and the scipy entry visible in the file is scoped to python >=3.9,<3.13, so a resolver on 3.13 is working from a different constraint set than one on 3.12. The release history explains the drift: v0.12 added Python 3.12 compatibility in November 2024 and v0.14 added Python 3.13 support in November 2025, one interpreter at a time.
numba through econml is marked as needing Python below 3.11
pyproject.toml carries a comment block titled dependency compatibility notes with a single entry: numba, imported by econml, requires python <3.11. That one line explains a lot about how this library relates to econml. In pyproject.toml, econml appears as something the dependency tree reaches through.
The consequence is about which estimators you can use on a modern interpreter. The same file allows python >=3.9,<3.14, so the note is a reason to check, on your interpreter, any estimation path that reaches numba via econml. That is the question to ask before choosing an effect estimation method: what does this one import, and is that import still resolvable on our runtime.
The version is generated from git, so an untagged build reports 0.0.0
pyproject.toml declares dynamic = ["version"] and leaves version = "0.0.0" as a placeholder, with a comment saying that value is standard for poetry-dynamic-versioning and that changes to it should not be checked in. The plugin section turns the mechanism on, points it at git, sets the format to {base}, and substitutes the result into dowhy/__init__.py.
That is tidy for releases and awkward everywhere else. The 0.0.0 in pyproject.toml is only a placeholder for the value poetry-dynamic-versioning derives from git. The visible consequence is in your own systems: a bug report that carries the printed version, or a lock file that pins dowhy, records a number that may not correspond to the code it was taken from. Vendoring the directory into another project removes the git context entirely, and with it the version.
The alternative, a number written by hand and bumped by hand, is what this setup trades for fewer merge conflicts in the version file.
Three releases in two years, with new estimators added rather than changed
The tags tell a slow story. v0.12 came on 2024-11-24 with Python 3.12 compatibility, experimental support for time-series data, and extensions to new scenarios. v0.13 followed on 2025-07-12 with a Generalized Adjustment Criterion for effect estimation and missing data support in GCM. v0.14 landed on 2025-11-08 with Python 3.13 support and a new doubly robust estimator. The last push to the repository was on 2026-11-02.
Two things follow for an adopter. The additions are named methods, a criterion and an estimator, so moving from v0.12 to v0.14 mostly widens what you can call rather than rewriting what you already call, which is the friendlier shape of a version bump. And the time-series support from v0.12 is the one feature the project labels experimental, with no later release note claiming it graduated, so a time-series question in v0.14 is still on the label it was born with. Read the note attached to the version you are pinning rather than assuming the newest tag means the newest work.
Governance lives in markdown while the package maintainer list is empty
The repository root is unusually explicit about process. GOVERNANCE.md, MAINTAINERS.md, CONTRIBUTING.md and AGENTS.md sit beside the code, and the project sits in the PyWhy organization with a Discord for use cases, documentation published at py-why.github.io/dowhy, example notebooks in their own index, and a binder/ directory for running them without a local environment.
The gap is in the packaging metadata. pyproject.toml lists authors as the PyWhy Community with one contact address and sets maintainers to an empty list. So who reviews a change is written down in a markdown file and who maintains the distribution is written down nowhere a tool can read. That is a small thing for an analyst and a real thing for a platform team that checks dependency health from distribution metadata.
The example notebooks are the other half of the onboarding story, covering effect estimation and root cause analysis including a microservice latency case, but a notebook that runs on binder is not a test suite, and the repository keeps its tests in tests/.
Editorial conclusion
Use DoWhy when your team can defend a causal graph and wants the assumption checks to survive an estimator swap, and use a plain estimator library when nobody will own the graph. Verify two things before building on it: whether the estimator you need routes through econml and therefore through numba, which pyproject.toml marks as needing Python below 3.11, and what version your install reports, since it is generated from git tags rather than a number committed to the tree.
Frequently asked questions
what is dowhy
DoWhy is an MIT-licensed Python library for causal inference that guides you through the steps of causal reasoning with a unified interface. It supports effect estimation, quantification of causal influences, what-if analysis, and root cause analysis and explanations.
dowhy vs econml
pyproject.toml mentions econml in a compatibility note recording that numba, imported by econml, requires python <3.11.
Which Python versions does DoWhy actually support?
The README says DoWhy supports Python 3.8+, while pyproject.toml constrains python to >=3.9,<3.14 with classifiers from 3.9 to 3.13. Release v0.12 added Python 3.12 compatibility and v0.14 added Python 3.13 support.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/py-why-dowhy)Star history chart for your README
[](https://hysenlabs.com/projects/py-why-dowhy)Was this useful?