Optuna builds its search space while your objective runs, and that choice shapes the rest of the library
A hyperparameter optimization framework
At a glance
- What is it?
- A close look at optuna/optuna, the MIT-licensed Python hyperparameter optimization framework: how define-by-run search spaces work, what a base install pulls in and leaves out, and where Rustuna and Optuna Dashboard sit beside it.
- Who is it for?
- Optuna fits Python 3.10+ teams who want conditional search spaces written as ordinary Python and a library with a steady release history; it does not fit projects stuck on older interpreters or teams that need the full search space declared before any trial runs.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
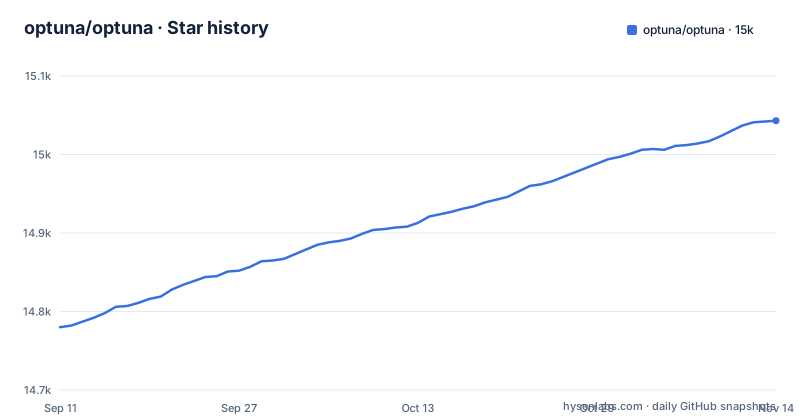
- optuna/optuna15,043 ★ · +263
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| optuna/optuna | 14.8k | 15k |
263 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The search space is whatever the objective function executes
Optuna's central design choice is its define-by-run API. You do not declare a parameter grid up front and hand it to a tuner. Instead you write an objective function that receives a trial object, and every call to a suggest method on that trial both draws a value and adds that parameter to the search space. The scikit-learn sample on the project page shows why this matters:
def objective(trial):

    # Invoke suggest methods of a Trial object to generate hyperparameters.
    regressor_name = trial.suggest_categorical("regressor", ["SVR", "RandomForest"])
    if regressor_name == "SVR":
        svr_c = trial.suggest_float("svr_c", 1e-10, 1e10, log=True)
        regressor_obj = sklearn.svm.SVR(C=svr_c)
    else:
        rf_max_depth = trial.suggest_int("rf_max_depth", 2, 32)
        regressor_obj = sklearn.ensemble.RandomForestRegressor(max_depth=rf_max_depth)
The parameter svr_c only exists in trials where the categorical choice landed on SVR, and rf_max_depth only exists in trials that picked RandomForest. Nothing outside the function has to encode that dependency. Plain Python if statements and loops build the space, which is what the project means by Pythonic search spaces. The value of svr_c is drawn between 1e-10 and 1e10 on a log scale because log=True is passed to suggest_float, while suggest_int keeps the tree depth between 2 and 32.
The cost of this design is that the search space is no longer a static object you can print or review before spending compute. It is discovered as trials execute. If a branch is never taken, its parameters never appear in the study at all. Anyone who wants to audit the full space, for a paper, a compliance review or a cost estimate, has to read the objective code itself rather than a configuration file.
Two nouns carry the whole API: study and trial
Optuna works with two terms. A study is an optimization based on an objective function. A trial is a single execution of that objective function. In the sample, the goal of a study is to find the best set of values for hyperparameters such as regressor and svr_c across multiple trials, for example n_trials=100, and the comment above the sample function states that the objective is a function to be minimized.
That vocabulary is small enough to keep in your head, and it maps directly onto how you structure code: one function that builds, trains and scores a model given a trial, and one study that calls it again and again. Between calls, Optuna's algorithms sample the next set of hyperparameters and prune unpromising trials, which are the two halves of what the project calls efficient optimization algorithms. The Key Features list on the project page links each claim to a tutorial chapter on optuna.readthedocs.io, from the first steps through configurations, optimization algorithms, distributed runs and visualization.
The distributed claim is specific: studies scale to tens or hundreds of workers with little or no changes to the code. How workers share one study is covered in the distributed tutorial chapter, so read that page before you design a cluster around Optuna rather than assuming a single-process script carries over unchanged. The separate optuna/optuna-examples repository has worked setups for multi-objective optimization, constrained optimization, pruning and distributed optimization, and a Colab notebook version of the quickstart.
A base install brings SQLAlchemy and Alembic whether or not you use a database
Optuna ships on PyPI and on conda-forge:
# PyPI
$ pip install optuna# Anaconda Cloud
$ conda install -c conda-forge optunaThe leading $ is the shell prompt, not part of the command. The package declares requires-python = ">=3.10" in pyproject.toml, and the project page repeats that Optuna supports Python 3.10 or newer. The trove classifiers list 3.10 through 3.15. If your environment is pinned to Python 3.9 or older, you have to upgrade the interpreter before you can install a current release; there is no supported path for older Python.
The runtime dependency list is short but not empty: alembic>=1.5.0, colorlog, numpy, packaging>=20.0, sqlalchemy>=1.4.2, tqdm and PyYAML. A comment in pyproject.toml notes that PyYAML is only used in optuna/cli.py, so it arrives even if you never touch the command line tool. SQLAlchemy and Alembic are hard requirements too, which means they are installed in a notebook where you never point Optuna at a database. In a locked-down image where every package must be reviewed and kept patched, that is several packages beyond numpy to vet before the first trial runs. The project describes its architecture as lightweight and platform agnostic with few requirements, and the list above is what few means in practice.
The package is built with setuptools 61.1.0 or newer and wheel, and its version is computed dynamically rather than written in pyproject.toml.
Plotting and the CMA-ES sampler sit outside the default dependency set
The extras section of pyproject.toml shows what the base install leaves out. The document extra lists plotly>=4.9.0 with a comment pointing at optuna/visualization, cmaes>=0.12.0 with a comment pointing at optuna/samplers/_cmaes.py, matplotlib with version 3.6.0 excluded, pandas, pillow, scikit-learn, lightgbm, ase and fvcore, plus the Sphinx packages used to build the documentation. None of these appear in the runtime dependencies.
The consequence for a reader: pip install optuna gives you the study and trial machinery, but the quick visualization features advertised on the project page call into code that needs plotly, and the CMA-ES sampler module relies on the cmaes package. You add both yourself. The same applies to the scikit-learn sample above. It imports sklearn, but scikit-learn is not an Optuna runtime dependency, so a fresh environment with only optuna installed cannot run the quickstart. Build your requirements file around the features you will call, not around the single optuna line.
One more detail from the same file: the docs extra pins sphinx-gallery below 0.22 because Sphinx-Gallery 0.22.0 truncates dotted image filenames, and a comment marks the pin for removal once the upstream filename handling is fixed. That only affects people building the documentation locally from the docs/ and tutorial/ directories, but it is the kind of pin to know about if you mirror the docs build inside your own tooling.
Version 5 arrived in September 2026, so unpinned installs cross a major version
The repository is not archived, the last push was on October 30, 2026, and the release history is regular. Optuna 4.7.0 shipped on January 19, 2026, 4.8.0 on March 16, 4.9.0 on June 1, a v5.0.0-rc1 release candidate on August 3, and v5.0.0 on September 7, 2026. The pyproject.toml classifier marks the package as Development Status 5, Production/Stable, and the library is under active development on the master branch.
The major version bump is the part to plan for. The v5.0.0 release blog post on Medium and the GitHub release notes for v5.0.0-rc1 are where the maintainers explain what changed. If you have objective functions and study code written against 4.x, an unpinned pip install optuna in a fresh environment now resolves to the 5.x line. Pin optuna below 5 in existing projects until you have read those notes and rerun your own studies on the new version, rather than letting a rebuilt container move you across a major version in the middle of an experiment series where results need to be comparable.
The repository layout tells you where to look when something breaks after an upgrade: the library is in optuna/, the test suite in tests/, tutorial sources in tutorial/ and the Sphinx documentation in docs/. There is a SECURITY.md for vulnerability reports, a CONTRIBUTING.md for patches, and a CITATION.cff for anyone citing Optuna in academic work. LICENSE_THIRD_PARTY sits next to the MIT LICENSE file for bundled third-party code notices.
Rustuna is faster for cheap objectives but does not yet cover Optuna's API
The same team released Rustuna v0.1.0 alongside Optuna v5 on September 7, 2026. Rustuna is an implementation of Optuna written in Rust that keeps the API Optuna users already know and rewrites the parts that hurt at scale: sampling speed and memory efficiency. It supports TPE, MOTPE, NSGA-II and CMA-ES samplers, and the project says it finishes the same study several times to several hundred times faster for cheap objective functions.
That qualifier matters. The speedup is stated for cheap objectives, where sampler overhead is a large share of each trial. When each trial trains a large model, the objective dominates run time and a faster sampler changes far less. Rustuna's storage is designed to be memory-efficient and can discard unnecessary trial history so that memory use and runtime do not grow with the trial count. It has no Python runtime dependencies by default, which the maintainers tie to much faster imports and less exposure to supply chain attacks.
The limits are stated plainly. Rustuna is experimental. Compared with Optuna it still lacks some features and APIs, it has not been optimized enough to beat Optuna for every use case, and it has not reached Optuna's maturity, so bugs and rough edges remain. For a reader, Rustuna is a candidate only when you run very large numbers of fast trials and have hit sampling or memory limits in Optuna itself. Before switching, confirm that every sampler, pruner and helper your code calls exists in Rustuna; anything outside the four listed samplers needs checking in the optuna/rustuna repository first.
Optuna Dashboard is a separate package with its own install
Optuna Dashboard lives in its own repository, optuna/optuna-dashboard, and installs from pip under the name optuna-dashboard. It is a real-time web dashboard for Optuna that shows the optimization history, hyperparameter importance and other views as graphs and tables. Its pitch is that you do not need to write a Python script to call Optuna's visualization functions in order to see how a study is going. The maintainers invite feature requests and bug reports on that repository.
This split has a practical consequence. Neither the dashboard nor the plotting stack is included by pip install optuna. You choose between two paths: the visualization functions under optuna/visualization, which need plotly in your environment and code that calls them, or the dashboard, which is one more package to install, run and keep updated next to the library. For a single analyst in a notebook, the plotting functions keep everything in one process. For a group watching a long study while it is still running, the real-time view is the reason to add the dashboard.
If your team expects a web interface out of the box, plan for it as a second component with its own issue tracker rather than a feature of the core package. Bugs in the dashboard's charts get reported to optuna/optuna-dashboard, not to optuna/optuna.
Editorial conclusion
Optuna fits Python 3.10+ teams who want conditional search spaces written as ordinary Python and a library with a steady release history; it does not fit projects stuck on older interpreters or teams that need the full search space declared before any trial runs. Before adopting it, pin a major version because of the v5.0.0 jump, add plotly or cmaes yourself if you need visualization or the CMA-ES sampler, and treat Rustuna as experimental until every API you call exists there.
Frequently asked questions
What is Optuna used for?
Optuna is an automatic hyperparameter optimization framework designed for machine learning. You write an objective function, and a study runs it across many trials to find the best hyperparameter values.
How do I install Optuna?
Run pip install optuna to install from PyPI, or conda install -c conda-forge optuna to install from conda-forge. Optuna supports Python 3.10 or newer.
How to install Optuna in Anaconda?
Use the conda-forge channel with conda install -c conda-forge optuna. The environment needs Python 3.10 or newer.
How to use Optuna for hyperparameter tuning?
Write an objective function that takes a trial and calls suggest methods such as suggest_float, suggest_int and suggest_categorical to get hyperparameter values, then trains and scores your model. A study runs that function for a number of trials, for example n_trials=100.
How to use Optuna Dashboard?
Install the separate optuna-dashboard package with pip. It is a real-time web dashboard that shows optimization history and hyperparameter importance in graphs and tables without writing a script to call Optuna's visualization functions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/optuna-optuna)Star history chart for your README
[](https://hysenlabs.com/projects/optuna-optuna)Was this useful?