PyTensor ships one Cython extension, caps numba at 0.67.0, and tags releases rel-3.3.3
PyTensor allows you to define, optimize, and efficiently evaluate mathematical expressions involving multi-dimensional arrays.
At a glance
- What is it?
- The compiler behind PyMC, three generations forked from Theano through Aesara, building a static graph you can still edit in place. The packaging tells you more about its constraints than the feature list does.
- Who is it for?
- PyTensor is a good fit if you need a graph you can rewrite after building it, which is the one capability it claims over the two frameworks it names, and if you want the same source to compile through C, JAX or Numba. Two things to check before you depend on it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
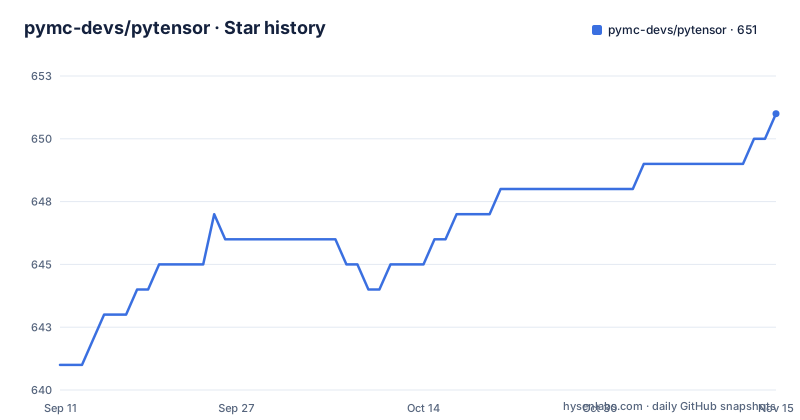
- pymc-devs/pytensor651 ★ · +10
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| pymc-devs/pytensor | 641 | 651 |
10 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Release tags are rel-3.3.3, and the version comes out of git
Three release tags are visible and none of them follows the convention tooling expects: `rel-3.3.1`, `rel-3.3.2` and `rel-3.3.3`. A `rel-` prefix, and no `v`.
The version number is not written in the package metadata at all. It is declared dynamic, and the build resolves it through versioneer, which is pinned to an exact version in the build requirements and called from `setup.py` to produce both the version string and the setuptools command classes.
So the number in a PyTensor install comes from the tag it was built from. That is a good design for a project that wants reproducible development installs, and it puts the naming convention on the critical path: anything that parses tags, anything that sorts releases, and any release automation written against a `v` prefix has to be told about `rel-`.
The timing is worth noting too. The newest release, `rel-3.3.3`, is stamped one second after the last push to the default branch, which means the tag is on the head commit rather than on a prepared release commit.
The cadence between the three is eight days and then seventeen, which is normal for a library with an active user base.
Three advertised backends and exactly one hand-written extension
The feature list says the transpilation framework compiles through C, JAX and Numba. The build configuration defines one extension module.
`setup.py` constructs a single `Extension` named `pytensor.scan.scan_perform`, compiled from `pytensor/scan/scan_perform.pyx` with the NumPy include directory added. That is the whole compiled surface of the package.
So the C backend is one Cython file covering the scan primitive, and the JAX and Numba paths are graph transformations rather than compiled extensions. That is a coherent design, since a transpiler emits code for another compiler rather than linking its own, but the two numbers are easy to conflate when reading the feature list.
There is a second branch in the same file that is more interesting. It checks an environment variable, and when it is set to 1 the extension list is left empty, which the comment explains as building a universal wheel that must be pure Python for Pyodide, the browser runtime.
The consequence is that the same source produces two different artefacts, and which one you get depends on an environment variable at build time rather than on a platform tag or a wheel name. If you are installing somewhere unusual, it is worth confirming whether you received the accelerated wheel or the pure-Python one.
numba has a floor and a ceiling, and everything else floats
There are five runtime dependencies, and only one of them is pinned on both sides.
setuptools at 59.0.0 or newer, numpy at 2.0 or newer, and filelock at 3.15 or newer all have a floor and no ceiling. scipy is bounded by a major version, from 1 up to but not including 2. numba is bounded from 0.58 up to and including 0.67.0.
That last one is the constraint to be aware of. A nine-minor-version window with a hard upper bound means numba cannot float forward without a PyTensor release, so a numba upgrade is a coordinated event rather than something a resolver can do for you. It also means the two numeric libraries behave differently on the same manifest: numpy can move to any 3.x, while numba stops.
The build requirements are looser still. Cython is unpinned, NumPy has a floor of 2.0, and versioneer is pinned to exactly 0.29.
Cython being unpinned in the build requirements is the sharpest edge here, since Cython's compiler output changes between releases and a build environment that resolves a different Cython than the one you tested is a different artefact.
One more note: setuptools appears in the runtime dependency list rather than only in the build requirements, which is unusual and reflects the project actually importing it at runtime.
The classifier says mature and the free-threading classifier says unstable
The package metadata declares its development status as mature, which is a strong claim for a library whose most recent release was cut this week.
Two classifiers sit next to each other and pull in opposite directions. One marks the project as mature, and the other declares free-threaded Python support as unstable, at version one of that classifier's scale.
The Python version range is `>=3.12,<3.15`, and the classifiers list 3.12, 3.13 and 3.14 individually. So the newest Python the project will install on is the newest one it claims, and the next minor is excluded by an upper bound rather than simply untested.
Intended audiences are declared three times over: education, science and research, and developers. Topic classifiers cover code generators, compilers and scientific and engineering mathematics.
Operating systems are Windows, POSIX, Unix and macOS, which is a complete list for a compiled scientific package with a Cython extension and no platform wheels declared in the visible configuration.
That is where the separate environment file for Apple silicon comes in: the repository carries both a general conda environment file and one named for macOS on arm64, which is what a project with compiled extensions and a cross-compiled toolchain usually needs.
Two homepages and two descriptions for the same package
The project has two of each, and they do not match.
For the homepage, the repository metadata points at the Read the Docs site while the package metadata points at the GitHub repository. One is where a reader starts and one is where the source lives, and only one of them is recorded in the file a package manager reads.
For the description, the readme calls it a Python library that lets one define, optimize and efficiently evaluate mathematical expressions involving multi-dimensional arrays. The package metadata calls it an optimizing compiler for evaluating mathematical expressions on CPUs and GPUs.
The second is shorter and says more, since a compiler is what distinguishes it from an array library. The first is the more accurate description of the user-facing API.
Both descriptions are correct and neither is wrong, which is exactly the problem: a search index and a package listing will show two different summaries for the same artefact.
The licence has a similar shape. The package metadata declares BSD-3-Clause and names a licence file, and the repository itself records no identifiable licence.
Twenty-two top-level entries, an RST readme, and a conftest at the root
The root of the repository is unusually broad for a single Python package.
Twenty-two entries. Two of them are build configuration, with `pyproject.toml` and `setup.py` side by side, and `setup.py` reads the package name back out of the parsed configuration rather than declaring it. Three are environment and packaging files: `environment.yml`, a second one for macOS on arm64, and `MANIFEST.in`.
There is a `conftest.py` at the repository root rather than inside the test directory, which is what makes fixtures available to the whole tree in one place.
Documentation is split between a `doc/` directory, a Read the Docs configuration, and a readme written in reStructuredText with the badge row built from substitution definitions. That last detail is why the readme looks odd when flattened: the project name appears as a placeholder that gets substituted at render time.
Three governance and community files sit at the top level: a code of conduct, a contributing guide, and a governance document. There is also an agent instruction file alongside a pre-commit configuration and a codecov configuration.
A repository that advertises a pure-Python, hackable codebase keeps a lot of machinery in its root, and the difference between the pitch and the tree is worth holding in mind.
The graph is static, and being able to edit it afterwards is the point
The design decision the project states plainly is that it keeps a static graph, and that the graph can be modified in place. It names PyTorch and TensorFlow as the contrast, on the grounds that they do not.
That is the capability the whole library is organised around, and the getting-started example is built to show it rather than to show arithmetic. You declare two symbolic scalars, build an expression from them, and turn it into a callable. Then you differentiate the same expression symbolically and compile that too.
import pytensor
from pytensor import tensor as pt

# Declare two symbolic floating-point scalars
a = pt.dscalar("a")
b = pt.dscalar("b")

# Create a simple example expression
c = a + b

# Convert the expression into a callable object that takes `(a, b)`
# values as input and computes the value of `c`.
f_c = pytensor.function([a, b], c)

assert f_c(1.5, 2.5) == 4.0

# Compute the gradient of the example expression with respect to `a`
dc = pytensor.grad(c, a)

f_dc = pytensor.function([a, b], dc)

assert f_dc(1.5, 2.5) == 1.0
Then the graph is printed twice, before and after compilation, and the two prints are the argument. The first shows a division node and a generic dot node. The second shows a constant one and a BLAS call, with an allocation and a shape query inlined around it.
So compilation rewrites `a/a` into `1` and the dot product into a BLAS routine. The graph is not something you inspect once; it is something you build, let the optimiser rewrite, and read again.
This is also where the project's lineage shows. PyTensor is a fork of Aesara, which is a fork of Theano, and it remains the computational backend for PyMC.
Editorial conclusion
PyTensor is a good fit if you need a graph you can rewrite after building it, which is the one capability it claims over the two frameworks it names, and if you want the same source to compile through C, JAX or Numba. Two things to check before you depend on it. The runtime dependency set is pinned harder than it looks, with numba carrying both a floor and a ceiling, so upgrades are your problem rather than the package manager's. And the build falls back to a pure-Python wheel whenever it detects Pyodide, so check which artefact you actually installed if you are somewhere unusual.
Frequently asked questions
what is pytensor
A Python library for defining, optimizing and efficiently evaluating mathematical expressions over multi-dimensional arrays, and the computational backend for PyMC. It keeps a static graph that can be modified in place for further optimization, and compiles through C, JAX and Numba.
pytensor vs theano
PyTensor is a fork of Aesara, and Aesara is a fork of Theano, so it is two generations removed. The documentation does not enumerate what changed at each step; it states the lineage and points at the tutorials for behaviour.
pytensor vs numpy
NumPy evaluates arrays; PyTensor compiles a graph of symbolic operations into a callable. Constructing a function also optimizes the graph, rewriting a division of a symbol by itself into a constant one and a dot product into a BLAS call.
pytensor vs tensorflow
The project's stated position is the static graph. PyTensor says it maintains a graph which can be modified in place to allow advanced optimizations, and names PyTorch and TensorFlow as the contrast, without documenting that comparison in detail.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pymc-devs-pytensor)Star history chart for your README
[](https://hysenlabs.com/projects/pymc-devs-pytensor)Was this useful?