python-escpos released 3.1 in December 2023, and the branch has moved on since
Python library to manipulate ESC/POS printers. python-escpos - Python library to manipulate ESC/POS Printers Description =========== ..
At a glance
- What is it?
- python-escpos is a small, focused library for driving ESC/POS receipt printers over USB, network and serial, with the awkward part of the protocol handled by a shared capability database rather than by guesswork. Its version number comes from git tags, so the gap between the last release and the last commit is not cosmetic: it is the difference between installing 3.1 and installing a development build.
- Who is it for?
- python-escpos fits anyone writing a receipt, label or ticket printer script and who would rather not implement ESC/POS by hand, especially if you can supply a profile for your printer.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 22, 2026, and from our analysis. They are not legal advice.
Star history
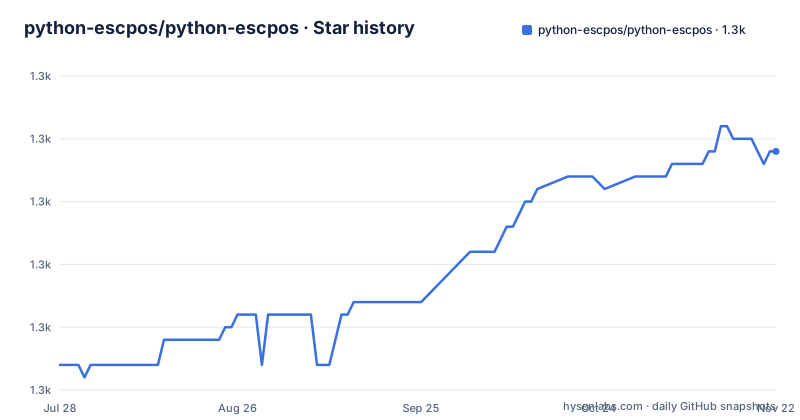
- python-escpos/python-escpos1,329 ★ · +17
| Repository | 2026-07-28 | 2026-11-22 |
|---|---|---|
| python-escpos/python-escpos | 1.3k | 1.3k |
17 Stars in the last 117 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The version number is a git tag, which makes the release gap visible
The release list has three entries: a 3.0 alpha in May 2023, 3.0 in November 2023, and 3.1 in December 2023. The repository's last push is dated 2026-09-21.
That gap only matters because of how the version is produced. The packaging script does not contain a number. It asks the version-control system for one, writes the result into a generated module inside the package, and ships a template for that file whose own comment says it is generated and should not be tracked.
Two consequences follow. A tagged install gets 3.1. An editable install from a checkout after that tag gets a development version derived from the distance to the nearest tag, which is the honest description of code that has had two and a half years of commits without a release. And there is no way to ask the library which release it is and get an answer that distinguishes those two cases without reading the generated file.
The packaging script also inserts the source directory into the import path before it runs, so it can import its own package while building it. That is a small workaround, and it is the reason the file exists at all.
The printer profile is the part that decides whether it works
The command set is the same family across ESC/POS printers, but not every printer implements every command. The library's answer is a profile: a description of what a specific model can do, supplied by the caller.
The documentation is emphatic about it. There is a note saying it is highly recommended to include a matching profile so the library knows the printer's capabilities, and every example on the page passes one, naming the same model.
The data behind those profiles does not live in this repository. It comes from a separate capability database project, which is also used by a PHP implementation of the same protocol. So the model-by-model knowledge is shared across two languages rather than duplicated, and the repository holds a directory of that data alongside the code.
This is the design decision that makes a thin library viable. Without a profile you are guessing at a device's limits; with one, the library can avoid sending a command that would leave a printer in a bad state. The cost is that you have to know which profile matches, and the mapping from model number to profile is not something the page enumerates.
Three transports, three constructor shapes
The page shows one complete example per transport, and each one is short enough to read as the whole API.
USB takes a device identifier as two hexadecimal numbers and a profile. Serial takes a device file and the line settings spelled out: baud rate, byte size, parity, stop bits, a timeout, and a flag for hardware flow control. Network takes an address.
The method calls are identical across all three. Text, then either an image, a barcode or a QR code, then a paper cut. The cut is the last call in every example, which is the correct order and also the reason a receipt printer example reads the way it does.
The dependencies follow the transports rather than the features. A USB library for USB printers, a serial library for serial printers, an imaging library for images, a QR generator, and a barcode generator. So a network-only user still installs the USB stack, which is the usual shape for a library that grew by accretion rather than by extras.
The feature list is deliberately narrow, and code pages show the pain
Beyond transport, the library covers text with alignment and justification, fonts changeable by size, type and weight, images, barcodes, QR codes, and the hardware bits: paper cutting, control characters and a printer reset.
That is the whole surface, and it is a sensible boundary. Each of those maps to a command group in the ESC/POS specification, and the interesting work is in the details rather than the breadth.
The examples directory shows what the details are. There are files for barcodes, block text, font variations, graphics, QR codes, software-generated barcodes and columns, plus a receipt, a weather report, and a file whose name is a clue about the hardest part: code page tables.
Code pages are the traditional trap in this protocol, because a receipt printer has a set of character tables and the wrong one produces readable-looking garbage. Having an example dedicated to the tables suggests the library treats it as something you inspect rather than something it hides.
Several examples also ship a result image next to the script, so you can see what the output looked like without running hardware.
The test configuration names a directory that is not in the tree
The pytest configuration carries an oddity worth reading twice. The test paths are given as four entries: the test directory, the source directory, the source package directory, and the package directory at the top level. The repository has a source directory and a test directory, and it does not have a top-level package directory, because the package lives under the source tree.
So one of the four paths is a leftover from a layout that no longer exists. Pytest tolerates it because a missing path in the list is simply nothing to collect.
The rest of the configuration is more careful. Tests run with doctest collection enabled, so the docstring examples in the modules are executed as tests. Coverage is measured on the package and written as XML, and a coverage service configuration sits at the repository root, which is what receives that file.
The matrix is wide. A tox environment list covers Python 3.10 through 3.14 and adds separate environments for the documentation, for flake8 with a docstring plugin, and for mypy. The test dependencies include a property-based testing library, a mocking library, a console-script testing library, and a JSON conversion helper.
Environment variables carry the test cache and the ghosts of older CI
The tox configuration passes a list of environment variables through to the test run, and the list is a history of the project's tooling.
Two of them are specific to this library: one naming a directory for a pickled capabilities cache, and one naming a capabilities data file. So a test run can read capabilities from a cached pickle or from an explicit file rather than recomputing or re-downloading them. That is what you need when the data is large or the network is not available.
The rest are continuous integration variables: a generic one, a code coverage one, and then Travis and AppVeyor variables with their star-suffixed companions. Both of those services predate GitHub Actions as a default for open source projects, and a repository that still passes their variables through is one that has migrated its hosting at least once without pruning what the tests read.
It is harmless, and it is also a precise record of which CI systems this suite was written against.
The docs build fails on a spelling mistake
The documentation environment builds with Sphinx in two passes, and both pass a flag that turns warnings into errors. The first builds HTML. The second builds a spelling target, using a spelling extension for Sphinx.
That combination means the documentation job fails on a typo, not only on a broken reference. For a project whose prose is mostly short descriptions of printer commands, that is a strict setting, and it explains why the readme's language is plain and consistent.
The documentation environment's dependency list is also larger than you would expect for a library page set: a theme, an argparse extension for documenting command line options, a data templating extension, an extension for type hints in generated API docs, a CUPS binding, and the spelling extension. The last one is there to run the second pass.
Generated API documentation with type hints, an option parser documented automatically, and a spellchecker are three separate quality gates in one environment. It is more machinery than the library itself needs, and it is the part of the project most likely to need updating when a new Sphinx version lands.
Vendors are named throughout, and none of them endorses this
Every example names a specific printer model from a specific manufacturer, and the USB example carries that manufacturer's vendor and product identifiers as hexadecimal numbers. The capability profiles are keyed by the same model names.
The repository states the position plainly in its disclaimer: none of the vendors cited agree with or endorse any of the patterns or implementations, and their names are used only to maintain context.
That is the correct posture for a library whose entire surface is one manufacturer's command language. The protocol is theirs, the model numbers are theirs, and the identifiers in the USB example are the ones the operating system uses to find the device. Writing anything else would make the code less accurate, so naming them is the only workable option and the disclaimer covers the rest.
The repository also carries a contributors file, a licence file, a changelog, a mailing map for commit attribution, and an install file, which is the paperwork of a project that has been around long enough to have accumulated it.
Editorial conclusion
python-escpos fits anyone writing a receipt, label or ticket printer script and who would rather not implement ESC/POS by hand, especially if you can supply a profile for your printer. Verify four things first: which version you are actually installing, because the newest tag is from December 2023 while the branch has moved on and a checkout install reports a development version; that you pass a matching profile, since the page calls it highly recommended and every example does; which transport your printer speaks, because each constructor and its dependency are separate; and whether you need the optional printing backends, since the type-checking configuration names CUPS and Windows printing alongside the USB and serial paths. MIT licensed, default branch master, last push dated 2026-09-21.
Frequently asked questions
What is python-escpos?
It is an MIT licensed Python library for driving ESC/POS receipt printers, the command language defined by Epson. It covers text with alignment and justification, fonts by size, type and weight, images, barcodes, QR codes, paper cutting, control characters and reset, over USB, network and serial connections.
Why should I pass a profile to python-escpos?
Because supported commands differ from printer to printer, and a matching profile tells the library what the hardware can do. The page calls including one highly recommended, and every example passes a profile naming a model. The capability data itself comes from the escpos-printer-db project, which the PHP implementation also uses.
How do I install python-escpos?
The repository's requirements file contains only an editable install of the project itself, and the packaging script derives the version from git tags, writing a generated module into the package. The package ships a capabilities data file and registers a console script named python-escpos pointing at the command line entry point.
Which printer types does python-escpos support?
USB, network and serial, each with its own constructor shape: device identifiers for USB, an address for network, and a device file plus baud rate, byte size, parity, stop bits, timeout and flow control for serial. The dependencies follow the transports, including pyusb, pyserial, Pillow, qrcode and python-barcode.
How is python-escpos tested?
Pytest runs with doctest collection enabled and coverage measured on the package, written as XML for a coverage service configured at the repository root. A tox matrix covers Python 3.10 through 3.14 with separate environments for the documentation, flake8 with a docstring plugin, and mypy, and the test dependencies include hypothesis, pytest-mock and scripttest.
Is there a release after python-escpos version 3.1?
The newest release tag is 3.1 from 2023-12-17, preceded by 3.0 in November 2023 and a 3.0 alpha in May 2023, while the repository's last push is dated 2026-09-21. Because the version is derived from git tags at build time, installing from the branch gives a development version rather than 3.1.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/python-escpos-python-escpos)Star history chart for your README
[](https://hysenlabs.com/projects/python-escpos-python-escpos)Was this useful?