TorchVision locks each release to one torch version, and its build reads a dozen environment variables
Datasets, Transforms and Models specific to Computer Vision
At a glance
- What is it?
- TorchVision is the vision sidecar to PyTorch, carrying datasets, model architectures and image transformations, released in lockstep with a single torch version and shipped as a compiled extension whose contents are decided by environment variables at build time. Two things to check before you pin anything: the compatibility table and the published releases are not the same set of numbers, and the license of the weights you load is not the license of the code.
- Who is it for?
- Use TorchVision when you want the reference datasets, architectures and transforms that match your torch release exactly, and check three cells in the compatibility table before touching your environment: the torch number, the torchvision number, and the Python ceiling, since the ceiling moves between rows.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
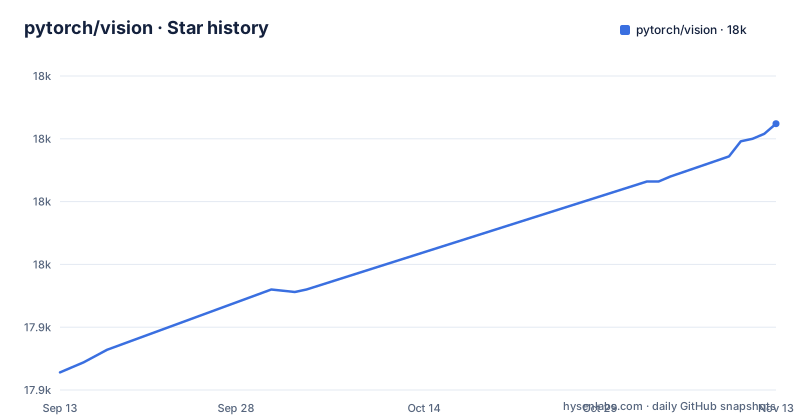
- pytorch/vision18,006 ★ · +99
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| pytorch/vision | 17.9k | 18k |
99 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The version table stops at torch 2.13 while the tags are already at 0.29
The compatibility table and the release list do not line up. The newest row of the table pairs torch 2.13 with torchvision 0.28 on Python from 3.10 to 3.14, and the rows below it repeat that same Python range for torch 2.12 with 0.27, 2.11 with 0.26, and 2.10 with 0.25. The published tags go further: v0.29.2 on 28 October 2026, v0.29.1 on 30 September 2026, and v0.29.0 on 2 September 2026 under the title TorchVision 0.29: ABI stability. A reader who installs the newest tag and then hunts for its row in the table finds nothing there. The escape hatch is the first row, which pairs main and nightly torch with main and nightly torchvision, and it is also the only line that does not name a fixed release number. Treat the table as a description of how the coupling works rather than as a full index of what has shipped, and check the release list for the row that is missing.
One torch release per torchvision release makes an upgrade a two-cell decision
The pairing is strict and one to one: 2.13 with 0.28, 2.12 with 0.27, 2.11 with 0.26, 2.10 with 0.25, 2.9 with 0.24, 2.8 with 0.23, 2.7 with 0.22, 2.6 with 0.21, 2.5 with 0.20. The Python column moves too, climbing with the torch number: 2.8 and 2.7 want Python from 3.9 to 3.13, 2.6 and 2.5 want 3.9 to 3.12, 2.4 and 2.3 want 3.8 to 3.12, and 2.2, 2.1 and 2.0 want 3.8 to 3.11. Older rows show how far the floor has moved: torch 1.13 pairs with 0.14 on Python from 3.7.2 to 3.10, and torch 1.4 pairs with 0.5 on Python exactly 2.7, or anything from 3.5 to 3.8. The consequence for a reader is that no upgrade is a single decision. The interpreter ceiling constrains the torch number, and the torch number constrains the torchvision tag, so a runtime bump can be blocked by a Python version that has nothing to do with the framework.
The install is a compiled extension, and the README hands the build off
There is no pip command in the project documentation, and the reason sits in the build files. setup.py imports BuildExtension, CppExtension, CUDA_HOME, CUDAExtension and ROCM_HOME from torch.utils.cpp_extension, the C++ sources live under torchvision/csrc, and the build system requires setuptools, torch and wheel. The repository root carries CMakeLists.txt, a cmake directory and a .clang-format file, which is the layout of a project that compiles its own extension rather than shipping pure Python. What the documentation does is point you out: stable torch and torchvision binaries come from the official install instructions on the pytorch.org site, and source builds are described on the contributing page. So there are two procedures with two different owners, and the short document is responsible for only one of them. If you are not sure which you need, the answer is that anything requiring a compiler is the second one.
Eight environment variables decide which codecs and backends get compiled in
The build reads its configuration from the environment, and every switch is a string compared against 1:
FORCE_CUDA = os.getenv("FORCE_CUDA", "0") == "1"
FORCE_MPS = os.getenv("FORCE_MPS", "0") == "1"
DEBUG = os.getenv("DEBUG", "0") == "1"
USE_PNG = os.getenv("TORCHVISION_USE_PNG", "1") == "1"
USE_JPEG = os.getenv("TORCHVISION_USE_JPEG", "1") == "1"
USE_WEBP = os.getenv("TORCHVISION_USE_WEBP", "1") == "1"
USE_NVJPEG = os.getenv("TORCHVISION_USE_NVJPEG", "1") == "1"
NVCC_FLAGS = os.getenv("NVCC_FLAGS", None)
The defaults decide more than the names do. Each USE_ switch starts on, so PNG, JPEG, WebP and NVJPEG support are all compiled unless the matching variable is set to something other than 1, and FORCE_CUDA, FORCE_MPS and DEBUG all start off. NVCC_FLAGS is the only one read without a comparison, which makes it a free-form value rather than a flag. The build then prints a header reading Torchvision build configuration: and echoes every resolved setting, so the result is visible in the build log instead of hidden. The practical consequence is that a missing codec is fixed by an environment variable set before the build, not by a package installed afterwards.
CUDA sources are compiled only when torch sees a device, unless you force it
Whether the accelerator path is built at all comes down to two lines:
IS_ROCM = (torch.version.hip is not None) and (ROCM_HOME is not None)
BUILD_CUDA_SOURCES = (torch.cuda.is_available() and ((CUDA_HOME is not None) or IS_ROCM)) or FORCE_CUDA
So CUDA sources are compiled when torch reports an available device and either CUDA_HOME is set or the ROCm test passes, and they are skipped otherwise, with FORCE_CUDA as the override. ROCm is detected separately and needs two things at once, that torch reports a hip version and that ROCM_HOME is present, so a machine with the hardware but a torch build without a hip version falls back to the branch without accelerator sources. TORCHVISION_PACKAGE_NAME changes the name the package is built under. Header and library locations are overridable too, and both are split on os.pathsep so several directories can be listed. The consequence is that a build machine is configured as much in its shell profile as in its source tree, and a missing accelerator produces a smaller binary rather than an error.
Datasets are downloaded for you and no license check happens
The disclaimer is unusually direct. The library is described as a utility that downloads and prepares public datasets, and the project states that it does not host or distribute them, does not vouch for their quality or fairness, and does not claim that you have a license to use them. Deciding whether permission exists is left entirely to you. That changes how the package should be used in a pipeline. A call that reaches for a dataset can begin a download the first time it runs, and the terms that come with the data are the dataset's terms, not the BSD-3-Clause license that covers this code. Owners have a channel for both directions: they can open a GitHub issue to correct a description or citation, or to have their dataset removed from the library entirely. Pre-trained weights carry the same warning, with one named exception: SWAG models are released under CC-BY-NC 4.0, so those weights are not available for commercial use.
Only torch tensors and PIL images are supported backends
The list of image backends is short enough to read in one breath: torch tensors, and PIL images through either Pillow or Pillow-SIMD, the latter described as a much faster drop-in replacement for Pillow with SIMD. That is the entire list, and the documentation for the details is the transforms page on the pytorch.org site rather than the short README. The consequence is a boundary condition. If your images arrive in some third representation, converting them into a tensor or a PIL image is your code, not the library's, which means an extra copy in memory at that point and a place where color ordering and data type mismatches can surface after the fact. A pipeline whose front end already produces one of the two supported forms pays nothing; a pipeline that does not pays for the conversion on every sample, and Pillow-SIMD only speeds up the PIL side of that path.
Contributing rules sit in two files, and the citation entry is frozen at 2016
The root of the tree is where the maintenance arrangement shows. Alongside the code there is CONTRIBUTING.md, a separate CONTRIBUTING_MODELS.md for adding architectures, a maintainer_guide.md, CODE_OF_CONDUCT.md, mypy.ini, pytest.ini, a .pre-commit-config.yaml, and the directories benchmarks, references, release, scripts, test, gallery, docs and packaging, with examples split into examples/python and examples/cpp. Style settings live in pyproject.toml, where black runs with a line length of 120 and a target version of py38, and ufmt is configured to skip the gallery directory. A py38 target sitting next to a package that supports Python from 3.10 upward is the kind of drift a reader can see without being able to explain. The citation entry is a software record with year 2016 and publisher GitHub, so it does not move as releases move, and CITATION.cff sits in the root as the machine-readable counterpart.
Editorial conclusion
Use TorchVision when you want the reference datasets, architectures and transforms that match your torch release exactly, and check three cells in the compatibility table before touching your environment: the torch number, the torchvision number, and the Python ceiling, since the ceiling moves between rows. Do not reach for pre-trained weights such as SWAG in anything commercial, because those are released under CC-BY-NC 4.0, and do not treat the BSD-3-Clause code license as covering the datasets. If you build from source, record your FORCE_CUDA, USE_PNG, USE_JPEG, USE_WEBP and USE_NVJPEG settings, because a skipped codec only shows up as a missing feature later.
Frequently asked questions
How do I install torchvision?
The project sends you to the official instructions at pytorch.org/get-started/locally for stable binaries, and matches the pair yourself: torch 2.13 with torchvision 0.28, or 2.12 with 0.27, on Python from 3.10 to 3.14. Building from source is a different path, covered on the contributing page, and needs a compiler.
Is 2.75 vision bad?
This repository has nothing to do with eyesight or eye charts. TorchVision is a set of computer vision datasets, model architectures and image transformations, and the supported image backends are torch tensors and PIL images.
How do I set up Vision Pro?
Nothing in the pytorch/vision repository concerns Vision Pro hardware. The package holds datasets, model architectures and common image transformations, and the API documentation is on the pytorch website rather than in the repository.
What does vision mean in this library?
In this repository the word is the name of the package. The description is datasets, transforms and models specific to computer vision, and the image backends it supports are torch tensors plus Pillow, with Pillow-SIMD offered as a faster drop-in replacement.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pytorch-vision)Star history chart for your README
[](https://hysenlabs.com/projects/pytorch-vision)Was this useful?