Triton Inference Server: what the container, the branch pin and the model repository actually decide
The Triton Inference Server provides an optimized cloud and edge inferencing solution.
At a glance
- What is it?
- NVIDIA's serving engine splits its work across a container, per-framework backend repos and a versioned release branch, and the three-step quickstart only works if you follow that split. Here is what the repository structure means for the models you can load, the requests you can batch and the upgrades you have to plan.
- Who is it for?
- Adopt Triton Inference Server when you have to serve more than one framework behind one endpoint and you can commit to the monthly container cadence that release 2.74.0 and the 26.10 tag represent. Do not adopt it if you need a model format whose backend is not in one of the linked backend repos, or if you cannot absorb a monthly upgrade.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
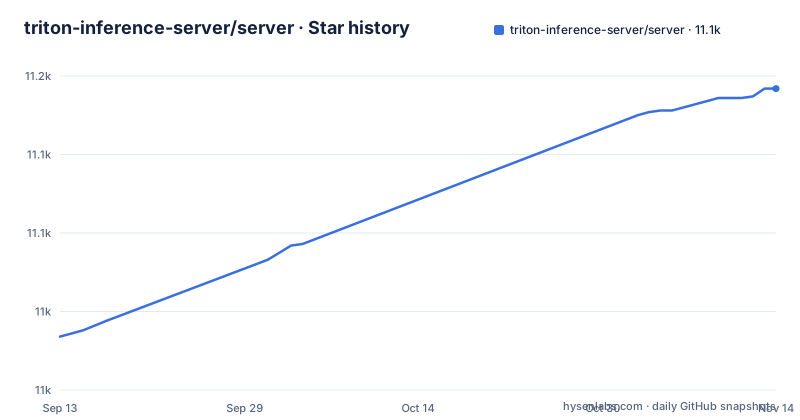
- triton-inference-server/server11,142 ★ · +158
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| triton-inference-server/server | 11k | 11.1k |
158 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The version you run is a container tag, not a git branch
The `main` branch carries a warning that it tracks under-development progress toward the next release, and the current release named there is 2.74.0, which corresponds to the 26.10 container release on NVIDIA GPU Cloud. The release history makes the cadence explicit: v2.74.0 shipped on 2026-11-02 against container 26.10, v2.73.0 on 2026-09-30 against 26.09, and v2.72.0 on 2026-08-31 against 26.08. One GitHub release maps to one container release, roughly every month. Two numbers therefore have to be kept in step in your own deployment, and the repository gives you no mechanism that does that for you. If your production image says `26.10-py3` while your build scripts pull `main`, the source you compiled and the binary you serve are not the same thing.
Explicit model loading hides every model until you name it
The launch command mounts a host directory at `/models`, points the server at it with `--model-repository=/models`, and then adds two flags that do the real work: `--model-control-mode explicit` and `--load-model densenet_onnx`.
# Step 1: Create the example model repository
git clone -b r26.10 https://github.com/triton-inference-server/server.git
cd server/docs/examples
./fetch_models.shdocker run --gpus=1 --rm --net=host -v ${PWD}/model_repository:/models nvcr.io/nvidia/tritonserver:26.10-py3 tritonserver --model-repository=/models --model-control-mode explicit --load-model densenet_onnxExplicit mode means the server loads what it is told to load, so a client that expects a model name the flags never mention gets nothing back. The consequence lands on the caller: every model that should answer traffic has to appear in the launch flags, and adding one later means naming it explicitly rather than dropping a directory into the repository and waiting. Anyone who assumes that putting a model folder under the mount point is enough will debug their client code for a long time before looking at the flags.
Backends live in their own repos, so this repo alone decides nothing about formats
The feature list covers TensorRT, PyTorch, ONNX, OpenVINO, Python and RAPIDS FIL, and the top-level tree of this repository contains `src/`, `python/`, `docker/`, `deploy/`, `docs/`, `qa/`, `tools/` and `enhancements/`, but none of the backends themselves. The list of available backends lives behind the Backend API link and in the separate fil_backend repository, and Python-based backends have their own documentation. That split is fine for a container that bundles the backends, and misleading for anyone auditing what this repository can serve. Before promising a framework to a customer, check the backend repository and the container tag you plan to ship. The Backend API is the escape hatch: custom backends and pre- or post-processing steps are written against it, and a backend written in Python is a supported shape rather than a hack. The cost sits with you: you now own the Python process, its imports and its failure modes.
Batching has two mechanisms, and only one of them keeps state
Dynamic batching and sequence batching are separate features documented on separate pages, `docs/user_guide/batcher.md` and `docs/user_guide/architecture.md`, and the second one comes with implicit state management for stateful models. That is the single most consequential split in the serving path. A stateless model can sit in a dynamic batch queue and be answered in any order. A stateful model needs its correlation identifiers and its retained state to survive between requests, and the sequence batcher with implicit state management is the feature that carries that, which is also why a model of that kind cannot be treated as an interchangeable entry in the same repository. Concurrent model execution is a third, separate mechanism rather than an automatic result of the other two. The README names these mechanisms and links the user guide, so if your traffic is bursty you have to read the user guide before sizing a GPU.
Pipelines are ensembles and BLS, not one thing
Model pipelines come in two documented shapes: Ensembling, which is a server-side model composed of other models, and Business Logic Scripting in the Python backend, where the orchestration lives in code you write. That gives you two very different places to look when a request returns a wrong answer. With an ensemble the topology is data inside the repository; with BLS it is Python in your own process, and a bug there is not something a Triton flag will tell you about. The README also states that Triton delivers optimized performance for real time, batched, ensembles and audio/video streaming query types, which is a claim about workload shapes and not a number you can check from here.
Three client surfaces, three debugging stories
Inference goes over HTTP/REST and GRPC, both based on the community developed KServe protocol, and there are also a C API and a Java API that let Triton link directly into your application for edge and other in-process use cases. Metrics are exposed for GPU utilization, server throughput and server latency. This repository is written in C++ and Python, CMake and `build.py` sit at the top level, `Dockerfile.sdk` is present for the SDK side, and `Dockerfile.QA` for the test images. Anyone building from source is taking on that toolchain rather than pulling a published image.
NVIDIA hardware is the target list, and licensing has two PDFs attached
Supported inference targets are NVIDIA GPUs, x86 and ARM CPU, and AWS Inferentia, and the QuickStart guide carries an example of launching Triton on CPU-only systems. That list is short and specific. A team that needs another accelerator family should check the documentation first, and a team whose real target is Inferentia should not assume parity with a GPU deployment. Licensing is BSD-3-Clause for the source, and the tree also carries `NVIDIA_Deep_Learning_Container_License.pdf` and `Triton-CCLA-v1.pdf`, plus `SECURITY.md` and `CITATION.cff`. Read the container license before shipping anything, since the code license and the terms covering the distributed container are separate documents; the file name Triton-CCLA-v1.pdf points to a contributor agreement rather than a usage license.
What the repository leaves to you
Several things are left to you. Releases map to container tags, so going back after a bad release is a decision about your image tags and configuration. The README points at the QuickStart for the CPU-only launch, so any sizing argument has to be made with your own models. The repository is also honest about where to go next, with tutorials, NVIDIA LaunchPad labs for hands-on practice, end-to-end examples for ResNet, BERT and DLRM, and the NVIDIA Developer Zone for further documentation.
Editorial conclusion
Adopt Triton Inference Server when you have to serve more than one framework behind one endpoint and you can commit to the monthly container cadence that release 2.74.0 and the 26.10 tag represent. Do not adopt it if you need a model format whose backend is not in one of the linked backend repos, or if you cannot absorb a monthly upgrade. Before you commit, clone the r26.10 branch rather than main, run the three commands in the QuickStart on the hardware you plan to use, and read the user guide pages named in the README for the batching and ensemble behaviour you are counting on.
Frequently asked questions
How does Triton Inference Server serve a loaded model?
Triton serves models from several frameworks, including TensorRT, PyTorch, ONNX, OpenVINO, Python and RAPIDS FIL, and offers concurrent model execution plus two separate batching mechanisms. Clients reach it over HTTP/REST and GRPC, both based on the KServe protocol.
How do I install and start Triton Inference Server?
The recommended way to build and use Triton is with Docker images. Clone the release branch with `git clone -b r26.10`, create the example model repository, then run the container tritonserver with `--model-repository=/models --model-control-mode explicit --load-model densenet_onnx`.
Why does my Triton Inference Server instance not answer for a model I added?
With `--model-control-mode explicit` the server loads only the models named on the command line, here `--load-model densenet_onnx`. A model directory added under the mount point is not picked up until it is named.
What can I do with Triton Inference Server after it is running?
You can build pipelines with Ensembling or Business Logic Scripting, batch with the dynamic or sequence batcher, write custom backends in Python against the Backend API, and read metrics for GPU utilization, server throughput and server latency. A C API and a Java API also allow in-process use.
Official sources
Where this project is recommended
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Jensen is out. CUDA isn't. A Developer's Guide to Everything Nvidia Builtdev.to · Nov 13, 2026 · 7 points · 2 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/triton-inference-server-server)Star history chart for your README
[](https://hysenlabs.com/projects/triton-inference-server-server)Was this useful?