WeRSS: WeChat Official Accounts turned into RSS, one container at a time
A WeChat Official Account assistant that matches natural reading habits: converts official account articles to Markdown or PDF, does scheduled article updates, generates and exports RSS feeds, and supports Webhook/API/AI Agent integration with WeChat Official Accounts.
At a glance
- What is it?
- WeRSS is a FastAPI and Vue application that subscribes to WeChat Official Accounts, schedules collection jobs and republishes the articles as RSS feeds, Markdown, docx, pdf or json. Its install is a single docker run, and most of the sharp edges come from what the image bakes in rather than from what you configure.
- Who is it for?
- WeRSS fits a reader who follows a fixed set of WeChat accounts and wants them in an existing feed reader, and who is willing to keep a browser profile and an authorized session alive in a container. It does not fit a serverless deployment, since the image carries a browser, a profile directory and a scheduled job runner.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
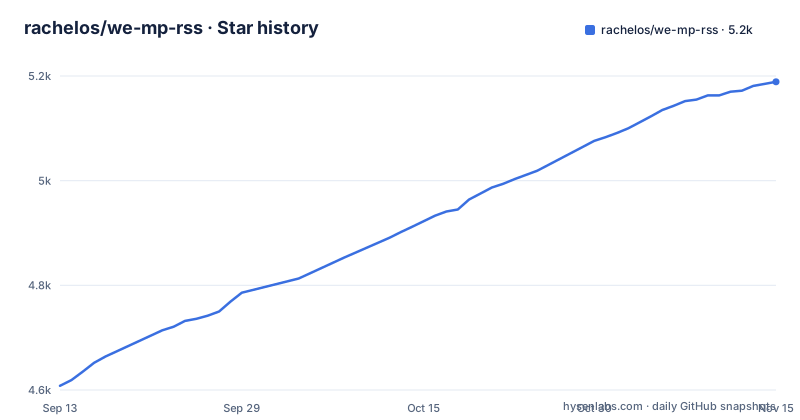
- rachelos/we-mp-rss5,189 ★ · +581
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| rachelos/we-mp-rss | 4.6k | 5.2k |
581 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One docker run is the whole install
There is no pip step in the documented quick start. The entire installation is a single container on port 8001 with one volume mounted:
docker run -d --name we-mp-rss -p 8001:8001 -v ./data:/app/data ghcr.io/rachelos/we-mp-rss:latestThen you open `http://<your-ip>:8001/` and authorize. The same command exists in two other forms, one for the official image at `rachelos/we-mp-rss:latest` and one pointing at `docker.1ms.run/rachelos/we-mp-rss:latest`, described as a proxy mirror for faster access in China.
Upgrading is four commands and no state migration, because the container is thrown away:
docker stop we-mp-rss
docker rm we-mp-rss
docker pull ghcr.io/rachelos/we-mp-rss:latest
The comment under that block is the catch: if you added other parameters, modify them accordingly. Nothing records your run flags, so every upgrade is a retyped command.
The data volume holds the browser profile
The one mount in that command, `./data` onto `/app/data`, carries more than article files. The Dockerfile puts the WeChat license at `/app/data/wx.lic` and the browser profile directory at `/app/data/weread-chrome-profile`, and the Playwright browser path at `/app/env/driver/_x86_64` sits outside it.
So the volume holds an authorized session and a browser profile, not a cache. Deleting `./data` throws away that license file and browser profile. On a host where that directory is a tmpfs, or in a compose file where the volume is recreated, you get a fresh login on every restart.
The volume also means the SQLite database, which defaults to `sqlite:///data/db.db` in the config table, travels with the same directory. Backing up one folder backs up the feeds, the subscriptions and the session.
The image bakes config.example.yaml as your config.yaml
One line in the Dockerfile explains a class of confusion. After copying the repository in, it runs `COPY config.example.yaml /app/config.yaml`, so the configuration a fresh container uses is a copy of the example file shipped with the code.
Nothing in the documented `docker run` mounts a configuration file, which means the config your container reads is the image's example unless you add a mount yourself. If you edit `config.yaml` expecting the container to see it, the edit needs to land at `/app/config.yaml` inside the container or be mounted over it.
The development path does the opposite and expects a local file: `cp config.example.yaml config.yaml` before starting the service. Two different flows use the same filename.
Filter rules are global by default and ordered by priority
Article cleanup is the part with a real interface, and it works in two scopes. A global rule applies to every official account when no specific account is selected, and an MP-specific rule targets one account. Rules carry a priority between 0 and 100, where a higher number is executed first, so ordering is explicit rather than dependent on creation time.
Six removal methods are available: remove elements by ID, by CSS class, by CSS selector, filter by attribute, remove content by regular expression, and strip common elements such as script, style and comments. Rules are created through the admin interface on the Filter Rules page, and the same functionality is exposed over HTTP with four endpoints:
GET /api/filter-rules
POST /api/filter-rules
PUT /api/filter-rules/{rule_id}
DELETE /api/filter-rules/{rule_id}
Note the `mp_id` field in the request body is written as the string `"[]"` for global rules, with an inline comment. That is not valid JSON, so the documented request cannot be pasted into a client as it stands.
Three browser drivers and two schedulers are pinned together
The dependency file is fully pinned, and two corners of it are worth reading before you install. The browser story is `playwright==1.55.0`, `playwright-stealth==2.0.0`, `selenium==4.27.1` and `webdriver-manager==4.0.2` at the same time, so three ways of driving a browser ship together. The Dockerfile sets `BROWSER_TYPE=webkit` as an environment variable and still runs `playwright install chromium`, so the default and the installed browsers do not obviously agree.
The scheduling story is similar: `APScheduler==3.11.0` and `schedule==1.2.2` are both present, and the config table has an `ENABLE_JOB` switch defaulting to `True` plus a `THREADS` value defaulting to `2`.
For a reader, the practical effect is size and ambiguity. The image is not small.
.env.example ships admin credentials and a socks5 line
The environment template is short and it contains values you should not keep:
USERNAME=admin
PASSWORD=admin@123
TZ=Asia/Shanghai
AUTO_RELOAD=True
PROXY_ENABLED=False
PROXY_URL=socks5://<username>:<password>@p.webshare.io:80
Two of those matter on a deployment. The credentials are the web interface's login, and a container that maps port 8001 to the host with the default account is an open door until you change them. `AUTO_RELOAD=True` restarts the service when code changes, which is a development default left switched on in a template people copy.
The proxy line is the more interesting one for planning: egress can be routed through a socks5 proxy, and `PySocks==1.7.1` is pinned in the requirements, so the feature is wired rather than aspirational.
The development steps leave a Windows command behind
The contributor path is short: Python 3.13.1 or newer, Node 20.18.3 or newer, clone, `pip install -r requirements.txt`, copy the config, then start the backend with `python main.py -job True -init True`. The frontend is a separate step in `web_ui` with `yarn install` and `yarn dev`, served on `http://localhost:3000`.
The copy step is where it gets untidy. Two numbered steps are both labelled 3, and the config copy is given twice in a row:
cp config.example.yaml config.yaml
copy config.example.yaml config.yaml
The first is the shell form and the second is the Windows command form. Following the block literally on macOS or Linux fails on the second line, and nothing in the README says which one to ignore.
One more line in the Dockerfile explains the repository's shape: a comment asks contributors to stop adding frontend builds, since compiling the frontend eats workflow time, and suggests compiling once and copying the result into `static/` before opening a pull request.
Export to pdf and docx pulls in six document libraries
The export feature is where the dependency list gets heaviest, and it explains the feature list's four formats: md, docx, pdf and json. Turning an article into any of them needs `Markdown==3.9` with `markdownify==1.2.0` for Markdown, `python-docx==1.2.0` and `docx2pdf==0.1.8` for Word, `reportlab==4.4.3`, `pymupdf==1.27.2.2` and `pdf2docx==0.5.12` for PDF, plus `markitdown==0.1.5` as a general converter.
Six document libraries for one export button is a maintenance surface, since each has its own release cadence inside a fully pinned file. `docx2pdf` is the one to check first on a Linux host,.
The rest of the feature list sits on top of this: scheduled updates, authorization expiry reminders, custom notification channels, custom feed titles and covers, a Cascade system for distributing collection tasks across parent and child nodes, and configuration caching through Redis, Memcached or plain memory.
Editorial conclusion
WeRSS fits a reader who follows a fixed set of WeChat accounts and wants them in an existing feed reader, and who is willing to keep a browser profile and an authorized session alive in a container. It does not fit a serverless deployment, since the image carries a browser, a profile directory and a scheduled job runner. Before you deploy it, change the credentials that `.env.example` ships with, decide whether the baked `config.yaml` is acceptable or whether you need to mount your own, and confirm that the data volume on your host is somewhere a browser profile belongs, because deleting it throws away the license file and browser profile.
Frequently asked questions
How do I run WeRSS for the first time?
Run `docker run -d --name we-mp-rss -p 8001:8001 -v ./data:/app/data ghcr.io/rachelos/we-mp-rss:latest` and open `http://<your-ip>:8001/`. An official image and a China proxy mirror of the same command are also published.
Which database does WeRSS use?
SQLite by default with MySQL optional, set through the `DB` variable, which defaults to `sqlite:///data/db.db` and lives inside the mounted data directory. The pinned dependencies also include `psycopg2-binary==2.9.10`, so a Postgres client is installed even though only two backends are named.
How does WeRSS strip ads out of articles?
Through HTML content filtering rules that are either global or specific to one official account, ordered by a priority from 0 to 100 where higher runs first. Removal works by element ID, CSS class, CSS selector, attribute, regular expression, or by stripping common elements such as script, style and comments.
What formats can WeRSS export an article to?
md, docx, pdf and json. The pinned dependencies behind those four are Markdown with markdownify, python-docx with docx2pdf, and reportlab with pymupdf and pdf2docx.
What does WeRSS need before it can read articles?
An authorized WeChat session. The interface has a QR code authorization step, the feature list includes authorization expiration reminders, and the container keeps a license file at `/app/data/wx.lic` with a browser profile at `/app/data/weread-chrome-profile` inside the mounted volume.
Can WeRSS send its requests through a proxy?
Yes. The `.env.example` template carries `PROXY_ENABLED=False` and a `PROXY_URL` written as a socks5 URL, and `PySocks==1.7.1` is pinned in the requirements file.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rachelos-we-mp-rss)Star history chart for your README
[](https://hysenlabs.com/projects/rachelos-we-mp-rss)Was this useful?