A RAG guide whose newest tag is from 2023, with an unbounded requirements.txt
A comprehensive guide to building RAG-based LLM applications for production.
At a glance
- What is it?
- Anyscale's guide to building a retrieval augmented generation application on Ray, distributed as notebooks and a rag package. The environment it sets up has not moved since 2023: a Ray 2.6.2 Python 3.9 cluster image, model names two generations old, and a requirements file with no version on any line.
- Who is it for?
- This is worth reading for the shape of the system rather than for anything you can install unchanged. The pipeline it teaches, load, chunk, embed, index, serve, with an experiment loop that scores retrieval separately from output quality, is the right skeleton for a RAG service and the notebooks are unusually complete about it.
- Can I use it commercially?
- Yes, with credit. CC-BY-4.0 allows commercial use as long as you credit the authors and indicate what you changed. It is written for creative content, so check how it applies to any code.
- Is it still maintained?
- Yes. The repository last received commits 91 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
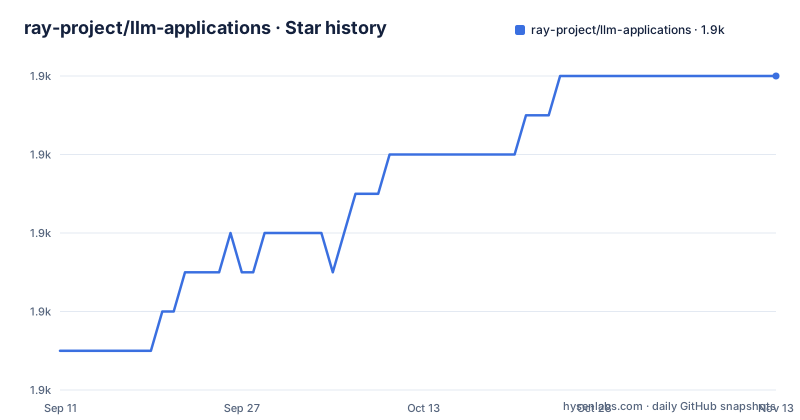
- ray-project/llm-applications1,864 ★ · +7
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| ray-project/llm-applications | 1.9k | 1.9k |
7 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The newest tag is from 2023 and the environment is Ray 2.6.2 on Python 3.9
The release history stops three years ago. v0.0.9, named for an update to the Ray Assistant Service, is dated 2023-09-17, preceded by v0.0.8 when the experiments were completed and v0.0.7 a fix to serve against Anyscale Endpoints. The repository itself was pushed to on 2026-08-15, so the code has moved while the tags have not, and the version is still 0.0.x. The compute instructions make the vintage concrete: the cluster environment to select is `default_cluster_env_2.6.2_py39`, a Ray 2.6.2 image on Python 3.9, on a `g3.8xlarge` head node with two GPUs and 32 CPUs. The formatting configuration agrees with that vintage, since pyupgrade is set to `py39plus = true`. Nothing in the visible page tells a reader which Ray version the code now expects, so the environment the guide was written for and the library it will resolve today are two different things.
requirements.txt has no version on any line
The dependency file is a list of names and nothing else. `ray`, `langchain`, `sentence_transformers`, `openai`, `fastapi`, `tiktoken`, `streamlit`, `slack_bolt` and the rest appear with no constraints at all, and the setup step installs them globally into the user site:
pip install --user -r requirements.txt
export PYTHONPATH=$PYTHONPATH:$PWD
So the versions a reader gets are whatever is current on the day they run it, against a notebook written against a 2023 stack. `pyproject.toml` does not help, because it contains no project table: it is four tool configurations, black, isort, flake8 and pyupgrade, and no `[project]` section, so nothing declares the application as installable either. What the file does do is tell you what kind of project this is. Black, flake8, Flake8-pyproject, isort and pyupgrade appear under a heading for styling, next to matplotlib and seaborn under plotting, and the styling tools are in the same file as the runtime requirements rather than separated into a development group.
The Data section repeats the clone command verbatim
Two blocks in the setup sequence are byte-identical. The Repository section gives
git clone https://github.com/ray-project/llm-applications.git .and the Data section, which explains that the corpus is already prepared and describes how to load it yourself, gives the same line again. So the instruction for fetching the data is the instruction for fetching the repository, and the paragraph about changing an output directory on shared storage describes a command that never appears. That is the kind of gap a reader notices at the exact moment the retrieval results come back empty. Two more commands in the same sequence deserve a glance: `git config --global user.name` and `git config --global user.email` change the configuration of every repository on the machine, and `pre-commit autoupdate` rewrites the pinned hook versions in the local checkout so it no longer matches the committed `.pre-commit-config.yaml`.
The setup points at an internal staging console and two different regions
The Anyscale instructions ask you to start a workspace on staging, and the link goes to `console.anyscale-staging.com/o/anyscale-internal/workspaces`, which is a staging console inside an internal organisation rather than the public one. The data is described as already sitting at `/efs/shared_storage/goku/docs.ray.io/en/master/` on staging in `us-east-1`, while the region instruction a few lines earlier tells you to use `us-west-2` if you want the artifacts in the shared storage, which is where the source docs and vector database dumps are said to be. So the tutorial names two regions for the same assets, and the path carries an internal codename. None of this makes the guide wrong; it makes it a document written by people with access to infrastructure a reader does not have. Expect to supply your own corpus and your own cluster, and treat the two region lines as a documentation bug rather than an instruction.
make clean reformats the tree before it deletes anything
The Makefile is twenty lines and has two targets. The style target runs black, flake8, isort and pyupgrade over the repository. The clean target depends on style:
clean: style
	python notebooks/clear_cell_nums.py
In make, a prerequisite runs first, so `make clean` is not a cleanup command. It reformats every Python file in the repository, applies automatic syntax upgrades, clears notebook cell numbers and only then removes the caches, the `.DS_Store` files and the pytest output. Run it on a branch with work in progress and the diff you get back is not the diff you wrote. The delete steps use `find . | grep -E ... | xargs rm -rf`, where the cache patterns are written with an unescaped dot, so the patterns match more than their names. The one genuinely considerate thing in the file is the removal of `.DS_Store`, which is the fingerprint of a tutorial maintained on a Mac.
Black is set to 99 columns and isort to 79 in the same file
The tool configuration disagrees with itself in a way that would produce a diff every time both run. Black is configured with `line-length = 99`. isort is configured with `profile = "black"` and then `line_length = 79`, which overrides the profile it just asked for, since the black profile exists precisely to make isort agree with black. flake8 then ignores E501, the line too long check, and W503 and E226, each with a comment explaining why, which is a sane set of suppressions. So the file says: format to 99, sort imports to 79, and do not report long lines. If you adopt this configuration, pick one width and write it down. If you are only reading it, this is the clearest evidence in the repository that the tooling was assembled from several sources rather than designed once.
The dependency list is an archaeology layer of the pipeline
Read the requirements file as a record of what the project tried. Two retrieval strategies appear side by side, `rank-bm25` for lexical matching and `sentence_transformers` for embeddings, which is the shape of a hybrid retriever and matches the guide's mention of hybrid routing between open source and closed models. Five database clients appear together: `pgvector`, `asyncpg`, `psycopg[binary,pool]`, `psycopg2-binary` and `sqlalchemy[asyncio]`, so two generations of the same PostgreSQL driver are installed at once. Then there are two frameworks a retrieval tutorial does not obviously need, `slack_bolt` for building a Slack bot and `streamlit` for a dashboard, plus matplotlib and seaborn for plots and structlog and typer for logging and a command line. Every one of those is a dependency someone added for a demo, and none of them is marked optional.
The licence is a content licence and the price line is two model generations old
The repository metadata and the LICENSE file both record CC-BY-4.0. That is a Creative Commons attribution licence written for content, and this repository's primary language is Jupyter Notebook, so the choice is defensible for the prose. It is worth checking before you lift code out of the `rag/` package into a product, because CC-BY-4.0 carries attribution obligations that MIT or Apache-2.0 do not, and the surrounding Ray ecosystem is not licensed this way. The other dated detail is the pricing line in the closing notes, which quotes $1 per million tokens for Llama-3-70b and offers a free trial of private endpoints, while the model actually used in the guide is Llama-2-70b through Anyscale Endpoints and the OpenAI examples name gpt-3.5-turbo and gpt-4. The page also invites readers to a summit described as happening this September 18 to 20 in San Francisco, which is Ray Summit 2024.
Editorial conclusion
This is worth reading for the shape of the system rather than for anything you can install unchanged. The pipeline it teaches, load, chunk, embed, index, serve, with an experiment loop that scores retrieval separately from output quality, is the right skeleton for a RAG service and the notebooks are unusually complete about it. What you cannot do is run it as written and expect the behaviour the author saw. Pin the stack yourself, expect the model calls to need replacing, and be suspicious of the shared-storage paths and the staging console in the setup steps, which point at internal infrastructure rather than at something a reader can reach. Two smaller decisions first: the licence is CC-BY-4.0, a content licence, so check before you copy code out of it, and `make clean` reformats the tree, so do not run it on a branch with work in progress.
Frequently asked questions
What is ray-project llm-applications?
It is a guide and codebase from the Ray project for building retrieval augmented generation applications, licensed CC-BY-4.0 with Jupyter Notebook as the primary language. The repository holds notebooks, a `rag/` package, an `experiments/` directory, a `datasets/` directory and a `deploy/` directory, and its release tags stop at v0.0.9 in September 2023.
Which models does the llm-applications guide use?
OpenAI models named gpt-3.5-turbo and gpt-4 through platform.openai.com, and Llama-2-70b through Anyscale Endpoints for open source models. The closing notes quote $1 per million tokens for Llama-3-70b and mention a free trial of private endpoints.
What do I need to run the llm-applications guide?
An OpenAI account and an Anyscale Endpoints account, a machine with GPUs (the page suggests a g3.8xlarge head node with 2 GPUs and 32 CPUs), a PostgreSQL database with pgvector, and a `.env` file holding the API keys and a connection string. The install step is `pip install --user -r requirements.txt` followed by adding the project to PYTHONPATH.
Does the llm-applications guide pin its dependencies?
No. Every entry in requirements.txt is a bare package name with no constraint, including ray, langchain, sentence_transformers and openai. The pyproject.toml holds only black, isort, flake8 and pyupgrade configuration and has no project table, so nothing in the repository fixes the versions the notebooks were written against.
How does the llm-applications guide measure quality?
It evaluates different configurations of the application against a per-component metric such as a retrieval score and an overall quality score, and it separates the pipeline into load, chunk, embed, index and serve stages so each can be scaled. The repository has an `experiments/` directory for this and a `migrations/` directory for the database.
What license does llm-applications use?
CC-BY-4.0, recorded both in the repository metadata and in the LICENSE file. Since the primary language is Jupyter Notebook, that is a content licence applied to a notebook-first project, and it carries attribution conditions that differ from the permissive software licences common in the Ray ecosystem.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ray-project-llm-applications)Star history chart for your README
[](https://hysenlabs.com/projects/ray-project-llm-applications)Was this useful?