Recommenders: a notebook library with pinned dependencies and an Azure-only production path
Best Practices on Recommendation Systems
At a glance
- What is it?
- The repository teaches recommendation systems through Jupyter notebooks spread across five tasks, but the install spelled out in its README covers CPU notebooks on Linux and WSL only, and its newest tagged release is 22 months older than the newest commit. Valuable as a reference and a template, not as something you can deploy unchanged.
- Who is it for?
- Researchers who want reproducible notebooks for classical and deep recommendation models will get real value here, provided they accept the numpy ceiling and build their own serving layer. Teams expecting a supported production service should look elsewhere, and anyone pinning versions should check first whether 1.2.1, tagged 2024-12-24, resolves against the current state of main.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
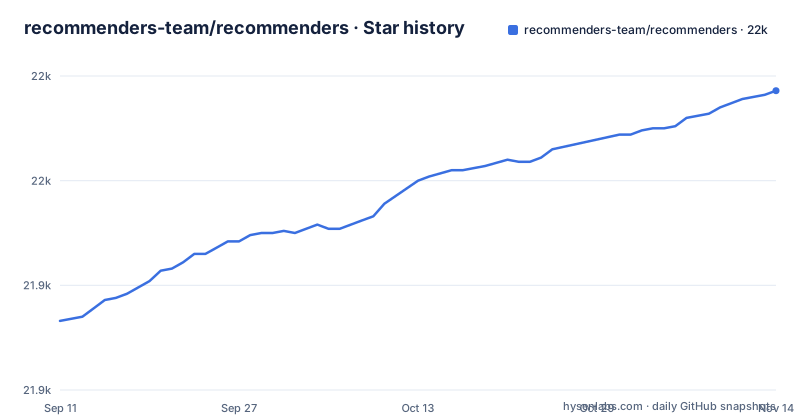
- recommenders-team/recommenders21,993 ★ · +110
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| recommenders-team/recommenders | 21.9k | 22k |
110 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The documented setup stops at Linux and WSL
The install sequence spelled out in the README targets Linux and WSL, and it starts from a compiler rather than from a package index. gcc is step one, on the stated grounds that it might not be installed already, and the comment supplies the Ubuntu command. uv then replaces conda and pip for environment management, and a Python 3.11 virtual environment is created under the home directory. The last step matters as much as the install itself: a Jupyter kernel is registered by hand, so opening a notebook without that registration leaves the kernel pointed at the wrong interpreter. Readers on Windows or macOS get no command here at all, only a pointer to SETUP.md.
# 1. Install gcc if it is not installed already. On Ubuntu, this could done by using the command
# sudo apt install gcc

# 2. Install uv (if not already installed)
curl -LsSf https://astral.sh/uv/install.sh | sh

# 3. Create and activate a new virtual environment
uv venv ~/.venvs/recommenders --python 3.11
source ~/.venvs/recommenders/bin/activate

# 4. Install the core recommenders package. It can run all the CPU notebooks.
uv pip install recommenders

# 5. Create a Jupyter kernel
uv pip install ipykernel
python -m ipykernel install --user --name recommenders --display-name "Python (r
The core install runs CPU notebooks and nothing else
The core install is deliberately narrow. The package description states that the recommenders package can run all the CPU notebooks, and everything else arrives through extras: [gpu] for GPU models, [spark] for Spark models, [dev] for work on the repository itself, [all] defined as gpu, spark, and dev together, and [experimental] for models that are not thoroughly tested. The algorithm table shows what that split costs in practice. Alternating Least Squares works in the PySpark environment, so the ALS quick start cannot run in a core environment no matter how carefully the five install steps were followed.
numpy is pinned below 2.0.0 next to a scikit-learn ceiling
Dependency pinning is where this package collides with whatever else lives in the environment. install_requires in setup.py carries numpy<2.0.0 with an inline comment pointing at issue 2224, pandas>2.0.0,<3.0.0, scikit-learn>=1.2.0,<2, transformers>=4.27.0,<6, and notebook>=6.5.5,<8, alongside category-encoders, cornac, hyperopt, lightgbm, locust, memory-profiler, nltk, pyarrow, retrying, seaborn, and vowpalwabbit, each with its own upper bound. numpy below 2.0.0 is the constraint that reaches outside the project: a neighbouring package built for numpy 2 cannot share this virtual environment without a downgrade. The scikit-learn bound carries a comment that it introduces a breaking change affecting feature_extraction.text.TfidfVectorizer.min_df, so text feature pipelines can change behaviour inside the permitted version range rather than only at the boundary.
setup.py learns its version by executing recommenders/__init__.py
The build script determines its own version by running Python code. It opens recommenders/__init__.py, passes the contents to exec, and reads __version__ out of the resulting namespace, falling back to the string 0.0 when that key is missing. The same file then reads recommenders/README.md to build the long description, which means the README inside the package directory, not the one at the repository root, has to exist before setup gets that far. An environment variable named HASH changes the result: when it is set, a .post suffix and the current epoch time are appended to the version, so two builds from identical source carry different version strings. A third line, site.ENABLE_USER_SITE being derived from whether --user appears in sys.argv, is a workaround for editable installs made through pip install --user.
Operationalize means Azure and nothing else
The production story is narrow in the same way the install is. The operationalize stage of the five task list is defined as operationalizing models in a production environment on Azure, and its example directory is examples/05_operationalize, sitting next to examples/run_notebook_on_azureml.ipynb. What the repository holds, by its own description, is examples and best practices provided as Jupyter notebooks. The entries at the repository root are contrib, docs, examples, recommenders, scenarios, tests, and tools, with no serving component, no request handler, and no deployment manifest for any other cloud among them. A reader planning to run on Kubernetes, on bare machines, or on a provider other than Azure ends up writing the serving layer on their own.
Evaluation stops at offline metrics
Model comparison in this repository ends at offline metrics, and the task list states that in a single line: Evaluate covers evaluating algorithms with offline metrics. None of the five tasks measures clicks, dwell time, retention, or revenue, and no latency budget is set for answering a request with a trained model. The consequence surfaces after deployment: a configuration that wins on an offline ranking metric can still lose traffic, because offline metrics reward ordering a fixed candidate set while production ordering must also return quickly. Readers who need to know which model is genuinely better have to add their own online measurement.
The newest release predates the newest commit by 21 months
Repository activity and published releases tell different stories, and the gap matters when deciding what to install. The main branch received a push on 2026-11-02 and the repository is not archived, so code movement is current. The newest tagged release is 1.2.1 from 2024-12-24, preceded by 1.2.0 from 2024-05-01 and 1.1.1 from 2022-07-20, leaving the newest release 22 months behind the newest commit. The newest section of the README is headed What's New (April, 2025), marks 20,000 stars, and credits release 1.2.1 with dependency fixes and improved security. Because uv pip install recommenders resolves to the released package and not to main, a reader chasing one of those fixes gets the December 2024 resolution, and anything newer requires building from a source tree.
Experimental, GPU and Spark tests are opt-in markers
The test configuration says plainly which parts of the project a default run never touches. pyproject.toml registers four pytest markers: experimental for tests that will not be executed and may need extra dependencies, gpu for tests running on GPU, notebooks for tests for notebooks, and spark for tests that require Spark. Only the experimental marker is described as covering tests that will not be executed. That interacts with the extras and with the algorithm table, where A2SVD, DKN, and xDeepFM are the entries carrying an asterisk, and with the [experimental] extra described as covering models that are not thoroughly tested or may need additional installation steps. Readers who read a green test run as proof that those three models reproduce will not find that proof here.
Editorial conclusion
Researchers who want reproducible notebooks for classical and deep recommendation models will get real value here, provided they accept the numpy ceiling and build their own serving layer. Teams expecting a supported production service should look elsewhere, and anyone pinning versions should check first whether 1.2.1, tagged 2024-12-24, resolves against the current state of main.
Frequently asked questions
What are the types of recommendations?
The repository's algorithm table includes Collaborative Filtering entries, covering ALS, A2SVD, Cornac BPR, Cornac BiVAE, Caser, and xDeepFM, and Content-Based Filtering, covering DKN. Each row also names the environment it runs in, such as CPU, CPU/GPU, or PySpark.
Is "recommenders" a word?
As a package name it is one. The project publishes to PyPI as recommenders, and the core install line given in the project documentation is uv pip install recommenders, with extras such as [gpu] and [spark] layered on top of it.
How to use recommendations?
The documented route is a uv virtual environment on Linux or WSL running Python 3.11, then uv pip install recommenders, then uv pip install ipykernel and kernel registration, and only then opening a notebook from the examples directories such as examples/00_quick_start. GPU, Spark, development, and experimental models each need their extra on top.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/recommenders-team-recommenders)Star history chart for your README
[](https://hysenlabs.com/projects/recommenders-team-recommenders)Was this useful?