rust-analyzer pins the toolchain at 1.98 and tags releases by date
A Rust compiler front-end for IDEs
At a glance
- What is it?
- rust-analyzer is the language server that gives editors go-to-definition, references, refactoring, completion, formatting through rustfmt and diagnostics through rustc and clippy. The repository file is a thin router to a manual, the release tags are dates rather than versions, and the workspace requires a recent language edition and a compiler floor of 1.98.
- Who is it for?
- rust-analyzer fits a team writing Rust in any editor that speaks the language server protocol, and a team willing to read a manual hosted outside the repository. It does not fit a build pinned to an old toolchain, because the workspace requires a recent Rust and an edition from 2024, and it does not suit a team that wants a version number to reason about, because the tags are dates.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
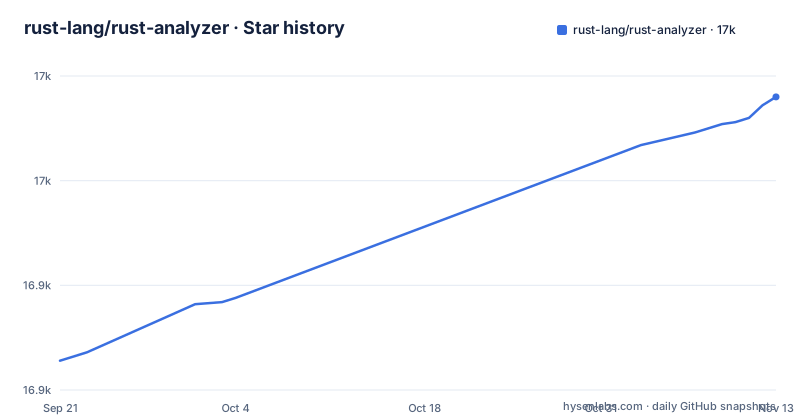
- rust-lang/rust-analyzer16,990 ★ · +126
| Repository | 2026-09-21 | 2026-11-13 |
|---|---|---|
| rust-lang/rust-analyzer | 16.9k | 17k |
126 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The readme is a router, and every answer lives on a website
The repository file is about two hundred words and contains no configuration, no flags and no build instructions, which is a choice rather than an omission. It says what the thing is, that it provides language server functionality, that it works with any editor speaking the protocol, naming Visual Studio Code, Vim, Emacs and Zed as examples, and it lists what you get: go-to-definition, find-all-references, refactorings, code completion, formatting through rustfmt and diagnostics through rustc and clippy. Everything else is a link. Installation is a page. Security and privacy are pages. So is the manual, the API documentation, a metrics dashboard and a changelog. Support is split the same way, with usage and troubleshooting going to a category on the Rust forum and development questions going to a working group on Zulip, which is a sensible division and a fast way to send a question to the wrong crowd.
The tags are dates, so pinning means choosing a day
The release list is the first thing to look at and it is not a semantic version list. The three most recent tags are a nightly build and two dated releases, one dated 2026-11-02 and one 2026-10-26, with the nightly published after the dated release. So the project ships a moving target and a fixed one, and the moving target is named differently from the fixed one rather than hiding in the same namespace. The practical consequence is small but real: there is no major and minor to reason about, no upgrade path to read, and no way to ask whether a version is compatible with something. A dated tag is the thing to pin, and when something breaks you compare two dates rather than two versions. It is also worth noticing that a compiler front-end dated by build rather than by release is being measured in days, which tells you something about how fast the edge of the toolchain moves.
An edition from 2024 and a compiler floor of 1.98
The workspace block is where the build requirements live, and they are not modest. The package metadata sets a compiler floor and a language edition:
[workspace.package]
rust-version = "1.98"
edition = "2024"
license = "MIT OR Apache-2.0"
authors = ["rust-analyzer team"]
There is also a file at the root holding a Rust version, next to a formatter configuration, a linter configuration and a spelling configuration, which is the shape of a repository that pins its toolchain deliberately rather than discovering whatever is installed. For an adopter the consequence is direct. You cannot build this on an older compiler, and if your continuous integration image is a year old, the first failure will be the toolchain rather than anything to do with analysis. The dual licence is worth noticing too, since the file states the project is primarily distributed under both the MIT terms and version 2 of the Apache licence, with a file for each at the root.
Three build profiles, each with a different debugging intent
The profiles section is the most telling part of the manifest. The development profile turns on debug information at level one. The release profile turns it off, with a comment saying to set it to one or two if you want more useful backtraces in a debugger, and a third profile inherits the release settings and turns debug information on at level two instead. So the cost of a build and the usefulness of a stack trace are treated as separate axes, and you pick one knowingly. There are also per-package optimisation overrides: a list of dependencies, including the syntax tree library, a small-string type and the incremental computation framework, are compiled at maximum optimisation in development because the comment says it speeds up local tests, and a compression library is optimised for the same reason in the distribution task. The effect is a repository that tests quickly and ships quickly, at the cost of a manifest where the profile settings are load-bearing.
Two crate chains, and a feature usually belongs to one of them
The local dependency list is effectively the architecture, and the names divide cleanly. One chain lowers the program: the high-level intermediate representation, its definitions, its expansion pass and its type inference. Another implements features: the top-level feature surface, assists, completion and the database behind them. Alongside them sit the macro support crate, the configuration crate, and base database helpers. So when you want to change how the analyser understands a type you are in the first chain, and when you want to change what a completion suggests you are in the second, and the first thing a new contributor has to work out is which of the two owns the behaviour they were asked to change. The workspace members list reinforces it, with patterns for the crates and lib directories plus a task runner, and one member excluded from the workspace entirely because it is a test fixture for the procedural macro server.
An empty patch section is the local development mechanism
Near the end of the manifest is a patch section aimed at the crates registry, and every line in it is commented out. The names are not random: the parser's syntax tree library, an incremental line index, an arena, the language server crate, the grammar tool and the incremental computation framework. That block is how you develop one of rust-analyzer's dependencies in place, and the fact that the file ships the template with the names pre-filled is the difference between a five-minute setup and an afternoon spent working out which library the analyser actually uses for a given job. If you are contributing to anything below the feature layer, this is the first thing to uncomment.
An AI policy, a privacy file and a privacy page, in the same repository
Four files at the root say things about how the project is run rather than how it is built, and one of them is unusual. There is a policy file about artificial intelligence, an instructions file for assistants, an agent configuration file, and a privacy file, and the readme points at both a security page and a privacy page in the manual. For a compiler front-end that reads an entire workspace, that is the right set of questions to answer in the open, and answering them in the repository rather than in a vendor's documentation is what makes the answer usable. The rest of the root follows the same pattern of stating the mechanism rather than implying it: a triage bot configuration, a synchronisation configuration, a benchmark data directory, an editors directory for the editor integrations, and a task runner directory. This is a project that documents its process with the same care it gives its architecture.
Editorial conclusion
rust-analyzer fits a team writing Rust in any editor that speaks the language server protocol, and a team willing to read a manual hosted outside the repository. It does not fit a build pinned to an old toolchain, because the workspace requires a recent Rust and an edition from 2024, and it does not suit a team that wants a version number to reason about, because the tags are dates. Before you adopt it, pin a dated release tag rather than the nightly, which is a separate moving target. Then read the security and privacy pages before you point it at a private repository, because a compiler front-end reads your whole workspace, and this project answers that question in the repository rather than leaving it to your editor's vendor. And if you intend to contribute, the empty patch section in the workspace manifest names the dependencies you can redirect at a local checkout, which is the difference between a quick start and a long afternoon.
Frequently asked questions
How do I install a rust-analyzer?
The project does not put installation steps in the repository file; it links a page in its manual for installation, and a separate page for using the language server with an editor of your choice. The file names Visual Studio Code, Vim, Emacs and Zed as editors it is known to work with, because it speaks the language server protocol.
how to use rust analyzer
You install it as a language server and point your editor at it, then use the features it provides: go-to-definition, find-all-references, refactorings and code completion, with formatting through rustfmt and diagnostics through rustc and clippy. The manual is also where the project says it keeps tips for being more productive with it.
how to use rust analyzer vscode
The project does not document editor-specific setup steps in the repository file. It names Visual Studio Code as one of the editors it works with, because the language server speaks the protocol, and it links a manual page for using the server with the editor of your choice. Editor-level configuration is where those links end.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rust-lang-rust-analyzer)Star history chart for your README
[](https://hysenlabs.com/projects/rust-lang-rust-analyzer)Was this useful?