Text-To-Video-AI ships 54 fully pinned Python packages, a React composer, and an example env file with tru
Generate video from text using AI
At a glance
- What is it?
- A single command turns a topic string into a captioned, voiced, scored video, with the LLM, text to speech, speech to text and video models all chosen in a .env file. The composition itself is done by Remotion rather than Python, three demo videos with attachment UUID names sit at the repository root, and the recommended install path is a hosted API rather than the code you cloned.
- Who is it for?
- This is a reasonable starting point for short vertical videos if you want the pieces of the pipeline visible and adjustable: script, voice, caption timing, music and B-roll are separate switches rather than one opaque call. Two things to check before you rely on it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 37 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
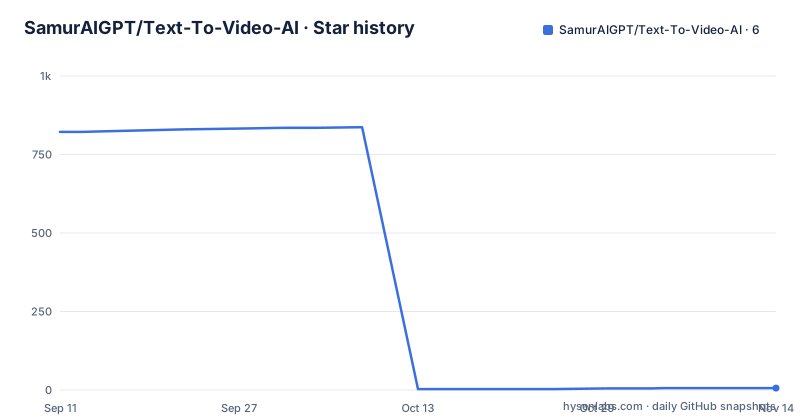
- SamurAIGPT/Text-To-Video-AI6 ★ · -816
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| SamurAIGPT/Text-To-Video-AI | 822 | 6 |
-816 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The shipped example file spells true as tru
Configuration is entirely a `.env` file, copied from the example that ships with the repository.
git clone https://github.com/SamurAIGPT/Text-To-Video-AI.git
cd Text-To-Video-AI

# Install dependencies
pip install -r requirements.txt

# Create your configuration file
cp .env.example .env
There is no command line surface beyond the topic. The whole invocation is:
python app.py "Your topic here"and the output is written to a fixed name, `rendered_video.mp4`. Everything that would normally be a flag is an environment variable, which is a clean design and also means you cannot render two different configurations in one process without rewriting the file.
The bug worth knowing about is in that example file. The documentation shows the caption switch as `CAPTIONS_ENABLED=true`, while the value in `.env.example` is written `CAPTIONS_ENABLED=tru`. If your loader treats anything other than a specific string as false, you will copy the example, leave captions disabled and spend an afternoon wondering why the render has no text on it. It is a one character slip, and it is in the file every new user is told to copy.
The rest of the example file is thorough. It carries three LLM models with their defaults, three provider keys, the always-required Pexels key, the orientation choice, both speech providers with their keys, a commented list of EdgeTTS voice names by accent and gender, five ElevenLabs voice identifiers with names, and then the caption block.
The feature list says B-roll comes from Pexels, the samples say Veo3
There is a direct contradiction on the page about where the background footage comes from.
The feature list has a bullet for automatic B-roll that fetches relevant background videos from Pexels, and the API key table marks the Pexels key as always required, with no exception offered. That is consistent with a design where stock footage is mandatory.
The two named sample videos say something else. Each is described as generated using local EdgeTTS voiceover, whisper timestamped local word captions, Suno AI background music, and Veo3 AI B-roll video segments. So the B-roll in the demonstrated output is generated video from a Google Veo model, not stock footage from Pexels.
Both can be true, and the likely reading is that the Muapi integration added an AI video path after the Pexels bullet was written and the feature list was not revised. But the consequence for a user is concrete: the samples do not represent the default configuration. The Muapi block in the configuration, with its own base URL, key and model, is what produced the Veo3 segments, and turning that block off gets you the Pexels path the features list describes.
The rest of the ingredient list is worth reading closely because it separates free local stages from paid hosted ones. The voiceover is EdgeTTS, which the configuration describes as free. Caption timing is local, through whisper-timestamped. Only the music, from Suno, and the B-roll, from Veo3, are remote services in that list.
Ten video vendors behind one key, with four different naming conventions
The video stage is not in the repository. It is a model string sent to a hosted service.
# Muapi API credentials
MUAPI_BASE_URL=https://api.muapi.ai
MUAPI_API_KEY=your_key

# Video Model to use
MUAPI_VIDEO_MODEL=veo3-fast-text-to-video
The list of model identifiers behind that one setting is long, and it spans ten vendors: Google Veo with five variants, xAI Grok with one, ByteDance Seedance with four, Wan with four, LTX with three, Kling with two, Vidu with two, OpenAI Sora with two, MiniMax with two, and Alibaba with one.
What the list exposes is the naming inconsistency of the layer underneath. Some identifiers hyphenate the version, as in `veo3-fast-text-to-video` and `kling-v3.0-pro-text-to-video`. Some put a dot in it, as in `veo3.1-text-to-video`. Some end in `t2v` and some end in `text-to-video`, in the same family: `sd-2-t2v` sits beside `seedance-2-vip-text-to-video`, and `seedance-pro-t2v` beside `seedance-lite-t2v`. One carries a resolution in its name, `happy-horse-1-text-to-video-1080p`. One carries a model tier word that means a different thing in each family, `pro` and `standard` in Kling and Sora, `vip` and `lite` in Seedance.
The practical consequence is that you cannot infer cost or quality from the string. You have to look up each identifier in whatever catalogue the service publishes, and a typo here fails silently in the sense that you get a different model or an error with no hint which.
The default is the fast Veo 3 text to video model, which is a sensible starting choice given the sample videos.
Fifty four exact pins, including torch and whisper, with no ranges at all
The dependency file is a wall of exact versions, and every single line uses `==`.
The list runs to fifty four entries. The heavyweight ones are `torch==2.3.1`, `openai-whisper==20231117`, `whisper-timestamped==1.15.4`, `moviepy==1.0.3`, `numba==0.59.1` with `llvmlite==0.42.0`, `scipy==1.13.1` and `sympy==1.12.1`. The provider clients are `openai==1.31.1`, `groq==0.11.0`, `google-generativeai==0.8.0`, `deepgram-sdk==3.7.0` and `elevenlabs==2.31.0`, and the audio and video helpers are `edge-tts==6.1.12`, `imageio==2.34.1` and `imageio-ffmpeg==0.5.1`.
There is not one lower bound and not one upper bound in the file. That is the opposite of the usual choice and it cuts both ways. A fresh install will reproduce the environment the samples were made in, which is exactly what you want if you are chasing a rendering difference. It also means the pins are frozen at whatever those versions were, and a security or compatibility fix in any of them requires editing this file by hand.
Two absences are more informative than the fifty four pins. There is no Pexels client library, so that API is called with a plain HTTP request. And there is no Node manifest anywhere at the top level, even though the repository has a `remotion-composer/` directory, which means the composition tool is installed separately.
The stated prerequisites are Python 3.8 or newer, FFmpeg and ImageMagick. FFmpeg is consistent with the imageio and moviepy stack; ImageMagick is a separate system binary for image work. Windows users are pointed to a dedicated install document.
The renderer is React and Remotion, not Python
The sample descriptions name the thing that actually draws the frames.
Both named samples are described as generated end to end by this project using the React and Remotion composition engine. That is a Node rendering stack, and the repository reflects it with a `remotion-composer/` directory at the top level alongside `app.py`, `assets/` and `utility/`.
So the split is roughly this: the Python entry point writes the script, calls the language model for text, gets the voiceover, computes caption timings from a local transcription, and assembles the assets; Remotion then renders the composition to the output file. The fifty four pinned Python packages are the content half of the pipeline, and the layout half is JavaScript.
That structure has consequences for anyone extending it. The project's primary language is recorded as Jupyter Notebook rather than Python, which points at the Colab notebook being the artefact people actually work in. The interactive path is a notebook named `Text_to_Video_example.ipynb`, and the quick start presents running it in Google Colab as one of three options, with no local setup at all.
The three options are worth separating clearly, because only two of them involve this repository. The first is a hosted premium API, described as the recommended route, which generates with a single API call and no installation. The second is the Colab notebook. The third is the local installation above.
Three demo videos with attachment UUID names sit at the repository root
The top-level entries include three MP4 files whose names are the identifiers from which they were uploaded.
`1e440ace-8560-4e12-850e-c532740711e7.mp4`, `752c1d80-e011-4d2e-bc23-0dea2a091244.mp4` and `9718fba7-f9a4-45a6-bc7c-c7e5fa21c8cf.mp4` are all at the repository root, next to `app.py`, `requirements.txt` and `.env.example`. Those exact identifiers are the ones used in the attachment URLs on the project page, so the files were committed by downloading what had been uploaded and dropping it where the tooling put the name.
Two of the three are the named samples, an educational piece on the cosmos, galaxies and black holes, and a cinematic short on deep sea depths, bioluminescent creatures and thermal vents. The third appears to be the single demo video linked above the features section.
Committing rendered video next to source is ordinary for a project whose output is video, and the clips are also what a visitor sees first. It is the naming that is unrecoverable: three files at the root whose names say nothing, no thumbnails, and no indication in the tree of which one is the demo and which two are the samples. Anyone who regenerates those videos has no convention to follow for where the new files go.
The repository also carries a `LICENSE` under MIT, an `.env.example`, a `.gitignore`, a Windows install document and an `assets/` directory. There are no GitHub releases, and the last push to the default branch is recorded as 2026-08-24.
The recommended path is the hosted API, not the repository you just cloned
The quick start opens by offering to skip the setup.
A callout near the top points to a premium API with the promise of generating videos instantly, no installation required, production ready, and scaling with demand. That link is the first item under the quick start, labelled option one and marked recommended. Option two is the Colab notebook. Option three is the local install. So the recommended route is the commercial one, and the repository is the fallback.
That is not hidden, and the project page also links a hosted product page and a badge for the video service the model strings go through. But it does mean the open source artefact and the supported artefact are different products, which is worth knowing before you build something on it.
The rest of the configuration surface is where the project's actual personality shows. Captions are not a boolean and nothing more: font size, font colour from a named list of seven, font face, stroke width, stroke colour, and position from six named slots including `bottom_center`, `bottom_left` and `bottom_right`. The default block is a hundred point Arial Bold in white with a three unit black stroke at the bottom centre, which is a specific look for short vertical video rather than a neutral default.
Voice selection is equally granular. The EdgeTTS path names voices by locale and gender across American, British, Australian, Indian and Canadian English, and the default is an Australian male voice. The ElevenLabs path takes a voice identifier instead, with five named examples in the configuration file.
Orientation is a single variable with two values, portrait at 1080 by 1920 or landscape at 1920 by 1080, with portrait recommended for short form platforms. The contributing guide is the conventional five steps, from fork through pull request.
Editorial conclusion
This is a reasonable starting point for short vertical videos if you want the pieces of the pipeline visible and adjustable: script, voice, caption timing, music and B-roll are separate switches rather than one opaque call. Two things to check before you rely on it. The example configuration file sets CAPTIONS_ENABLED to tru, so copy it carefully rather than trusting it, and the dependency list is pinned to exact versions including torch and whisper, which means you are installing a fixed environment rather than resolving current ones. And the video model is not in the repository at all: ten vendors sit behind one Muapi key, so the cost and the content terms of your output come from whichever model string you pick there.
Frequently asked questions
How do I run Text-To-Video-AI locally?
Clone the repository, run `pip install -r requirements.txt`, copy `.env.example` to `.env`, fill in your keys, then run `python app.py "Your topic here"`. The output is written to `rendered_video.mp4`. Prerequisites are Python 3.8 or newer, FFmpeg and ImageMagick, with a separate install document for Windows.
Which LLM, voice and video models does Text-To-Video-AI support?
The LLM is OpenAI, Groq or Gemini chosen with `LLM_PROVIDER`, the voice is EdgeTTS or ElevenLabs with `TTS_PROVIDER`, transcription is Whisper or Deepgram with `STT_PROVIDER`, and the video model is any of ten vendor families behind one Muapi key, including Google Veo, xAI Grok, Seedance, Wan, LTX, Kling, Vidu, OpenAI Sora, MiniMax and Alibaba.
Where does the background footage in Text-To-Video-AI come from?
The project page says both things. A feature bullet describes automatic B-roll as fetching background videos from Pexels, and the Pexels key is marked always required, while both named sample videos are described as using Veo3 AI B-roll segments. So the samples reflect the AI video path rather than the stock footage path.
Is there anything wrong with the .env.example in Text-To-Video-AI?
Yes. The caption switch is written `CAPTIONS_ENABLED=tru` in the example file, while the documentation shows the value as `true`. Copy the example and correct that value before your first render, or captions may be disabled without an error.
What renders the video in Text-To-Video-AI?
A React and Remotion composition engine, in a `remotion-composer/` directory at the top level. The sample videos are described as generated end to end by the project using that engine, while the Python side handles the script, voiceover, caption timing and assets.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/samuraigpt-text-to-video-ai)Star history chart for your README
[](https://hysenlabs.com/projects/samuraigpt-text-to-video-ai)Was this useful?