A plain MLServer install gives you transports and no way to load a model
An inference server for your machine learning models, including support for multiple frameworks, multi-model serving and more
At a glance
- What is it?
- MLServer speaks the KFServing V2 dataplane over REST and gRPC, but the base package is only the transport layer. Ten framework runtimes ship separately, the Apache-2.0 label does not cover two of them, and the version string in the tree trails the newest published release.
- Who is it for?
- Pick MLServer when you want the KFServing V2 dataplane over REST and gRPC and you already know which framework your models come from, since that choice decides which of the ten runtime packages you add on top. Skip it if you want one install to cover everything, because no such install exists.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
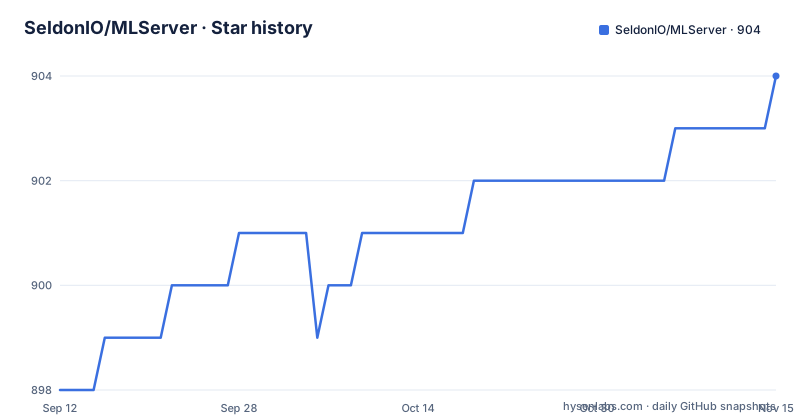
Star history
- SeldonIO/MLServer904 ★ · +6
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| SeldonIO/MLServer | 898 | 904 |
6 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The server installs first and the model loaders install after it
A plain install gives you the transports and no way to load a model. The server package is one command:
pip install mlserverEvery framework backend is a second, separate command. The usage notes spell out that step with the scikit-learn runtime named explicitly:
pip install mlserver-sklearnScikit-Learn, XGBoost, Spark MLlib, LightGBM, CatBoost, Tempo, MLflow, Alibi-Detect, Alibi-Explain and HuggingFace each have their own row in the support table, their own documentation link and their own package name, and the project describes these runtimes as the backend glue between MLServer and the framework you already use. They are not plugins discovered at startup. Each directory under `runtimes/` carries its own packaging and its own tox configuration, so the release target walks those same directories and publishes each one separately. An image build can fold them together, since the Dockerfile exports constraints for an extras group named `all-runtimes` and the runtime stage takes `ARG RUNTIMES="all"`, but the pip command above does not do that for you.
The base package depends on a Triton client it never offers as a runtime
The dependency list of the base package reads more like a full serving stack than a REST wrapper, and a few entries are worth a second look. `tritonclient[http]>=2.5,<2.61` is a hard requirement even though Triton appears nowhere in the supported framework table, so an installation with no Triton runtime behind it still carries a Triton HTTP client. `aiokafka` is unconditional, and so is the OpenTelemetry set: the sdk, instrumentation for both FastAPI and gRPC, and the OTLP gRPC exporter. FastAPI is the only dependency with a single version carved out, `!=0.89.0`, inside a range running from 0.88.0 to below 0.125.0. `uvloop>=0.22.1,<0.24` carries a platform marker that switches it off on win32, on cygwin and on PyPy, and `importlib-resources>=5.12,<7.0` is present, per the inline comment, so data files stay reachable on Python below 3.10. Metrics and the REST schema ship too: `starlette-exporter` and `py-grpc-prometheus` are both required, and the packaging includes `mlserver/rest/openapi/*.json` as package data.
A four state Python legend that only ever uses two of its states
Python support is presented with a legend of four states: unsupported, deprecated and marked for removal in a future version, supported, and untested. The version table then uses only the first and the third. 3.7 and 3.8 are unsupported, 3.13 is unsupported as well, and 3.9 through 3.12 are supported. Nothing anywhere in the repository is marked deprecated or untested, so the two extra states the legend takes the trouble to define have no rows pointing at them. The packaging metadata agrees with the table exactly: `requires-python = ">=3.9,<3.13"`. The drift is on the platform side instead. The classifiers claim only `Operating System :: POSIX` and `Operating System :: MacOS`, while the dependency spec still carries branches that disable uvloop on win32 and on cygwin, which means Windows exclusions were written into the install requirements for a package that no Windows classifier claims. The container image sits in the middle of the supported band rather than at either end of it.
The image tag comes from a placeholder version, not from a release
The version in the tree is a placeholder and the project admits it: the versioning notes say they generally keep the version as a placeholder for an upcoming version, illustrated with `./hack/update-version.sh 0.2.0.dev1`. `pyproject.toml` currently reads `version = "1.7.0.dev0"`, while the newest published release is 1.7.1 from 2025-06-06, ahead of 1.7.0 from 2025-04-11 and 1.6.1 from 2024-09-10. The Makefile never reads a release tag. It derives a value of its own by running sed against the source file:
VERSION := $(shell sed 's/^__version__ = "\(.*\)"/\1/' ./mlserver/version.py)That value becomes the container tag. The build target runs `./hack/build-images.sh ${VERSION}` after cleaning, the publish target pushes `${IMAGE_NAME}:${VERSION}` and a `-slim` variant under `seldonio/mlserver`, and the same version string feeds the wheel build. So the tag a build publishes follows whatever placeholder the source file currently holds, which means two different trees can produce the same version string with different contents. Anyone pinning by image tag should read the tag off the release it came from.
Apache-2.0 covers the server while two bundled runtimes are BUSL
The Apache-2.0 label covers the server, not everything the server can be asked to load. Two of the ten runtimes in the support table, Alibi Detect and Alibi Explain, are licensed under the Business Source License 1.1, and the project states this in the same paragraph as its own Apache notice, adding that software used in conjunction with MLServer may be licensed under different terms. The container build runs into the same split as a mechanical problem. After exporting constraints for every runtime, it edits the generated file in place, first stripping bracketed extras markers and then deleting alibi lines by match string:
sed -i 's/\[.*\]//g' /opt/mlserver/dist/constraints.txt && \
# skip constraints for alibi libraries as they are currently pointing to git and thus confusing constraints \
# remove when the alibi libraries versions are pointing to a released version \
sed -i '/git+https:\/\/github.com\/SeldonIO/d' /opt/mlserver/dist/constraints.txt
The comment above the second command says alibi libraries are currently pointing at git, which makes the constraints confusing, and asks for the line to come back once they point at a released version. An image built today therefore resolves two of its framework backends from git rather than from a numbered release. A `licenses/` directory sits at the top level and `make licenses` is among the declared phony targets.
Six targets have recipes and no place in the phony list
The Makefile declares fourteen phony names and then defines six further targets that carry recipes without appearing on that list:
.PHONY: install-dev _generate generate run build \
	push-test push test lint fmt version clean licenses
`lock`, `bootstrap-test`, `generate-model-repository`, `generate-dataplane`, `_generate_model_repository` and `_generate_dataplane` are all absent from the declaration. Nothing at the top level is named `lock` or `generate-model-repository` today, so a target that shadows a recipe still runs the recipe, which is the friendly outcome. The same file leans on order-only prerequisites, with `generate: | _generate_model_repository _generate_dataplane fmt`, and each of those two private helpers ends by calling `fmt` itself. One `make generate` formats the tree three times, and `make generate-model-repository` formats it twice. The private helpers are the ones doing the actual work, invoking `poetry run bash ./hack/generate-types.sh` against either the `model_repository` or the `dataplane` target, and their inline comments mark them as targets that exist to call `fmt` after `generate`.
Root pytest configuration skips the directory holding all ten runtimes
Testing gets one sentence in the guide, and the root configuration narrows what that sentence covers. The testing section offers `make test` for MLServer and the runtimes, and a single file with `tox -e py3 -- tests/batch_processing/test_rest.py`. The pytest settings set `asyncio_mode` to `auto`, force `--import-mode=importlib`, and then exclude one directory from collection:
[tool.pytest.ini_options]
asyncio_mode = "auto"
addopts = "--import-mode=importlib"
norecursedirs = [
    "runtimes"]
A bare pytest run started at the top level therefore collects nothing from `runtimes/`, which is where every framework backend lives. Those directories are less excluded from testing than relocated within it. The `bootstrap-test` target copies the top-level `tox.runtime.ini` into each runtime directory as that directory's `tox.ini`, and each runtime is packaged on its own, so runtime tests run in per-runtime environments that have to exist before they can be collected. Both `tox.ini` and `tox.runtime.ini` sit at the top level, and the single-file example above names a root test path rather than anything inside a runtime.
Model paths are set in the image and left out of the written guide
The published image encodes a convention about where models live, and that convention is visible only if you read the image build. Three environment variables carry it: `MLSERVER_MODELS_DIR=/mnt/models`, `MLSERVER_ENV_TARBALL=/mnt/models/environment.tar.gz` and `MLSERVER_PATH=/opt/mlserver`. The middle one is the interesting one, because it points inside the model directory at a conda tarball, which implies a model directory can arrive carrying its own environment archive. The example list does include loading and unloading models from a model repository, yet none of these three variable names appear anywhere in the guide. The runtime base is Red Hat's `registry.access.redhat.com/ubi9/ubi-minimal` rather than anything Debian based, with conda under `/opt/conda` and Miniforge pinned by `ARG CONDA_VERSION=23.11.0` plus `ARG MINIFORGE_VERSION=${CONDA_VERSION}-0`, which derives the miniforge version from the conda version. The last line of the ENV block declares `LD_LIBRARY_PATH` with no value at all, directly beneath a note telling maintainers to update the `/opt/conda` path inside it.
Editorial conclusion
Pick MLServer when you want the KFServing V2 dataplane over REST and gRPC and you already know which framework your models come from, since that choice decides which of the ten runtime packages you add on top. Skip it if you want one install to cover everything, because no such install exists. Before pinning anything, read the version out of the tree rather than off the release list, check whether the runtime you need is on the Apache-2.0 side of the licence split or the Business Source License side, and if you build the image yourself, look at the constraints file the build writes to see whether the alibi backends came from git.
Frequently asked questions
How does MLServer relate to KServe?
KServe, formerly known as KFServing, appears in the project as a deployment target where MLServer is the core Python inference server used to serve models, and MLServer itself implements the same V2 Inference Protocol over gRPC and REST. So the two are layers of one stack rather than competing servers on the wire.
Is MLServer the same kind of thing as MLflow?
Not in this project's own framing. MLflow is one of the ten framework backends in the support table, installed through its own separate package, so a model produced by MLflow can be served through MLServer rather than MLflow standing in as an alternative server.
What are the alternatives to MLServer?
The project names no competing servers. What it does document is the V2 Inference Protocol, described as standardised and adopted by various model serving frameworks, plus deployment paths through Seldon Core and KServe, which means substitution happens at the protocol layer rather than in a list of rivals.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/seldonio-mlserver)Star history chart for your README
[](https://hysenlabs.com/projects/seldonio-mlserver)Was this useful?