pycorrector wraps nine correction models and they disagree about errors
pycorrector is a toolkit for text error correction, implementing models like Kenlm, T5, MacBERT, ChatGLM3 and Qwen2.5 for correction tasks, ready to use out of the box.
At a glance
- What is it?
- pycorrector is a Chinese text error correction toolkit that puts nine backends, from a CPU n-gram model to Qwen2.5 fine-tunes, behind one Python API. The evaluation table is the part worth reading: the model tagged as recommended is not the highest scoring one, and the ranking depends entirely on which test set you look at.
- Who is it for?
- Use pycorrector when your text is Simplified or Traditional Chinese and you want to choose a correction model against your own domain data. Do not reach for it as an English spell checker, and do not put the ChatGLM3 or Qwen classes on a latency-sensitive path, since the project's own figures put them at 3 and 6 QPS on a Tesla V100.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 113 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
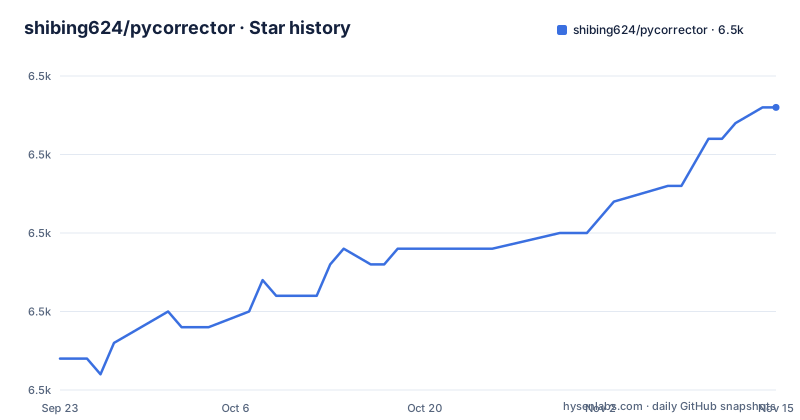
- shibing624/pycorrector6,543 ★ · +16
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| shibing624/pycorrector | 6.5k | 6.5k |
16 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Pinyin, Wubi and OCR errors are three different problems
The project opens by separating error types rather than treating correction as one task, and that separation is the most reusable thing here. Pinyin input methods and speech recognition proofreading produce phonetic-similar errors, characters that sound alike. Wubi input methods and OCR proofreading produce shape-similar errors, characters that look alike. Search engine query correction has to handle every type at once.
The wording matters because the useful model differs per category. A shape-similar detector trained on OCR output is wasted on dictated text. pycorrector states that it focuses on the phonetic-similar, shape-similar, grammar and proper-noun categories.
The toolkit also distinguishes two task definitions. CSC, Chinese Spelling Correction, means length-aligned errors: phonetic, shape and grammar problems where the corrected sentence has the same length. CTC, Chinese Text Correction, additionally covers length-unaligned errors, such as extra or missing characters. That is the dividing line between the older MacBERT and ERNIE models and the Qwen fine-tunes, and it is the first question to settle before choosing a backend.
Sentence-level scoring is why the F1 numbers look low
The metric explains the numbers before you read them. pycorrector scores correction precision and recall at strict sentence level: a corrected sentence counts as correct only if it exactly matches the reference sentence, anything else counts as wrong. One extra comma, one substituted synonym that is semantically fine, and the sentence scores zero.
That choice produces averages such as 0.3409 for Kenlm-CSC and 0.6802 for Qwen2.5-1.5B-CTC, which looks poor next to token-level spelling benchmarks until you know the scoring rule. It also means the figures are not comparable to anything computed at token level.
Three test sets drive the table: SIGHAN-2015, EC-LAW and MCSC. Their tsv files ship in the repository, two of them under examples/data/, so you can run the comparison yourself rather than take the published column. The evaluation script is examples/evaluate_models/evaluate_models.py, and the named hardware is a Tesla V100 with 32 GB of memory, which matters when reading the QPS column.
None of this makes the metric wrong. It makes it strict in a specific direction, and if your own use case tolerates partial credit, the published ranking is not the ranking you will get.
MacBERT carries the recommended tag and the weakest EC-LAW score
MacBERT4CSC is the one model the project tags as recommended. It is a PyTorch implementation with separate error detection and correction networks, adapted to Chinese spelling correction, and the project's own verdict on it is that the effect is good.
The numbers tell a more complicated story. MacBERT-CSC scores 0.8314 on SIGHAN-2015, second only to ERNIE-CSC at 0.8383. On EC-LAW it scores 0.1610, the weakest figure among the rows shown, against 0.3357 for ERNIE and 0.4369 for ChatGLM3-6B. Its average sits at 0.3993, below ERNIE at 0.4353, ChatGLM3 at 0.4538 and Qwen2.5-1.5B-CTC at 0.6802.
Qwen2.5-1.5B-CTC is the more interesting row. It averages 0.6802 and reaches 0.9529 on MCSC, but drops to 0.3032 on SIGHAN-2015, worse than the CPU Kenlm n-gram model at 0.3147. A model that leads on one set and trails on another is telling you the sets measure different things.
So the recommendation tag is a starting point, not an answer. Pick on your test set, not on the tag.
QPS splits the table into two different products
The throughput column divides these models into groups that are not really competitors. MacBERT-CSC runs at 224 QPS and Mengzi-T5-CSC at 214, both on GPU. ERNIE-CSC sits at 114. Kenlm-CSC runs at 9 QPS, and it is the only row marked CPU rather than GPU.
Then there is the gap. ChatGLM3-6B-CSC measures 3 QPS on the same V100, and Qwen2.5-1.5B-CTC measures 6. Those two carry the accuracy end of the table, and they cost roughly two orders of magnitude in latency relative to MacBERT.
This is the practical dividing line. If you are correcting search queries or OCR output in a request path, a six-QPS model is a non-starter and the MacBERT or Mengzi-T5 class is the only realistic choice. If you are cleaning a corpus overnight, throughput is irrelevant and you should take the Qwen row.
Kenlm deserves a separate mention because it is the only row benchmarked on CPU. It is an n-gram language model combined with rule methods and a confusion set, and the project's own assessment is that it is fast, extensible, and only average in effect.
v1.1.4 turned the proper-noun dictionary into an inverted index
The ProperCorrector work in release 1.1.4, dated 2026-07-25, is the most specific engineering note in the project and worth reading for what it says about the old design. The old approach scanned a proper-noun dictionary segment by segment in full. The new one builds a multi-level inverted index keyed by word length plus position, removes a redundant Trie, and fixes out-of-vocabulary stroke false positives.
The stated effect is a correction speed improvement of about 80 times at a dictionary scale of 40,000 entries. That is a data structure change rather than a model change, which is why it landed without touching any checkpoint.
The release history shows a project that revises itself on its own schedule rather than on a calendar. Version 1.0.0 on 2023-11-07 brought in ChatGLM3 and LLaMA2 and rewrote the DeepContext, ConvSeq2Seq and T5 implementations. Version 1.1.0 on 2024-10-14 added Qwen2.5 with the 1.5b and 7b checkpoints. Version 1.1.2 on 2025-07-08 added the Qwen3-based model. Version 1.1.4 arrived 2026-07-25, with v1.1.1 dated 2024-12-13 in between.
Those gaps are the maintenance signal: the last push was 2026-07-25, and the previous release was a year earlier. Plan for a project that moves in bursts.
Install the CPU wheel of torch first, then run the gradio demo
The package itself installs with pip (the Dockerfile runs pip3 install pycorrector), but the backends use different frameworks. The Dockerfile shows the intended order, and it puts torch in first, pinned to the CPU wheel index:
pip3 install torch --index-url https://download.pytorch.org/whl/cpu --no-cache-dir
pip3 install -r requirements.txt -i https://pypi.tuna.tsinghua.edu.cn/simple
The base image is nikolaik/python-nodejs:python3.8-nodejs20, and the README states the toolkit is developed against python3.8. Nine plain Python dependencies come next, and this list is the actual floor for any backend:
jieba
pypinyin
transformers
datasets
numpy
pandas
six
loguru
pyahocorasick
Each one has a job. pypinyin is what makes phonetic-similar comparison possible, jieba segments text, pyahocorasick provides Aho-Corasick string matching, and transformers loads model checkpoints.
First real use is the MacBERT demo, which is the one the README names:
python examples/macbert/gradio_demo.pyA HuggingFace space and an official demo page also exist. The examples/ tree carries one directory per backend, plus examples/evaluate_models/ for the comparison script, so each model has a runnable entry point rather than a shared one.
The Dockerfile installs pycorrector from PyPI, not from its own checkout
The container recipe contains a step worth flagging if you build from it. After COPY. . it runs pip3 install pycorrector from the package index, which means the image ends up importing the published distribution rather than the source that was just copied in. The contents of /app/examples come from the checkout while the library itself comes from PyPI, so a local edit to pycorrector/ has no effect on what the container runs.
The final state is WORKDIR /app/examples with CMD /bin/bash, so the image starts a shell in the examples directory rather than a service. That is a development sandbox, not a deployment image.
Version declarations disagree in a second place. setup.py declares python_requires='>=3.6' and gates on sys.version_info < (3,), while the README says python3.8 and the image is python3.8. The 3.6 floor is permissive in a way the rest of the project is not, and transformers and datasets in particular have moved their own minimums upward since 3.6 stopped being a sensible target. Treat 3.8 as the real floor.
The license field is a plain string, license="Apache 2.0", and a LICENSE file sits at the repository root. That is the permissive path for the code; the model checkpoints are hosted separately on HuggingFace.
Editorial conclusion
Use pycorrector when your text is Simplified or Traditional Chinese and you want to choose a correction model against your own domain data. Do not reach for it as an English spell checker, and do not put the ChatGLM3 or Qwen classes on a latency-sensitive path, since the project's own figures put them at 3 and 6 QPS on a Tesla V100. Verify first by running examples/evaluate_models/evaluate_models.py on your own sentences, because the strict sentence-level metric and the choice of test set will reorder the ranking for your data.
Frequently asked questions
Is pycorrector a spell checker available for Python?
Not in the sense that phrasing implies. pycorrector corrects Chinese text, specifically phonetic-similar, shape-similar, grammar and proper-noun errors, and its package classifiers declare Chinese Simplified and Chinese Traditional. The Python package is how the toolkit is delivered, not the language it corrects.
What does installing pycorrector pull in?
setup.py lists jieba, pypinyin, transformers, datasets, numpy, pandas, six, loguru and pyahocorasick as install_requires, which is the same set requirements.txt carries. Model backends add more on top, and the Dockerfile installs torch from the CPU wheel index before any of them.
Which pycorrector model is recommended?
MacBERT4CSC is the one the project tags as recommended, a PyTorch model with separate error detection and correction networks. Alternatives include the CPU Kenlm n-gram model, a Mengzi-T5 fine-tune, ERNIE_CSC on PaddlePaddle, ModelScope's MuCGECBart, NaSGECBart without the ModelScope dependency, and ChatGLM and Qwen fine-tunes.
How is pycorrector evaluated?
Correction precision and recall at strict sentence level, where a corrected sentence counts as right only if it exactly matches the reference. The test sets are SIGHAN-2015, EC-LAW and MCSC, the score reported is F1, and the run hardware named is a Tesla V100 with 32 GB of memory.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shibing624-pycorrector)Star history chart for your README
[](https://hysenlabs.com/projects/shibing624-pycorrector)Was this useful?