Hyper-Extract: one-command knowledge extraction, with document ingestion behind an optional extra
Hypergraph is more powerful. Transform unstructured text into structured knowledge with LLMs. Graphs, hypergraphs, and spatio-temporal extractions — with one command.
At a glance
- What is it?
- An LLM knowledge extraction CLI whose rich document ingestion depends on an optional extra, and where Anthropic, Google Gemini and DeepSeek are LLM-only and must be paired with an OpenAI-compatible embedder.
- Who is it for?
- Hyper-Extract suits someone who already has chosen a model provider and wants a graph-shaped answer rather than a text chunk, and who is willing to read the provider system page before configuring anything. Check these things first.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
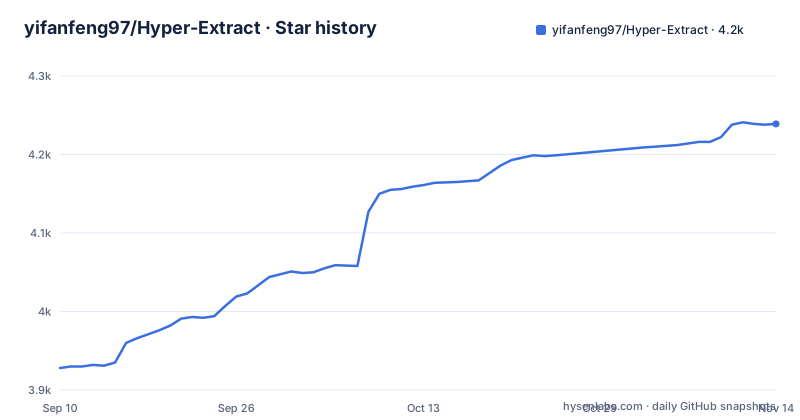
- yifanfeng97/Hyper-Extract4,239 ★ · +311
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| yifanfeng97/Hyper-Extract | 3.9k | 4.2k |
311 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The ingestion feature row promises more formats than the extra delivers
The core features table has a row for rich document ingestion, and the row names its formats: PDF, Word, PowerPoint, Excel, HTML and EPUB among others, with a parenthetical giving the extra to install. The parenthetical is the point. Since the row sits in the table headed core features, it is easy to miss that anything beyond .txt and .md needs that extra. The same conversion package is also declared in the development dependency group, with a comment saying it is kept there so continuous integration exercises it. That is a sensible reason, since a pipeline cannot test an extra it does not install, and it explains the duplication.
Three of the six providers leave you needing a second vendor's key
The provider setup splits into two kinds, and the difference is which key you need. The configuration block shows both:
# OpenAI (LLM + embeddings in one key)
he config init -p openai -k YOUR_OPENAI_API_KEY

# DeepSeek (LLM only — pair with an OpenAI embedder, most cost-effective)
he config llm -p deepseek -k YOUR_DEEPSEEK_API_KEY
he config embedder -p openai -k YOUR_OPENAI_API_KEY

# Local vLLM (free, on-premise)
he config llm -p vllm -u http://localhost:8000/v1 -k dummy -m Qwen/Qwen3.5-9B
he config embedder -p vllm -u http://localhost:8001/v1 -k dummy -m BAAI/bge-m3
Only two of the six named providers supply both roles from one key. The other three supply the language model only, and the file's own remedy is to pair them with an OpenAI-compatible embedder, which means someone who has chosen Anthropic or Gemini or DeepSeek still needs a separate embedder, and the README's examples pair them with an OpenAI key. The cheapest option, DeepSeek, is quoted at roughly $0.001-0.005 per page, a fivefold range. The local option is the only one that sends nothing anywhere, and it is also the most work: two servers, on two different ports, serving two different models, with a placeholder key of dummy.
The verified model table names three models and stops partway through
There is a hard requirement stated before the table: the tool uses structured output through function calling, so the model must support tool or function calling. That is a real constraint rather than a preference, and it rules out a class of models and self-hosted setups regardless of quality. The table that follows is headed verified models rather than supported models, which is a narrower and more useful claim, and its first row names three OpenAI models. Elsewhere a comment names a default for Google, giving a specific model identifier, which suggests defaults are chosen per provider and documented in the configuration examples rather than in the table. The provider system page is linked for the full picture.
Tags are added in full and then searched by prefix, without saying so
Two quick start lines sit next to each other and between them they hint at how tags are matched. The first adds a tag to a document, passing an add flag and the full word biography. The second runs a search against the same output directory, passing a tag flag and the four letters biog.
The tag added is the full word, and the tag searched for is its first four letters. Check how the search tag flag is matched in the documentation before you build a tag vocabulary. The same block contains a naming choice that is genuinely confusing. Feeding an updated document names the new file as the positional argument and the old one in a flag called source, so the flag identifies the record being replaced rather than the file being read. The knowledge base section makes it clearer by using a versioned filename for the new content and the original name in that flag, which is the right way round.
There are two configuration systems and the file documents one of them
Every setup instruction in the readme goes through the command line, with a subcommand for initialising and separate ones for the language model and the embedder. So the supported path is a config file written by the tool. The repository also ships an environment file example, and that file documents a different mechanism: four variables, of which one is described as required for OpenAI-compatible providers and embeddings, one as an optional base URL for use with a proxy, and two as optional but required when using their respective provider. The Anthropic entry mentions a second variable name accepted as an alias without showing it assigned. And there is nothing in the example for two of the six providers the readme names, nor for the local model option, which needs two addresses and a placeholder key on the command line instead. So a user has two mechanisms to discover, and the template file does not say which wins when both are set. Given that the tool writes its own configuration, the environment route reads as the compatibility path for people who already inject secrets that way.
One example block ends in a comment that stops mid-word
The knowledge base section's example block spells out the update semantics: ingest with attribution, feed a new version under the old source so previous facts roll back, remove a document to undo everything it contributed, and remove a single wrong fact with a dry-run preview. Those four operations are the difference between a demo and a knowledge base you can correct.
The keywords advertise a package the manifest does not declare
The manifest's keyword list includes a validation library that appears nowhere in its dependency list. It comes in transitively through the language model integration, so nothing breaks, but the keyword is a claim about what the package is built on and the dependency list is the authority on that. The declared dependencies are more informative when read as a group. A CPU-only vector index library, which is consistent with the file's claim that the free local option needs a GPU: the GPU is for serving the model, not for the search index, and the index stays on the CPU. A near-duplicate detection library, which is what makes it plausible that feeding an updated document can roll back the facts the previous version contributed. Two packages with an ontology-sounding prefix and low version numbers, which appear to be the project's own extraction layer. A structured logging library and a terminal formatting library for the command line, a TOML writer for the config file, and a dotenv reader. So the architecture is legible from the manifest even where the readme is thin.
Alpha status, patch five of the 0.10 line, and three releases in ten days
Three dates and one status line frame the project. The manifest reads 0.11.1 and its classifier calls the project alpha. The last three releases are v0.10.5 on 2026-09-29, v0.11.0 on 2026-10-29 and v0.11.1 on 2026-11-03, and the last push is the same day as v0.11.0. So this is a fast-moving pre-one project, and the release names are written as changelog headlines rather than version strings, describing what changed. One of them is worth reading closely: v0.11.1 is titled as shipping provider presets as a 0.11.0 packaging correction, and v0.11.0 as a preset regression fix with new providers and diagnostics, while v0.10.5 mentions load-time template validation and friendlier local-model errors, so the recent releases are largely about failure modes rather than features. On the licensing side the manifest declares Apache-2.0 using the older table form with the licence as free text rather than an identifier, a licence file is present at the root, and the recorded identifier for the repository is undetermined. The documentation, the readme and the examples are all bilingual, and the documentation site is versioned with every link pointing at a moving path.
Editorial conclusion
Hyper-Extract suits someone who already has chosen a model provider and wants a graph-shaped answer rather than a text chunk, and who is willing to read the provider system page before configuring anything. Check these things first. The rich document ingestion feature is an optional extra, so install it if you need more than .txt and .md. The cheapest provider is quoted per page, which means your bill tracks document length. Anthropic, Google Gemini and DeepSeek supply the language model only, so their users need a separate OpenAI-compatible embedder. And the project is marked alpha while shipping releases of a 0.11 line, so expect the command surface to move.
Frequently asked questions
What is Hyper-Extract?
A command line tool and Python library that turns documents into structured knowledge with large language models. It offers nine knowledge structures from plain chunk corpora through graphs, hypergraphs and spatio-temporal graphs, eleven or more extraction engines, and over eighty YAML templates, with export to an Obsidian vault of linked Markdown notes.
How do I install Hyper-Extract?
There are three documented routes. Install the uv tool, whose own installer is a curl of a script piped into a shell, then either a uv tool install or a pipx install of the package, both of which give you the command line tool. The library path uses uv pip install instead. All three are shown in the readme.
Which model providers does Hyper-Extract support?
OpenAI and Alibaba Bailian supply both the language model and the embedding model from one key. Anthropic, Google Gemini and DeepSeek supply the language model only and are paired with an OpenAI-compatible embedder, so choosing one of those still means holding an OpenAI key. A local option runs against a self-hosted server on two ports with a placeholder key.
What document formats can Hyper-Extract ingest?
The core features table names PDF, Word, PowerPoint, Excel, HTML and EPUB among others, and gives the extra to install. Those formats beyond .txt and .md need that extra: pip install "hyperextract[ingest]".
Does Hyper-Extract need a model that supports function calling?
Yes, and the file states it as a requirement rather than a preference, because the tool uses structured output through function calling.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yifanfeng97-hyper-extract)Star history chart for your README
[](https://hysenlabs.com/projects/yifanfeng97-hyper-extract)Was this useful?