MimirQ: a Chinese-first RAG stack where the Makefile has 103 targets and the versions disagree
A Chinese-first enterprise RAG knowledge base with controllable parsing, governance, chunking, hybrid retrieval, reranking, citations, knowledge graphs, evaluation and Dify integration.
At a glance
- What is it?
- MimirQ is an enterprise retrieval stack built around inspectable parsing, replaceable policies and Golden-set regression, with ten opt-in parser containers and two Dify integration shapes. Its rough edges are version drift in the release history, a shipped default password in DATABASE_URL, and a torch pin that exists twice for one reason.
- Who is it for?
- MimirQ fits a team that has to say why a retrieval answer was wrong, that needs parsing and chunking swapped per document type, and that wants a fixed question set gating releases. It does not fit a quick prototype, a laptop without 16 GB of RAM, or a team that wants one process and one command.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
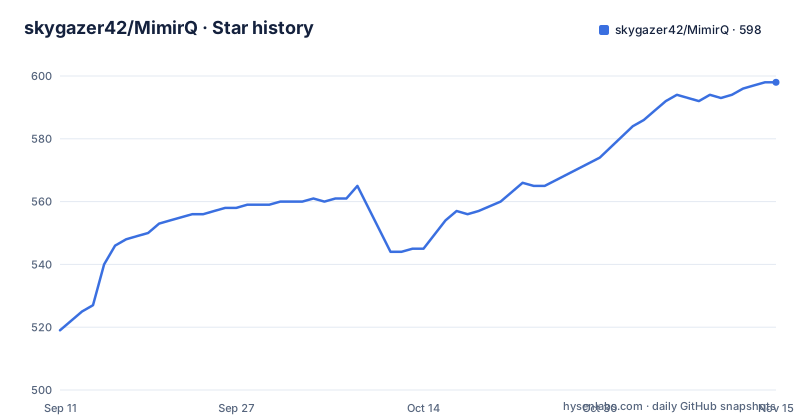
- skygazer42/MimirQ598 ★ · +79
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| skygazer42/MimirQ | 519 | 598 |
79 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three releases on one July day, two of them a second apart
The release history is compressed into a single morning. v0.7.17, whose release name is about hardening identity and general-knowledge boundaries, went out at 01:18:49 UTC on 2026-07-28. Ten hours later, at 11:36:39, v0.8.0 landed with a name about general knowledge capability and concurrency safety. One second after that, at 11:36:40, v1.0.0 was published. Two of the three tags in the recent list are therefore separated by a single second, and the one that jumps the major version is the last of them.
The README does not agree with that list about the current version. It states the latest stable release is v1.0.1 and links a release note file for it, while the newest published tag is v1.0.0. A reader who installs by the documented version and then checks the releases page finds a gap, and a reader who wants to reproduce a deployment has to work out whether v1.0.1 exists as a tag, as a document, or only as the newest entry in a docs directory.
Against that, the last push to main is 2026-09-23, more than two months after the version burst, and the project is Apache-2.0 with a NOTICE file at the root. The handbook is published separately at skygazer42.github.io/MimirQ/handbook/, so the documentation a user reads is not necessarily the documentation in the repository, which is the likelier explanation for the version mismatch.
The Makefile is the interface, and it declares 103 phony targets
Everything is a make target. Setup is three commands:
git clone --depth 1 --single-branch https://github.com/skygazer42/MimirQ.git
cd MimirQ
make init
`make init` only creates the missing `.env` and `web/.env.local` and will not overwrite existing configuration, which is the behaviour you want from a bootstrap step. The rest of the surface is large: the .PHONY line names 103 targets, from `up-web`, `up-lite` and `down` through parser launchers, test and lint targets, migration commands, Dify console checks, plugin release gates, quality checks with names like `mixed-rag-quality` and `live-core-release-gate`, and diagnostics ending in `doctor`.
The interpreter handling is deliberate. The Makefile prefers `.venv/bin/python` whenever it exists, and the comment says why: a missing package should fail inside the project environment rather than silently falling back to an unrelated global tool. On Windows the paths become `python` and `.venv/Scripts/python.exe`, and elsewhere `HOST_PYTHON` defaults to python3.11.
Two startup shapes are documented. Docker one-click is the recommended path, with the frontend, API, worker and dependency services all in containers, started by
make up-web
make api-ping
and the UI lands on http://localhost:3000 with API docs on http://localhost:8000/docs. Source development mode keeps the API in a venv and the web app under pnpm while Docker runs only the infrastructure. Shutdown has three depths: `make down` stops, `make docker-reset` clears persistent data, and `make docker-purge` also removes this project's service images, with the last two documented as unrecoverable. The Compose project name is pinned to `mimirq` so a co-located Dify on the same machine is not mistaken for part of this deployment.
Ten extra parsers, ten containers, and one port they cannot share
The built-in DeepDoc handles ordinary PDF, Office and text with no extra container. Everything heavier is opt-in, one make target each: Docling Serve for tables, formulas and complex layout on CPU, Docling Serve CUDA for the same on GPU with CUDA 12.8 by default, Marker for PDF to Markdown without a GPU, ETL4LLM for mixed layout documents, PaddleOCR-VL for scans and OCR, MinerU pipeline and MinerU VLM, olmOCR for high-precision OCR, MagicPDF for formula and table PDFs, and Qianfan-OCR, which calls an external service and needs no local GPU at all.
The resource numbers attached to those targets are the practical part. PaddleOCR-VL is told to reserve about 10 GiB, olmOCR is recommended for a 48 GiB-class GPU, MinerU downloads models on first run, and the Docling GPU image is about 11.13 GB. The Docling note adds two constraints that decide whether you can run it at all: the heavy dependencies and models exist only in that separate container rather than the main image, and the CPU and GPU profiles share port 5001, so they cannot be started together.
The same note records where the Docling path was exercised: PDF, DOCX, Markdown tables and `ParserFactory` on an RTX 3070 Ti 8 GiB, with no fallback chain behind them. That is an honest boundary statement, and it also means a document type outside that list fails rather than degrading to the built-in parser.
Torch is pinned twice with identical versions and a CPU-wheel warning
requirements.txt pins everything exactly, with no version ranges anywhere in the visible portion. PyTorch appears four times as two versions duplicated across platform markers:
torch==2.13.0; platform_system == "Linux"
torch==2.13.0; platform_system != "Linux"
torchvision==0.28.0; platform_system == "Linux"
torchvision==0.28.0; platform_system != "Linux"
The identical pins are explained by the comment above them: installing torch from PyPI on Linux pulls the CUDA runtime libraries, which are huge and can exhaust CI runner or docker builder disk, so Linux installs are supposed to use the official CPU wheels and pass `--extra-index-url https://download.pytorch.org/whl/cpu`. Same version, different wheel source per platform, which is a workaround for installer behaviour rather than a compatibility difference.
The same pattern guards FAISS, which is excluded on Windows because no official wheels exist and is only used when `VECTOR_BACKEND=faiss`. Four database drivers are installed at once, asyncpg, psycopg2-binary, pymysql and pyodbc, alongside SQLAlchemy and Alembic, so the database story is Postgres-first with MySQL and ODBC reachable rather than one backend. numpy is held at 2.4.4 with a comment to keep it on the tested line for the current parsing and ML stack, and MagicPDF is called out as an optional heavy local parser to install separately when `MAGIC_PDF_ENABLED=true`.
One line does not add up. A comment above the `langgraph==1.2.4` pin records that the USTC mirror and PyPI currently provide up to 1.0.5 because 1.0.15 was never published, which describes a mirror that cannot serve the version pinned directly beneath it. Either the note belongs to a different package or it is stale, and either way it is the kind of comment that costs someone an afternoon.
DATABASE_URL ships a password that POSTGRES_PASSWORD leaves blank
.env.example is the most useful file in the repository, because each key carries a note about when to change it. The contradiction is in the first section. `DATABASE_URL` is shipped as `postgresql://postgres:postgres@localhost:5432/mimirq`, embedding a password in the connection string, while `POSTGRES_PASSWORD` is deliberately empty with a comment saying production must set a strong password and not keep the Compose default. The default URL therefore encodes the default password that the variable below refuses to set, so a first run connects with the value nobody was supposed to keep.
Two migration toggles carry the same shape of warning. `MIMIRQ_DB_CREATE_ALL_ON_STARTUP` and `MIMIRQ_DB_RUNTIME_MIGRATIONS_ENABLED` both default to true, and both are marked as fine for local and development use but mandatory false in production, where `make db-upgrade` has to be run separately before the API or worker starts. Schema changes by default happen because the process started; the escape is to turn that off and run Alembic yourself, and alembic.ini plus the alembic/ directory at the root are what you point it at.
The rest of the defaults describe the container topology. `MILVUS_IMAGE` is pinned to milvusdb/milvus:v2.6.11 with a note about switching to a trusted mirror when Docker Hub is unreachable, the internal host and port are `mimirq-milvus` and 19530, MinIO is enabled by default, `DOCKER_BUILD_NETWORK` defaults to `default` with `host` reserved for Linux loopback proxy setups, and the npm registry points at registry.npmmirror.com, which is the clearest single signal that this is a project built for a Chinese-first deployment.
up-lite drops Milvus and MinIO, and a new embedding model invalidates every index
For a machine that cannot spare the full stack, `make up-lite` swaps Milvus for Chroma or FAISS, skips MinIO, and ships without the frontend. It is aimed at verifying that the API reports ready and that `make core-e2e` closes the minimal loop, with `make web` run separately when the UI is needed. External LLM and embedding calls still need provider keys, so low-resource means less local infrastructure, not less model dependency.
The consequence to plan around sits in the same paragraph: after changing the embedding model you must rebuild the existing knowledge base indexes. That is not a documentation nicety in a system where retrieval quality is measured against a Golden question set; a swapped embedding silently invalidates every stored vector, and the fix is a rebuild rather than a reindex.
Source development is the other documented path, and it is the one that assumes a workstation:
make setup-hostThen two terminals:
# Terminal 1: FastAPI (hot reload)
make backend

# Terminal 2: Next.js (hot reload)
make web
`make setup-host` creates the venv, installs pip and pnpm dependencies, prepares the parsing models and starts the Docker infrastructure, which here means PostgreSQL, Redis and Milvus. By default the API runs its background tasks in-process, which is why two terminals are enough. Verification is `make api-ping` and shutdown is `make infra-down`. The stated floor for source mode is Python 3.11, Node.js 20 and pnpm 10.26, on top of Docker 20.10, Compose 2.0, GNU Make, 4 CPU cores, 16 GB of RAM and 50 GB of disk.
Breadth numbers are quoted, then disclaimed as breadth
The repository advertises 30 parsing backends, 86 chunking strategies, 13 categories of reranker, and a fixed 800-question measured evidence set. The sentence that follows is the important one: the numbers are only the breadth of the implementation, and the real claim is that each step can be inspected for inputs and outputs, traced back to citations, and tied to a version through the Golden question set and quality gates.
The pipeline it describes runs in a fixed order: data evaluation first, then scenario-specific parsing, cleaning and governance, business-oriented chunking, vector and full-text indexing, hybrid recall, reranking with citations, and Golden regression at the end. The chunking rule is the one that contradicts common practice: chunks follow headings, sections, business records or parent-child relationships rather than a uniform length with an overlap window, which is why there are 86 strategies rather than one.
Governance sits between parsing and chunking and comes in three forms, scripts, a rule DSL, or plugins. The index layer can be Milvus or something else, combining BM25, vector retrieval and reranking, and the application above it can be Dify, LangGraph, PydanticAI or a plain API service. The stated origin is a government knowledge base delivery, where a wrong answer had to be attributed to parsing, governance, chunking, recall, reranking, or generation drifting from its citation, which is the reason the Trace exists at all.
Dify integration is two shapes, and it declines to draw the canvas
MimirQ positions itself as a governable RAG layer under an existing application rather than a workflow builder, and it is explicit about not reimplementing the canvas. Two integration shapes are supported. The External Knowledge API leaves orchestration and generation to Dify and gives MimirQ document governance, retrieval, reranking, permission filtering and evidence return. The Workflow HTTP node inverts the split: Dify owns the custom routing and parameters, and MimirQ returns evidence and Trace for the knowledge scope it is asked about.
Permission filtering in the first shape is the detail that changes what you can build on top. Evidence comes back already filtered, so a tenant rule enforced in MimirQ does not have to be reimplemented in the calling application, and the Trace travels with the answer in the second shape, which is what makes a wrong answer diagnosable after the fact.
The platform comparison table is unusually blunt about when not to use it. For a simple business, a stable process and low-code preference, Dify or FastGPT are usually faster. For DeepDoc plus GraphRAG used together, RAGFlow is the mature choice. MimirQ is for a knowledge chain that needs per-business replacement, auditing and regression, either on its own or as an external knowledge layer for Dify. The repository also ships four READMEs, Simplified Chinese, English, Japanese and Korean, a docs directory, a separate docs-site, and DESIGN_PLAN.md and DESIGN_MEMORY.md at the root.
Editorial conclusion
MimirQ fits a team that has to say why a retrieval answer was wrong, that needs parsing and chunking swapped per document type, and that wants a fixed question set gating releases. It does not fit a quick prototype, a laptop without 16 GB of RAM, or a team that wants one process and one command. Before adopting it, read .env.example line by line and set a real database password instead of inheriting the one in DATABASE_URL, turn off both schema-creation toggles in production and run `make db-upgrade` deliberately, decide which parser containers you will actually fund on GPU, and confirm which version you are deploying, since the README names v1.0.1 while the newest published tag is v1.0.0.
Frequently asked questions
What are the system requirements for MimirQ?
Docker 20.10 or later and Docker Compose 2.0, GNU Make, and at least 4 CPU cores, 16 GB of RAM and 50 GB of disk. The Docker one-click path also needs Python 3.9 to generate configuration, while source development needs Python 3.11, Node.js 20 and pnpm 10.26.
How do I start MimirQ with Docker?
Clone the repository, run make init, edit the generated .env, then make up-web and make api-ping. The frontend is on http://localhost:3000 and the API docs on http://localhost:8000/docs. Stop with make down, clear data with make docker-reset, or remove service images with make docker-purge, the last two being unrecoverable.
Which document parsers can MimirQ use?
The built-in DeepDoc covers ordinary PDF, Office and text with no extra container. Optional containers add Docling Serve on CPU or CUDA, Marker, ETL4LLM, PaddleOCR-VL, MinerU pipeline, MinerU VLM, olmOCR, MagicPDF and Qianfan-OCR, each started by its own make target.
Does MimirQ replace Dify?
No. It can act as Dify's external knowledge layer through an External Knowledge API, where Dify orchestrates and MimirQ handles governance, retrieval, reranking, permission filtering and evidence, or through a Workflow HTTP node where Dify owns routing and MimirQ returns evidence and Trace.
What happens to existing indexes when I change the embedding model in MimirQ?
Existing knowledge base indexes have to be rebuilt. The low-resource mode make up-lite, which replaces Milvus with Chroma or FAISS and skips MinIO, is the documented way to verify API readiness and the make core-e2e loop on a smaller machine.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/skygazer42-mimirq)Star history chart for your README
[](https://hysenlabs.com/projects/skygazer42-mimirq)Was this useful?