WebLLM: Running LLM Inference in the Browser with WebGPU
High-performance In-browser LLM Inference Engine
At a glance
- What is it?
- WebLLM brings OpenAI-compatible chat completions to the browser using WebGPU, but it carries real constraints around model size, memory, and setup that engineers must weigh before adopting it.
- Who is it for?
- Adopt WebLLM if your application must keep all user data client-side, needs to avoid server inference costs, or targets users with capable WebGPU hardware and sufficient RAM. Do not adopt it if your audience includes older devices, Safari users without WebGPU, or scenarios where multi-gigabyte model downloads are unacceptable.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
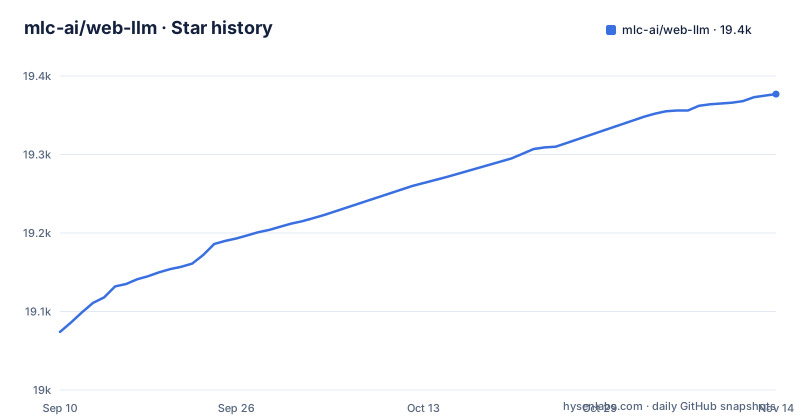
Star history
- mlc-ai/web-llm19,377 ★ · +303
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| mlc-ai/web-llm | 19.1k | 19.4k |
303 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What WebLLM Actually Solves
WebLLM targets a specific pain point: running LLM inference entirely inside a web browser without any server-side processing. The README is explicit that everything runs in the browser and is accelerated with WebGPU. This matters for applications where privacy is a hard requirement, where you cannot rely on a backend, or where you want to avoid the cost and latency of sending prompts to a remote API. The intended audience is front-end developers building AI assistants, chatbots, or tools that need local model execution. The project is a companion to MLC LLM, which handles broader hardware deployment, but WebLLM narrows the focus to WebGPU-capable browsers. If your use case does not involve a browser front end, or if your users cannot access WebGPU, this library is not the right starting point.
The Mechanism: WebGPU, MLC Format, and an OpenAI-Compatible API
The core of WebLLM is the MLCEngine interface. You create an instance, load a model, and then call chat completion methods that mirror the OpenAI API. The documentation states that WebLLM is fully compatible with the OpenAI API, supporting streaming, JSON-mode, function-calling (marked as WIP), logit-level control, and seeding. Under the hood, the model weights are compiled into the MLC format, which is a specific representation that WebLLM can load and execute. The inference itself runs on WebGPU, the browser's GPU compute API. Structured JSON generation is implemented in the WebAssembly portion of the model library, according to the README, which suggests that some parts of the pipeline run in WASM rather than directly in WebGPU. The precise interaction between the WebGPU kernels, the WASM modules, and the JavaScript engine is something you would need to inspect in the source or docs.
Getting It Running: Install, Import, and Model Loading
Installation is standard for an npm package. The README shows npm install @mlc-ai/web-llm, yarn add @mlc-ai/web-llm, or pnpm install. You can import the whole module with import * as webllm from "@mlc-ai/web-llm" or selectively import CreateMLCEngine. For quick prototypes, a CDN import from esm.run works directly in environments like JSFiddle or CodePen. The README also points to a deployed chat demo at chat.webllm.ai, which is the fastest way to see the library in action without writing code. Once installed, you create an engine by calling CreateMLCEngine, which loads a model. The README's example passes a model identifier, "Llama-3.1-8B-Instruct-q4f32_1-MLC", and an engineConfig with an initProgressCallback; loading the model requires a download that can take significant time on the first run without caching. The examples folder is meant to show the full flow, including how to handle streaming responses. For an advanced reference, the WebLLM Chat repository contains a larger client implementation.
Model Support and the Prebuilt List Boundary
WebLLM does not run every model you can find on Hugging Face. It supports a subset of the models available on MLC Models, and the list is stored in prebuiltAppConfig.model_list in the source. The README names several families: Llama 3, Llama 2, Hermes-2-Pro-Llama-3, Phi 3, Phi 2, Phi 1.5, Gemma-2B, Mistral-7B-v0.3, several Hermes and OpenHermes variants, and Qwen2 in 0.5B, 1.5B, and 7B sizes. This is a real constraint. If you need a model outside that list, you have two paths: request it via a GitHub issue, or compile your own model into MLC format. The custom model route is not trivial; it requires using the MLC LLM toolchain to convert weights, which adds a build step to your workflow. The practical takeaway is that WebLLM is not a universal model runner. You must check the prebuilt list first, and if your target model is absent, you are committing to a compilation pipeline, which the README points to in its Custom Models section.
Where It Breaks: Memory, Download Size, and WebGPU Availability
The most obvious limitation is hardware dependency. WebGPU is not available in every browser, and even where it exists, GPU memory is finite. Running a 7B model, like Qwen2 7B or Llama 3, requires several gigabytes of VRAM and a matching download of weights. On a typical laptop with integrated graphics, a 7B model will likely be too slow or fail to load. The README describes acceleration through WebGPU, so check WebGPU availability on your target browsers. The README also notes that function-calling is WIP, which means that part of the OpenAI API surface is not fully stable. JSON mode is described as state-of-the-art, though that is the project's own claim. Another failure mode is the initial download latency. Loading a model requires downloading it, which the README says can take a significant amount of time on the first run without caching, which is a poor experience for users who expect instant interactions. The library does support service workers and web workers to offload computation and manage model lifecycle, but that adds implementation complexity.
The Alternative: Server-Side Inference or WebGPU-Only Runtimes
The obvious alternative to WebLLM is running an LLM on a server, either with a proprietary API like OpenAI or with an open-source serving framework like vLLM or llama.cpp. The difference in approach is fundamental. Server-side inference keeps the model weights on a machine with dedicated GPUs, so the client only sends text over the network. That means no download, no VRAM limit on the client, and no WebGPU dependency. But it also means the user's prompts leave the browser, which defeats the privacy benefit that WebLLM advertises. A second alternative is a different in-browser runtime that does not require WebGPU, such as ONNX Runtime Web with WebAssembly. That approach trades performance for compatibility: it runs on more devices but is slower for large models. WebLLM's choice to bet on WebGPU is a performance-first decision, and the README's emphasis on hardware acceleration makes that clear. If your priority is maximum browser coverage over raw speed, a WASM-based runtime might be a better fit, though it will struggle with models larger than a few billion parameters.
Maintenance, Licensing, and Upgrade Considerations
The repository shows active maintenance, with the last push on November 2, 2026, and recent releases v0.2.87, v0.2.86, and v0.2.85. That cadence suggests ongoing fixes and feature work, but it also means you should expect frequent updates. The API is not frozen at version 0.2.x, so minor releases may introduce breaking changes. The project is licensed under Apache-2.0, which is permissive for commercial use, but you should verify how the MLC model format and any compiled weights are licensed separately, since model licenses vary. The README points to a paper and a blog post, which are useful for understanding the underlying techniques, but those are not substitutes for reading the changelog before upgrading. The package is distributed on npm, so you can track versions easily. One cost to consider is the size of the npm package itself plus the model weights. The library code is small, but the models are not bundled; they are fetched at runtime, which means your deployment must handle dynamic, large downloads. If you are building a Chrome extension, the README mentions examples exist, but the memory and storage limits of extension contexts may require careful engineering.
Editorial conclusion
Adopt WebLLM if your application must keep all user data client-side, needs to avoid server inference costs, or targets users with capable WebGPU hardware and sufficient RAM. Do not adopt it if your audience includes older devices, Safari users without WebGPU, or scenarios where multi-gigabyte model downloads are unacceptable. Before committing, verify that your target models are in the prebuilt list or that you can compile custom models with MLC LLM, and check the actual memory footprint of your chosen model on your lowest-spec target device. WebLLM is a serious engineering effort with a clear API and active maintenance, but it is not a drop-in replacement for server inference unless your users' hardware can handle it.
Frequently asked questions
Can I run an LLM in the browser?
That is what WebLLM is for. It is a high-performance in-browser LLM inference engine that brings language model inference onto web browsers with hardware acceleration: everything runs inside the browser with no server support and is accelerated with WebGPU, behind an interface that is OpenAI API compatible.
What is a web LLM?
In WebLLM's case, a language model running on WebGPU inside the browser tab with no server support, exposed through an `MLCEngine` interface created by the `CreateMLCEngine()` factory. Loading a model downloads it, which can take a significant amount of time on the first run without a cache, and the `initProgressCallback` is how you report progress while it happens.
How do I install and import WebLLM?
Install the package with `npm install @mlc-ai/web-llm`, or yarn or pnpm, then import it as `import * as webllm from "@mlc-ai/web-llm"` or import only what you need with `import { CreateMLCEngine } from "@mlc-ai/web-llm"`. It can also be loaded from a CDN with a dynamic `await import("https://esm.run/@mlc-ai/web-llm")`.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- I put a real LLM in my portfolio. It runs on your GPU, not my server.dev.to · Nov 13, 2026 · 2 points · 0 comments
- OutThere: meet new people, make real friends and practice languages outdoors, with Gemma running in your browserdev.to · Oct 12, 2026 · 2 points · 0 comments
- GrassRoute: The Zero-Signal Outdoor Companion & Trail Naturalistdev.to · Oct 11, 2026 · 5 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mlc-ai-web-llm)Star history chart for your README
[](https://hysenlabs.com/projects/mlc-ai-web-llm)Was this useful?