A version string that encodes your CUDA build, tags that skip 0.4.0, and code on branches
Model compression toolkit engineered for enhanced usability, comprehensiveness, and efficiency.
At a glance
- What is it?
- AngelSlim is Tencent's model compression toolkit, and its English front page reads as a dated news log rather than documentation: fourteen entries from January to September 2026, most of them one-line announcements with paper and docs links. The packaging tells a sharper story than the page does.
- Who is it for?
- AngelSlim is worth reading for anyone doing post-training compression, because the project publishes weights, papers and per-model configs rather than only code, and the documentation is organised by feature. Three things to settle before relying on it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
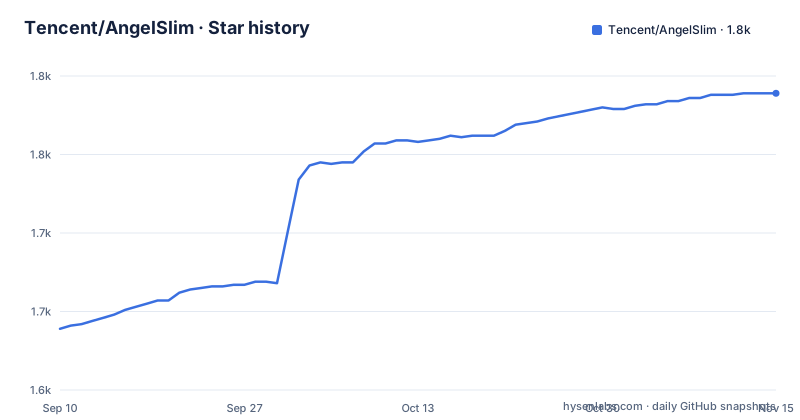
Star history
- Tencent/AngelSlim1,789 ★ · +150
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| Tencent/AngelSlim | 1.6k | 1.8k |
150 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The PyPI version string encodes the CUDA and torch build
The packaging file treats the version as something to compute rather than to declare, and the comment explaining why is unusually specific. A source distribution ships a top level `PKG-INFO` whose `Version:` line already holds the fully resolved version, including a local segment shaped like `+cuXXX.torchY`. When pip's build backend re-runs `setup.py` from the extracted archive, the helper reuses that line verbatim. The file gives two reasons: recomputing would call `git` inside a tree that is not a git checkout, and it would append the local segment a second time, producing an invalid double local version. A fresh checkout has no `PKG-INFO`, so that path returns nothing and the git based computation runs instead, which is the branch that is cut off partway through. The practical consequence is that the version you see in a pip list is telling you which CUDA and which torch the package was built against.
The tag trail goes 0.2.0, 0.3.0, then 0.5.0
Three releases are recorded: v0.2.0 on 2025-11-05, v0.3.0 on 2026-01-13 and v0.5.0 on 2026-06-22. There is no v0.4.0 among them, so a minor version is not represented in the tag history, which leaves the numbering harder to reason about than a clean sequence would. The gap between the newest tag and the branch is also worth noting: the default branch was last pushed on 2026-10-01, more than three months after v0.5.0. The news entries describe what changed in that window, and they run well past the last release, with the most recent dated 2026-09-01. That is the shape to expect here: the page tracks work in flight, and the tags do not.
Several algorithms are only reachable on named branches
Two of the announced quantization methods are not linked from the default branch. Sherry, described as a hardware efficient 1.25 bit quantization algorithm, is pointed at as `Tencent/AngelSlim/tree/sherry/Sherry`. TEQUILA, the ternary quantization algorithm, is pointed at as `Tencent/AngelSlim/tree/tequila/TernaryQuant`. Both links are by branch path rather than by tag, which means the code behind those papers sits outside `main` and outside every release. Two other items are contributions outward rather than inward: a kernel for 1.25 bit models was offered as a pull request to llama.cpp, and the SpecExit early exit reasoning algorithm has a matching pull request against vLLM. The root listing carries a `.gitmodules` file and a `third_party/` directory, so part of the build comes from elsewhere, and which parts depends on the branch you checked out.
The English page routes most documentation links through /zh-cn/latest/
The language switch at the top offers a Simplified Chinese readme at `README_cn.md`, which is the normal arrangement. The links inside the English page are not. The documentation links attached to the quantization, distillation, speculative decoding and sparse attention announcements are written as `angelslim.readthedocs.io/zh-cn/latest/...` paths, while the banner at the top links the same site at its root, `angelslim.readthedocs.io/`, and points at the Chinese readthedocs configuration through a `.readthedocs.yaml` in the tree. A reader following the English page is therefore sent into the Chinese documentation tree by nearly every feature link, with the path still resolving because the site publishes both. It is a small thing, and it is the kind of detail that only shows up when you follow the links rather than read the index.
1.5TB becomes 214 GiB, and then the number that matters is 1.02 tokens per second
The headline entry, dated 2026-09-01, announces a preview MIX-STQ1_0 build of Hunyuan4 compressed from 1.5TB to 214 GiB with a stated 0.7 percent drop on SWE-bench Pro. The same entry then gives the deployment reality: the 214 GB model was run through Prima.cpp on a laptop 4090 with 32GB of RAM and 16GB of VRAM, together with a server carrying four A4000s with 32GB of RAM and 16GB of VRAM each, at 1.02 tokens per second. Read together, the two figures describe a working demonstration rather than a usable serving configuration. The compression ratio is the headline, the tokens per second is the qualifier, and both numbers appear in the same bullet for a reason. The entry links a blog, a deployment guideline inside this repository's docs tree, and the weights themselves on the Hugging Face organisation.
Fourteen dated entries are the index to the whole toolkit
The front page is a news log with no table of contents, and the entries are the only way to see what exists. Compression spans post training quantization at FP8 static, SmoothQuant for Hy3, NVFP4 for the Qwen3 series, and W4A8-FP8, plus low bit paths at 2 bit, 1.25 bit through the STQ1_0 kernel and Sherry, and ternary through TEQUILA. Distillation appears twice, once as quantization aware distillation on Megatron-Core for Qwen3-MoE and Hy3 with TP, EP, CP and SP parallelism, and once for full precision HuggingFace models alongside quantized QAT style ones. Speculative decoding has the widest spread: Eagle3 training and deployment for LLMs, VLMs and audio models, the MTP and DFly drafters for Hy3-A21B released through a separate torch native framework called AngelSpec, block diffusion decoding called DFlare, adaptive verification depth pruning called D-Cut, and the SpecExit early exit. Sparse attention is the fourth area, with Stem for the prefill stage.
Licence metadata, the LICENSE file and the file header do not agree
No licence value appears anywhere in the repository metadata, which is what NOASSERTION means rather than a statement that the code is unlicensed. The root listing does contain a `LICENSE` file, and `setup.py` opens with a header naming the Apache License, Version 2.0, along with the standard permissions notice and the URL. Those three records do not line up, and this page does not pick a winner among them. For anyone planning to use the released weights rather than the code, that matters more than usual: the weights sit on a Hugging Face organisation and a ModelScope organisation under the same name, and the compression recipes are published alongside papers, so the terms for each artifact have to be checked where it is actually hosted. The repository itself keeps the usual release plumbing around it, with `MANIFEST.in`, a `.pre-commit-config.yaml` and a `.readthedocs.yaml`.
Configs are organised per model family, and the tree splits data from evaluation
The root listing has twenty entries and only three of them are files you would read: the two readmes and the setup script. The rest are directories with a clear division of labour. `angelslim/` holds the package, `scripts/` the entry points, `configs/` the recipes, and the news entries point into it by model family, with separate directories for FLUX and for Seed-OSS. Alongside those sit `dataset/`, singular, for input data, `evaluation/` for measurement, `requirements/` as a directory of requirement files rather than one list, `tests/`, `tools/`, `docs/` and `third_party/`. Separating requirements into their own directory is what lets a feature branch like `tequila` or `sherry` add its own pins without colliding with everyone else, and it is also why the two branch linked algorithms can diverge from the main dependency set. Installation is not written on the front page; the package is on PyPI and the documentation site is `angelslim.readthedocs.io`, with weights distributed through the Hugging Face and ModelScope organisations.
Editorial conclusion
AngelSlim is worth reading for anyone doing post-training compression, because the project publishes weights, papers and per-model configs rather than only code, and the documentation is organised by feature. Three things to settle before relying on it. First, the licence is not stated consistently: the metadata carries no value, the root has a LICENSE file, and the setup.py header names Apache 2.0, so take the terms from the file in the tree rather than from any of the other two. Second, several algorithms are only reachable on named branches, so check which branch you are reading before comparing it to a paper. Third, the headline compression figures come with a throughput figure of 1.02 tokens per second, which is the number that tells you whether the ratio matters for your workload.
Frequently asked questions
What is AngelSlim used for?
It is Tencent's model compression toolkit, covering post training quantization, including FP8 static, NVFP4, SmoothQuant, 2 bit, 1.25 bit and ternary work, plus quantization aware distillation, speculative decoding methods such as Eagle3, MTP and DFly, and a sparse attention algorithm called Stem.
Why does the AngelSlim version string carry a local segment?
The packaging computes the version from git and appends a local segment shaped like +cuXXX.torchY, so the version records the CUDA and torch build. When pip rebuilds from an sdist it reuses the Version line in the shipped PKG-INFO instead, to avoid calling git in a non git tree and to avoid appending the segment twice.
Which AngelSlim algorithms live outside the main branch?
Sherry, the 1.25 bit quantization algorithm, is linked as a branch path at tree/sherry/Sherry, and TEQUILA, the ternary algorithm, at tree/tequila/TernaryQuant. Neither link points at main or at a release tag.
What licence applies to AngelSlim?
The records do not agree. The repository metadata carries no licence value, the root listing contains a LICENSE file, and the setup.py header names the Apache License, Version 2.0. Check the file in the tree rather than assuming the metadata is authoritative.
What speed did the compressed Hunyuan4 preview model actually run at?
The 2026-09-01 entry reports a 1.5TB model compressed to 214 GiB with a stated 0.7 percent drop on SWE-bench Pro, and reports 1.02 tokens per second when that 214 GB build was run through Prima.cpp on a laptop 4090 plus a server with four A4000 cards.
Where are AngelSlim model weights published?
On a Hugging Face organisation and a ModelScope organisation both named AngelSlim, linked from the front page banner alongside the technical report on arXiv at 2602.21233 and the documentation site.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tencent-angelslim)Star history chart for your README
[](https://hysenlabs.com/projects/tencent-angelslim)Was this useful?