AnkiAIUtils is a pile of scripts the author hopes someone packages into an add-on
AI-powered tools to enhance Anki flashcards with explanations, mnemonics, illustrations, and adaptive learning for medical school and beyond
At a glance
- What is it?
- Six Python files that add AI fields to Anki cards you keep failing, with a requirements list that names the same string library twice and one line you may have to comment out. The release note says the scripts may be broken, the documentation was written with an AI coding tool, and the intended form is an add-on with a GUI the author did not have time to build.
- Who is it for?
- AnkiAIUtils fits a medical student who already runs Anki, already has API keys for an image model, and is willing to read a script before running it against a collection. It does not fit anyone who wants a button in Anki, because that is exactly what the author says is missing, and it does not fit a shared or synced collection without thought, because the scripts write new fields into your notes.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 167 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
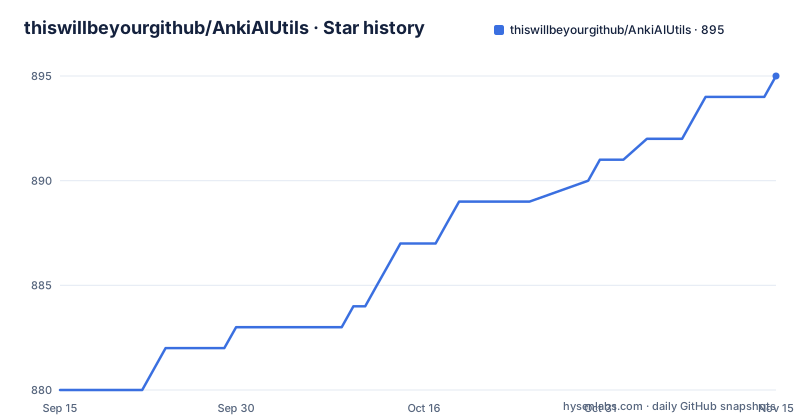
- thiswillbeyourgithub/AnkiAIUtils895 ★ · +15
| Repository | 2026-09-15 | 2026-11-15 |
|---|---|---|
| thiswillbeyourgithub/AnkiAIUtils | 880 | 895 |
15 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The release note asks for help building the thing it should have been
The most honest paragraph in the file is the developer's note. The scripts are described as the culmination of efforts to add the AI features the author wished existed when starting medical school, followed by three admissions: they should all be working, but they were released hastily after being documented heavily with the help of the aider coding assistant; the documentation may be slightly off or imprecise; and some of the scripts may be slightly broken during the release process. Then the reason for publishing in this form. The stated hope is to motivate other people to package the scripts into add-ons, because the author has too little time to learn how to do that packaging or to build the appropriate GUI, and asks for help with the TODO list. So the current state is intentional as a stopgap and unfinished on purpose, which is worth knowing before you spend an evening on it. Two smaller signals sit in the same territory: the default branch is called `public` rather than `main`, and the repository publishes no releases.
Six scripts at the root, and each one owns a dataset
The top level is a flat list of Python files, which is what a collection of scripts looks like before it is a package. There is `illustrator.py`, the image one, `reformulator.py`, the rewording one, `explainer.py`, `mnemonics_creator.py`, `mnemonics_helper.py` for managing the mnemonic library, and `anchors_to_anki.py`, plus `utils/`, `tests/` and `screenshots/`. Under `examples/` each tool has a matching text file of examples, `explainer_dataset.txt`, `illustrator_dataset.txt`, `mnemonics_dataset.txt`, `reformulator_dataset.txt` and a second illustrator file for sanitising, with `anchors.json` alongside them and a `string_formatting.py` helper. There is also `anki_ai_utils_tmux_launcher.sh`, which tells you how the author expects several of these to be run at once, in panes. That dataset pattern is the design in one line: these tools are few-shot prompts with a dataset file, not a pipeline with configuration.
Anki is reached over a bridge, and the page never says so
The dependency list contains `py-ankiconnect`, a client library for the AnkiConnect bridge, which is how a running Anki instance is reached programmatically. The feature list puts the same idea the other way round, saying the tools modify Anki notes directly in place, which works across all clients on Windows, Mac, Linux, Android and iOS, and that extensive logging lets you track changes and roll back if needed. Put together, that means there is no collection file to copy and no sync to break, and also that something has to be listening. A reader who installs the requirements and runs a script against a closed Anki has a connection problem before they have a model problem, and the page does not walk through the bridge as a prerequisite the way it walks through model choice. The rollback claim also deserves a test on your own collection, since the logging is the only stated way to see what changed.
Datasets are the interface, and semantic similarity picks from them
There are no command lines on the visible page. What there is instead is a set of dataset files, one per tool, and a stated selection mechanism. The adaptive learning feature works by using semantic similarity to match each card with the most relevant examples from your training datasets, and the promise attached is that the more examples you add, the better it gets. The infographic feature is worded the same way, calling the datasets infinitely extensible because the semantic filtering picks the relevant ones automatically. Two consequences follow for anyone using this. The first run's output is a function of the dataset files as much as of the model, so the fastest way to improve results is to edit text in `examples/` rather than to change a prompt. And a dataset intended as training material for a medical student is also a record of what that student found memorable, which is worth reading before importing it wholesale.
The illustrator prints its reasoning in English whatever the card says
The example output is the most revealing part of the page. Given a French flashcard on the diagnostic criteria for simple febrile seizures, `illustrator.py` produces a block of text with four labelled parts: the topic, the anchors, the phonetic substitutions, and remarks. The phonetic line is a major-system mapping, 1 to T as in Thai or tea, 3 to M as in mow, 8 to F as in fire, 5 to L as in low. The remarks then decompose the criteria one by one into images built on those substitutions, a toddler holding a teacup for age over one year, a thermometer with flames around it for a seizure with fever above 38 degrees. Then the parenthetical that matters: that text is always in English no matter the language of the original card. So the reasoning is not localised, which is convenient for an English-speaking user and meaningless to a learner working in another language, since the image is the part that is supposed to carry the memory. The tool supports DALL-E2, DALL-E3 and Stable Diffusion, keeps a history of generated images, and formats and lays out multiple images per card.
The reformulator rewrites wording and keeps the cloze intact
The second tool edits cards rather than adding to them. Its job is to rephrase a card while preserving its core meaning and structure, and the four situations given for it are a card that is poorly worded or unclear, a desire to vary phrasing to strengthen recall, a need for concision, and a preferred format that has changed over time, which the page ties to medical school specifically, saying your idea of a perfect flashcard often evolves after a few semesters. What it promises to preserve is cloze deletions and media, which is the constraint that makes it safe on a mature collection. The worked example is a radiology card written as a fragment, rewritten into a full question with the answer expanded inside the cloze marker, and then shown a third time as a bullet list with a much shorter cloze. All three versions come from one input, which is the feature: the same knowledge, rephrased to whatever shape your current template wants.
The requirements list names one library twice and asks you to edit it
The dependency file is where a hurried release shows. `Levenshtein>=0.24.0` and `python_Levenshtein >= 0.25.0` both appear, which are two names for the same string-distance library rather than two different ones, so one of them is redundant. Then there is a line with a comment in it:
stability-sdk>=0.8.5 # if encountering grpcio install errors, comment this lineThat is a known-bad install path with a manual workaround written into the manifest, and a fresh `pip install -r requirements.txt` on a machine with a mismatched grpcio will fail unless you edit the file. The rest of the list is coherent and tells you what the scripts do: `litellm` for provider-agnostic model access, `Pillow` and `bs4` for image and HTML handling, `scikit-learn` and `rapidfuzz` for the similarity matching, `tiktoken` for counting, `tqdm` and `tqdm-logger` for progress, `fire` for the command line, and `pudb` for a debugger, which is what you will want given the author's own note about scripts that may be broken. The license is AGPL-3.0, a stronger copyleft than the scripts' casual structure would suggest.
Editorial conclusion
AnkiAIUtils fits a medical student who already runs Anki, already has API keys for an image model, and is willing to read a script before running it against a collection. It does not fit anyone who wants a button in Anki, because that is exactly what the author says is missing, and it does not fit a shared or synced collection without thought, because the scripts write new fields into your notes. Four things to check before you run anything: that your Anki instance is reachable, since the dependency list includes a client for the AnkiConnect bridge and there is no file-level fallback; which model each tool will call, since text goes through LiteLLM and images through DALL-E2, DALL-E3 or Stable Diffusion; whether the datasets in `examples/` are the ones you want driving the output, because the tools pick their few-shot examples by semantic similarity and the quality of the result follows those files; and the version you are reading, since the repository publishes no releases, sits on a branch called `public`, and its last commit is dated June 1, 2026. The license is AGPL-3.0, which matters if you ever redistribute it as a service or an add-on.
Frequently asked questions
What is AnkiAIUtils?
A collection of Python scripts that add AI-generated fields to the Anki cards you keep failing, namely explanations, mnemonics and illustrations, tested through medical school. The author describes it as scripts rather than an add-on and asks for help packaging it into one.
Do I need an Anki add-on to use AnkiAIUtils?
Something has to be listening, because the dependency list includes py-ankiconnect, a client for the AnkiConnect bridge. The scripts modify notes in place so every client sees the change, which means a running Anki rather than an edited collection file.
Which models do the AnkiAIUtils tools call?
The illustrator supports DALL-E2, DALL-E3 and Stable Diffusion, while text work goes through LiteLLM so any provider and model it routes to can be used. The requirements also carry stability-sdk with a comment telling you to remove that line if grpcio install errors appear.
How does AnkiAIUtils choose examples for a card?
By semantic similarity. Each tool has its own dataset file under `examples/`, and the filtering selects the entries most relevant to the card, which is why the page says the more examples you add, the better the result.
Is AnkiAIUtils finished?
The author's note says the scripts were released hastily after being documented with the help of aider, that the documentation may be imprecise, and that some scripts may be slightly broken. Publishing in this form is meant to motivate someone else to package them into add-ons with a GUI.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thiswillbeyourgithub-ankiaiutils)Star history chart for your README
[](https://hysenlabs.com/projects/thiswillbeyourgithub-ankiaiutils)Was this useful?