llm-apps-java-spring-ai, a Gradle sample tree with crossed links
Samples showing how to build Java applications powered by Generative AI and LLMs using Spring AI and Spring Boot.
At a glance
- What is it?
- A Gradle multi-module set of Spring AI samples: five use cases on Ollama, with PGVector appearing only where retrieval is needed, and four chat and embedding providers against a single image provider. Two details are worth checking before you follow a link. The two audio entries point at each other's directories, and the guardrails paths are not in the top-level tree.
- Who is it for?
- Read llm-apps-java-spring-ai as a catalogue rather than something to adopt. There is no library to depend on and no releases published, the last push is dated 2026-10-01, and the module list in settings.gradle is the version of record.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
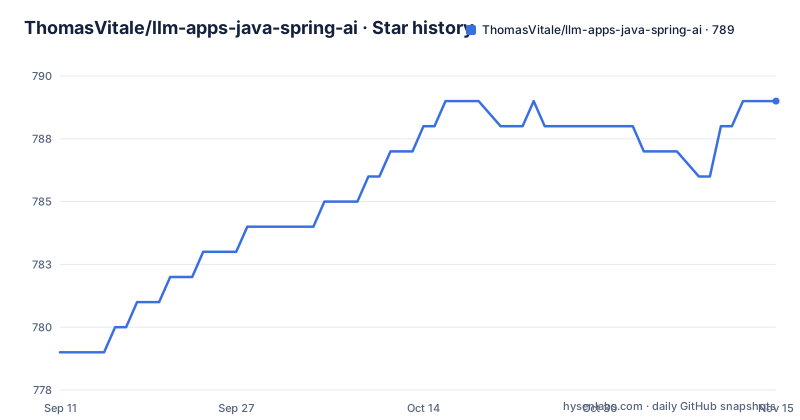
- ThomasVitale/llm-apps-java-spring-ai789 ★ · +10
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| ThomasVitale/llm-apps-java-spring-ai | 779 | 789 |
10 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The two audio entries point at each other's directories
The Audio Models heading holds two subsections and both have the shape wrong in the same way. The first is introduced as speech generation with LLMs via different model providers, and its only entry is OpenAI, whose link path ends in `models/audio/speech-to-text-openai`. The second is introduced as speech transcription, and its only entry is OpenAI, whose path ends in `models/audio/text-to-speech-openai`. The label and the destination are crossed: the generation heading lands in the transcription directory and the transcription heading lands in the generation one. Both introductions also promise different model providers while listing exactly one. Image Models has the milder version of the same shape, a single OpenAI entry under a section described as image generation with LLMs via different model providers. So the two audio samples exist under both names, and a reader arriving by label gets the wrong one first.
The PDF reader link and the Text reader link resolve to one path
Document Readers carries five entries: JSON, Markdown, PDF, Text, and Tika. The JSON, Markdown, and Tika paths carry their own names, so those three are unambiguous. PDF points at `data-ingestion/document-readers/document-readers-text-ollama`, and Text points at the same path. Two of the five entries therefore resolve to a single directory, and the destination is the one carrying the least specific name. Whether the PDF sample differs from the text sample is not something the link can tell you, because only one target exists between them. The section introduces all five the same way, as reading and vectorizing documents with LLMs via Ollama, so every entry sits on the same local model path and the entries differ only by reader type. The Document Transformers subsection that follows is where a different axis would come in, and its first entry is Metadata.
Guardrails are presented as a pattern but addressed at the repository root
Guardrails is the last subsection under the Patterns heading and it has two entries, Input Guardrails and Output Guardrails. Both links point into a top-level `guardrails` directory, at `guardrails/guardrails-input` and `guardrails/guardrails-output`. So a directory the page presents as a pattern is addressed as a sibling of `patterns/` rather than as a child of it. That has a consequence for the tree as well. The top level of the repository carries buildSrc, data-ingestion, the gradle directory with its wrapper, mcp, models, observability, patterns, rag, and use-cases, and no guardrails entry appears among them. Two directories in that list, mcp and observability, are also not named anywhere in the visible part of the page, and rag/ sits there as well while the use cases cover retrieval separately.
Three use cases need nothing but Ollama and two add PGVector
The five use cases split cleanly by how much stack they ask for. The chatbot runs on LLMs via Ollama. Structured data extraction and text classification also run on LLMs via Ollama and name nothing else. The two that need a datastore are question answering with documents, described as retrieval augmented generation, and semantic search, and both name Ollama and PGVector together. So the two-stack pair is the retrieval half and the single-stack pattern covers the other three. Nothing in the use case list names an OpenAI or a Mistral endpoint, even though the models section underneath offers four chat providers and four embedding providers. The provider spread lives one directory down, which means the top of the tree is deliberately local and the hosted options are demonstrated separately.
Three separate files pin the toolchain before Gradle runs
The build is Gradle, with `gradlew` and `gradlew.bat` for the wrapper, `settings.gradle` for the module list, `gradle.properties` for properties, and `buildSrc` for shared build code. Alongside those sit two environment definition files that exist for the same reason. `.sdkmanrc` is the SDKMAN per-project JDK pin, and `devbox.json` with `devbox.lock` is a Jetify devbox shell pinned with its own lock file. So a contributor has three version declarations to satisfy before Gradle says anything: the JDK line the SDKMAN file asks for, the tool set the devbox lock resolves, and the Gradle version the wrapper downloads on first run. The stated pre-requisites are Java 25 and Podman or Docker, with Podman named first, which is a specific pair rather than a range. No GitHub releases are published, so the module list is the version of record.
Moderation is the one model category with nothing behind it
Six model categories are named on the page. Chat has four entries, and they are the widest spread anywhere on the page: Mistral AI, Ollama, OpenAI, and a fourth sample covering multiple providers side by side. Embedding also has four, of which ONNX Transformers is the only entry on the whole page that names a runtime format rather than a vendor. Image has one entry. Audio has one per direction, both from the same vendor, with the crossed paths noted elsewhere. Moderation has none, and the section says coming soon in italics with no link and no further text. So four categories have samples, one is a single vendor, and one is a placeholder. The consequence for a reader is that the category list on the page is a wish list in at least one place, and a tool call that expects a moderation model will not find one here.
Most patterns pair two providers, memory switches to four mechanisms
The Patterns section opens with three flavours of prompting, each given for Ollama and OpenAI: plain text, structured messages with roles, and templates. Structured Output follows with the same pair, and its description names the conversion as going to structured JSON and Java objects. Multimodality, for including various media in prompts, carries three providers instead of two, Mistral AI, Ollama, and OpenAI, and those same three are the ones under Tool Calling. Memory then changes axis entirely: it is organised by storage mechanism rather than by provider, with Basic Chat Memory, JDBC Chat Memory, Spring Security Chat Memory, and Vector Store Chat Memory. So the same section mixes a provider axis with a mechanism axis, and the four memory entries are the only ones where you choose a backing store instead of a vendor.
Editorial conclusion
Read llm-apps-java-spring-ai as a catalogue rather than something to adopt. There is no library to depend on and no releases published, the last push is dated 2026-10-01, and the module list in settings.gradle is the version of record. It earns its place if you want one small runnable example per Spring AI capability, with Ollama doing the local work in every use case and PGVector showing up only in the two retrieval ones. Verify three things before you spend an afternoon on it. The two audio entries point at each other's directories, so the speech-to-text sample and the text-to-speech sample are not where their labels say. The PDF document reader and the text document reader share a single directory path, so two of the five reader entries resolve to one target. And the guardrails links address a top-level directory that does not appear in the tree listing, which means locating those two samples is your problem. Moderation models are marked as coming soon with nothing behind them. If you need a production service, this is not one: it asks for Java 25 and a container runtime with Podman named before Docker, and it assumes you already run a local model.
Frequently asked questions
What prerequisites does llm-apps-java-spring-ai need?
Java 25 and Podman or Docker, with Podman named first. The repository is a Gradle multi-module build with gradlew, settings.gradle, gradle.properties, and buildSrc, alongside an .sdkmanrc file for the JDK pin and devbox.json with devbox.lock for the development shell.
Which model providers does llm-apps-java-spring-ai cover for chat and embeddings?
Four each. Chat models cover Mistral AI, Ollama, OpenAI, and a multiple-providers sample. Embedding models cover Mistral AI, Ollama, OpenAI, and ONNX Transformers, the last being the only entry on the page that names a runtime format rather than a vendor. Image models have a single OpenAI entry, and moderation models are marked coming soon with no sample.
Which use cases in llm-apps-java-spring-ai need a vector database?
Two of the five. Question answering with documents and semantic search both name Ollama and PGVector together. The chatbot, structured data extraction, and text classification run on LLMs via Ollama and name no datastore at all.
How does llm-apps-java-spring-ai handle chat memory?
The memory pattern has four entries and is organised by storage mechanism rather than by provider: Basic Chat Memory, JDBC Chat Memory, Spring Security Chat Memory, and Vector Store Chat Memory. Elsewhere in the patterns section the axis is the provider, with Ollama and OpenAI paired for prompting, messages, templates, and structured output.
Does llm-apps-java-spring-ai publish releases?
No GitHub releases are published. The last push on the repository is dated 2026-10-01, the licence is Apache-2.0, and the version of record is the module list in settings.gradle rather than a tag.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thomasvitale-llm-apps-java-spring-ai)Star history chart for your README
[](https://hysenlabs.com/projects/thomasvitale-llm-apps-java-spring-ai)Was this useful?