OpenLTM ticks eight of thirteen model boxes and never says what the tick means
Implementations, Pre-training Code and Datasets of Large Time-Series Models
At a glance
- What is it?
- A research codebase for pretraining and evaluating large time-series models, with a checklist that mixes this repository's own work with links to other people's implementations. Two models with empty boxes appear in the recommended list, and the last push is dated 2026-03-22 with no published releases.
- Who is it for?
- Use it if you want the pretraining and evaluation pipeline rather than a model, and read the checklist with care: it does not say whether a tick means implemented here, tested here or merely known, and five entries are empty without an explanation. Two things to verify before building on it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
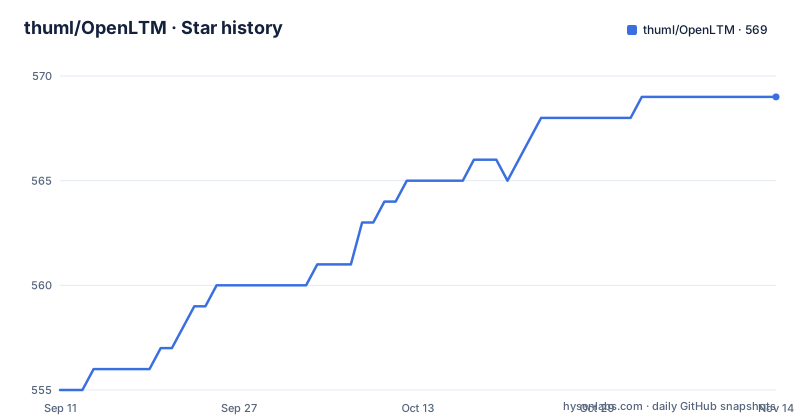
- thuml/OpenLTM569 ★ · +14
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| thuml/OpenLTM | 555 | 569 |
14 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Eight ticked boxes, five empty ones, no key to the symbol
The model checklist is the centre of the page and it carries no legend. Eight entries are ticked: Timer-XL, Moirai, Timer, Moment, TTMs, GPT4TS, Time-LLM and AutoTimes. Five are empty: Sundial, LLMTime, Chronos, Time-MoE and a decoder-only forecasting foundation model linked to the Google Research repository.
What the page never says is what a tick asserts. Three readings are available and they are not equivalent: implemented in this repository, tested by this repository, or simply documented with a citation. The evidence points both ways, because most ticked entries do not link back here at all. Moirai's code link points to Salesforce's uni2ts, Moment's to its own foundation model repository, TTMs' to an IBM research repository and GPT4TS' to a DAMO-DI-ML repository. Even the two that do point at the same organisation, Timer and AutoTimes, resolve to `thuml/Large-Time-Series-Model` and `thuml/AutoTimes`, which are separate repositories.
So a ticked box next to a foreign code link cannot mean implemented here. Whatever the symbol means, it is at best a reading-list marker, and the page's own opening recommendation points elsewhere again, to Time-Series-Library and a survey, for anyone who wants a deep time-series model.
Two unticked models sit in the recommended list
The recommended resources section collects out-of-the-box checkpoints on Hugging Face, and two of them belong to models whose checklist boxes are empty.
Sundial is listed as an unticked model and its recommended checkpoint is `thuml/sundial-base-128m`. Chronos is listed as unticked and its recommended checkpoint is `amazon/chronos-t5-base`. Timer and Moirai, both ticked, also appear there as `thuml/timer-base-84m` and `Salesforce/moirai-1.0-R-base`, and the list continues past a truncated line naming a fifth entry.
So the emptiness of those two boxes is not a statement that the checkpoints are unusable, because the same page recommends downloading them. The most charitable reading is that the unticked entries are models OpenLTM has not itself implemented, which is consistent with the foreign code links, but the page does not say so. An empty box here carries no stated meaning at all, which makes it a poor signal for deciding what to install.
The unattributed direction runs the other way too. Two news entries credit outside contributors for implementations, with thanks to `frndtls` for TTMs and other LLM4TS methods in April 2025 and to `khairulislam` for GPT4TS in December 2024. Those are the entries most likely to correspond to ticked boxes inside this repository.
Two model releases share one checkpoint link
The 2025.05 news entry announces 260B pre-trained Timer weights in PyTorch, described as equivalent to the Hugging Face model `timer-base-84m` but friendlier for fine-tuning, with a notebook in the repository showing how to load the checkpoint.
Later, in the usage steps, the repository offers a checkpoint pre-trained on 260B time points, and the paper linked beside it is the Timer-XL arXiv entry rather than the Timer one. Both places point at the same download address on the Tsinghua cloud share, one file identifier for both.
That matters because the two descriptions are not the same artefact. One is an 84M-parameter model offered as a PyTorch checkpoint, the other is the long-context forecasting checkpoint described in the Timer-XL paper. A reader who follows the usage step expecting Timer-XL weights may end up with the smaller release, and there is no checksum, file size or version marker in the visible text to tell them which arrived.
Loading is done through `load_pth_ckpt.ipynb`, which is also why the repository's primary language is recorded as a notebook rather than Python.
Adding a model means editing a dictionary in an experiment file
The extension mechanism is three manual steps, and none of them is a plugin interface.
The model file goes into `./models`, following `./models/timer_xl.py` as the pattern. The new model is then registered in the `Exp_Basic.model_dict` mapping inside `./exp/exp_basic.py`, which is a Python source file rather than a configuration entry. Finally, the launch scripts for it are created under `./scripts`.
So a new model is added by copying a file, editing a dict literal in experiment code, and writing shell scripts. The tree explains the rest of the layout: `run.py` at the root as the entry point, `exp/` for experiment classes, `data_provider/` for dataset loading, `layers/` for network components and `utils/` for helpers, with `figures/` holding the dataset summary image.
Nothing here describes a registry file, a config schema or a validation step for the dict edit, which means a typo in `model_dict` is a runtime failure rather than a startup error, and there is no visible test that enumerates the registered models.
requirements.txt pins torch 2.0.1 and leaves transformers open
The dependency file is seven lines and mixes two styles. Six packages are pinned exactly: `einops==0.8.0`, `matplotlib==3.9.2`, `numpy==1.26.0`, `pandas==2.2.3`, `scikit-learn==1.5.2` and `torch==2.0.1`. The seventh, `transformers`, has no version bound at all.
The asymmetry is the interesting part. The library whose API this codebase depends on most heavily for backbone and tokenizer work is the one free to drift, while the plotting and array libraries are frozen. Anyone reproducing a pretraining run gets whatever `transformers` resolves to on the day they install, against a torch release from before most of the transformer ecosystem's current expectations and a NumPy release from before the 2.x line.
Installation itself is one command, `pip install -r requirements.txt`, and the instruction above it names Python 3.11. Nothing in the repository states a minimum CUDA version or a GPU requirement, even though the scripts it ships are pretraining runs over a billion time points.
Scripts are grouped by training regime, not by model
The launch scripts are organised by what you are doing, and the directories read like a taxonomy of the paper literature:
# Supervised training
# (a) one-for-one forecasting
bash ./scripts/supervised/forecast/moirai_ecl.sh
# (b) one-for-all (rolling) forecasting
bash ./scripts/supervised/rolling_forecast/timer_xl_ecl.sh

# Large-scale pre-training
# (a) pre-training on UTSD
bash ./scripts/pretrain/timer_xl_utsd.sh
# (b) pre-training on ERA5
bash ./scripts/pretrain/timer_xl_era5.sh

# Model adaptation
# (a) full-shot fine-tune
bash ./scripts/adaptation/full_shot/timer_xl_etth1.sh
# (b) few-shot fine-tune
bash ./scripts/adaptation/few_shot/timer_xl_etth1.sh
The split is one-for-one forecasting against one-for-all rolling forecasting under supervised training, pretraining against adaptation, and full-shot against few-shot fine-tuning. Models appear inside the scripts rather than defining the directories, and the same dataset, ETTh1 in both adaptation scripts, is the fine-tuning target.
Datasets follow the same logic. Pre-training on your own data is skipped when a checkpoint is used, and the two large corpora are UTSD at one billion time points in NumPy format and the ERA5 family across a 40-year span with thousands of variables, the second framed as the domain-specific option. Supervised training and adaptation instead draw on datasets from Time-Series-Library. Everything goes into `./dataset`, checkpoints into `./checkpoints`.
The last push predates the newest news entry by nearly a year
The commit record stops on 2026-03-22, and the repository publishes no releases. The most recent news entry in the page is dated 2025.05, and the one before it April 2025, so the written history ends about a year before the last commit rather than at it.
That gap is the practical fact for anyone planning to use this. There is no tag to pin, no changelog to consult and no release notes; the newest artifact is whatever is on the branch. The project is MIT licensed, has no homepage set, and defaults to the `main` branch.
What the page does offer is a stated purpose narrower than the checklist implies: an open codebase providing a pipeline to develop and evaluate large time-series models. On that reading, an eight-month gap between the last news item and the last commit is not a promise of anything, and the useful question is whether the pinned dependency versions still install and whether `transformers`, being unpinned, still matches the code.
Editorial conclusion
Use it if you want the pretraining and evaluation pipeline rather than a model, and read the checklist with care: it does not say whether a tick means implemented here, tested here or merely known, and five entries are empty without an explanation. Two things to verify before building on it. The last push is dated 2026-03-22, so treat the scripts as a snapshot rather than a moving target, and check which checkpoint a download link actually serves, because one URL is attached to two different model releases.
Frequently asked questions
What is OpenLTM and what does it contain?
An MIT codebase for developing and evaluating large time-series models, with a tree of model implementations, an experiment framework under exp/, dataset loading in data_provider/, and shell scripts for supervised training, pretraining and adaptation. Installation is `pip install -r requirements.txt` with Python 3.11.
Does OpenLTM implement the models on its checklist?
The page does not say what a ticked box means, and most ticked entries link to other repositories, Moirai to Salesforce's uni2ts, TTMs to an IBM research repository, GPT4TS to a DAMO-DI-ML repository. Five entries are unticked, including Sundial, LLMTime, Chronos, Time-MoE and a decoder-only forecasting model.
Which datasets does OpenLTM pretrain on?
UTSD, with one billion time points in NumPy format, and the ERA5 family, a 40-year span with thousands of variables framed as the domain-specific option. Both pretraining steps are skipped when a pretrained checkpoint is used, and supervised training draws on datasets from Time-Series-Library.
How do I add my own model to OpenLTM?
Put the model file in ./models following timer_xl.py, register it in the Exp_Basic.model_dict mapping inside ./exp/exp_basic.py, and create launch scripts under ./scripts. There is no plugin interface; the registration step edits Python source.
What are the pinned dependencies in OpenLTM?
Six exact pins: einops 0.8.0, matplotlib 3.9.2, numpy 1.26.0, pandas 2.2.3, scikit-learn 1.5.2 and torch 2.0.1. transformers is the one dependency listed with no version bound, so a fresh install resolves it to whatever is current.
Is OpenLTM still being updated?
The last push to the branch is dated 2026-03-22 and the repository publishes no releases. The newest news entry on the page is from 2025.05, so treat the scripts as a fixed snapshot rather than something that changes under you.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thuml-openltm)Star history chart for your README
[](https://hysenlabs.com/projects/thuml-openltm)Was this useful?