OpenLLMetry: LLM traces that speak plain OpenTelemetry, with a batch gotcha
Open-source observability for your GenAI or LLM application, based on OpenTelemetry
At a glance
- What is it?
- OpenLLMetry is Traceloop's set of OpenTelemetry instrumentations for LLM applications, covering sixteen model providers and seven vector databases and exporting to twenty four named backends. Two things shape how you adopt it. You can take the SDK or a bare instrumentation, because it emits standard OpenTelemetry data either way, and if you run locally you may want to disable batching so you can see the traces immediately.
- Who is it for?
- Adopt it when your LLM calls already speak OpenTelemetry somewhere else, since the output is standard telemetry and the destination list is long enough that you will find your backend on it. Do not adopt it as an evaluation platform, because what it gives you is traces, not judgements about model output.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
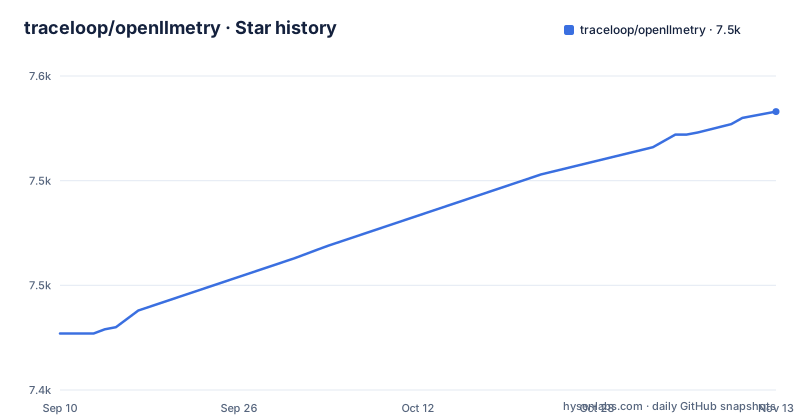
- traceloop/openllmetry7,533 ★ · +106
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| traceloop/openllmetry | 7.4k | 7.5k |
106 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two ways in, and the SDK is only a convenience
The repository holds two kinds of thing, and the distinction matters for adoption. First, standard OpenTelemetry instrumentations for LLM providers and vector databases, which you can add to an application that already emits telemetry. Second, a Traceloop SDK that makes the first kind easy to start with, while still outputting standard OpenTelemetry data that connects to whatever stack you run. That is the argument for it: nothing here is a private data format. If you already have OpenTelemetry instrumented, the page says you can just add any of their instrumentations directly, and if you do not, the SDK gets you there in two lines. The consequence is that the decision is not SDK versus no SDK, it is whether you want a wrapper or a bare instrumentation, and either way the traces that arrive at your backend are ordinary spans.
Locally, batch sending hides your traces behind a queue
The getting started section is one command and two lines of Python:
pip install traceloop-sdkfrom traceloop.sdk import Traceloop
Traceloop.init()Then comes the detail that saves an afternoon, and it is phrased as a suggestion rather than a rule: if you are running locally, you may want to disable batch sending so you can see the traces immediately.
Traceloop.init(disable_batch=True)Batch sending is the right default in production, where exporting per span costs more than it is worth. On a laptop it means your first span sits in a buffer until the interval elapses, so you conclude the instrumentation is broken when it is working perfectly. That is the whole of the local development story: one flag. Anything deeper, such as how spans map onto your model calls or which attributes are attached, is documentation rather than a code change.
Twenty four tested destinations, and the word tested is doing work
The destination list is the section that decides whether this fits your stack, and its heading is Supported (and tested) destinations. Traceloop itself is first, then Axiom, Azure Application Insights, Braintrust, Dash0, Datadog, Dynatrace, Google Cloud, Grafana, Highlight, Honeycomb, HyperDX, IBM Instana, KloudMate, Laminar, New Relic, the OpenTelemetry Collector, Oracle Cloud, Scorecard, Service Now Cloud Observability, SigNoz, Sentry, Splunk and Tencent Cloud. The Collector entry is the escape hatch, since it means you can export to your own pipeline rather than to a vendor. The tested qualifier is the part to respect. Because the output is standard OpenTelemetry, almost any compatible backend will probably accept the data, but a backend nobody has run against this instrumentation is a different proposition from one on this list, and the difference shows up as attribute names and dashboard defaults rather than as an error.
Sixteen providers and seven vector databases, with one honest asterisk
What gets instrumented is broader than model calls. Anything OpenTelemetry already instruments is covered, so your database and API calls come along, and on top of that the project built extensions for calls to model providers and for vector databases. The provider list runs to sixteen entries: Aleph Alpha, Anthropic, Bedrock on AWS, Cohere, Google Generative AI, Groq, HuggingFace, IBM Watsonx AI, Mistral AI, Ollama, OpenAI and Azure OpenAI, Replicate, SageMaker, Together AI, Vertex AI and WRITER. The vector database list is seven: Chroma, LanceDB, Marqo, Milvus, Pinecone, Qdrant and Weaviate. Then the frameworks, which include Agno, AWS Strands, CrewAI, Haystack, LangChain and Langflow. The asterisk worth noticing is on the Strands entry, which is annotated as having built-in OpenTelemetry support, which tells you when you do not need this library at all.
The semantic conventions now live in OpenTelemetry, not in this repository
The announcement at the top of the page is the most consequential line for anyone with dashboards. The semantic conventions are now part of OpenTelemetry, and the project invites you into a discussion in the OpenTelemetry community repository to help shape the future of LLM observability. That is a transfer of ownership rather than a cosmetic change. Attribute names for spans about model calls, token counts and costs are being standardised upstream, which means queries and dashboards written against the earlier names may need rewriting, and it also means the conventions survive a change of vendor. For a team that picked a tracing library and later wants a different one, that portability is the point of the whole exercise. For a team that already has traces on a dashboard, it is a migration to plan rather than a setting to change.
JavaScript and TypeScript are a different repository with a different licence header
If you are on Node, the package you want is not in this repository. The page points to OpenLLMetry-JS as the JS and TS version, which means the two implementations are versioned and released separately and you install one or the other. The root manifest here reflects that split in a way that can confuse a reader. It is a private shell named openllmetry at version 0.0.0, declaring MIT, whose only dev dependencies are an Nx plugin for Python and Nx itself, with workspaces over packages/. Meanwhile the project itself is stated to be built and maintained by Traceloop under the Apache 2.0 license. So the version number in that root manifest describes the monorepo scaffolding rather than the Python library, whose releases are the 0.62.x series. Read the manifest of the package you install rather than the one at the repository root.
Frequent patch releases and a governance file in the tree
The release cadence is the last practical thing. Version 0.62.4 was published 2026-09-29, followed 0.62.3 on 2026-08-10 and 0.62.2 on 2026-08-09, and the repository is not archived with the last push dated 2026-11-02. So the project is moving quickly at a patch level, which is what you would expect from a library whose output is bound to a fast moving upstream in two places at once, the OpenTelemetry specification and the model provider SDKs. The governance side is visible in the tree rather than described: there is a GOVERNANCE.md and a MAINTAINERS.md beside the contributing guide, the code of conduct, the security policy and the changelog, and a commit message configuration at the top level. If you are adopting a library whose conventions are being standardised upstream, those files are the place to look for who decides when the conventions change.
Editorial conclusion
Adopt it when your LLM calls already speak OpenTelemetry somewhere else, since the output is standard telemetry and the destination list is long enough that you will find your backend on it. Do not adopt it as an evaluation platform, because what it gives you is traces, not judgements about model output. Before you start, add Traceloop.init(disable_batch=True) so local runs show spans immediately, pick your export path from the tested list rather than assuming any collector-compatible backend works, and check whether your framework already ships OpenTelemetry support of its own.
Frequently asked questions
what is openllmetry
OpenLLMetry is a set of extensions built on top of OpenTelemetry that gives you observability over an LLM application. It contains standard OpenTelemetry instrumentations for model providers and vector databases, plus a Traceloop SDK for getting started, and it outputs standard OpenTelemetry data so it can be connected to existing backends. It is built and maintained by Traceloop under the Apache 2.0 licence.
how to use openllmetry
Install the SDK with pip install traceloop-sdk, then add an import of Traceloop from traceloop.sdk and call Traceloop.init() in your code. If you are running locally, pass disable_batch=True so spans are visible immediately instead of waiting on the batch interval. If your application is already instrumented with OpenTelemetry you can skip the SDK and add the provider or vector database instrumentations directly.
openllmetry alternatives
The project does not list competitors. It does say that because it uses OpenTelemetry under the hood it can be connected to existing observability solutions, naming Datadog and Honeycomb among others, and its tested destination list covers 24 backends including the OpenTelemetry Collector, Grafana, Sentry, Splunk and the major cloud providers. A JavaScript and TypeScript implementation is maintained separately as OpenLLMetry-JS.
What are some effective observability tools for LLMs?
On the provider side OpenLLMetry instruments OpenAI and Azure OpenAI, Anthropic, Cohere, Mistral, Groq, HuggingFace, Aleph Alpha, IBM Watsonx, Vertex AI, Bedrock, SageMaker, Together AI, Replicate, Ollama, Gemini and WRITER. On the retrieval side it covers Chroma, LanceDB, Marqo, Milvus, Pinecone, Qdrant and Weaviate, plus frameworks including LangChain, CrewAI, Haystack, Agno and Langflow.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/traceloop-openllmetry)Star history chart for your README
[](https://hysenlabs.com/projects/traceloop-openllmetry)Was this useful?