Triton Model Analyzer splits one config space four ways, and the widest search is still marked alpha
Triton Model Analyzer is a CLI tool to help with better understanding of the compute and memory requirements of the Triton Inference Server models.
At a glance
- What is it?
- A CLI from NVIDIA that profiles single, ensemble, BLS, multi-model, and LLM deployments on a Triton Inference Server, sweeping Max Batch Size, Dynamic Batching, and Instance Group or the whole model configuration, then writing the trade-offs out as PDF reports. Two things to know before the first run: the README prints no install command, and the container build sits on an older Triton than its own dev tag claims.
- Who is it for?
- Reach for it when you have a Triton deployment whose numbers disappoint you and you need to know which knob is at fault, and when you can afford sweeps that rerun the server many times. Skip it for a one-off latency question, since the quick mode still walks three parameters and the constraint filter discards work only after the fact.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
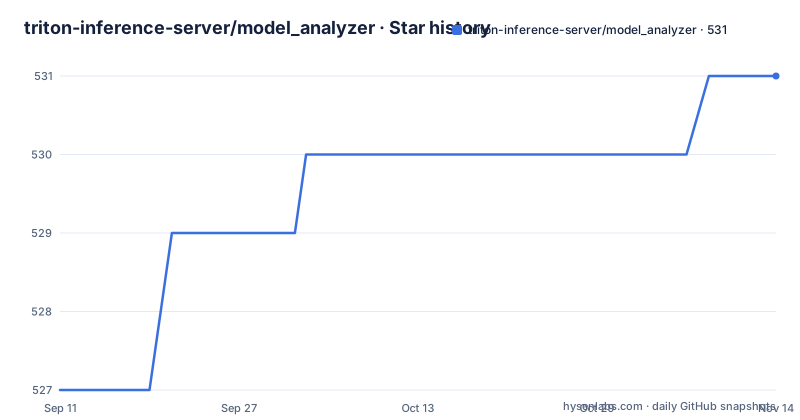
- triton-inference-server/model_analyzer531 ★ · +4
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| triton-inference-server/model_analyzer | 527 | 531 |
4 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four search modes, and one of them carries an alpha label
Model Analyzer splits its exploration into four modes, and one is flagged in the README as an alpha release. Optuna Search covers every parameter that can be set in a model configuration, handing the search itself to a hyperparameter optimization framework. Quick Search covers three named parameters with a heuristic hill-climbing algorithm. Automatic Brute Search covers those same three parameters exhaustively. Manual Brute Search leaves you to build a sweep over every parameter and choose the points yourself. A terminology section at the bottom sorts them into two families: exhaustive means brute, heuristic means quick or Optuna. Nothing in the repository states how long each mode takes or how many points a manual sweep is expected to cover, so the choice comes down to reading docs/config_search.md before the first run.
Quick search moves three parameters, brute moves the same three exhaustively
Those three parameters are Max Batch Size, Dynamic Batching, and Instance Group, and each is linked straight to the Triton server's own page for that knob, which tells you where the setting is defined. Everything else in a model configuration is reachable only through the two modes that reach wider: Manual Brute Search for sweeps you set up yourself, and Optuna Search for automated optimization over the full space. Multiply by the model types on offer, single, ensemble, BLS, multi-model, and LLM, and the README's own definition of Model Config Search as the cross product of model type and search mode yields sixteen cells to plan for. The mode descriptions say the quick search is sparse and the automatic brute search is exhaustive, but neither says whether a heuristic run reports only its best point or the whole hill it climbed.
A latency budget filters the finished table instead of bounding the run
QoS constraints operate as a filter on the outcome, not as a ceiling on the work. You state a requirement, a latency budget in the case the README walks through, and Model Analyzer drops configurations whose measured latency misses your threshold. The feature is documented under the constraint anchor of docs/config.md. Two consequences follow. The sweep still pays for every configuration that gets thrown away, because the filter is applied to results rather than steering the search itself. And the threshold is only worth what sits behind it, so a latency budget carried over from another GPU, another batch shape, or another Triton container will not transfer. The examples directory makes this visible: mm_result_summary_constraint_table.jpg and mm_result_summary_constraint_top.jpg sit beside the unconstrained multi-model screenshots, which is the same run shown twice, once filtered.
The Dockerfile sits on Triton 26.06 while v1.58.0 names container 26.09
The container build is pinned further back than the release history implies. The Dockerfile sets BASE_IMAGE to nvcr.io/nvidia/tritonserver:26.06-py3 and takes its client wheels from the matching 26.06-py3-sdk stage, while the same file declares MODEL_ANALYZER_VERSION=1.59.0dev and MODEL_ANALYZER_CONTAINER_VERSION=26.10dev. Release tags carry the NGC container they correspond to in the release name: v1.58.0 is labelled 26.09, v1.55.0 is 26.06, and v1.54.0 is 26.05. That leaves two NGC releases between the Triton the image is built on and the container version it claims. The tag spacing is its own signal, since 1.54.0 to 1.55.0 advanced one container release and 1.55.0 to 1.58.0 advanced three. Anyone comparing a fresh report against an older one needs to know which Triton produced the older number.
Installing means following a link, because the README prints no command
There is no install command anywhere in the README, and both routes out of the page end in a link. The documentation index points at docs/install.md, and the readme field inside pyproject.toml redirects to the anchor install.md#using-pip3 with the note that the package details live there. The container route is the Dockerfile, which copies the tree in, runs python3 -m build --wheel, installs the triton*model*analyzer*.whl it finds in the dist directory, and hands control to nvidia_entrypoint.sh. The naming is worth keeping straight: the distribution is triton-model-analyzer, while the repository and the import package are both model_analyzer. The badge line at the top is an empty link too, an opening bracket pair pointing straight at the Apache-2.0 license URL with no image in between, so nothing renders there.
Reports leave as PDF and JPEG, which is why wkhtmltopdf is in the image
Every artifact in the examples directory says the output is files on disk. There are four PDFs: online_summary.pdf, offline_summary.pdf, online_detailed_report.pdf, and offline_detailed_report.pdf, plus JPEG screenshots of the same summary tables for BLS, ensemble, and multi-model runs. The PDF step explains an apt line in the Dockerfile that installs wkhtmltopdf alongside docker.io. The Docker client in that same line matters as much, because the tool needs a way to stand a server up and take it down again, and Launch Mode is its own documented concept with its own page. The multi-model set ships constraint variants next to the plain ones, which is the visual evidence for the filtering described above. No wkhtmltopdf version is recorded anywhere, so a PDF that renders differently on your host is worth checking before you circulate it.
One exact hatchling pin is holding the license string together
The build backend is pinned to a single release, and the comment above it says why. pyproject.toml sets requires = ["hatchling==1.27.0"] with build-backend = "hatchling.build" instead of a range. The note says the PEP 639 SPDX license string is rejected outright by setuptools older than 77, quoting the failure as project.license must be valid exactly by one definition, and that the previous unbounded setuptools >= 61.0 left the build to whatever the environment happened to provide. The ticket is TRI-1775. The project table then uses license = "Apache-2.0" with license-files = ["LICENSE"], a dynamic version, and one author entry naming NVIDIA Inc. at a shared alias, [email protected]. Pinning the backend fixes the build, but the version number is not written there at all: the table marks it dynamic and a VERSION file sits at the top of the tree.
Ten doc pages and a helm chart, none of them walked through
The documentation index names ten pages: installation, CLI, launch modes, configuration, metrics, model config search, model types, checkpointing, reports, and Kubernetes deployment. A helm-chart directory sits at the top level next to them. None of that gets an example in the README, so checkpoint resume in particular is a page you will need before a long sweep, since the page list proves the feature exists and nothing else says when a checkpoint is written or picked back up. For support the README sends you to the Stack Overflow MCVE process and asks for examples that are minimal, complete, and verifiable. The repository carries 529 stars, 90 forks, and 4 open issues, and the most recent release tag, v1.58.0, was published on 2026-09-30.
Editorial conclusion
Reach for it when you have a Triton deployment whose numbers disappoint you and you need to know which knob is at fault, and when you can afford sweeps that rerun the server many times. Skip it for a one-off latency question, since the quick mode still walks three parameters and the constraint filter discards work only after the fact. Before trusting any number it produces, check which Triton container the run came from, because the Dockerfile pins 26.06 while the newest release tag names 26.09.
Frequently asked questions
What does Triton Model Analyzer actually do?
It is a CLI that finds a more optimal configuration for single, multiple, ensemble, or BLS models on a given piece of hardware, and generates reports covering the trade-offs and the compute and memory requirements of the configurations it tried.
What is the difference between Quick Search and Automatic Brute Search?
Both cover Max Batch Size, Dynamic Batching, and Instance Group. Quick Search is sparse and uses a heuristic hill-climbing algorithm, while Automatic Brute Search covers the same three parameters exhaustively. Manual Brute Search and Optuna Search are the modes that reach every parameter in the model configuration, and Optuna Search is the one marked as an alpha release.
How do I install Triton Model Analyzer?
The README contains no install command and points at docs/install.md instead. The readme field in pyproject.toml redirects to the anchor install.md#using-pip3 for the package details, and the container route runs through the Dockerfile and nvidia_entrypoint.sh. The distribution name is triton-model-analyzer.
Which model types can Triton Model Analyzer profile?
The feature list names ensemble, BLS, multi-model, and LLM models, and the opening description adds single models. Each has its own quick start document under docs/.
Which Triton version does the Triton Model Analyzer container target?
The Dockerfile sets BASE_IMAGE to nvcr.io/nvidia/tritonserver:26.06-py3 and declares MODEL_ANALYZER_CONTAINER_VERSION=26.10dev, while the v1.58.0 release name corresponds to NGC container 26.09.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/triton-inference-server-model-analyzer)Star history chart for your README
[](https://hysenlabs.com/projects/triton-inference-server-model-analyzer)Was this useful?