crawl4ai: pip installs the library and a second command installs the browser
Crawl4AI turns web pages into clean Markdown for retrieval systems, agents, and data pipelines, with browser control and structured extraction.
At a glance
- What is it?
- An Apache-2.0 crawler that turns pages into LLM-ready Markdown, with browser control, structured extraction and a hosted cloud on the same key. The open-source path is genuinely free but the dependency list exists twice with different contents, and the container's output directory is a tmpfs.
- Who is it for?
- crawl4ai is a good fit if you want Markdown output and structured extraction you control yourself, and you can live with owning the browser, the proxies and the bot walls. Take the library path rather than the cloud if per-request cost is the problem, but understand that web search is only in the cloud.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
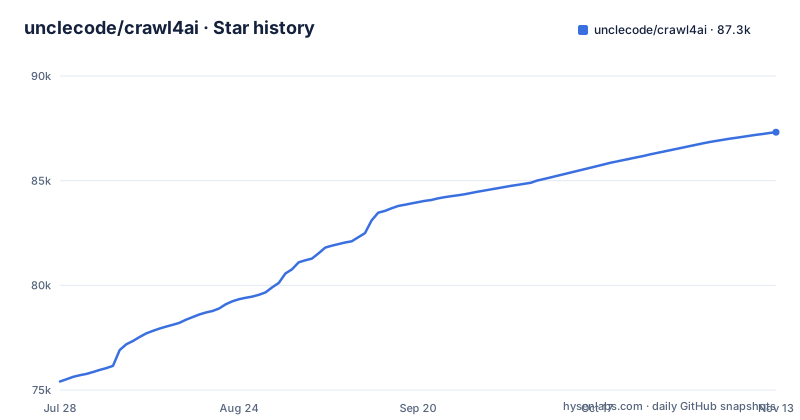
- unclecode/crawl4ai87,315 ★ · +11,911
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| unclecode/crawl4ai | 75.4k | 87.3k |
11,911 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The install is two commands, and the second one is the browser
The quickstart is a two-line block, and the second line is not optional.
pip install -U crawl4ai
crawl4ai-setup        # installs the browser, once
So pip gives you the package and a second command fetches the browser binary. The comment says once, which is the saving grace for repeat installs and also the trap for automation: a Docker build or a CI step that runs only the pip line produces an environment where `import crawl4ai` works and a crawl does not. The library usage in the file reflects that split, because it needs no browser setup of its own.
import asyncio
from crawl4ai import AsyncWebCrawler

async def main():
    async with AsyncWebCrawler() as crawler:
        result = await crawler.arun(url="https://news.ycombinator.com")
        print(result.markdown)

asyncio.run(main())
Consequence: a deployment that treats the pip line as the install is a deployment whose first real request fails, and the failure looks like a runtime bug rather than a missing step.
requirements.txt is not the pyproject list, and it carries three packages the library omits
Two files hold the dependency list and the file itself says so. requirements.txt opens with a note that these requirements are also specified in pyproject.toml, and that the file is kept for development environment setup and compatibility. Read them side by side and the claim is only half true. Four lines in requirements.txt are missing from or differ from the pyproject dependencies.
colorama~=0.4
fake-useragent>=2.2.0
pdf2image>=1.17.0
pypdf>=6.0.0
One of those, pypdf, exists in the pyproject as the optional pdf extra rather than as a core requirement. Going the other way, click, humanize and lark are in the pyproject dependencies and absent from requirements.txt, and fake-useragent is a lower bound of 2.0.3 in one place and 2.2.0 in the other. Consequence: an environment built from the requirements file is not the environment the package declares, so an import that works for a maintainer can fail for you, and a version floor that looks like documentation is actually a divergence.
One LLM dependency is pinned to an exact build while everything around it floats
Every entry in the dependency list uses a range except one.
unclecode-litellm==1.81.13That single exact pin is the LLM call layer, and it is pinned to a build published under the project's own namespace rather than to the upstream package name. The rest of the list uses lower bounds or compatible ranges, lxml>=5.3,<7 and numpy>=1.26.0,<3 being the ones with a ceiling. Alongside the browser work there are four packages doing related jobs: playwright>=1.49.0, patchright>=1.49.0, playwright-stealth>=2.0.0 and fake-useragent. Consequence for a reader: the component every LLM-backed feature depends on is the one component that cannot float, so a fix or a breaking change there requires editing both dependency files by hand, and the stealth story is assembled from four separate packages rather than one switch. The README's own comparison table is blunt about what that buys you on the free path: JS-heavy pages and bot walls are your settings and your proxies.
Web search exists only in the cloud, and both free columns carry a dash
The comparison table has four rows and three columns, Library, Your own server, and Crawl4AI Cloud. Two rows show the free side as self-run. Who runs the browsers: you, in your Python process, or you in Docker on your machine, against we do. And price: free, forever, or free on your hosting, against pay as you go. The third row is the one to read. For Web search, the Library and Your own server columns both carry an en dash, and only the cloud column names endpoints, /search, /serp and /answer. The same split appears in the text, where the cloud gets scrape, search and extract through one API. Consequence: if your pipeline needs a search step and not just a fetch step, the open-source route does not contain it, and you either build it yourself or pay for the hosted key. The cloud side of the price row reads 1,000 free credits a month, with plans from $10.
The container runs read-only with six tmpfs mounts, and outputs are one of them
The compose file is written defensively and the comments explain why. shm_size is 1gb, with a note that Chromium needs shared memory but the host /dev/shm bind was a shared writable mount, so a private sized tmpfs is used instead. cap_drop is ALL, security_opt sets no-new-privileges:true, and read_only is true. Six paths are then mounted as tmpfs, all but /tmp with uid=999, gid=999, mode=0700: /tmp, /var/lib/redis, /var/lib/crawl4ai/outputs, /home/appuser/.crawl4ai, /home/appuser/.cache/url_seeder and /home/appuser/.gunicorn. The Gunicorn port is 11235. Consequence: with a read-only root, those six paths are the only writable locations in the container, so any code path that writes elsewhere fails, and crawled output lands on a tmpfs, which means it is discarded when the container is recreated. If you need results to survive a restart, you have to mount a volume at that path yourself.
A tmpfs is mounted over part of the cache directory the browser was baked into
One line in that tmpfs list has a comment that does not match its path. The entry is /home/appuser/.cache/url_seeder, and the comment above it reads that the baked Playwright browser under ~/.cache/ms-playwright should stay visible. So the container mounts a tmpfs at one child of the cache directory in order to leave a sibling of it alone. The arithmetic works only because the mount point is the more specific path, and a writable url_seeder directory under a home directory that is otherwise read-only is the only reason that entry can exist at all. Consequence: this is a fragile arrangement, since any change to the Playwright cache location, or any feature that wants to write beside the browser rather than under url_seeder, meets a read-only filesystem. The file is the documentation of that constraint, and it is expressed only as a comment next to a tmpfs entry rather than as a documented writable-path list.
Two environment file conventions and two webhook tests outside the test package
The root carries a .env.example, and the compose file references a different name, .llm.env, with a comment telling you to create it from .llm.env.example and marking it optional so a fresh clone runs. That makes two environment file names, so a reader has to work out which tool reads which.
Version 0.9.x carries a Beta classifier, and the changelog is generated from commits
The three most recent releases are v0.9.3 on 2026-08-31, v0.9.4 on 2026-09-23 and v0.9.5 on 2026-10-14, roughly three weeks apart. The packaging metadata classifies the project as Development Status :: 4 - Beta, and the version is read dynamically from a file in the package rather than hardcoded, with a setup.py kept for backwards compatibility. A cliff.toml sits at the root beside a CHANGELOG.md, which is the configuration for generating a changelog from conventional commits. Consequence for a reader: the version scheme has not left the 0.9 line and the project labels itself beta, so nothing in the metadata signals a stability promise, and the changelog entries are whatever text the commit messages produced. The root also carries ten other markdown documents, including MISSION.md and ROADMAP.md, so the README is one of eleven.
Editorial conclusion
crawl4ai is a good fit if you want Markdown output and structured extraction you control yourself, and you can live with owning the browser, the proxies and the bot walls. Take the library path rather than the cloud if per-request cost is the problem, but understand that web search is only in the cloud. Before you containerise it, read the read-only filesystem settings, decide where crawled output should live rather than leaving it in a tmpfs, and check which of the two dependency files your environment actually uses.
Frequently asked questions
what is crawl4ai
It is an open-source web crawler and scraper that turns any website into clean, LLM-ready Markdown for RAG, AI agents and data pipelines, with browser control and structured extraction. The library is Apache-2.0 and there is also a hosted cloud that runs the browsers for you.
how to install crawl4ai
Two steps. `pip install -U crawl4ai` for the package, then `crawl4ai-setup # installs the browser, once` for the browser itself. The file also points to a Docker server, a CLI, the Installation section and docs.crawl4ai.com for every other option.
How much does Crawl4AI cost?
The library is free, forever, and your own server is free on your hosting. The cloud is pay as you go, with 1,000 free credits every month and no card needed, and paid plans from $10 a month.
Does Crawl4AI use Playwright?
Playwright is a declared dependency at playwright>=1.49.0, alongside patchright>=1.49.0 and playwright-stealth>=2.0.0. The browser control section names Chromium, Firefox and WebKit, and the second install command is the one that fetches the browser.
how to setup crawl4ai
For a self-hosted server the repository ships a Dockerfile and a docker-compose.yml. The compose file references .llm.env, marked optional so a fresh clone runs, and expects it to be created from .llm.env.example, and it also passes a CRAWL4AI_API_TOKEN through from the host shell.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/unclecode-crawl4ai)Star history chart for your README
[](https://hysenlabs.com/projects/unclecode-crawl4ai)Community discussions
Was this useful?