Miles pins a nightly build by date and writes its own wheel tags
Miles is an enterprise-facing reinforcement learning framework for LLM and VLM post-training, forked from and co-evolving with slime.
At a glance
- What is it?
- Miles is a reinforcement learning framework for post-training large models, pairing a high throughput inference engine for rollout with Megatron-LM for training, and forked from a project it still co-evolves with. The engineering record lives in two files that say more than the feature list does: a requirements file where every pin carries the reason it exists, and a setup script that computes wheel platform tags by hand.
- Who is it for?
- Miles is for a team that already runs SGLang and Megatron-LM at scale and wants an RL layer that treats rollout and training as separate systems it can schedule. Three things to check before you plan around it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 22, 2026, and from our analysis. They are not legal advice.
Star history
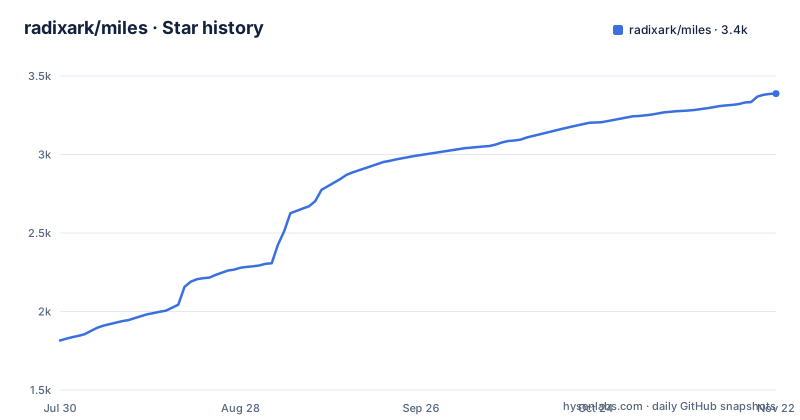
- radixark/miles3,388 ★ · +1,573
| Repository | 2026-07-30 | 2026-11-22 |
|---|---|---|
| radixark/miles | 1.8k | 3.4k |
1,573 Stars in the last 115 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Forked from a project it still co-evolves with
The repository description is the shortest honest summary available: a reinforcement learning framework for large language and vision language model post-training, forked from and co-evolving with another project named in that same line.
That relationship is worth holding onto, because it explains the shape of everything else. The framework pairs one engine for high throughput rollout with a different one for scalable training, and it inherits the assumption that those two engines are separate systems with separate versions, which is why the requirements file is full of pins that exist to keep them talking to each other.
The page also carries a line of verse about a thousand miles and a single rollout, which tells you what the authors consider the unit of work.
On versions, there are two releases and they are early: 0.1.0 in August 2026 and 0.1.1 in late September. The packaging file hard-codes the same 0.1.1 as a plain string, with no derivation from a tag. So the version you would pin is a 0.1 release, five weeks apart, and the news list underneath runs to ten dated entries from April to August, each of which is a blog post announcing one capability rather than a changelog entry.
Every pin in the requirements file carries its reason
The requirements file is the most valuable document in the repository, because each entry has a comment explaining why it is pinned the way it is. Four are worth quoting.
A fault tolerance component is pinned to a nightly build by date, and only on Linux on x86_64. That is a nightly in a production training stack, pinned so that a given day cannot change under you.
The actor framework is held between two versions with an upper bound, and the comment says a later release removed an internal function that the object store needs for RPC references. So the ceiling is not caution; it is a removed API.
The transformers library is pinned to one exact version, because it is required for native weight conversion and because the next version collides with a speech model inside the inference engine. That is one pin solving two unrelated problems.
Then there are the three utilities for the weight sync path, each pinned exactly: a hash function, a hash function for a second algorithm, and a compression library, labelled as the checksum and the codec for the disk-delta weight sync. And a wire format library is bounded below, with the comment that its malformed-payload exception contract was validated against that version.
The container image installs one package with resolution switched off
One comment in the requirements file explains why that file looks the way it does. A compiler library is an import-time dependency of a specific version of a GPU transformer library, and that GPU library is installed by the docker image with dependency resolution disabled. Without the extra entry, any run on the Megatron backend dies at the import of Megatron itself.
So the environment is assembled by the image, not by a resolver, and the requirements file exists to fill in the holes that the image deliberately leaves. That is the single most useful thing to know before installing this project, and it is written in a comment rather than in a document.
Two more entries are honest housekeeping. A memory profiler is a runtime requirement with a comment saying it is needed for debugging but lightweight, and that it could move to a development group when the project switches fully to the pyproject file. And a standard library backport is required below one Python version, which tells you the target interpreter is the one just below it, consistent with the import sorting configuration elsewhere in the project targeting that version.
The extras are thin: one extra for the fully sharded backend with a torch floor, one for experiment tracking, and one for a dashboard described in a comment as standalone offline serving, whose dependencies the training image already has.
The wheel's platform tag is computed in Python
The packaging script subclasses the wheel builder and overrides two things: it forces the distribution to be treated as platform specific, and it computes the tag itself.
The tag function asks the operating system and the machine architecture. On Linux it maps an x86_64 machine to the first generation many-platform tag, an arm64 machine to the 2014 generation tag, and anything else to a hand-built Linux tag named after the machine. Off Linux it just uses the operating system name. The ABI part of the tag is simply the running interpreter's version.
The consequence is that the tags are asserted rather than audited. Portable Linux tags exist because a build tool checks the binary against a glibc baseline and only then claims compatibility; here that check does not happen, and the first generation tag is the most permissive one in the family, which is exactly the tag that implies the widest glibc support.
The same file also reads the requirements file at build time to populate the install requirements, with a three line helper that skips blank lines and comments. So a typo in that file, or a comment character appearing inside a line, changes the installed dependency set silently rather than failing loudly.
Three training entry points, three example families
The repository root has three training scripts with names that map directly onto the feature list: one plain trainer, one asynchronous trainer, and one for multiple policies. Alongside them sits a serving script, which pairs with the dashboard extra described as standalone offline serving.
So the fully asynchronous design is not a flag inside one script; it is a separate entry point, which is the shape you would expect when the scheduler itself differs.
The examples directory has twelve entries and reads as a coverage matrix rather than a gallery. Two are named for the infrastructure features themselves. Two cover adapters. There are separate examples for one adapter and for several. One is a reinforcement learning algorithm, one is supervised fine tuning, one is on-policy distillation, and one is marked experimental.
Three of them are named after the work rather than the technique: a vision-language model example built around a geometry problem set, a tool-use version two example, and a software-engineering agent example running in a container. That last one is the clearest statement of what the agentic connectors are for, since the connectors listed on the page are harness frameworks and the sandboxes listed are container platforms.
One formatter at 119 columns, another at 320
Three style tools are configured in one file and they do not agree.
The import sorter uses the formatter's own profile at a line length of 119, with whitespace differences ignored for compatibility and the target interpreter version set explicitly. The formatter itself is at 119. The linter is at 320, and the number carries a comment marking it as unfinished.
The linter's ignore list then contains the line-length rule with another comment saying it will be handled later, which is what you would expect when the configured line length is wide enough that the rule would fire constantly.
What the linter does select is the structural rule set: syntax errors, the name and import checks, the bugbear checks for logic problems such as shadowed variables and dangerous defaults, and the modernisation rules. So the project has decided what it wants to catch and has deferred the formatting question, which is a defensible trade as long as the formatter is the one that decides.
The test configuration is more opinionated. Durations are always reported and sorted, markers are strict, the test path is set explicitly with a comment explaining that this avoids importing some other module named tests, and there is a long list of directories to skip during discovery.
Two features exist to stop a large run from diverging
The correctness section is three items, and two of them are about a specific way a distributed run goes wrong.
The first is token-in-token-out. It is supported for every model and every black-box harness, and the point is that there is no detokenize and retokenize step between rollout and training. Tokens that came out of the inference engine go into the trainer unchanged, so nothing is lost in translation.
The second is routing replay. The expert routing chosen during rollout is recorded and replayed in the trainer's forward pass, which removes the mixture-of-experts routing mismatch that the page says destabilises large runs. Compute and communication are overlapped to keep the cost down.
The third is fault tolerance at the engine level: when an inference engine dies, the framework recovers it and resumes the run in place, with no restart and no pause. That is a stronger promise than a checkpoint and resume, and it is the kind of claim that only makes sense in a system where the rollout fleet is managed as a fleet.
The performance section adds the other half. Rollout and training workers are decoupled with configurable on- and off-policy schedules, and new weights reach the engines inside the loop in seconds even on a trillion-parameter model, with a peer-to-peer remote memory access path as the fast route for disaggregated setups.
Day-0 model support is the headline and the news list is the changelog
The what-it-runs section is organised around arriving on the same day as a model.
Five are named as landing on release day: a DeepSeek model, a Kimi model, a GLM model, one described as a frontier multimodal model, and an Nvidia Nemotron model. Beyond day zero the page claims nearly every frontier model runs, naming two more.
Hardware is listed the same way, by generation: four Blackwell-class parts and three Hopper and Ampere parts on one side, four Instinct parts on the other. The page points to per-GPU status in the install documentation and to a separate page for the AMD images, which is the right way to publish a support matrix that changes weekly.
The recipes are named as four reinforcement learning algorithms, plus supervised fine tuning and on-policy distillation. Diffusion work is a separate repository with its own two algorithms and a fine tuning path on a diffusion rollout engine.
What ties it together is the news list, which is the real changelog: ten entries between April and August 2026, each linking a blog post and each announcing exactly one thing, from low-precision training formats to on-policy distillation to peer-to-peer weight transfer for trillion-parameter updates to day-0 support for three models in three weeks. The repository root also carries two agent instruction directories and an agent instruction file beside the contributor guide.
Editorial conclusion
Miles is for a team that already runs SGLang and Megatron-LM at scale and wants an RL layer that treats rollout and training as separate systems it can schedule. Three things to check before you plan around it. Read the requirements file, because several pins exist to work around a specific upstream removal or a collision, and they will constrain your own upgrades. Decide which training backend you are on, since the recipes and the largest models live on one of them and the other is described as the path of less resistance. And expect the container image rather than your resolver to define the environment, which is what makes the packaging file hand-written in the first place.
Frequently asked questions
What is Miles?
It is an enterprise-facing reinforcement learning framework for post-training large language and vision language models, forked from and co-evolving with another project of the same name. It pairs a high throughput inference engine for rollout with Megatron-LM for scalable training, and is Apache licensed with versions 0.1.0 and 0.1.1 released in 2026.
Which training backends does Miles support?
Megatron-LM is the main one, and the page says the recipes, the parallelism and the largest models all live there. A PyTorch fully sharded backend is available for runs that would rather train the HuggingFace implementation as is, and the documentation has a page comparing the two.
Which reinforcement learning algorithms does Miles support?
Four are named for reinforcement learning, plus supervised fine tuning and on-policy distillation. Diffusion work is handled separately: two algorithms and fine tuning on a diffusion rollout engine with a fully sharded trainer live in their own repository.
Which hardware does Miles support?
Four Nvidia parts including three Blackwell-class ones, plus three Hopper and Ampere parts, and four AMD Instinct parts. The page points to per-GPU status in the installation documentation and to a separate page for the AMD ROCm images rather than publishing a single static matrix.
How does Miles keep a large reinforcement learning run stable?
Three mechanisms. Token-in-token-out removes the detokenise and retokenise round trip between rollout and training. Routing replay records the expert routing during rollout and replays it in the trainer's forward pass, which removes the mixture-of-experts mismatch. And when an inference engine dies it is recovered and the run resumes in place, with no restart and no pause.
How is the Miles Python environment pinned?
The install requirements are read from a requirements file at build time, and that file pins a nightly fault tolerance build by date on Linux x86_64, caps the actor framework below the release that removed an internal API it needs, and holds the transformers library at one exact version to avoid a collision with the inference engine. A comment in the same file records that the container image installs one GPU library with dependency resolution disabled.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/radixark-miles)Star history chart for your README
[](https://hysenlabs.com/projects/radixark-miles)Was this useful?