dvc puts placeholders in Git and a Makefile in your pipelines
Data Versioning and ML Experiments. When you make changes, only run the steps impacted by those changes.
At a glance
- What is it?
- DVC is a command line tool and editor extension for reproducible machine learning projects, and its readme explains itself with three analogies: git for data, Makefiles for machine learning, and local experiment tracking with no server. The quick start is a table of terminal commands, and the repository dogfoods its own formats by committing its own .dvc directory and shipping itself as a git hook.
- Who is it for?
- DVC fits a team with large files and no budget for a data platform, whose Git repository already holds the code and whose collaborators will not install anything but a command line tool and a client. It does not fit a team that wants a hosted experiment service with a web UI, because the tracking store is the repository itself.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
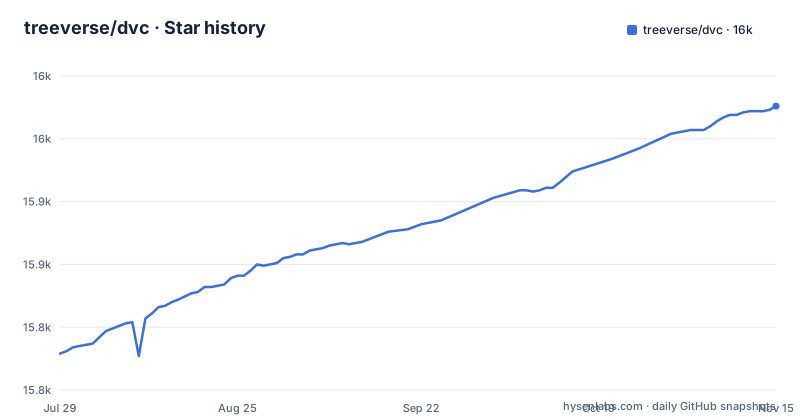
- treeverse/dvc15,976 ★ · +197
| Repository | 2026-07-29 | 2026-11-15 |
|---|---|---|
| treeverse/dvc | 15.8k | 16k |
197 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three analogies, and the mechanism underneath all of them
The readme offers three comparisons and then explains the mechanism, which is worth doing in that order. DVC as git for data is described as storing and sharing data artefacts and models like a large-file extension would, but without needing a server, connecting them through a git repository. DVC as Makefiles for machine learning is the one that explains the design: pipelines describe how one artefact is built from other data and code in a standard format, which is what makes the skipping of unaffected steps possible. Experiment tracking is described as turning your own machine into a platform, with collaboration happening through whatever git hosting you already have. The mechanism under all three: git stores your code and the DVC meta-files as placeholders, the real data and model files live in a cache outside the repository, and that cache is shared through remotes, which can be cloud object stores or on-premise storage reached over SSH.
The quick start is a table of terminal commands
The getting started section is a six-row table mapping a task to the exact command, and reproducing it is the fastest way to understand the vocabulary:
dvc add images/
dvc stage add -n featurize -d images/ -o features/ python featurize.py
dvc stage add -n train -d features/ -d train.py -o model.p -M metrics.json python train.py
dvc exp run -n exp-baseline
dvc exp show
dvc exp apply exp-baseline
dvc remote add myremote -d s3://mybucket/image_cnn
dvc push
Every flag in the stage lines is load-bearing. The name identifies the stage, each dependency flag declares an input, each output flag declares a file the stage produces, and the metrics flag records a file of numbers rather than an artefact. The last two commands are how the data leaves your machine: a remote is declared with a location, and a push sends the cache there. The readme also tells you to consult its command reference for the complete list, which is the sensible next step before you script any of this.
Pipelines are graphs, and declaring outputs is what enables skipping
The pipeline section describes computational graphs that connect code and data, and specifies what a stage has to contain: input dependencies including code, data and the command to run, plus the output information to be saved. That definition is the whole contract, and it is also where the central promise lives. Because a stage declares its inputs, the tool can decide that a change to one script does not invalidate a stage that never read it, so a run touches only the affected steps. The cost of that design is that a wrong dependency declaration quietly breaks incremental behaviour: a stage that reads an undeclared file will not rerun when that file changes, and you will get a stale result rather than an error. Which is why the readme spends its effort on the command reference and the getting started material rather than on the theory.
Experiments are named, compared, and applied back into the working tree
Experiment versioning is the third pillar, and its workflow is four commands. You run an experiment with a name, change a script, run another, list them for comparison, and apply the one you want. The description says results can be filtered and compared on hyperparameters and metrics and visualised with multiple plots, which is the part that makes a comparison useful rather than a table of numbers. Applying an experiment is the step people miss: it is what moves the chosen run's outputs back into your working tree so the next piece of work starts from the winning model. The readme is explicit that tracking happens in the local repository with no servers needed. Worth noting that the comparison and plotting come from a sibling rendering package and that a client for a hosted service is among the dependencies, so the no-server claim is about where the record lives rather than a promise that nothing else is involved.
The editor extension is a separate install with two working features
The VS Code extension is presented as the way to use DVC as a graphical tool inside the editor, installed from the marketplace. What it currently offers is stated narrowly: experiment tracking and data management, with data pipeline support named as coming soon. That is worth weighing before you plan around it, because the pipeline layer is where most of the tool's value lives and it is the part the extension does not yet cover. The extension also has a dependency most marketplace extensions do not: you have to install the core command line tool on your system separately, and the readme says the extension will guide you if you have not. In other words it is a front end over the binary rather than a self-contained application, which is a reasonable design and means your CI and your editor stay consistent by construction.
A release line that moved twice in March, and a dependency list worth reading
The packaging metadata answers several questions at once. The package name and its description position it plainly as a tool for data scientists to manage code and data together, the licence file is named explicitly, and the maintenance metadata lists the organisation rather than a person, with the original author credited separately. It supports Python 3.9 upward and its classifiers run to 3.14, so it is keeping pace with new interpreter releases while still supporting an old floor, and its development status is declared beta. Version numbers are not written in the file at all; they are computed at build time, which is why the repository carries an archival metadata file for source archives. The dependency list is the interesting part: several DVC-family packages are pinned to tight patch ranges, and the list includes a pure-Python git implementation, a file-locking library, a graph-layout library used to draw pipelines, a task queue with its client, and a telemetry package. That last one is a fact worth knowing if your environment is sensitive.
The repository commits its own data directory and ships itself as a hook
Two things in the file list show the tool being used on itself. There is a .dvc directory at the root and a .dvcignore file sitting next to the git ignore, which means the repository is itself set up as a DVC project. And there is a pre-commit hooks definition alongside the pre-commit configuration, which means DVC can be installed as a hook in other people's repositories rather than only as a command you remember to run. Around those sit the artefacts of a project that wants citing and archiving: a citation file, an archival metadata file for Zenodo, and a blame-ignore file so that bulk edits do not distort the history. Installation itself is offered through the editor extension, the usual system package managers for each platform, and plain language-specific package managers, with a separate route for an operating-system-specific package.
Editorial conclusion
DVC fits a team with large files and no budget for a data platform, whose Git repository already holds the code and whose collaborators will not install anything but a command line tool and a client. It does not fit a team that wants a hosted experiment service with a web UI, because the tracking store is the repository itself. Before you commit, read the stage definition format rather than the marketing, since the value is entirely in declaring dependencies and outputs so that unchanged steps are skipped. Check the dependency surface as well: installing DVC pulls a task queue, a graph layout library and a telemetry package, and the newest tagged release is 3.67.1 from 2026-03-31 while the default branch was pushed on 2026-11-02.
Frequently asked questions
What is DVC used for?
For developing reproducible machine learning projects. It versions data and models by storing the files in cloud storage while keeping their version information in the git repository, adds lightweight pipelines where only the steps affected by a change rerun, tracks experiments in the local repository without a server, lets you compare data, code, parameters, models and plots, and makes someone else's experiment reproducible.
What is Data Version Control (DVC) and how does it work?
Git stores your code and small meta-files that stand in for the data, while the data and model files themselves live in a cache outside the repository. That cache is shared through remotes, which can be cloud object stores or on-premise storage over SSH. Pipelines then declare each stage's inputs, outputs, metrics and command, which is what lets the tool skip unaffected steps, and experiments are recorded in the repository and compared on their parameters and metrics.
What are the key differences between lakeFS and DVC?
DVC's readme describes itself as like Git-LFS but without a server, and lays out its own model: placeholders and meta-files in git, a data cache outside it, remotes for sharing, pipeline stages with declared dependencies, and experiment records kept in the repository. Any comparison with a data-lake platform would be the reader's own analysis of those components.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Treeverse/Dvc: Data Versioning and ML ExperimentsHacker News · Nov 6, 2026 · 1 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/treeverse-dvc)Star history chart for your README
[](https://hysenlabs.com/projects/treeverse-dvc)Was this useful?