CHINESE-OCR: an anchor function with three dead parameters, and a test instruction naming a function that does not exist
End-to-end Chinese scene-text detection and recognition with CTPN, CRNN, and CTC (legacy project).
At a glance
- What is it?
- A three-network Chinese scene-text pipeline, a VGG16 angle classifier feeding CTPN detection feeding CRNN recognition, kept by its author as a historical project and carrying no open source license. The mechanics are documented well enough to argue with, and the details that will cost you an afternoon are in the anchor generator, the demo instructions and the training defaults.
- Who is it for?
- CHINESE-OCR is worth reading if you want the three-network layout in one place with both Keras and PyTorch training code, and the CTC explanation in the file is a genuinely good short explanation of why that decoder suits OCR. It is not a dependency to build on.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 86 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
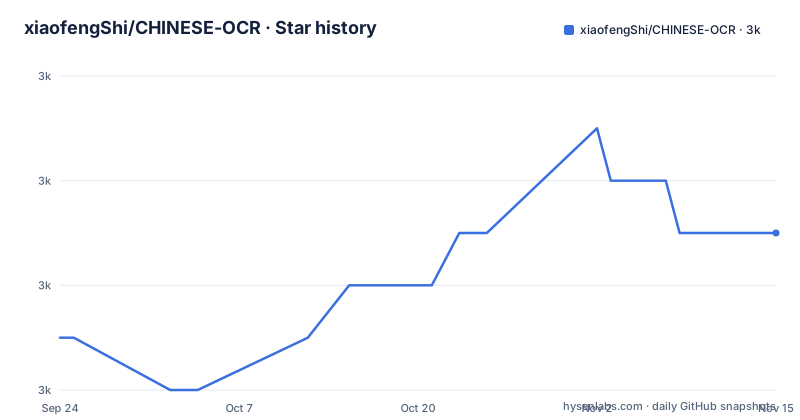
- xiaofengShi/CHINESE-OCR2,959 ★ · +2
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| xiaofengShi/CHINESE-OCR | 3k | 3k |
2 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The file declares itself historical and pins a decade-old stack
The first thing the page does is tell you not to start a new project on it. An important block states the maintenance status as a historical project, maintained only, built on Python 3.6, TensorFlow 1.x and earlier versions of Keras or PyTorch, and kept for research reproduction and community reference. It says feature development has stopped, that replies to questions may be slow, and that new users should read the existing issues first, with a warning that dependency versions and download links may already have expired. A later update note repeats the reason, saying the author changed jobs and direction, remains in computer vision but no longer in OCR, and now works on salient object detection and search intent. The last push to the repository is dated 2026-08-21.
No license is attached, and the README says so in a section of its own
There is a section devoted entirely to licensing, and it does not grant anything. It states that the repository currently carries no clear open source license, so copyright remains with the author by default, and that commercial use, redistribution, or large-scale derivative development requires contacting the maintainer first to confirm authorization. The license field for the repository is likewise empty. That combination, an author-retained copyright with an explicit request to get in touch, is workable for someone reading the code and awkward for anyone shipping it, and it is the first thing to resolve rather than the last. The practical difficulty is compounded by where the artefacts live: the pretrained weights, the VGG file, the CTPN dataset and the synthetic Chinese data are all linked to a single file-sharing service rather than to a package index.
The anchor generator accepts three arguments and uses none of them
CTPN detection is configured by an anchor function shown in full:
def generate_anchors(base_size=16, ratios=[0.5, 1, 2],
                     scales=2 ** np.arange(3, 6)):
    heights = [11, 16, 23, 33, 48, 68, 97, 139, 198, 283]
    widths = [16]
The signature advertises a base size, a list of width-to-height ratios, and a range of scales. The body uses none of the three: the ten heights are hardcoded, the width list holds a single value, and the two collections of numbers are never referenced. So a reader who tunes the ratios or the scales gets no change in behaviour and no error, which is the worst kind of configuration surface. The consequence is stated plainly afterwards, that with widths fixed at one value the detector can only find horizontal text, and that supporting vertical text requires editing this function.
One accuracy figure exists, and it belongs to the angle classifier
Three networks are described: an angle classifier built on VGG16, a CTPN detector combining a CNN with an RNN, and an end-to-end CRNN recognizer combining a CNN with a GRU or LSTM and a CTC head. Numbers appear for only the first. The angle section reports training on 8,000 images with an accuracy of 88.23 percent. No detection or recognition accuracy is given anywhere for the other two, which are the parts that decide whether the pipeline works on your images. The results section makes the same gap visible: what is presented as recognition output is a run of separator lines. The one qualitative explanation offered is that training covered only Chinese characters and English letters, so formula structures are largely not recognised.
The demo step tells you to edit a call that cannot work
Running the pretrained demo is described in one sentence: run `demo.py` and write in the path of your test image. To see the detector's boxes you are told to modify the last part of the `draw_boxes` function in `./ctpn/ctpn/other.py`, giving the line as `cv2.inwrite('dest_path',img)`. That function name is the problem. The OpenCV function for writing an image is `imwrite`, and there is no `inwrite`, so following the instruction as printed raises an attribute error on the line you were told to add. The destination is also given as the literal string `dest_path` rather than a path, so two changes are needed before the call means anything. Training instructions have a smaller version of the same slip, pointing at `.ctpn/lib/datasets/pascal_voc.py` with a leading dot two lines after using `./ctpn/ctpn/train_net.py`.
The PyTorch defaults are Chinese sentences inside an argparse call
The CRNN training section shows the argument parser for the PyTorch script, and both defaults are prose rather than values:
parser.add_argument(
    '--crnn',
    help="path to crnn (to continue training)",
    default=预训练权重的路径,看你下载的预训练权重在哪啦)
That is not valid Python, and the second argument carries the same problem with a note to choose your own save location. Anyone following the section is expected to replace the defaults, which is fine as a template but should not be mistaken for a runnable snippet, since the file presents it the same way it presents the working `demo.py` instruction. Three model definition files also sit loose at the top of the repository rather than inside their packages: `keras_model.py`, `model.py` and `pytorch_model.py`, next to a Jekyll config and a checked-in editor directory, with the Keras and PyTorch training code in separate subdirectories below.
Two dataset figures collide and two paper links are malformed
The training data section is thorough, listing Chinese text in the wild, RCTW-17, an ICPR competition set, Total-Text, Google street view text, COCO-TEXT and three synthetic corpora with sizes and splits. Two entries need care. In the first, the test split and the validation split are given different image counts, 3,269 and 3,129, but the identical character count of 103,519 for each, which is the kind of duplication that comes from copying a line. And two of the cited paper links are written with a space between the scheme and the host, in the Total-Text and street view entries, so they will not resolve as written. The weights problem is the same shape as the licensing one: with every artefact on one file-sharing service, availability is a property of your network rather than of the repository.
Editorial conclusion
CHINESE-OCR is worth reading if you want the three-network layout in one place with both Keras and PyTorch training code, and the CTC explanation in the file is a genuinely good short explanation of why that decoder suits OCR. It is not a dependency to build on. The file declares the project historical, pins Python 3.6 and TensorFlow 1.x, warns that its download links may have expired, and attaches no license at all, with copyright retained by the author. Before you copy any of it, check the three things the documentation itself undermines: the anchor function ignores two of its own arguments, the demo instruction calls an OpenCV function that does not exist under that name, and the PyTorch training snippet has Chinese prose where Python defaults belong.
Frequently asked questions
What is xiaofengShi/CHINESE-OCR?
An end-to-end Chinese scene-text detection and recognition project built on TensorFlow with Keras and PyTorch versions. It uses three networks: a VGG16-based classifier for 0, 90, 180 and 270 degree text orientation, CTPN for text region detection, and a CRNN with CNN, GRU or LSTM and a CTC head for variable-length recognition without segmentation.
Is CHINESE-OCR still actively developed?
The file states the maintenance status as a historical project maintained only, built on Python 3.6, TensorFlow 1.x and older Keras or PyTorch, kept for research reproduction and community reference, with no further feature development and possibly slow replies. It also warns that dependency versions and download links may have expired. The last push is dated 2026-08-21.
What license is CHINESE-OCR under?
None is attached. The file has a licensing section stating that no clear open source license is included, that copyright remains with the author, and that commercial use, redistribution or large-scale derivative development requires contacting the maintainer first.
How do I run the CHINESE-OCR pretrained demo?
Run demo.py and enter the path of a test image. To draw the detected boxes you are told to modify the last part of the draw_boxes function in ./ctpn/ctpn/other.py, though the line given there is written as cv2.inwrite, and the OpenCV function is named imwrite.
Why does CHINESE-OCR use CTC instead of sequence to sequence?
CTC avoids needing per-character position labels: the input sequence must be at least as long as the output, and you only need the whole label rather than where each character sits. The file notes that labelled positions would reduce the task to single-character recognition, but that data at that density is not available. The alternative described is a convolutional encoder with an RNN decoder, usually with attention.
Can CTPN in CHINESE-OCR detect vertical text?
Not with the anchor setup as shipped. The anchor widths are fixed at a single value of 16 while ten different heights are listed, so the detector is limited to horizontal text, and the file says supporting vertical text requires modifying the anchor generation function.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xiaofengshi-chinese-ocr)Star history chart for your README
[](https://hysenlabs.com/projects/xiaofengshi-chinese-ocr)Was this useful?