bilingual_book_maker sends an epub tag by tag, and skips the ones a model says to skip
Make bilingual epub books Using AI translate
At a glance
- What is it?
- bilingual_book_maker turns epub, txt, md, srt and pdf files into bilingual editions by asking an LLM endpoint to translate them. The interesting split is between endpoints that can hold a conversation and translation engines that cannot, because only one of those two can classify tags.
- Who is it for?
- Adopt this tool when you hold the rights to the source text and you have an endpoint that can answer a structured classification prompt, which is what makes the tag-level skip and translate decisions reliable. Do not reach for it if poetry and verse matter, because the machine translation routes fall back to `p` tags alone and the project says verse may be omitted.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 16 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
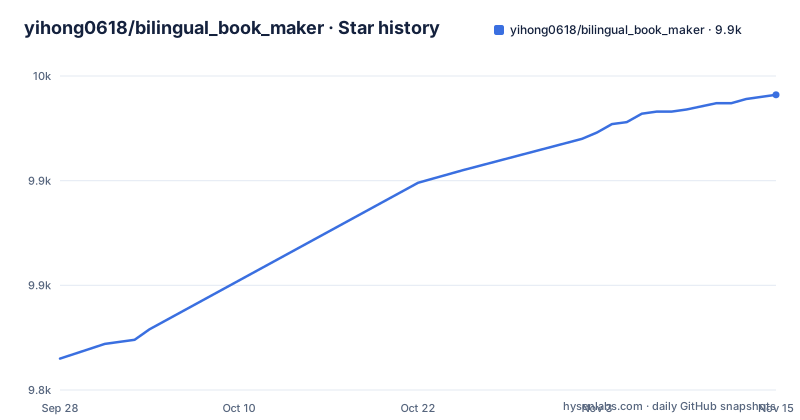
- yihong0618/bilingual_book_maker9,941 ★ · +126
| Repository | 2026-09-28 | 2026-11-15 |
|---|---|---|
| yihong0618/bilingual_book_maker | 9.8k | 9.9k |
126 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Install from requirements.txt or the bbook_maker package, then translate a few paragraphs
Preparation is a token, a book, and Python 3.10 or newer. The package installs two ways, from the pinned file or from PyPI under a different name.
pip install -r requirements.txt # or: pip install -U bbook_maker`requirements.txt` is generated by PDM and every entry carries a sha256 hash, so a plain `pip install -r` gives you a reproducible dependency set rather than floating versions. The PyPI name is `bbook-maker` while the repository is `bilingual_book_maker`, which trips people up when they search for the package.
A sample book ships in the repository at `test_books/animal_farm.epub`, and `--test` limits the run to its first few paragraphs. That is the fastest way to find out whether your key and endpoint work before you pay for a whole book.
python3 make_book.py --book_name test_books/animal_farm.epub --provider openai --test --use_context sessionThe run needs an environment with internet access or a proxy. Nothing is done offline, and the book text leaves your machine for whichever endpoint you name.
Three ways to pass credentials, and --api_format decides which vendor answers
The command line takes a key directly, in which case the format flag picks the vendor and the model flag names the model:
python3 make_book.py --book_name test_books/animal_farm.epub \
  --key sk-... --model gpt-6-luna --api_base https://api.openai.com/v1 --test --use_context session
A format that belongs to one vendor already knows that vendor's address, so `--api_format openai` plus `--key` is a whole command with no `--api_base`. `--api_base` is for any other OpenAI-compatible endpoint and ends in `/v1`. `--api_format` also covers `anthropic`, `gemini`, `qwen`, `groq`, `xai`, `litellm` and `codex`, plus the translation services `google`, `caiyun`, `deepl`, `deeplfree`, `tencent` and `customapi`.
The third route is a config file. `bbm_providers.example.json` carries an entry for Gemini, Qwen, xAI, Groq, OrcaRouter, Ollama, LiteLLM, SiliconFlow and OpenRouter, and you copy it into place and edit three fields.
cp bbm_providers.example.json bbm_providers.json
# edit base_url, default_models and env_key in ./bbm_providers.json
After that, `--provider gemini` picks Gemini out of the file. The separate `env_key` field is what lets the key stay out of the command line. Older spellings such as `--model gpt4o` and `--openai_key` are still accepted, which matters because the wiki keeps both sets of notes.
Epub tags are classified only on endpoints that hold a conversation
This is the design decision that separates two uses of the same binary. On JSON-schema endpoints, epub tag classification switches on automatically, and the model returns exact `skip` or `translate` verdicts. On any endpoint that can hold a conversation, including the codex route and what the README calls plain reseller proxies, it also switches on automatically and still asks for those verdicts.
Only the machine translation routes behave differently. When an endpoint has no conversation at all, the MT engines, the tool falls back to translating `p` tags only, which means paragraph tags. The project says plainly that some poetry or verse may be omitted there.
So the same epub, the same model family, and the same command produce different output quality depending on which route answers. On a conversation route the model is asked for skip or translate verdicts on epub tags. On an MT route those tags are passed over because there is nothing to ask with. For a book of verse this is the difference between a readable bilingual edition and a file with gaps in it, and the choice is made by the endpoint, not by a flag you can add later.
You can also spend a Codex subscription instead of an API key, which swaps the quota rather than the endpoint format.
python3 make_book.py --book_name test_books/animal_farm.epub --model gpt-6-luna --api_format codex --testSession mode keeps one 8k history so a character's name stops drifting
`--use_context session` turns on a mode where the whole book shares one conversation history. Consistency is the point: recurring names stay stable from chapter to chapter instead of being re-invented per request. The history compacts at 8k by default, and `--context-compact-at` moves that threshold.
Compaction is the cost of the feature. Past the threshold the history compacts. The project recommends session mode on OpenAI-compatible endpoints and uses it in its own examples.
On top of that sits an optional glossary.
`--glossary-auto on` turns on glossary learning, and it is off by default. The glossary is learned from the model's own handoff reports, so the terminology list grows during the run.
The two flags interact. Session mode without the glossary gives you name stability within the context window. Session mode with `--glossary-auto on` gives you a term list as well, at the cost of letting the model decide what to record.
PDF support is an extra on purpose, because it brings PyTorch
`--to-epub` reads a PDF with docling, which uses layout and table models, and pdfium measures what a page actually shows so a scanned page can be told from a typed one before the heavy models start. Neither is a base dependency, and `pyproject.toml` explains why in the manifest comment: most users translate epubs and never open a PDF, and PyTorch is a large thing to install on every machine.
The fallback is refusal rather than degradation. The manifest states that a PDF without those packages is refused with the install line, never read by something weaker. That is the right call and also a visible one: your run stops and tells you what to install instead of producing a translated PDF full of holes.
Two separate requirement files exist for this path, `requirements-pdf-cpu.txt` and `requirements-pdf-gpu.txt`, and the manifest makes a deliberate point about them: it declares what is needed and never which PyTorch build, because a PyPI package cannot pin a build that depends on your CUDA version. The CPU and GPU choice is therefore yours to make at install time, not something the package resolves.
The cost of all this is visible in the container sizes below. Reading a scanned page is a different job from translating a paragraph, and the tool treats it as one.
The Dockerfile publishes three images, and the pdf tag is 2.35 GB
One Dockerfile builds three images. `core`, tagged `latest`, `basic` or `<version>`, is `python:3.12-slim` and handles EPUB, TXT, Markdown, SRT, plus PDFs on the older text route. `pdf`, tagged `pdf` or `<version>-pdf`, adds Pandoc and the PDF packages with PyTorch's CPU build, for amd64 and arm64. `pdf-cuda`, tagged `pdf-cuda` or `<version>-pdf-cuda`, starts from the official `pytorch/pytorch` CUDA runtime image and is amd64 only.
The sizes are recorded in the file itself, measured with `docker image inspect`: core is 278 MB, pdf is 2.35 GB, of which the PDF packages are 1.66 GB and torch 2.7.1+cpu is 0.69 GB. The CUDA base is a 3.4 GB compressed download on its own. Every tag also exists as `sha-<commit>` with the same suffix, so you can pin an image to a commit.
Two host constraints are spelled out. GPU here means NVIDIA CUDA and nothing else, so an arm64 host with a card such as a GH200 or a Jetson has no matching tag. And on macOS any container is CPU-only, because Docker runs a Linux VM that cannot see Metal; the file says a native install is faster there. On Windows the GPU route needs the WSL-capable NVIDIA driver through Docker Desktop, since Windows-containers mode cannot reach the GPU at all. `--device cpu` skips the detection, and pdf-cuda runs on CPU too, but pdf is the smaller image when you are not using the GPU.
socksio is declared because httpx raises on every proxied request without it
One dependency in `pyproject.toml` carries a comment longer than most changelog entries. httpx honours an `all_proxy=socks5://` setting only when socksio is installed, and raises on every request without it. The comment records that a pinned `requirements.txt` used to drag socksio in through a stale lock entry, and that it is now declared so a `pip install` has it too.
That is a small thing with a large blast radius for the users it targets. A SOCKS proxy is common in front of these APIs for a lot of this tool's audience, and without the package every single request fails rather than degrading.
Two other pins in the same manifest have reasons attached. `openai>=1.92.0` is required because `chat.completions.parse`, the Structured Outputs call behind the JSON-schema tag classification, does not exist before 1.92. So on the oldest supported route, the version floor is what makes automatic epub tag classification possible at all. And `tiktoken` sits in the base dependency list rather than an extra, which suits token counting for the 8k compaction threshold in session mode.
The remaining base dependencies are the SDKs and parsers the job needs: `anthropic` and `google-genai` for the non-OpenAI routes, `ebooklib` for epub in and out, `bs4` for HTML, `PyMuPDF` for PDFs on the text route, plus `tenacity` for retries, `tqdm` for progress, `rich` for terminal output and `pydantic` for the structured verdicts.
Prompts are repository files, so a bad translation is something you can edit
The prompts are not buried in code. The root holds `prompt_md.prompt.md`, `prompt_template.json`, `prompt_template_sample.txt` and `prompt_md.json`, which by their names look like the prompt files. When a model keeps translating something it should skip, or skips a heading it should translate, the first place to look is these files rather than the Python.
The layout is otherwise plain. `make_book.py` is the entry point, `book_maker/` holds the package, `tests/` holds `tests/test_integration.py`, `docs/` plus `mkdocs.yml` drive the documentation site, and `tools/` holds helper scripts. The `Makefile` has three targets: `fmt` runs `venv/bin/black .`, `tests` runs `venv/bin/pytest tests/test_integration.py`, and `serve-docs` runs `mkdocs serve`.
That test target matters more than it looks. The Makefile runs only tests/test_integration.py. The CI badge in the README points at a workflow named `make_test_ebook.yaml`, which suggests the sample epub is what gets run.
Two other routes in exist for running this. There is a `Dockerfile` for container use, and there is a skill for coding agents. Clone and hand it a sentence:
git clone https://github.com/yihong0618/bilingual_book_maker.git
cd bilingual_book_maker
codex "Hi, please use bbm-plan to translate this book: test_books/animal_farm.epub into a bilingual Chinese-English edition, thanks."
The legal position is yours, not the tool's. The README restricts use to material you have the right to translate, covering works you hold the necessary rights for, suitably licensed or permitted works, public-domain books, or uses otherwise allowed by applicable law, and it asks you to read `disclaimer.md` first. A translation of a whole book is a derivative work, and no flag in this command line changes that.
Editorial conclusion
Adopt this tool when you hold the rights to the source text and you have an endpoint that can answer a structured classification prompt, which is what makes the tag-level skip and translate decisions reliable. Do not reach for it if poetry and verse matter, because the machine translation routes fall back to `p` tags alone and the project says verse may be omitted. Verify first that your endpoint is a conversation route rather than an MT engine, since that single choice decides whether chapter titles and other non-paragraph tags get translated at all.
Frequently asked questions
How do I install bilingual_book_maker?
Either run `pip install -r requirements.txt` from the repository, which is a PDM-generated file with pinned hashes, or `pip install -U bbook_maker` to get the package from PyPI. Python 3.10 or newer is required.
Does bilingual_book_maker handle PDF files?
Yes, through the `--to-epub` route, which uses docling for layout and table models and pdfium to tell a scanned page from a typed one. Those packages are optional because they bring PyTorch, and a PDF without them is refused with the install line rather than read by something weaker.
Which translation APIs can bilingual_book_maker call?
The `--api_format` flag covers openai, anthropic, gemini, qwen, groq, xai, litellm and codex, plus the services google, caiyun, deepl, deeplfree, tencent and customapi. A JSON config file named `bbm_providers.json` holds entries for Gemini, Qwen, xAI, Groq, OrcaRouter, Ollama, LiteLLM, SiliconFlow and OpenRouter.
Will the poetry in my book get translated?
Not on every route. Automatic epub tag classification needs an endpoint that can hold a conversation and return skip or translate verdicts, and the routes with no conversation at all, the MT engines, fall back to translating `p` tags only, so some poetry or verse may be omitted.
Can bilingual_book_maker use my ChatGPT subscription instead of an API key?
Pass `--api_format codex` to spend a Codex subscription instead of paying per request through an API key. The codex route is treated as a conversation endpoint, so epub tag classification still switches on automatically.
How large is the Docker image for bilingual_book_maker?
The core image on linux/amd64 is 278 MB and handles epub, txt, markdown and srt. The pdf tag is 2.35 GB with the PDF packages and PyTorch's CPU build, and the pdf-cuda base is a 3.4 GB compressed download on its own.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yihong0618-bilingual-book-maker)Star history chart for your README
[](https://hysenlabs.com/projects/yihong0618-bilingual-book-maker)Was this useful?