skill-seekers pins three different version numbers, and its requirements file contradicts its own manifest
Convert documentation websites, GitHub repositories, and PDFs into Claude AI skills with automatic conflict detection
At a glance
- What is it?
- Skill Seekers turns documentation sites, GitHub repositories, PDFs and other sources into structured knowledge assets for AI systems, exporting to a long list of targets and running as a CLI or an MCP server. It ships on PyPI under an MIT licence with a push to its development branch on 2026-09-30. Two inconsistencies are worth knowing before you install it. Three different version numbers appear across its packaging files, and its pinned requirements file names a version of the Anthropic client that its own manifest says is too old.
- Who is it for?
- This suits someone who has a documentation set they want an agent to actually read, and who would rather not hand-write a retrieval layer over it. The design is the reason: scraping and packaging are separate steps from AI enhancement, which runs through an agent (Claude by default).
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 45 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
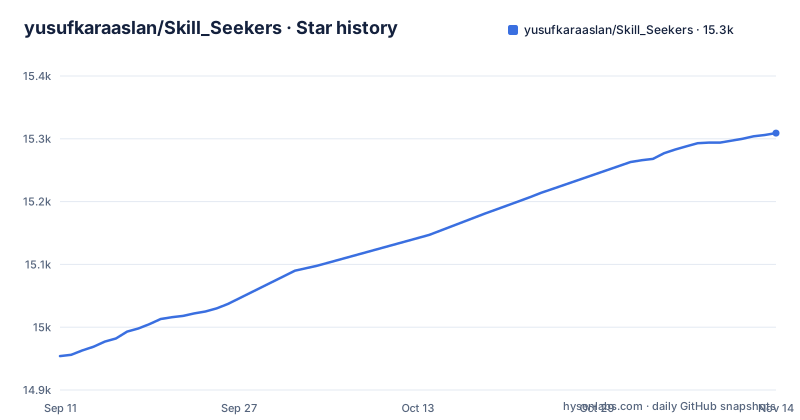
- yusufkaraaslan/Skill_Seekers15,309 ★ · +355
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| yusufkaraaslan/Skill_Seekers | 15k | 15.3k |
355 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three packaging files carry three different version numbers
Look for the version in three places in this repository and you will get three answers.
The project manifest declares the package version as a development build of 3.11.0. The published releases stop at 3.10.0, released 2026-09-30, after 3.9.1 in August and 3.9.0 in July. And the container file carries a label saying 3.9.0.dev0, which is a version number two minor releases behind what the manifest declares.
The default branch is named development rather than main, which is consistent with the manifest carrying a development version. So the pattern is coherent in one direction: the manifest is ahead of the releases, which is what a development branch should look like.
The container label is the outlier. It is baked into the image at build time, and a label is easy to forget to bump. That is not dangerous in itself, since the label is metadata rather than behaviour, but it does mean anyone reading the image to identify what is running gets an answer two versions old.
The consequence is that there is no single place to check what you have. Read the installed package metadata rather than the container label, and if you pin a version in your own build, pin to a published release rather than to whatever the development branch happens to say.
The pinned requirements name an Anthropic client older than the manifest's own minimum
This repository ships two dependency specifications and they do not agree.
The project manifest lists its dependencies with lower bounds, and among them a minimum of 0.76.0 for the Anthropic client, marked in a comment as required for AI enhancement. Alongside it, an HTML parser is marked as a lenient fallback for broken markup, and an async HTTP client is marked as required for async scraping, which is also called a core feature.
Now the pinned requirements file, which lists exact versions with no ranges at all. It names the Anthropic client at 0.40.0. That is below the minimum the manifest states.
So one file says at least 0.76.0 is required and the other pins 0.40.0. Both cannot be satisfied at once.
This matters more than a stale lockfile usually would, because the Anthropic client is on the path for AI enhancement. A version from before the manifest's floor may not have the interface the code expects, and the failure would appear at the point where you invoke enhancement rather than at install time.
The consequence is that you should install from the manifest, letting the resolver choose, rather than forcing the pinned file. If you need reproducible builds, regenerate the pinned set rather than trusting it, and check the Anthropic version specifically before you rely on the enhancement path.
The base package is deliberately small and every other source needs its own extra
Installation is one command for the core and a long menu of extras for everything else, and the split is finer than most projects of this kind.
The core install covers scraping, GitHub repositories, PDF handling and packaging. That is the whole floor. Beyond it there is an extra for each model platform, one for all of them at once, one for the MCP server, one for video transcripts and metadata, one that adds transcription and visual frame extraction on top of video, and separate extras for Jupyter notebooks, PowerPoint, Confluence, Notion, RSS and Atom feeds, Slack and Discord chat export, and AsciiDoc.
There is also a wizard, a separate command, for anyone who cannot decide:
pip install skill-seekers              # Core: scraping, GitHub, PDF, packaging
pip install skill-seekers[all-llms]    # + every LLM platform
pip install skill-seekers[mcp]         # + MCP server
pip install skill-seekers[all]         # Everything
The stated prerequisites are Python 3.10 or later, and Git.
The reason the split is this fine is the dependency weight. After installing the video extra that adds transcription, the front page instructs you to run a setup command that detects your GPU and installs the matching PyTorch variant plus easyocr. That is a large download, which is why it is not in the base install.
The consequence is practical: a missing source type is nearly always a missing extra rather than a defect. If a particular format is not recognised after install, check which extra covers it before assuming the tool cannot read it.
Detection runs as a separate command so you can see what a source is before creating anything
There is a dry-run capability, and its presence tells you something about how the tool handles source variety.
The documented flow is install, create, package. Alongside create there is a detect command that reports how a source would be handled without producing anything, and it takes a JSON output flag.
That separation is useful because the input space is wide. The front page claims eighteen source types, and they are detected from the input rather than declared by you: a GitHub shorthand like an organisation and repository name, a local directory, a PDF, a Word document, an EPUB, a Jupyter notebook, an OpenAPI specification, a PowerPoint file, an AsciiDoc file, a local HTML page.
A repository shorthand and a local directory both go to the same command. The tool has to infer the type from the shape of the argument, which is exactly the step that can be wrong when a site is unusual or a document is mislabelled.
So run detect first. It costs nothing, it tells you what the tool thinks it is looking at, and on a large documentation site that is the difference between a sensible scrape and a wrong one that takes an hour to produce.
The project scan hands framework detection to a model, and can publish the result
One command routes source detection through an AI agent rather than through rules, and that is a design choice with consequences.
The scan command points at a project directory and an agent reads its manifests, its README, its container and CI files, and a sample of its source imports. It then emits one configuration file per detected framework, plus a codebase JSON file for the project's own code. The documented example names the outputs: React, Vite, Tailwind and Jest configurations, plus a codebase file.
Each of those can be handed straight to create, so a detected configuration is not an intermediate report but the input to the next step.
The consequence is that the detection quality depends on which agent you point at it, and the agent defaults to one particular assistant unless you override it. You can also pass a completely custom command as the agent, which is the extension point for using your own tooling.
The second consequence is about where the output goes. When a detected framework has no existing preset, the tool generates a fresh configuration, and on exit you can optionally publish it to a community registry hosted in a separate repository. Publishing is opt-in rather than automatic, which is the right default, but it does mean generated configurations can become shared artefacts. Read one before you send it.
The container ships an MCP server with anonymous vector database access enabled
The deployment files configure a stack that is convenient for evaluation and needs attention before it faces anything real.
The compose file defines the CLI application, an MCP server in HTTP mode, and a Weaviate vector database among its services. The MCP server publishes a port, sets its transport and port through environment variables, mounts the data, configs and output directories, and declares a health check against a health endpoint on a thirty second interval.
The vector database is configured with anonymous access enabled and with the default vectorizer module set to none and no modules enabled. Anonymous access and no vectorizer is a coherent combination for a demo where the vectors come from elsewhere, but it is not a production posture.
Four API keys are passed through as environment variables to both application services: one for each of three model providers, plus one for GitHub.
The container itself is more careful. It builds in one stage and runs in another, creates a non-root user with a fixed identifier, chowns the writable directories to that user, switches to it, and copies the installed packages rather than the build tree.
So the image is sound and the compose file is a starting point. Treat the anonymous vector database access as something to change before anything you care about is indexed into it.
The front page has eleven language versions and none of them changes the content
Localisation here is broad in coverage and thin in depth, and that is worth understanding before you rely on a translation.
The front page exists in twelve languages: English, Simplified Chinese, Japanese, Korean, Spanish, French, German, Brazilian Portuguese, Turkish, Arabic, Hindi and Russian. Each is a separate file at the top of the repository, linked in a single row at the top of the English page.
The content behind them is the same front page, which is installation instructions, a source list, a documentation index and a table of extras. The repository's own metadata lists only English and Simplified Chinese as declared natural languages for the package.
So the translations cover the readme, and the packaged distribution declares two languages.
The consequence is that a translated readme tells you the install command and the source types in your language, and then hands you documentation paths that lead to whatever language the documentation is in.
That is a reasonable division of labour for a project with one author and eleven translations, and better than having no translation at all. Just know which part you are getting.
Editorial conclusion
This suits someone who has a documentation set they want an agent to actually read, and who would rather not hand-write a retrieval layer over it. The design is the reason: scraping and packaging are separate steps from AI enhancement, which runs through an agent (Claude by default). Check two things first. Which extras you install, because the base package is deliberately small and the video, notebook, wiki and presentation sources each need their own extra, so a missing import is usually a missing extra rather than a broken install. And which version you are on, since three different numbers appear across the manifest, the container file and the release list and a mismatch between the manifest and the pinned requirements is a real possibility rather than a theoretical one.
Frequently asked questions
how to use skill seekers
Install it with pip, then create a skill from a source and package it for a target platform. The documented sequence is `pip install skill-seekers`, then `skill-seekers create https://docs.djangoproject.com/`, then `skill-seekers package output/django --target claude`, which produces a zip. A detect command reports how a source would be handled without creating anything, and Python 3.10 or later plus Git are the stated prerequisites.
What licence is Skill Seekers under?
MIT, declared as text in the project manifest and matching the licence file at the top of the repository. The package is built with setuptools as an ordinary Python distribution on PyPI, requires Python 3.10 or later, and is classified as operating system independent.
What source types does Skill Seekers support?
Eighteen, claimed on the front page, and detected from the input rather than declared by the user. The examples given include a GitHub repository in organisation and name form, a local codebase directory, a PDF, a Word document, an EPUB, a Jupyter notebook, an OpenAPI or Swagger specification, a PowerPoint file, an AsciiDoc file and a local HTML page, with video, wikis and feeds among the rest.
Does Skill Seekers need an API key?
For its AI enhancement and project scan features, yes. The container deployment passes keys for three model providers and for GitHub through environment variables. The core install covers scraping, GitHub repositories, PDF handling and packaging, and the dependency list marks both the async HTTP client and the Anthropic client as required for core features, so plan on credentials for the parts of the workflow that use a model.
What is the latest version of Skill Seekers?
The most recent published release is 3.10.0 from 2026-09-30. The project manifest on the default development branch declares a development build of 3.11.0, and the container file carries a label saying 3.9.0.dev0. The default branch took a push on 2026-09-30.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yusufkaraaslan-skill-seekers)Star history chart for your README
[](https://hysenlabs.com/projects/yusufkaraaslan-skill-seekers)Was this useful?