R-KV: redundancy-aware KV cache compression, and a shipped dataset that froze accuracy at 40 percent
[Neurips 2025] R-KV: Redundancy-aware KV Cache Compression for Reasoning Models
At a glance
- What is it?
- A NeurIPS 2025 method that discards repetitive tokens from the key-value cache during decoding, with four serving ports and a published warning that GSM8K numbers computed before a mid-2026 commit were wrong. The repository also ships a .DS_Store and a committed local history folder.
- Who is it for?
- R-KV fits a team serving reasoning models on constrained GPUs that has already accepted patching an inference server, since the production ports are patches over pinned upstream checkouts rather than drop-in packages. It does not fit anyone who wants a library-level change or a fresh set of numbers without re-running them.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
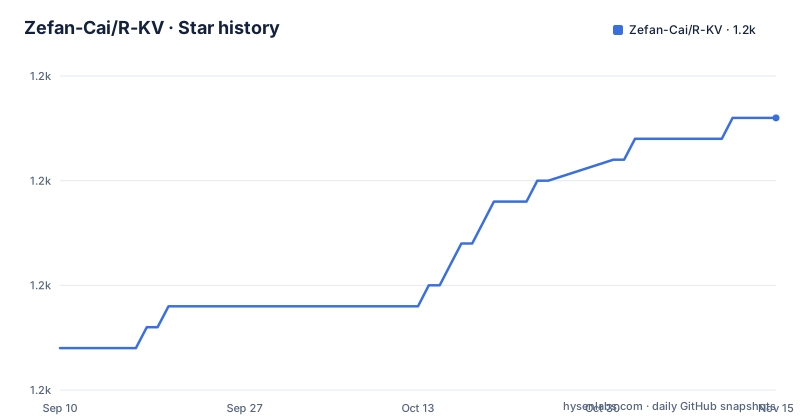
- Zefan-Cai/R-KV1,223 ★ · +11
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| Zefan-Cai/R-KV | 1.2k | 1.2k |
11 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The shipped GSM8K file froze scores near 40 percent
One news entry is a retraction, and it is the most useful thing in the README.
The data file that ships with the repository, data/gsm8k.jsonl, carried a stale generation field left over from an earlier experiment. The evaluation script, eval_math.py, preferred that field over the output of a fresh run. The effect was that GSM8K scores sat at roughly 40 percent no matter which method or budget was configured, which is the kind of flat result that looks like a failed experiment rather than a bug.
The README names the commit boundary. Anyone who computed GSM8K numbers before commit e9f54c45 is asked to re-run them, and the two issues tracking the problem are referenced. MATH and AIME24 were unaffected, which means the flat line appeared on one dataset rather than across the evaluation.
What followed is the part that suggests the maintainers took it seriously. All four serving integrations, vLLM, SGLang, Nano-vLLM and Mini-SGLang, plus the HuggingFace path, were validated on an A100 with R-KV both on and off, and the smoke tests and raw artifacts live in the repository under tests/smoke/ and a dated results directory.
For a research repository this is the behaviour you want: a published number was wrong, it was announced, and the fix came with evidence attached.
Compression switches itself on when a budget is set
There is no enable flag. Compression activates automatically once the budget and the buffer are both greater than zero, which for the vLLM port means setting the two environment variables for the budget and the buffer.
That is a deliberate-looking choice and a slightly hazardous one. A serving deployment that sets a KV budget to control memory will get eviction whether or not anyone realised the budget implies R-KV, so the change from full cache to compressed cache is invisible in the command line and shows up only in behaviour.
The other piece of advice is counter-intuitive enough to quote. The README says not to pass the eager-execution flag, because R-KV selects the piecewise CUDA graph mode itself once compression is active. The performance entry confirms it: the port runs in-graph piecewise cudagraph decode without that flag, which is one of the reasons the throughput numbers improved.
So the operational model is: set the budget, let the runtime choose its own execution mode, and do not add the flag you would normally reach for when customising a CUDA-graph path.
The reference ports do require the opposite. Nano-vLLM, the roughly twelve-hundred-line paged-KV engine, needs eager execution enforced, since it is a teaching implementation rather than a tuned server.
Patch, not fork, for both production ports
The two integrations that matter are deliberately not forks, and the same layout is used for both.
For vLLM at version 0.25.1, an apply script clones the pinned upstream checkout, drops in the algorithm directory and applies a wiring patch, after which the package is installed from source and needs CUDA and a GPU. The SGLang port at version 0.5.14 does the same thing, then installs the pinned stack from an extra index URL, plus a separate requirements file for the compression extras.
Patch-not-fork has one clear benefit and one clear cost. The benefit is that rebasing onto an upstream release is a patch conflict rather than a merge of a divergent tree. The cost is that the installation is a script that clones and patches, so your environment is now produced by a shell command in a research repository rather than by a package manager.
The two lightweight ports are for reading rather than serving. Nano-vLLM is a small paged-KV inference engine with R-KV plugged into the attention path. Mini-SGLang carries the algorithm and a paged-cache integration helper under its compress package, with the attention-layer wiring described in its own documentation.
So there are four integrations at three levels of maturity, and only the two patched ones are described as performance-hardened.
The throughput numbers are memory-bound and quoted as ranges
The performance claims are specific about the condition that produces them.
For vLLM, the reported gain is 17 to 32 percent more tokens per second at GPU memory fractions between 0.40 and 0.25, and it is described as a memory-bound throughput win rather than a compute win. The mechanism is that a shrinking KV pool lets more requests stay in flight, and the additions that make that pay off are in-graph decode, asynchronous scheduling, batched cross-layer redundancy scoring, and bounded-footprint block freeing that returns evicted KV to the allocator instead of holding it.
Accuracy is reported as lossless at a budget of 512 on GSM8K. The SGLang port makes the same claim at the same budget and adds that throughput sits within a few percent of a fair full-cache baseline. The earlier SGLang validation was on Qwen2.5-Math-7B on an H100 with 95 percent on GSM8K, matching the baseline.
Parallelism is where the largest multiples appear. Data parallelism scales 7.6 times on eight H100s for the vLLM port and 7.8 times for SGLang. Two details make that credible rather than magic: every tensor-parallel rank evicts the identical set, and the SGLang port validates its ranks with a cross-rank eviction-score all-reduce.
What the claims do not cover is a second model family or a second benchmark for throughput, so treat them as one configuration measured carefully.
The evaluation knobs live on the command line
The quick start offers a script and a raw command, and the raw command is where the method's parameters are visible:
python3 ./run_math.py \
--dataset_path ./data/aime24.jsonl \
--save_path ./outputs/output.jsonl \
--model_path deepseek-ai/DeepSeek-R1-Distill-Llama-8B \
--max_length 32768 \
--eval_batch_size 1 \
--method rkv \
--kv_budget 1024 \
--window_size 8 \
--mix_lambda 0.1 \
--divide_method step_length \
--divide_length 128 \
--do_sample
Six of those flags are the method itself. The KV budget is the cache allowance. The window size is the local window kept regardless. The mixing parameter blends the two decisions. The divide method and divide length say how the sequence is segmented before redundancy is scored, which is step-length based here rather than block based. The remaining flags are evaluation plumbing.
Defaults matter more than usual in this kind of work, and the risk from the dataset bug is that a run can look plausible while measuring nothing.
Two setup steps are easy to miss. The HuggingFace path needs flash attention selected explicitly through the model's attention implementation argument, and the evaluation toolkit has its own build: a separate directory for a latex-to-sympy component that is pip-installed editable before the main requirements are installed.
A .DS_Store and a committed history folder are in the root
Two files in the repository root are worth naming, because neither belongs in version control. A .DS_Store file from macOS Finder is committed at the top level, and a .history directory is committed alongside it, which is the folder an editor's local history feature writes when it keeps per-file backups.
Neither affects the method. Both affect how the repository reads: the history folder suggests that editor backups have been committed along with real changes at some point, and the presence of a Finder artefact tells you the tree is being used from macOS without a global ignore in place.
The dependency story is a forwarder. The root requirements.txt does not list anything itself; it includes the requirements file from the HuggingFace directory, with a comment saying those are the minimal dependencies for that implementation. The install instruction is therefore a single pip command that resolves somewhere else in the tree.
Packaging is minimal in the same way. setup.py is five lines: a package name of rkv, version 0.1.0, and packages discovered from the tree. There is no pyproject at the root in the listing, and no wheel metadata to speak of.
Licensing is the item to resolve before anything else. There is no LICENSE file at the repository root and the license metadata carries no recognised identifier, so the repository does not state its terms even though the paper is published and the method is meant to be used.
The TODO is a better roadmap than most changelogs
The task list at the top of the README is maintained with evidence rather than aspiration, and the struck-through items are the interesting part.
Two items are marked done. Benchmark coverage across vLLM, Nano-vLLM and SGLang was hardened, with the parenthetical pointing at the smoke tests, the throughput benchmark and raw artifacts, and CPU tests in continuous integration. Performance hardening of the production serving ports was completed with in-graph decode, asynchronous scheduling, batched cross-layer scoring, bounded-footprint eviction, and tensor plus data parallelism.
Each done item names where the evidence lives, which is why the claims in the news section can be checked rather than taken on faith.
What remains is a short and honest list: apply the method to GPT-OSS, integrate with the VeRL training framework, extend the dataset to GPQA and liveCodeBench, apply it to QwQ, and expand Qwen-3 evaluation coverage. None of those is a rewrite; they are model coverage and one training-framework integration.
The release history itself is short. The method was announced on 2025-05-29 as a decoding-time KV cache compression method for serving reasoning models, it appeared at NeurIPS 2025 with the paper on arXiv, and the serving work followed through the summer of 2026 across four integrations. There are no GitHub releases, so the only version anchor in the tree is the 0.1.0 in setup.py, and the last commit on main is dated 2026-10-02.
Editorial conclusion
R-KV fits a team serving reasoning models on constrained GPUs that has already accepted patching an inference server, since the production ports are patches over pinned upstream checkouts rather than drop-in packages. It does not fit anyone who wants a library-level change or a fresh set of numbers without re-running them. Verify four things first. Re-run any GSM8K result you computed before commit e9f54c45, because the shipped data file carried a stale field that pinned scores near 40 percent regardless of method or budget. Read the throughput claims as memory-bound numbers on one model generation, since the gains are quoted at specific gpu_mem fractions on H100s and the accuracy claim is lossless at one budget on one benchmark. Decide whether you can carry a patch, since both production ports install by applying a wiring patch to a pinned checkout. And settle licensing before you build on it: there is no LICENSE file at the repository root and the license metadata carries no recognised identifier, so nothing in the repository states the terms. The method was released on 2025-05-29, the last commit is dated 2026-10-02, and there are no GitHub releases.
Frequently asked questions
What is R-KV?
A redundancy-aware KV cache compression method for reasoning models, presented at NeurIPS 2025. It discards repetitive tokens on the fly during decoding, and the project claims full-accuracy reasoning with a fraction of the memory, plus higher throughput as the KV pool shrinks.
How does R-KV's KV cache compression work?
Redundant tokens are scored across layers in batches and physically evicted during decoding, and evicted blocks are returned to the allocator rather than held. In the vLLM port the eviction activates automatically once the budget and buffer are both above zero, set through the two R-KV environment variables, and sequence segmentation is controlled by a divide method and divide length.
Do I need to re-run GSM8K numbers from the R-KV repository?
Yes, if you computed them before commit e9f54c45. The shipped data/gsm8k.jsonl carried a stale generation field that the evaluation script preferred over fresh output, freezing GSM8K scores near 40 percent regardless of method or budget. MATH and AIME24 were unaffected, and validation artifacts are in tests/smoke/ and a dated results directory.
How is the R-KV vLLM and SGLang integration installed?
Both ports ship as a patch over a pinned upstream checkout rather than a fork. In the vLLM or SGLang directory you run the apply script, which clones the pinned version, drops in the algorithm directory and applies the wiring patch, then install the result, with the vLLM build needing CUDA and a GPU.
What license does R-KV use?
The repository does not say in a way you can rely on. There is no LICENSE file at the repository root and the license metadata carries no recognised identifier. setup.py only declares the package name rkv at version 0.1.0, so anyone planning to build on the code needs to establish the terms first.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zefan-cai-r-kv)Star history chart for your README
[](https://hysenlabs.com/projects/zefan-cai-r-kv)Was this useful?