Paper-Notes: 23,000 conference notes, with the paper lists in a second repository
Interpretations of thousands of top-conference AI, LLM, NLP and CV papers, each distilled into a 5-minute read of the core idea.
At a glance
- What is it?
- zhaoyang97/Paper-Notes is a Python and Markdown corpus of short Chinese explanations of AI, LLM, NLP and CV conference papers, rendered as a site by MkDocs. Its first release already claimed two conferences that later releases describe as only being completed, and the paper lists live in a different repository entirely.
- Who is it for?
- This corpus fits a reader who wants a fast orientation to a paper before deciding whether to read it, in Chinese, organised by the conference a paper was published at rather than by topic alone. It does not fit anyone who needs the notes as a commercial training resource, because the stated terms are non commercial with attribution and share alike, while the repository record itself carries no recognised licence identifier.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 43 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
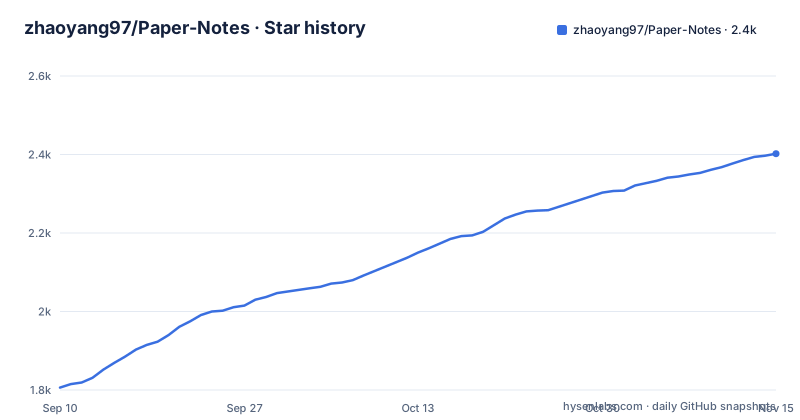
- zhaoyang97/Paper-Notes2,402 ★ · +596
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| zhaoyang97/Paper-Notes | 1.8k | 2.4k |
596 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The area table has 54 rows and adds up to the headline figure
The claim at the top of the README is over 23,000 notes, and the research area table lets you check it. It lists 54 folders with a note count each, and those counts sum to 23,848, so the headline and the table agree. The distribution is heavily skewed, which tells you what the corpus actually contains. Image generation leads with 2,076 notes, 3D vision follows at 2,010, multimodal vision language models at 1,450 and model compression at 1,045, while the catch all bucket called others holds 995. On the other end, anomaly detection has 14 notes, and earth science and federated learning have 19 each. Signal and communication has 39. Two entries are worth a second look because they are identical in a way that is hard to believe: video generation and video understanding both report exactly 506. A corpus this size will have files counted by a script, so that match may be a coincidence, but it is the kind of number a reader should check rather than cite.
Version 1.0.0 claimed two conferences that later releases completed
The release notes are the most informative section, and they contain a small inconsistency. Version 1.0.0, dated 2026-04-18, is described as the first formal version with 13,000 or more notes accumulated, covering nine conferences, and two of those nine are CVPR 2026 and ICLR 2026. Then version 1.3.0 on 2026-06-13 says it completed all roughly 4,000 CVPR 2026 notes, and version 1.4.0 on 2026-06-20 says it completed all roughly 5,000 ICLR 2026 notes. So a conference counted as covered at launch was still being described as incomplete two months later. The arithmetic is roughly consistent, since 13,000 plus 4,000 plus 5,000 plus the ACL, ICML and ECCV additions lands near the 23,848 the table reports, which suggests covered at launch meant partially covered. The current coverage table lists twelve conferences rather than nine, running from ECCV 2026 back to ECCV 2024.
The version history lives in the README because there are no releases
This repository has no GitHub releases at all, and every version number a reader will ever see is written in the README itself. The list runs from v1.0.0 in April 2026 to v1.6.0 in September, with the intermediate releases dated 2026-04-25, 2026-05-23, 2026-06-13, 2026-06-20 and 2026-07-11. That is a useful log, because each entry says what changed: ACL 2026 added in v1.1.0, ICML 2026 in v1.2.0, the CVPR and ICLR completions in v1.3.0 and v1.4.0, ECCV 2026 added in v1.5.0 and supplemented in v1.6.0, with the paper ordering improved at the same time. What it does not give you is a tag to pin, a release artefact to diff, or a published date enforced by the forge. The branch was pushed on 2026-10-03, days after v1.6.0, so any change since then exists only in the tree.
The paper lists are in a different repository from the notes
The coverage table has two columns, and the second one points somewhere unexpected. Each conference has a site path under papernotes.org, and next to it a link to a Markdown file in a separate repository, zhaoyang97/papers-with-notes, named after the conference and year, such as ECCV2026-Papers.md. So the paper lists and the notes are two different projects: one holds the enumeration of what was published, the other holds the explanations. Nothing in the notes repository pins a commit of the lists repository, so a conference's contents can change underneath the notes. It also means the complete list of papers for a venue is only as stable as the other branch. For a reader trying to check coverage, the two-column table is the place to look, and for anyone building tooling over the corpus it is a reminder that two repositories have to be read to answer a simple question.
MkDocs, a hooks directory, and a rendering tip about broken formulas
The site is generated by MkDocs, and the root shows it: mkdocs.yml for configuration, an overrides directory for theme customisation and a hooks directory for build hooks, alongside a scripts directory whose Python is what makes Python the primary language of the repository. There is also a hreflang pairs file at the root, which is the mechanism a static site uses to tell search engines which language version of a page is which. The content itself is entirely Markdown, and the directory structure is uniform: a top level index with site wide search, a per conference index that aggregates by research area, a per area index inside it, and then one Markdown file per paper named by slug. One admission in the README is worth passing on, because it is the kind of thing a project usually fixes quietly instead. Next to the link to the site there is a note saying that if the mathematical formulas render incorrectly, refreshing the page usually solves it. A rendering bug in a maths-heavy corpus is worth knowing about before you conclude the content is wrong.
The roadmap gives three dates per conference, and two of them collide
The update roadmap is a small table of upcoming venues with three columns each: when acceptance notifications go out, when the list of papers is published, and when the conference itself happens. NeurIPS 2026 has acceptance and list both in 2026-09 with the conference in 2026-12. EMNLP 2026 has acceptance in 2026-08, list in 2026-10 and conference also in 2026-10, so the list appears in the same month as the event. AAAI 2027 runs acceptance 2026-11, list 2026-12, conference 2027-01. ICLR 2027 has acceptance and list together in 2027-01 with the conference in 2027-04, and CVPR 2027 runs acceptance 2027-02, list 2027-03, conference 2027-06. The plan is legible and the direction is right, since a project that summarises accepted papers is bound by the list date rather than the conference date. The collisions are the detail to keep in mind, because a list published the same week as the conference leaves no room for the batch described in the update notes.
Non commercial terms in the README, no licence identifier in the record
The licence is stated at the end of the README in three parts: attribution is required, commercial use is not permitted, and modifications must be shared under the same terms, with the licence identified as CC BY-NC-SA 4.0. The repository record for this project, however, carries no recognised licence identifier, and the tree does contain a LICENSE file at the root. The two therefore need reconciling before anything is reused, and this article will not pick between them. The practical reading of the terms as written is narrow: a research or study audience is fine, and a company that wants to use the notes in a product, in customer material or in a paid internal tool is not. The corpus summarises other people's published work, so the terms of the original papers sit underneath these terms as well. The project also runs an explicit takedown and correction process, with an issues page, a contact address and a group number listed for that purpose.
Editorial conclusion
This corpus fits a reader who wants a fast orientation to a paper before deciding whether to read it, in Chinese, organised by the conference a paper was published at rather than by topic alone. It does not fit anyone who needs the notes as a commercial training resource, because the stated terms are non commercial with attribution and share alike, while the repository record itself carries no recognised licence identifier. Before building anything on it, check four things. Which conference and which area a note belongs to, because the same paper can be filed differently from another listing of the same venue. How current a version is, since the version history is maintained in the README rather than in releases, so there is no tag to pin. Where the paper lists come from, since they live in a second repository. And how the maths renders, because the site itself suggests refreshing the page when a formula breaks.
Frequently asked questions
What is Paper-Notes and how large is it?
It is a corpus of Chinese explanations of AI, LLM, NLP and computer vision conference papers, each meant to be readable in about five minutes. The README claims over 23,000 notes, and the research area table's 54 rows add up to 23,848. It covers venues including ACL, CVPR, ICLR, AAAI, NeurIPS, ICCV, ICML and ECCV.
Where are the paper lists kept?
In a separate repository, zhaoyang97/papers-with-notes, one Markdown file per conference and year such as ECCV2026-Papers.md. This repository holds the notes themselves, and nothing pins a commit of the lists repository, so the list of papers for a venue can change independently.
How is the Paper-Notes site built?
With MkDocs, configured through mkdocs.yml, an overrides directory for the theme and a hooks directory for build hooks, with the Python scripts in the repository doing the work. Content is Markdown: a top level index with site wide search, a per conference index, a per area index and one file per paper.
Can I use Paper-Notes notes commercially?
The terms written in the README say no. Content is offered under CC BY-NC-SA 4.0, which requires attribution, forbids commercial use and requires modifications to be shared under the same terms, while the repository record carries no recognised licence identifier. Read the LICENSE file at the root before relying on either statement.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zhaoyang97-paper-notes)Star history chart for your README
[](https://hysenlabs.com/projects/zhaoyang97-paper-notes)Was this useful?