spec-kitty: the tree is at rc6, the newest tag is rc5, and the README tells you to install rc2
Spec-Driven Development for serious software developers. Spec Coding with with Claude, Cursor, Gemini, Codex. Kanban dashboard, git worktrees, auto-merge and more.
At a glance
- What is it?
- Spec Kitty keeps specs, plans, work packages, acceptance criteria, review state and merge decisions inside your repository, then hands each coding agent an isolated git worktree so parallel runs stop colliding. The idea is well executed and unusually honest about its own edges, from a format check that only really runs inside the test suite to a Node manifest that exists for one maintenance script. The version numbers, meanwhile, point at three different release candidates.
- Who is it for?
- This is a serious tool with an unusual amount of self documentation, and the parts worth reading are the parts that admit their own limits. For a team already running several coding agents against one repository, the worktree isolation and the review gates are the reason to look, and the whole state model is plain files in Git, which means you can read your own governance without the tool.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
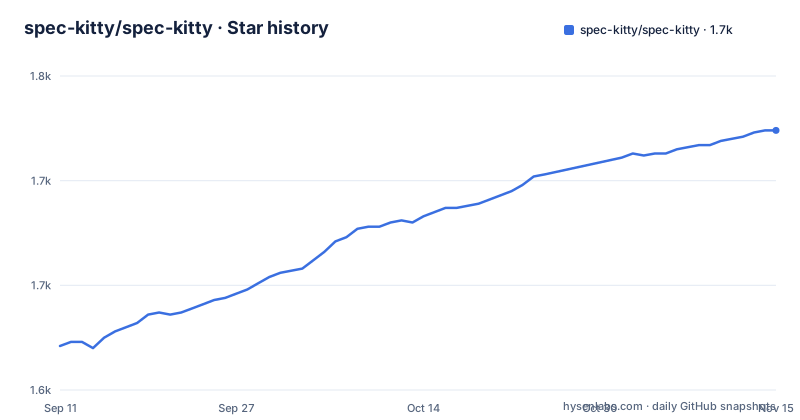
Star history
- spec-kitty/spec-kitty1,724 ★ · +103
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| spec-kitty/spec-kitty | 1.6k | 1.7k |
103 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three different release candidates, and which one you are told to install
The three numbers do not agree, and they are all in the project at once. pyproject.toml declares version 4.0.0rc6. The newest published release is v4.0.0rc5, tagged 2026-10-02, with v4.0.0rc4 on 2026-09-21 and v4.0.0rc3 on 2026-09-17 behind it. And the prerelease section of the README, headed Team Kitty 4.x prerelease, instructs you to test RC2 by installing its exact version:
uv tool install 'spec-kitty-cli==4.0.0rc2'So the tree you would clone is one candidate ahead of the newest tag, the newest tag is three candidates ahead of the version the documentation tells you to pin, and all three of the recent releases are candidates rather than a stable number. The classification in pyproject.toml is consistent with that: Development Status :: 4 - Beta, not a stable claim.
The page is explicit about why. It says the prerelease is for qualification and that stable launch acceptance remains pending, and that normal stable installs continue to select the published stable release. Which is a reasonable position to take, and also an instruction to read carefully: installing by name with pipx gives you the stable line, installing the exact candidate gives you rc2, and cloning gives you rc6. Nothing in the document tells you which of those three a new user is supposed to be on, and nothing tells you what the stable line's number is.
One arrow line, eight slash commands, and one command named with a hyphen
The whole workflow is written as a single line, and it is the clearest statement of the idea in the document:
spec -> plan -> tasks -> next -> review -> accept -> mergeSeven verbs, and the first three run as slash commands inside the agent while the fourth is a CLI call that decides what happens next. Initialisation is `spec-kitty init my-project --ai claude`, then `spec-kitty verify-setup`, then the agent side:
/spec-kitty.charter
/spec-kitty.specify Build a small task list app.
/spec-kitty.plan
/spec-kitty.tasks
Then the runtime picks the next action with `spec-kitty next --agent claude --mission <mission-slug>`, and the loop closes with `/spec-kitty.review`, `/spec-kitty.accept` and `/spec-kitty.merge --push`.
The naming is almost perfectly consistent, which makes the one exception worth knowing about. Every command in that namespace uses a dot, `/spec-kitty.charter` through `/spec-kitty.merge`, and the one that runs after the merge is spelled with a hyphen instead: `/spec-kitty-mission-review`. Two different separators for the same family of commands, and the odd one out is the one you need after every mission finishes, so a script or a muscle-memory habit built on the dotted form will fail exactly once per mission.
The retrospective is promised by default, and authored somewhere else
The capability table promises that every completed mission generates a retrospective by default, and says you can tune it through the retrospective block in `.kittify/config.yaml` or through the charter. The prose further down is more careful, and the two do not fully agree.
What the prose says is that the mission's retrospective.yaml is authored during the runtime terminus, by the human in the loop prompt or by the autonomous facilitator, and explicitly not by the merge command. Then it says that once it exists, you can use `spec-kitty retrospect summary` for the cross-mission view, and `spec-kitty agent retrospect synthesize --mission <mission-slug>` to apply any staged proposals. That last command is dry run by default, and you pass `--apply` to make it mutate, which is the right default for a command that rewrites what your agents learned.
The tension is in the word once. If the retrospective is generated by default on every completed mission, you would not need to wait for it to exist, and the sentence structure implies that sometimes it is not there. The honest reading is that the terminus step is the thing that produces the file, the terminus can run under either of two modes, and a mission whose terminus did not produce one leaves you with a summary command that has nothing to summarise and a synthesize step with no proposals staged.
Four directories hold the entire state, and they are all plain files
The design commitment is that the repository remains the source of truth, and the layout is where you can check that. Mission artifacts live under `kitty-specs/`. Work gets isolated into git worktrees under `.worktrees/`. Tuning lives in `.kittify/config.yaml`, where the retrospective section is the documented knob. And the work packages themselves move through five named lanes: `planned`, `in_progress`, `for_review`, `approved` and `done`.
Progress is read back out of those same lanes with `spec-kitty agent tasks status`, which the everyday commands table notes takes `--json` for tools. That is a deliberate choice worth naming: the same status is available for a human to read and for a program to parse, which is what makes the state usable as an interface rather than only as documentation.
One more command has an easy to miss consequence. `spec-kitty upgrade` is described as updating an existing project after you upgrade the CLI, so the tool and the project are versioned separately and moving one does not move the other. If you upgrade the CLI and skip that step, the repo is left holding mission state written by an older version of the runtime, and nothing in the document says what that looks like when it happens.
Twelve agent directories in this repository, thirteen agent keys in the docs
The top level of the tree carries a configuration directory per agent host: `.agent/`, `.amazonq/`, `.augment/`, `.cursor/`, `.gemini/`, `.kilocode/`, `.kiro/`, `.llxprt/`, `.opencode/`, `.qwen/`, `.roo/` and `.windsurf/`, alongside a `.claudeignore`, an `AGENTS.md` and a `CLAUDE.md`. That is the shape of a project developed with the same tools it ships support for, and the shape of what gets written into a user project after initialisation.
The mechanism that writes them is in the developer setup target:
uv sync --frozen --all-extras
uv run --frozen spec-kitty doctor skills --fix
So a doctor subcommand with a fix flag installs the slash commands for whichever agents a project has configured. The agent keys offered to `--ai` at init time number thirteen: claude, codex, cursor, gemini, copilot, opencode, qwen, windsurf, kiro, vibe, pi, letta and llxprt.
The number of hosts is not something the CLI help will tell you. The capability table names eight, Claude Code, Codex, Cursor, Gemini, Copilot, Windsurf and OpenCode, and then says and more, pointing at `docs/api/supported-agents.md` for the current list. So the supported surface is a document, and a document is the right place for a list that changes, but it does mean the count of what you can actually use lives outside the tool.
The enforced copy of the format check is a test, not a make target
The Makefile sets `.DEFAULT_GOAL := help` and lists twelve phony targets, but the interesting part is in the comments, which repeatedly point at the place where a check is actually binding. `format-check` is annotated as convenience only, with the enforced copy living in `tests/architectural/test_ruff_format_enforcement.py` as part of `make test-full`, and the stated reason is that a red gate is never silent regardless of whether anyone runs the target locally, citing issue #558. The same target is also the gate from issue #473, and `format-check-files` honours the format exclude ratchet from #5301.
Every invocation in the file is `uv run --frozen`, so no target will re-resolve the lockfile; a mismatch is a deliberate stop rather than a surprise upgrade. `lint` is `ruff check src/`, `format-check` is `ruff format --check .`, `docs-lint` runs a spelling check with scoped US spelling plus a changelog style check, and `convergence-census` does something unusual: it runs `git fetch old` and then reports convergence dispositions through a script.
A git remote named `old`, in a make target described as fetching upstream and reporting how the two lines have converged, with a `research/` and a `research-outputs/` directory at the top level, is the most distinctive thing in this repository. It tells you the project watches a predecessor it calls old and keeps a record of how far apart the two have drifted.
Type checking is scoped rather than total, and the visible invocation is a `mypy --strict` aimed at one path under `src/specify_cli/runtime/`, which also reveals the import package name: the source package is `specify_cli`, while the distribution is `spec-kitty-cli` and the command is `spec-kitty`. Three names for one tool.
A Node manifest for one maintenance script, pinned to a release candidate
There is a `package.json` and a `package-lock.json` at the root of a Python CLI, and they exist for a single job. The manifest is named `spec-kitty-maintenance`, marked private, and its one script is a Python call: `contributors:sync` runs `python3 scripts/sync_all_contributors.py`. The only dev dependency is `all-contributors-cli` at 6.27.0-rc.1, pinned to a release candidate, and there is an override forcing `tmp` to 0.2.4.
That is a complete Node toolchain, a lockfile, and a prerelease-pinned CLI, all to regenerate the contributor table that `.all-contributorsrc` and `CONTRIBUTORS.md` already hold. Worth knowing if you clone the project and wonder which runtimes you need, and worth knowing if you maintain a repository that would rather not carry either.
The Python side is more conventional. The distribution is `spec-kitty-cli`, it requires Python 3.11 or newer, the license is expressed as a file reference alongside an MIT classifier, and the classifiers cover 3.11, 3.12 and 3.13. The dependency comment is the interesting part: the upper bound exists because an unbounded range let fresh resolves pick untested future majors of a CLI framework, and it records three eras of vendoring that framework's internals, with the bound set to the span the code is exercised against. The comment ends mid-word after untested future majors of, which is where the explanation stops.
For comparison, the gate count in this repository is wide: ruff for lint and format, targeted mypy in strict mode, pytest through `pytest.ini`, a `run_tests.sh`, a `sonar-project.properties`, a markdownlint config, a commitlint config, and a docs spelling check. That is a real quality stack rather than a token one, and the format check being mirrored into the test suite is the kind of detail that usually only shows up in projects that have been burned by a gate nobody ran.
The project states its own position on autonomy, and several top level files go unexplained
The clearest paragraph in the document is the one about what the tool is not. It says a bright software factory rather than a black box, that dark factories and autonomous coding experiments are supported, and that it is deliberately not a lights-out system by default. Humans define intent, architecture and acceptance criteria; agents implement inside traceable worktrees; reviewers accept, reject or merge with an audit trail. Both modes are in the same binary, since the retrospective terminus runs under a human in the loop prompt or an autonomous facilitator.
The governance layer is one command and two documents. `spec-kitty dispatch "<request>"` loads governance context, opens an Op record, and returns the context the agent must use before it does the work, and the trail model document describes how that request maps to runtime behaviour while the host surface parity document tracks parity across the CLI, slash command and hosted surfaces. So there are three surfaces to keep in sync, with a hosted tracker and sync integrations described as something to add later rather than something present now.
The remaining top level entries are the ones the page never mentions, and they are not a trivial list: `occurrence_map.yaml`, `contracts/`, `packs/`, `kitty-ops/`, `research/`, `research-outputs/`, `ascii-art.txt`, `RELEASE_CHECKLIST.md` and `SECURITY-POSITION.md`. A file named occurrence_map.yaml at the root of a CLI, with no description anywhere in the documentation, is the kind of thing that tells you the repository has more history behind it than the README is willing to summarise. Which is a fair trade as long as you know it is there.
Editorial conclusion
This is a serious tool with an unusual amount of self documentation, and the parts worth reading are the parts that admit their own limits. For a team already running several coding agents against one repository, the worktree isolation and the review gates are the reason to look, and the whole state model is plain files in Git, which means you can read your own governance without the tool. Four things to settle first. Versioning is unsettled right now: the source declares 4.0.0rc6, the newest published tag is v4.0.0rc5, and the README still tells you to pin 4.0.0rc2, so decide whether you want the stable line or a specific candidate and write that down. The project calls itself a prerelease for qualification with stable launch acceptance pending, so treat the stable install path as the one that will still be there later. Autonomy is a choice, not a default, and the tool states plainly that it is not a lights-out black box: humans define intent, architecture and acceptance criteria, and reviewers accept, reject or merge with an audit trail. And the gate you would assume is enforced, the format check, is only authoritative inside `make test-full`, not when you run the target by hand. If you are working solo on a small script, the page says outright that this is overkill, and it is right about that too.
Frequently asked questions
What is Spec Kitty?
An open-source Python CLI for spec-driven development with AI coding agents. It keeps specs, plans, work packages, acceptance criteria, review state and merge decisions in the repository, and gives each agent an isolated git worktree under `.worktrees/`.
Which version of spec-kitty should I install?
The page pins 4.0.0rc2 for testing the prerelease, while pyproject.toml declares 4.0.0rc6 and the newest published release is v4.0.0rc5. It also says normal stable installs keep selecting the published stable release.
Does spec-kitty run fully autonomously?
Not by default. The project describes itself as a bright software factory rather than a black box: humans define intent, architecture and acceptance criteria, agents implement in traceable worktrees, and reviewers accept, reject or merge with an audit trail.
How do I install spec-kitty?
The preferred installer is pipx, because it keeps the CLI in its own virtual environment and avoids externally-managed-environment errors on modern Linux. `uv tool install spec-kitty-cli` and `python -m pip install spec-kitty-cli` inside an activated virtual environment are also listed.
What do the work package lanes in spec-kitty look like?
Five named lanes: `planned`, `in_progress`, `for_review`, `approved` and `done`. `spec-kitty agent tasks status` shows the status for a mission and takes `--json` so tooling can read the same state.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/spec-kitty-spec-kitty)Star history chart for your README
[](https://hysenlabs.com/projects/spec-kitty-spec-kitty)Was this useful?