Claude Code Migration Kit: a reference kit for structure-preserving language ports
Prompts, templates, and scripts for running large-scale language migrations with Claude Code
At a glance
- What is it?
- Anthropic's code-migration-kit-with-claude-code packages the prompts, templates and scripts behind a six-step migration process. It is reference code, not a maintained product, and it only fits ports that keep the same architecture.
- Who is it for?
- Adopt it if you are planning a structure-preserving port of a large codebase and you already have a test suite that exercises the public surface, or you are willing to build a parity harness with prompts/00b-judge-setup.md before anything else.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 129 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
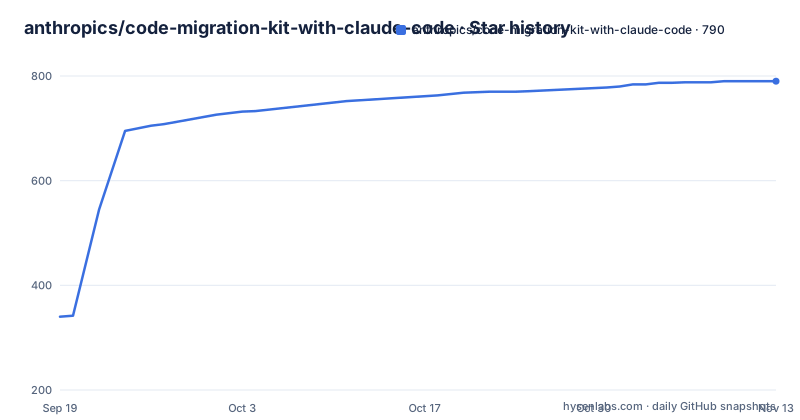
Star history
- anthropics/code-migration-kit-with-claude-code790 ★ · +450
| Repository | 2026-09-19 | 2026-11-13 |
|---|---|---|
| anthropics/code-migration-kit-with-claude-code | 340 | 790 |
450 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the kit is for, and what it refuses to be
The README is explicit that this repository defaults to structure-preserving migrations: same architecture, same data structures, new language. That restriction is the whole design. A port that keeps the architecture is mechanical enough that translation questions can be decided once, written down, and applied by agents without re-litigating them. A port that redesigns while it translates breaks that assumption, and the README says parts of the kit change and one part becomes invalid in that case, pointing readers at the "If you're redesigning" section first.
The audience is therefore narrow. It is a team that has already decided to move a large codebase to another language without changing its shape, and that has enough test coverage to grade the result. The README frames the starting point as a feasibility report produced by prompts/00-feasibility.md, run read-only inside the repository. That report makes three committed calls (structure-preserving or redesign, what verification costs, whether the existing tests survive), sketches the six steps for your repository, and returns a verdict. The README states that "Don't migrate" is a valid outcome, and that nothing else in the kit matters until that report says go.
The doctrine: fix the process, not the failing file
Every step in the kit follows one rule, quoted from the README: you don't fix the code, you fix the process that produced the code. Individual failures are burned down by fixer agents. A failure that keeps recurring indicts a rule, and the rule gets amended.
That doctrine explains the shape of the artifacts. The rulebook, copied from templates/RULEBOOK.md to migration/RULEBOOK.md in the target repository, is where every decision a translator could make two ways is settled once. Its meta-rule is that if two agents could answer differently, the answer belongs in the rulebook. The dependency map is a deterministic script (scripts/depmap_*.py or .mjs) rather than agent judgment, and the README notes it works at file granularity and at the target language's package granularity, because Bun's port had a clean file graph and still produced roughly 16K compile errors from package-level cycles nobody had checked. The gap inventory (prompts/02 plus templates/inventory.tsv) is a flat table of every site where the target language demands something the source let you keep in your head: ownership, lifetimes, nullability, interface contracts. Implementers grep it; nobody reads it end to end.
Installing the kit and running the first real prompt
There is no package to install. The quick start clones the kit inside or next to the repository being migrated, then wires two things into the target repository before the six steps begin.
The first is the operating manual that every session reads. The README gives the clone command with a placeholder for the kit's own URL:
git clone <kit> ./migration-kitAfter cloning, copy or @-import the kit's CLAUDE.md into the target repository's CLAUDE.md. The README treats this as a prerequisite for the six steps, not an optional extra.
The second is the settings file that carries the deny rules. The README says to copy templates/settings.json to the target repository's .claude/settings.json, and states that prompts 03 and 04 verify it exists and stop without it. In one early test run, according to the README, the step was silently skipped and nothing caught it. The denies need to be live for Step 2's pilot and stay active through Step 4, with test denies re-activated for Step 6's fix loops.
The optional skill install is also given as a copy command in the README:
cp -r migration-kit/skill ~/.claude/skills/code-migrationAfter copying, the README says to replace the [kit path] placeholder inside the installed SKILL.md. The first real use is then to open Claude Code in the target repository and paste prompts/00-feasibility.md with its placeholders filled. What you should see is a read-only report, not edits to the repository.
Step 2 is the part most teams will skip, and it is the part that catches bad rules
The rulebook has never met real code when Step 1 ends. Step 2 runs two things before any fan-out. The bakeoff puts two translators in separate contexts: one follows the rules, one never learns the rules exist, and a diff inspector turns every difference into a verdict on a specific rule. The pilot runs the production pipeline exactly as the fan-out will run it, graded on obedience rather than output quality. The README states that amendments are queued for you and never self-applied.
This is the strongest design choice in the kit and also the most expensive one. A bakeoff doubles translation cost on a sample of files, and its value depends entirely on whether the diff inspector's verdicts are good enough to change a rule rather than a file. The README offers no measurement of that, and no threshold for how large a sample should be. Teams that want a fast answer will be tempted to go straight to prompt 04, and the kit gives them no automated guard against it.
The judge requirement, and the case where the kit is the wrong tool
The quick start states the constraint plainly: make sure you have a judge before Step 1, because there is no exit condition without one. If the existing test suite hits the public surface, or already lives in a third language, that suite is the judge and gets carried into Step 6. If the suite imports internals that die with the old language, the README directs you to prompts/00b-judge-setup.md to build a portable parity harness, and to validate it against the original code and against deliberately broken code before any translation happens.
That requirement disqualifies a large class of projects. A codebase whose tests mock internal modules heavily, or whose behaviour is only observable through the old runtime, has no cheap judge. Building one is a project in itself, and the kit does not shorten it. The second disqualifier is scope: a migration that changes architecture while it changes language falls outside the kit's default, and the README says one part of the kit becomes invalid in that case without saying which part in the text available here. The third is the status line. The repository is not archived, and the last push was on 2026-07-08, but the README itself says this is reference code, a companion to a blog post, and that issues and PRs are not monitored. Treat the kit as a document you fork, not a dependency you track.
How the queue and the gates actually move work forward
Step 3 fans out implementer, two adversarial reviewers and a fixer per unit over a mechanical queue. The queue runner is scripts/queue_runner.mjs, and the queue itself is defined by what exists on disk: every entry in migration/manifest.tsv, a Step 1 output, that has no output file yet. The kickoff prompt in prompts/04-translation-kickoff.md is deliberately short because by that point the rulebook is the prompt.
The sign-off model is worth understanding before adopting the kit. A workflow runs its phase to completion, returns evidence, and exits. The README describes your sign-off as the act of kicking off the next one. Because every queue is derived from files on disk, stopping is free and resuming is a re-invocation rather than a recovery. In stock Claude Code, "use a workflow" means running the phase as parallel subagents that stop at the gate, which the README identifies as a Task or Agent fan-out. Step 4 then runs one survey build that grades everything, converts the error list into a machine queue sliced by module, and has fixers work without compiler access, which is what the deny rules in templates/settings.json are for.
Provenance, licence and what upgrading looks like
The README labels the prompts reconstructions: generalized and reviewed against real production migrations, including Bun's 1M+ line Zig to Rust port, but not transcripts. It notes that the real artifacts were messier and more specific, and that the Bun port's prompt was a 576-line rulebook plus a one-sentence kickoff. That matters when you read the prompts as a specification. They are a cleaned-up model of a process, and the messy parts that made it work in production are not all present.
The repository carries a LICENSE file, and the metadata classifies the licence as NOASSERTION, meaning the licence could not be determined automatically. Read LICENSE yourself before you vendor the prompts into a repository that ships to customers; nothing here is legal advice. Upgrade cost is close to zero and also close to meaningless: there are no published GitHub releases, the README says the project is not actively maintained and that issues and PRs are not monitored. The practical upgrade path is to diff your fork against the repository when you want to, and to expect no fixes for problems you find.
Editorial conclusion
Adopt it if you are planning a structure-preserving port of a large codebase and you already have a test suite that exercises the public surface, or you are willing to build a parity harness with prompts/00b-judge-setup.md before anything else. Skip it if your migration also redesigns the architecture, since the README states that one part of the kit becomes invalid in that case, and skip it if you need a maintained dependency, because the README says issues and PRs are not monitored. Verify three things before you commit: that the kit's CLAUDE.md is imported into the target repository's CLAUDE.md, that templates/settings.json is copied to .claude/settings.json before prompt 03, and that your judge passes against deliberately broken code.
Frequently asked questions
What is code migration in coding?
In this kit's terms it is moving a codebase to another language while keeping the same architecture and data structures, which the README calls a structure-preserving migration. The kit's six steps cover mapping dependencies, writing rules, translating, compiling, running and matching behaviour.
Is the Claude Code Migration Kit used for coding?
It is used to run a migration process through Claude Code rather than to write application code directly. The prompts drive implementer, reviewer and fixer agents over a queue, and the README says the rulebook becomes the prompt by Step 3.
How do I install the Claude Code Migration Kit?
Clone it inside or next to the repository you are migrating, copy or @-import its CLAUDE.md into that repository's CLAUDE.md, and copy templates/settings.json to .claude/settings.json before prompt 03. The skill install is optional and requires replacing the [kit path] placeholder in SKILL.md.
Does the Claude Code Migration Kit work if I am redesigning the architecture as I migrate?
The README states the kit defaults to structure-preserving migrations and that if you are redesigning, parts of the kit change and one part becomes invalid. It directs those readers to the "If you're redesigning" section before anything else.
What happens if I skip the judge setup in the Claude Code Migration Kit?
The quick start says there is no exit condition without a judge, so Step 6 has nothing to grade against. If your tests import internals that die with the old language, prompts/00b-judge-setup.md builds a portable parity harness that must be validated against the original code and against deliberately broken code.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/anthropics-code-migration-kit-with-claude-code)Star history chart for your README
[](https://hysenlabs.com/projects/anthropics-code-migration-kit-with-claude-code)Was this useful?