Apache Sedona: Distributed Geospatial Processing for Data Engineers
A cluster computing framework for processing large-scale geospatial data.
At a glance
- What is it?
- Apache Sedona brings geospatial analytics to Spark, Flink, and now a single-node engine. This review covers its architecture, setup, and where it fits among spatial data tools.
- Who is it for?
- Adopt Apache Sedona if you already run Spark or Flink and need spatial operations at scale, such as joins on billions of points. Skip it for single-node workloads unless you want the new SedonaDB, which is still young.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
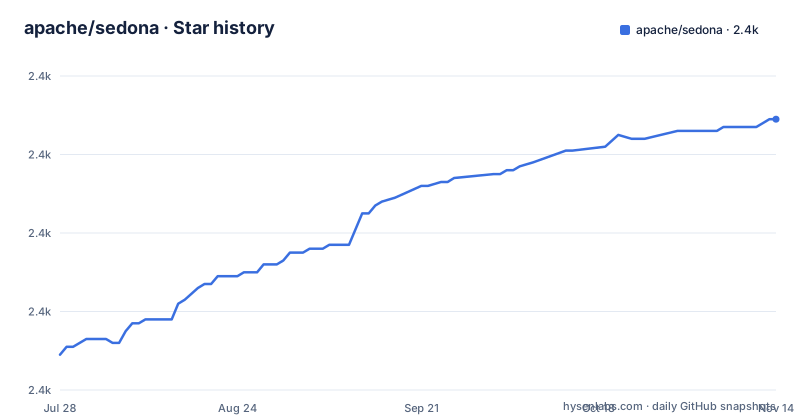
Star history
- apache/sedona2,429 ★ · +60
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| apache/sedona | 2.4k | 2.4k |
60 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Geospatial Data Does Not Fit Traditional SQL Engines
Most SQL engines treat spatial data as strings or coordinates without understanding relationships like distance, containment, or intersection. Apache Sedona solves this by adding spatial types, indexes, and operations to distributed processing frameworks. It targets data engineers and data scientists who need to run spatial queries on terabytes of location data, such as taxi trip records, satellite imagery footprints, or IoT device signals. The README's example loads NYC taxi trips and zones from CSV files on S3, then runs a spatial SQL query to return trips in Manhattan. That is the core use case: filtering and joining geospatial datasets at cluster scale.
Architecture: Spatial Extensions on Spark and Flink
Sedona is not a standalone database. It is a library that plugs into Apache Spark and Apache Flink, adding geospatial operations to their SQL engines. The README shows a spatial SQL query and a spatial join between a taxi dataframe and a zone dataframe. Under the hood, Sedona uses spatial indexing structures like R-trees, though the README does not detail them. The key mechanism is that spatial joins are distributed across the cluster, with data partitioned and shuffled between executors. Distribution changes resource and shuffle costs; single-node engines may also process data larger than memory using disk. The project also includes a Python API, an R package, and a Docker image, so it covers multiple language ecosystems.
Getting Started: From Maven to PyPI and Docker
The README points to Maven, PyPI, Conda-forge, CRAN, and DockerHub for downloads. For Java, you add the sedona dependency to your Maven build. For Python, you install apache-sedona from PyPI. The README's example uses Spark DataFrames, so you need a Spark session. A typical setup involves loading CSV files from S3 with a schema that includes a location column, then using Sedona's ST_Contains or ST_Intersects functions in SQL. The README also mentions a Docker image, which is the fastest way to try it without installing Spark manually. The documentation on the website provides detailed installation steps for each API.
The New SedonaDB: Single-Node Simplicity
The most notable recent addition is SedonaDB, a single-node analytical database engine with geospatial as a first-class citizen. The README announces it as a subproject for developers who want Sedona's spatial analytics without distributed complexity. This is a significant shift because Sedona's original value was distributed processing. SedonaDB trades scalability for simplicity, targeting datasets that fit on one machine. The README links to a blog post and a dedicated page, but it does not provide details on its internal architecture. This is a young project, so expect rough edges. If you have a multi-terabyte dataset, stick with the Spark-based Sedona.
Limitations and Failure Modes
The README does not list explicit limitations, but the design implies several. First, spatial joins on distributed systems are shuffle-heavy. If your data is skewed, for example many points in a dense city, some executors will become bottlenecks. Second, the learning curve is steep if you are not already comfortable with Spark. Sedona is not a drop-in replacement for PostGIS: it runs in a supported engine such as Spark, but spatial queries can be written in SQL. Third, the single-node SedonaDB is new and may lack mature features like advanced spatial indexes or full SQL coverage. Fourth, the README mentions archived GeoSpark releases, which means legacy users must migrate. Sedona documents GeoJSON and GeoParquet readers; check format and version compatibility for the actual dataset.
Alternatives: PostGIS, GeoPandas, and SpatialHadoop
For single-node workloads, PostGIS offers mature spatial SQL with a rich function library. It is a different approach: a relational database with spatial extensions, not a cluster library. If you need to process data that fits in memory, GeoPandas is a Python library that provides spatial operations on Pandas DataFrames, but it does not scale beyond one machine. For distributed processing, SpatialHadoop is an older framework that uses MapReduce, but it lacks the SQL interface and ecosystem of Spark. The key difference is that Sedona integrates with Spark's DataFrame API and SQL, making it more accessible to data engineers than Hadoop-based tools. The choice depends on your data size and existing infrastructure.
Maintenance, Licensing, and Upgrade Path
Apache Sedona is licensed under Apache-2.0, which permits commercial use with no copyleft obligations. The project is actively maintained, with releases 1.8.1, 1.9.0, and 1.9.1 in 2026, the latest on August 5. The README shows numerous CI workflows for Java, Python, R, and Flink, indicating ongoing testing. The upgrade path from GeoSpark to Sedona is documented as an archived release, so existing GeoSpark users can migrate. However, upgrading between Sedona versions may require changes to API calls, especially with new subprojects like SedonaDB. The last push date is recent, so the project is not abandoned. For maintenance, you must track Spark and Flink version compatibility, as Sedona extensions are tightly coupled to those frameworks.
Who Should Adopt It and What to Verify First
Adopt Sedona if you have a Spark or Flink cluster and need to run spatial queries at scale. The NYC taxi example is a realistic benchmark: spatial joins on millions of records. Do not adopt it for simple point-in-polygon on a few thousand points; PostGIS is simpler. Before committing, verify that the spatial functions you need exist in the 1.9.1 release. Check the documentation for supported geometry types and indexing options. Test a spatial join on a subset of your data to estimate shuffle costs. Also, review the SedonaDB subproject if you want single-node, but wait for it to mature. The project's active maintenance and Apache governance make it a reliable choice for long-term use.
Editorial conclusion
Adopt Apache Sedona if you already run Spark or Flink and need spatial operations at scale, such as joins on billions of points. Skip it for single-node workloads unless you want the new SedonaDB, which is still young. Before adopting, verify that your specific spatial functions and data formats are covered in the 1.9.1 release notes, and check the performance of spatial joins on your cluster, since distributed shuffles can be costly. The project is actively maintained under Apache-2.0, with a clear path from GeoSpark, making it a safe bet for long-term use.
Frequently asked questions
What is Apache Sedona?
A cluster computing framework for processing large-scale geospatial data. It is distributed through five package channels: a Maven artifact, a Python package, a Conda channel, an R package and a container image, with the engine-agnostic core in one shared directory and per-engine directories for Spark and Flink beside it, including shaded build variants.
How does Apache Sedona relate to GeoSpark?
GeoSpark is the predecessor project. The readme keeps a download-table row for the archived GeoSpark releases, showing roughly ten thousand downloads a month against Sedona's three hundred and thirty thousand, so a measurable share of installs is still pulling the old artifact.
Is Apache Sedona 2.0 released?
Not yet. The newest published release is 1.9.1 from August 2026, and the readme carries a link to a document tracking which parts of the GeoPandas 1.1.4 API are implemented, including partial implementations, for the 2.0.0 development line.
Is the Python project in the repository root the Sedona package?
No. A comment in that file says it exists only for documentation and development dependency management, that it is not a distributable package, and that it must not be published. It is named as a monorepo meta project at version zero, and the real Python package is defined one directory down.
How do you build the Apache Sedona documentation?
The make target installs dependencies, runs a Node-based site build inside a separate docs-overrides directory, then deploys the result with a documentation versioning tool. The repository also configures a link checker for documentation links and a linter for makefiles.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/apache-sedona)Star history chart for your README
[](https://hysenlabs.com/projects/apache-sedona)Was this useful?